Paper: 2605.15187 Authors: Matt Zhou, Ruining Li, Xiaoyang Lyu, Zhaomou Song, Zhening Huang, Chuanxia Zheng, Christian Rupprecht, Andrea Vedaldi, Shangzhe Wu Categories: cs.CV, cs.GR, cs.RO
The Gap
Articulated 3D assets—objects with moving parts like doors, drawers, or robot arms—are essential for robotics simulation, VR, and training vision models. But existing datasets are tiny (hundreds of objects) and narrow (a few categories). Manual creation doesn’t scale. Generative models like text-to-3D struggle with articulation constraints: joints must align precisely, parts must not interpenetrate, motion ranges must be physically plausible. Prior work either generates static meshes (no articulation) or uses procedural generation with hand-coded rules (limited diversity, requires expert knowledge per category).
The core problem: articulated asset generation requires both geometric creativity and structural precision. Neural generators lack the latter; rule-based systems lack the former.
Problem: Need 10K+ diverse articulated assets
   |
   v
Existing approaches fail:
   |
   +---> Neural generators: creative but structurally invalid
   |
   +---> Rule-based: valid but narrow/manual
   |
   v
Key insight: Articulation = executable specification
   |
   v
Method: LLM writes programs in domain SDK
   |
   +---> SDK: high-level primitives (parts, joints, tests)
   |
   +---> Harness: validates, returns structured feedback
   |
   v
Evidence: 10K assets, 245 categories, outperforms baselines
   |
   v
Conclusion: Code generation > direct generation for structured 3D
The Increment
One sentence: Before this paper, generating diverse articulated 3D assets required either manual modeling or narrow procedural rules; after, an LLM agent writes programs against a domain SDK to produce 10K+ validated assets across 245 categories.
Core Mechanism
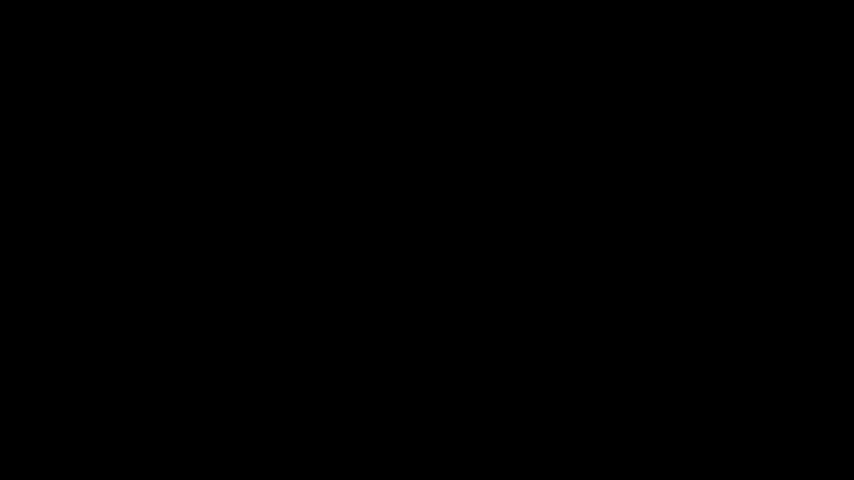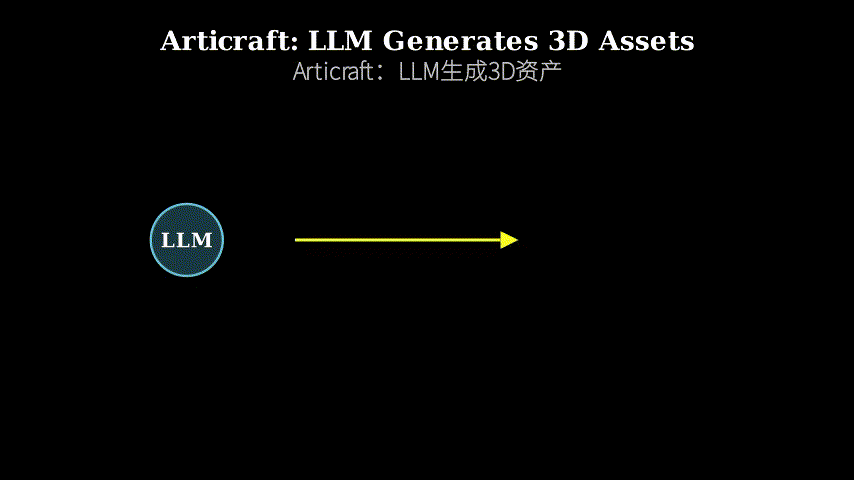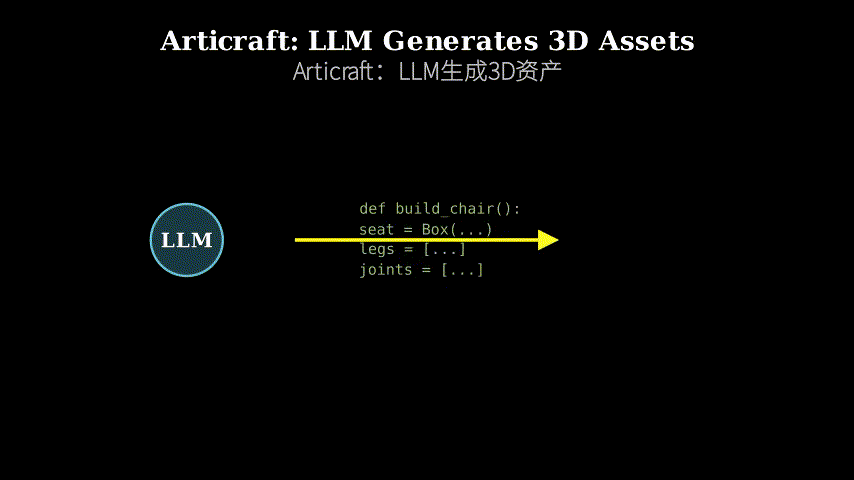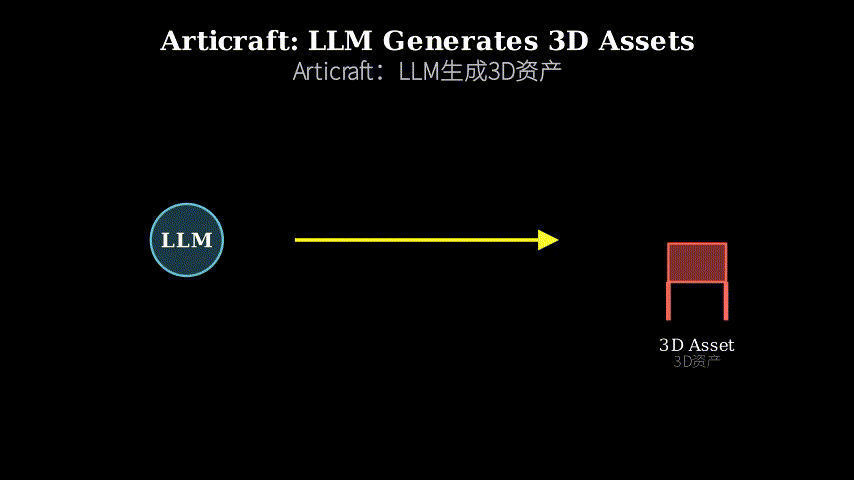
Articraft reframes articulated asset generation as a code generation problem. Instead of asking an LLM to output mesh coordinates or joint parameters directly, it asks the LLM to write a Python program that constructs the asset using a domain-specific SDK. The SDK provides high-level primitives: add_part() to define geometry, add_joint() to specify articulation, add_test() to validate constraints. The LLM writes a program, the harness executes it in a sandboxed environment, validates the resulting asset (collision checks, joint limits, kinematic feasibility), and returns structured feedback. If validation fails, the LLM revises the program based on the feedback. This loop continues until the asset passes all checks or a retry limit is reached.
The SDK abstracts away low-level details like URDF syntax or mesh file management. The LLM operates at the level of “add a rectangular base, attach a cylindrical leg with a revolute joint at this position.” The harness handles rendering, physics validation, and error reporting. Crucially, the LLM can write tests as part of the program—assertions about joint ranges, collision-free motion, or part dimensions—which the harness executes to catch errors early.
User prompt: "Generate a desk lamp"
   |
   v
LLM writes program:
   base = add_part("cylinder", ...)
   arm = add_part("box", ...)
   joint = add_joint("revolute", base, arm, ...)
   add_test("arm rotates 180 degrees without collision")
   |
   v
Harness executes program:
   |
   +---> Geometry instantiation
   |
   +---> Joint validation (limits, axes)
   |
   +---> Collision checking
   |
   +---> Test execution
   |
   v
Validation result:
   |
   +---> Pass: return asset (URDF + meshes)
   |
   +---> Fail: return structured error
             |
             v
          LLM revises program (loop)
Think of Articraft like a construction site with a foreman and inspector. The LLM is the foreman who reads blueprints (the user prompt) and writes work orders (programs) in a standardized format. The SDK is the set of prefabricated components—beams, joints, fasteners—that the foreman can specify without worrying about raw materials. The harness is the inspector who checks whether the assembled structure meets building codes (no collisions, joints work, tests pass) and issues violation reports if not. The foreman revises the work order based on the inspector’s feedback until the structure passes inspection. The key insight: by restricting the foreman to prefab components and giving the inspector clear checklists, you get both creativity (the foreman can design novel structures) and reliability (the inspector ensures they’re buildable).
Key Concepts
-
Domain-specific SDK: A programming interface tailored to a specific problem domain, exposing high-level operations that encapsulate complex low-level details. In Articraft, the SDK provides functions like
add_part(shape, dimensions, material)andadd_joint(type, parent, child, axis, limits). This is different from a general-purpose 3D library (like Blender’s Python API) because it bakes in domain knowledge: joints automatically handle coordinate frame transformations, parts have semantic labels (base, handle, lid), and the SDK enforces constraints (e.g., a revolute joint requires an axis). The benefit: the LLM doesn’t need to know how to compute rotation matrices or write URDF XML; it just callsadd_joint("revolute", ...)and the SDK handles the rest. Analogy: instead of giving someone a hammer and nails (low-level tools), you give them IKEA furniture with labeled parts and an instruction manual (high-level interface). -
Structured feedback loop: A validation-and-revision cycle where errors are reported in a machine-readable format that guides the next iteration. When Articraft’s harness detects a collision, it doesn’t just say “collision detected”; it returns
\{"error": "collision", "parts": ["arm", "base"], "joint_state": \{...\}\}. The LLM uses this structured data to diagnose the issue (the arm is too long, or the joint axis is wrong) and revise the program accordingly. This is more effective than natural language feedback (“something is wrong with the arm”) because it’s precise and actionable. The loop terminates when all validation checks pass or a retry limit is hit. This pattern—generate, validate, revise—is common in program synthesis but novel in 3D asset generation, where most systems generate once and hope for the best. -
Programmatic asset representation: Representing a 3D asset as executable code rather than as data (mesh files, parameter vectors). A desk lamp isn’t stored as vertices and faces; it’s stored as a Python function that, when executed, constructs the lamp by calling SDK functions. This has two advantages: (1) Composability: you can parameterize the program (lamp height, arm length) and generate variations by changing arguments. (2) Interpretability: you can read the program to understand the asset’s structure, which is harder with a raw mesh. The tradeoff: programs are less compact than meshes and require an execution environment. But for generation, programs are a better intermediate representation because they expose the generative process, making it easier to debug and refine.
Framework Shift
Before (neural/procedural generation):

User prompt --> [Generator] --> 3D asset
                    |
                    v
              (black box)
              - Neural: creative but invalid
              - Procedural: valid but narrow

After (Articraft):

User prompt --> [LLM] --> Program (SDK calls)
                           |
                           v
                      [Harness]
                           |
                           +---> Execute program
                           |
                           +---> Validate (geometry, physics, tests)
                           |
                           +---> Structured feedback
                           |
                           v
                      Valid asset <-- (loop if invalid)
From end-to-end generation to generate-validate-revise with a domain interface, the core shift is treating asset creation as a programming task where the LLM writes against a constrained API and an automated inspector ensures correctness.
Expert Assessment
Problem choice: Real and well-motivated. Articulated assets are a genuine bottleneck in robotics and embodied AI—existing datasets are orders of magnitude too small. The problem sits at the intersection of 3D vision, robotics, and program synthesis, which is a productive place to be. Not manufactured.
Method maturity: Clever insight (code generation for structured 3D) executed with solid engineering. The SDK design is the key contribution—it’s not trivial to identify the right abstraction level. Too low-level (raw URDF) and the LLM drowns in details; too high-level (just category names) and you lose diversity. The harness with structured feedback is well-designed. However, the method is somewhat brute-force: it relies on the LLM’s general coding ability rather than learning a 3D-specific prior. A hybrid approach (LLM + learned geometry module) might be more sample-efficient.
Experimental integrity: Baselines are fair (PartNet-Mobility, other procedural generators, general-purpose coding agents like GPT-4 with raw URDF). The human evaluation (quality, diversity, validity) is appropriate since there’s no ground truth for “good articulated asset.” The 10K dataset is impressive in scale. One concern: the paper doesn’t deeply analyze failure modes—what categories does Articraft struggle with? Are there systematic biases (e.g., overrepresentation of simple hinge joints)? The ablation on SDK design is useful but could be more thorough (e.g., impact of test-writing capability).
Writing quality: Clear and well-structured. The SDK design section is excellent. The related work could be tighter—it spends too much time on general text-to-3D methods that aren’t directly comparable. The results section would benefit from more failure analysis and a breakdown of asset complexity (number of parts, joint types) across categories. The supplementary material is thorough.
Verdict: strong accept — Addresses a real problem with a novel and effective method, produces a valuable dataset, and opens a new direction (LLM-based procedural generation with domain SDKs) that will likely inspire follow-up work.
Takeaways
For practitioners building generation systems: The SDK + harness pattern is broadly applicable. If you’re generating structured outputs (code, configs, 3D models, circuits), don’t ask the LLM to produce the raw format directly. Design a domain-specific interface that (1) abstracts low-level details, (2) encodes domain constraints, and (3) enables programmatic validation. Then wrap it in a harness that executes, validates, and returns structured feedback. This is more reliable than end-to-end generation and more scalable than hand-coded rules.
For robotics researchers: Articraft-10K is immediately useful for training manipulation policies, testing sim-to-real transfer, and benchmarking perception systems. The diversity (245 categories) is a step change from PartNet-Mobility (few dozen categories). The programmatic representation means you can generate variations on-the-fly for curriculum learning or domain randomization.
For 3D vision researchers: The result suggests that code is a better intermediate representation than geometry for generation tasks requiring structural constraints. This likely applies beyond articulated assets—architectural layouts, mechanical assemblies, molecular structures. The key is identifying the right SDK primitives for your domain.
Specific technique to steal: The test-writing capability. Letting the LLM write assertions as part of the generation program (e.g., “joint rotates 90 degrees,” “no part exceeds bounding box”) catches errors early and makes the validation loop more efficient. This is underused in program synthesis and could apply to other domains (data pipelines, config generation).
论文: 2605.15187 作者: Matt Zhou, Ruining Li, Xiaoyang Lyu, Zhaomou Song, Zhening Huang, Chuanxia Zheng, Christian Rupprecht, Andrea Vedaldi, Shangzhe Wu 分类: cs.CV, cs.GR, cs.RO
缺口
可动3D资产——带有活动部件的物体,比如门、抽屉或机械臂——对机器人仿真、虚拟现实和训练视觉模型至关重要。
但现有数据集规模很小(几百个物体)且类别狭窄(几个类别)。
手工创建无法规模化。
生成式模型如文本生成3D在处理可动约束时力不从心:关节必须精确对齐,部件不能相互穿透,运动范围必须符合物理规律。
此前的工作要么生成静态网格(无可动性),要么使用手工编码规则的程序化生成(多样性有限,每个类别都需要专家知识)。
核心问题:可动资产生成既需要几何创造力,又需要结构精确性。
神经生成器缺乏后者;基于规则的系统缺乏前者。
问题:需要1万多个多样化的可动资产
   |
   v
现有方法失效:
   |
   +---> 神经生成器:有创造力但结构无效
   |
   +---> 基于规则:有效但狭窄/手工
   |
   v
关键洞察:可动性 = 可执行规范
   |
   v
方法:大语言模型用领域SDK编写程序
   |
   +---> SDK:高层原语(部件、关节、测试)
   |
   +---> 执行框架:验证、返回结构化反馈
   |
   v
证据:1万个资产,245个类别,超越基线
   |
   v
结论:代码生成 > 直接生成(对结构化3D而言)
增量
一句话:这篇论文之前,生成多样化的可动3D资产需要手工建模或狭窄的程序化规则;之后,大语言模型智能体针对领域SDK编写程序,产出了245个类别的1万多个经过验证的资产。
核心机制
Articraft把可动资产生成重新定义为代码生成问题。
它不是让大语言模型直接输出网格坐标或关节参数,而是让大语言模型编写一个Python程序,用领域专用SDK构建资产。
SDK提供高层原语:add_part()定义几何体,add_joint()指定可动性,add_test()验证约束。
大语言模型写程序,执行框架在沙盒环境中执行程序,验证生成的资产(碰撞检查、关节限制、运动学可行性),并返回结构化反馈。
如果验证失败,大语言模型根据反馈修改程序。
这个循环持续到资产通过所有检查或达到重试上限。
SDK抽象掉了底层细节,比如URDF语法或网格文件管理。
大语言模型在”添加一个矩形底座,在这个位置用旋转关节连接一个圆柱形腿”这个层面操作。
执行框架处理渲染、物理验证和错误报告。
关键是,大语言模型可以在程序中编写测试——关于关节范围、无碰撞运动或部件尺寸的断言——执行框架执行这些测试以尽早捕获错误。
用户提示:"生成一个台灯"
   |
   v
大语言模型编写程序:
   base = add_part("cylinder", ...)
   arm = add_part("box", ...)
   joint = add_joint("revolute", base, arm, ...)
   add_test("灯臂旋转180度无碰撞")
   |
   v
执行框架执行程序:
   |
   +---> 几何体实例化
   |
   +---> 关节验证(限制、轴)
   |
   +---> 碰撞检查
   |
   +---> 测试执行
   |
   v
验证结果:
   |
   +---> 通过:返回资产(URDF + 网格)
   |
   +---> 失败:返回结构化错误
             |
             v
          大语言模型修改程序(循环)
把Articraft想象成有工头和检查员的建筑工地。
大语言模型是工头,读取蓝图(用户提示)并用标准化格式编写工单(程序)。
SDK是预制构件集——梁、关节、紧固件——工头可以指定这些构件而不用担心原材料。
执行框架是检查员,检查组装的结构是否符合建筑规范(无碰撞、关节工作、测试通过),如果不符合就发出违规报告。
工头根据检查员的反馈修改工单,直到结构通过检查。
关键洞察:通过限制工头只能使用预制构件,并给检查员明确的检查清单,你既获得了创造力(工头可以设计新颖的结构),又获得了可靠性(检查员确保它们可建造)。
关键概念
- 领域专用SDK:为特定问题领域定制的编程接口,暴露高层操作来封装复杂的底层细节。
在Articraft中,SDK提供像add_part(shape, dimensions, material)和add_joint(type, parent, child, axis, limits)这样的函数。
这与通用3D库(如Blender的Python API)不同,因为它融入了领域知识:关节自动处理坐标系变换,部件有语义标签(底座、把手、盖子),SDK强制执行约束(例如,旋转关节需要一个轴)。
好处:大语言模型不需要知道如何计算旋转矩阵或编写URDF XML;它只需调用add_joint("revolute", ...),SDK处理其余部分。
类比:不是给某人锤子和钉子(底层工具),而是给他们宜家家具,带有标记的部件和说明书(高层接口)。
- 结构化反馈循环:一个验证和修改循环,其中错误以机器可读格式报告,指导下一次迭代。
当Articraft的执行框架检测到碰撞时,它不只是说”检测到碰撞”;它返回\{"error": "collision", "parts": ["arm", "base"], "joint_state": \{...\}\}。
大语言模型使用这些结构化数据来诊断问题(灯臂太长,或关节轴错误)并相应地修改程序。
这比自然语言反馈(“灯臂有问题”)更有效,因为它精确且可操作。
循环在所有验证检查通过或达到重试限制时终止。
这种模式——生成、验证、修改——在程序合成中很常见,但在3D资产生成中是新颖的,大多数系统生成一次就寄希望于最好的结果。
- 程序化资产表示:将3D资产表示为可执行代码而不是数据(网格文件、参数向量)。
台灯不是存储为顶点和面;它存储为一个Python函数,执行时通过调用SDK函数构建台灯。
这有两个优势:(1)可组合性:你可以参数化程序(灯高、臂长)并通过更改参数生成变体。
(2)可解释性:你可以阅读程序来理解资产的结构,这比原始网格更难。
权衡:程序不如网格紧凑,需要执行环境。
但对于生成,程序是更好的中间表示,因为它们暴露了生成过程,使调试和改进更容易。
框架转变
之前(神经/程序化生成):

用户提示 --> [生成器] --> 3D资产
                |
                v
            (黑盒)
            - 神经:有创造力但无效
            - 程序化:有效但狭窄

之后(Articraft):

用户提示 --> [大语言模型] --> 程序(SDK调用)
                               |
                               v
                          [执行框架]
                               |
                               +---> 执行程序
                               |
                               +---> 验证(几何、物理、测试)
                               |
                               +---> 结构化反馈
                               |
                               v
                          有效资产 <-- (如果无效则循环)
从端到端生成到带领域接口的生成-验证-修改,核心转变是将资产创建视为编程任务,大语言模型针对受约束的API编写代码,自动化检查员确保正确性。
专家评审
选题眼光:真实且动机充分。
可动资产确实是机器人学和具身AI的瓶颈——现有数据集规模小了几个数量级。
问题位于3D视觉、机器人学和程序合成的交叉点,这是一个富有成效的位置。
不是人造缺口。
方法成熟度:巧妙的洞察(结构化3D的代码生成)加上扎实的工程执行。
SDK设计是关键贡献——识别正确的抽象层次并非易事。
太底层(原始URDF)大语言模型会淹没在细节中;太高层(只有类别名)会失去多样性。
带结构化反馈的执行框架设计良好。
然而,方法有些蛮力:它依赖大语言模型的通用编码能力,而不是学习3D特定的先验。
混合方法(大语言模型 + 学习的几何模块)可能更样本高效。
实验诚意:基线公平(PartNet-Mobility、其他程序化生成器、通用编码智能体如带原始URDF的GPT-4)。
人类评估(质量、多样性、有效性)是合适的,因为”好的可动资产”没有真值。
1万个数据集的规模令人印象深刻。
一个担忧:论文没有深入分析失败模式——Articraft在哪些类别上挣扎?是否存在系统性偏差(例如,简单铰链关节的过度表示)?SDK设计的消融实验有用但可以更彻底(例如,测试编写能力的影响)。
写作功力:清晰且结构良好。
SDK设计部分很出色。
相关工作可以更紧凑——它在不直接可比的通用文本生成3D方法上花了太多时间。
结果部分将受益于更多失败分析和跨类别的资产复杂度分解(部件数量、关节类型)。
补充材料很详尽。
判决:强接收 — 用新颖有效的方法解决真实问题,产出有价值的数据集,并开辟了新方向(带领域SDK的基于大语言模型的程序化生成),可能会激发后续工作。
要点总结
对于构建生成系统的实践者:SDK + 执行框架模式广泛适用。
如果你在生成结构化输出(代码、配置、3D模型、电路),不要让大语言模型直接产生原始格式。
设计一个领域专用接口,它(1)抽象底层细节,(2)编码领域约束,(3)启用程序化验证。
然后用执行框架包装它,执行、验证并返回结构化反馈。
这比端到端生成更可靠,比手工编码规则更可扩展。
对于机器人研究者:Articraft-10K可立即用于训练操作策略、测试仿真到现实的迁移以及基准感知系统。
多样性(245个类别)是相对PartNet-Mobility(几十个类别)的阶跃变化。
程序化表示意味着你可以即时生成变体,用于课程学习或领域随机化。
对于3D视觉研究者:结果表明,对于需要结构约束的生成任务,代码是比几何更好的中间表示。
这可能适用于可动资产之外——建筑布局、机械装配、分子结构。
关键是为你的领域识别正确的SDK原语。
可窃取的具体技术:测试编写能力。
让大语言模型在生成程序中编写断言(例如,“关节旋转90度”,“没有部件超出边界框”)可以尽早捕获错误,使验证循环更高效。
这在程序合成中使用不足,可以应用于其他领域(数据管道、配置生成)。