Paper: 2605.03989 Authors: Dutao Zhang, Tian Liao Categories: cs.AI
The Gap
RAG systems typically commit to one retrieval pipeline at design time. You pick BM25, or dense retrieval, or hybrid, and that’s what every query gets. But factoid questions want keyword matching, multi-hop reasoning needs iterative retrieval, and scientific claims demand citation-aware search. Adaptive-RAG introduced query-time routing, but it’s still a monolithic component baked into the workflow. The gap: retrieval strategy selection is treated as infrastructure plumbing rather than a modular capability an agent can learn and reuse.
Problem: One retrieval pipeline for all tasks
   |
   v
Assumption: Different tasks need different retrieval strategies
   |
   v
Method: Pluggable skill layer that selects strategies via experience memory
   |
   v
Evidence: nDCG@10 = 0.8924 across factoid/multi-hop/scientific tasks
   |
   v
Conclusion: Strategy selection can be encapsulated as reusable agent skill
The Increment
One sentence: Before this paper, retrieval strategy was infrastructure you configured; after, it’s a skill an agent can learn and swap in.
Core Mechanism
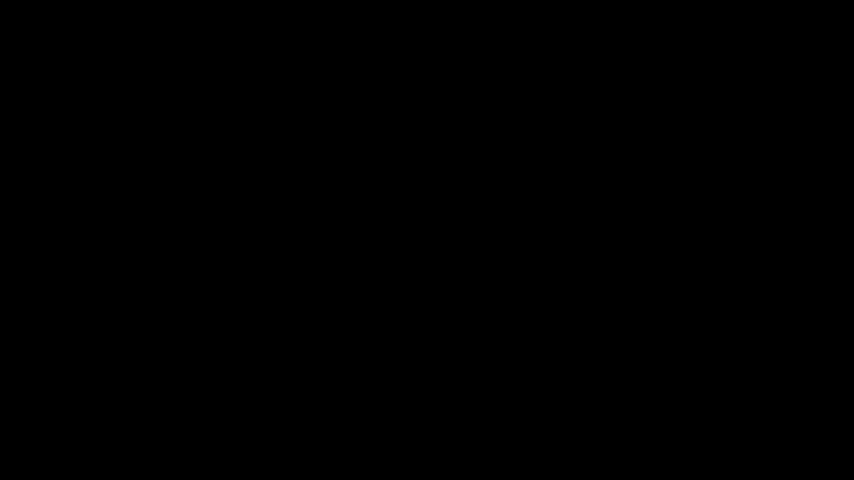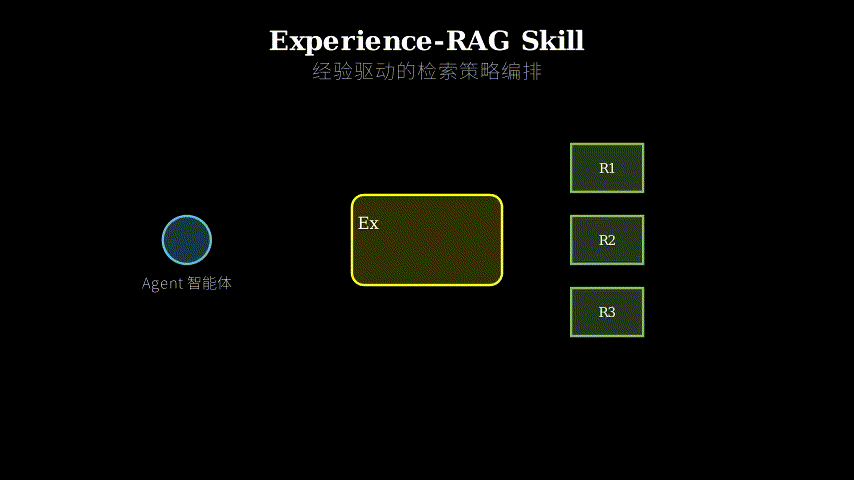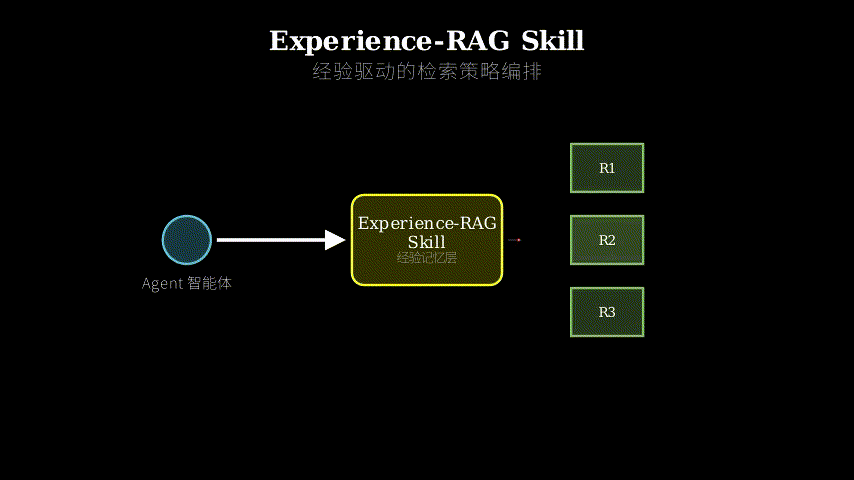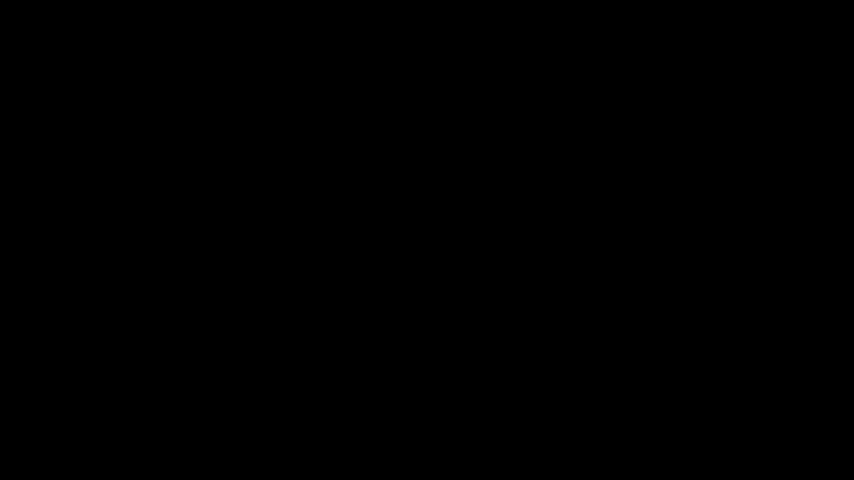
Experience-RAG Skill sits between the agent and a pool of retrievers. When a query arrives, the skill analyzes the “scene” (task type, query structure, domain), consults an experience memory of past strategy-performance pairs, selects a retrieval strategy, executes it against the retriever pool, and returns structured evidence to the agent. The experience memory is a lookup table: given scene features, which strategy worked before?
The skill doesn’t invent new retrievers. It orchestrates existing ones. The retriever pool might contain BM25, dense retrieval, hybrid search, or iterative multi-hop methods. The skill’s job is pattern matching: “This looks like a multi-hop question, last time we used iterative retrieval and it worked, let’s do that again.”
Agent query
    |
    v
+-------------------+
| Experience-RAG    |
| Skill             |
|                   |
| 1. Scene analysis |<--- (task type, query structure)
| 2. Memory lookup  |<--- (experience: scene -> strategy)
| 3. Strategy pick  |
+-------------------+
    |
    v
Retriever pool (BM25 | Dense | Hybrid | Iterative)
    |
    v
Structured evidence -> Agent
Think of it like a restaurant kitchen. The agent is the head chef who decides what dish to make. The retrievers are specialized stations: grill, sauté, pastry. Experience-RAG Skill is the sous chef who’s worked every station and knows which one to send each order to. A steak? Grill. A soufflé? Pastry. The sous chef doesn’t cook—they route based on pattern recognition from past service. The head chef doesn’t need to know which station handles what; they just ask the sous chef and get back prepped ingredients. The skill encapsulates routing logic so the agent can focus on reasoning, not retrieval plumbing.
Key Concepts
-
Scene: The task context that determines retrieval needs. A scene isn’t just the query text—it’s the inferred task type (factoid vs multi-hop vs verification), domain (news vs science), and structural cues (question length, entity count). Scene analysis is lightweight classification: “Does this query have multiple entities and a causal connector? Probably multi-hop.” The skill doesn’t need perfect classification; it needs enough signal to distinguish retrieval preferences.
-
Experience Memory: A mapping from scenes to strategies, built from past performance. Not a neural network—just a table. “For multi-hop science questions, iterative retrieval got nDCG 0.91 last time.” When a new query arrives, the skill finds the closest past scene and reuses its strategy. The memory grows over time as the agent encounters new task types. It’s collaborative filtering for retrieval: what worked for similar queries?
-
Pluggable Skill: A modular capability the agent can invoke without knowing its internals. The agent calls
retrieve(query)and gets back evidence. Whether that evidence came from BM25 or iterative search is hidden. The skill interface is stable even as the retriever pool changes. You can add a new retriever, update the experience memory, and the agent’s code doesn’t change. This is the key architectural move: retrieval strategy becomes a black-box service, not tangled logic in the agent’s control flow.
Framework Shift
Before (mainstream approach):        After (this paper):

Agent                                Agent
  |                                    |
  | (hard-coded strategy)              | retrieve(query)
  v                                    v
Single retriever pipeline            Experience-RAG Skill
  |                                    |
  v                                    | (scene analysis + memory lookup)
Evidence                               v
                                     Retriever pool
                                       |
                                       v
                                     Evidence
From monolithic retrieval pipeline to modular skill layer, the core shift is treating strategy selection as a learned, reusable capability rather than design-time configuration.
Expert Assessment
Problem choice: Real gap. RAG systems do struggle with heterogeneous tasks, and hard-coding strategy selection into agent logic is brittle. The framing as a “skill” is clever—it aligns with the agent-oriented architecture trend and makes the contribution feel like a design pattern, not just another routing method.
Method maturity: Mostly engineering, not algorithmic novelty. Scene analysis is heuristic classification, experience memory is a lookup table, and the retriever pool is off-the-shelf. The insight is architectural: encapsulation matters. But the paper doesn’t explore how the experience memory is built (manual annotation? online learning?) or how it generalizes to unseen scenes. The “experience” framing suggests learning, but the implementation seems closer to a hand-tuned dispatch table.
Experimental integrity: Baselines are fair (single retrievers, Adaptive-RAG), and nDCG@10 of 0.8924 is solid. But the evaluation is limited to three BeIR tasks. No ablation on scene analysis quality, no failure case analysis, no comparison of memory update strategies. The claim that this “remains competitive with Adaptive-RAG” undersells it—if they’re tied, why is the skill framing better? The paper needs to show where encapsulation pays off beyond raw performance.
Writing quality: The abstract and intro are crisp, but the method section is vague. How exactly is scene analysis implemented? What features go into the memory lookup? The paper reads like a position statement with preliminary results rather than a complete system description. Section 3 (Method) should be twice as long with concrete algorithms and data structures.
Verdict: weak accept — The architectural insight (retrieval strategy as pluggable skill) is valuable and the results are promising, but the paper needs deeper technical exposition and broader evaluation to be convincing.
Takeaways
The core idea transfers: encapsulate strategy selection as a reusable module with a stable interface. If you’re building any system where different subtasks need different tools (code generation with multiple LLMs, data pipelines with multiple transforms, UI rendering with multiple frameworks), don’t hard-code the dispatch logic into the orchestrator. Build a “skill” layer that maps task characteristics to tool choices, and let that layer evolve independently. The experience memory pattern is also portable: maintain a lightweight lookup table of (context, tool, performance) triples and use nearest-neighbor matching for new contexts. It’s not fancy, but it decouples tool selection from business logic, which is often the right move.
论文: 2605.03989 作者: Dutao Zhang, Tian Liao 分类: cs.AI
缺口
RAG 系统通常在设计时就固定了一条检索管道。
你选择 BM25、密集检索或混合检索,然后所有查询都走这条路。
但事实性问题需要关键词匹配,多跳推理需要迭代检索,科学声明验证需要引用感知搜索。
Adaptive-RAG 引入了查询时路由,但它仍是烘焙在工作流中的单体组件。
缺口在于:检索策略选择被当作基础设施管道,而非智能体可以学习和复用的模块化能力。
问题:所有任务用一条检索管道
   |
   v
假设:不同任务需要不同检索策略
   |
   v
方法:通过经验记忆选择策略的可插拔技能层
   |
   v
证据:在事实性/多跳/科学任务上 nDCG@10 = 0.8924
   |
   v
结论:策略选择可封装为可复用的智能体技能
增量
一句话: 这篇论文之前,检索策略是你配置的基础设施;
之后,它是智能体可以学习和替换的技能。
核心机制
Experience-RAG Skill 位于智能体和检索器池之间。
当查询到达时,技能分析”场景”(任务类型、查询结构、领域),查询过往策略-性能对的经验记忆,选择检索策略,在检索器池中执行,并向智能体返回结构化证据。
经验记忆是一张查找表:给定场景特征,之前哪个策略有效?
技能不发明新检索器。
它编排现有检索器。
检索器池可能包含 BM25、密集检索、混合搜索或迭代多跳方法。
技能的工作是模式匹配:“这看起来像多跳问题,上次我们用迭代检索成功了,这次再来一遍。”
智能体查询
    |
    v
+-------------------+
| Experience-RAG    |
| Skill             |
|                   |
| 1. 场景分析       |<--- (任务类型、查询结构)
| 2. 记忆查找       |<--- (经验:场景 -> 策略)
| 3. 策略选择       |
+-------------------+
    |
    v
检索器池 (BM25 | 密集 | 混合 | 迭代)
    |
    v
结构化证据 -> 智能体
把它想象成餐厅厨房。
智能体是主厨,决定做什么菜。
检索器是专门工位:烤架、炒锅、烘焙。
Experience-RAG Skill 是副厨,干过所有工位,知道每个订单该送到哪里。
牛排?
烤架。
舒芙蕾?
烘焙。
副厨不做菜——他们根据过往服务的模式识别来路由。
主厨不需要知道哪个工位处理什么;
他们只需问副厨,拿回处理好的食材。
技能封装了路由逻辑,让智能体专注于推理,而非检索管道。
关键概念
- 场景(Scene): 决定检索需求的任务上下文。
场景不只是查询文本——它是推断出的任务类型(事实性 vs 多跳 vs 验证)、领域(新闻 vs 科学)和结构线索(问题长度、实体数量)。
场景分析是轻量级分类:“这个查询有多个实体和因果连接词吗?
可能是多跳。”
技能不需要完美分类;
它需要足够的信号来区分检索偏好。
- 经验记忆(Experience Memory): 从场景到策略的映射,由过往性能构建。
不是神经网络——只是一张表。
“对于多跳科学问题,迭代检索上次得到 nDCG 0.91。”
当新查询到达时,技能找到最接近的过往场景并复用其策略。
记忆随着智能体遇到新任务类型而增长。
这是检索的协同过滤:对类似查询有效的方法是什么?
- 可插拔技能(Pluggable Skill): 智能体可以调用而无需了解其内部的模块化能力。
智能体调用 retrieve(query) 并获得证据。
这些证据来自 BM25 还是迭代搜索是隐藏的。
即使检索器池变化,技能接口也保持稳定。
你可以添加新检索器,更新经验记忆,而智能体的代码不变。
这是关键的架构举措:检索策略成为黑盒服务,而非纠缠在智能体控制流中的逻辑。
框架转变
之前(主流方法):                之后(本文方法):

智能体                            智能体
  |                                 |
  | (硬编码策略)                    | retrieve(query)
  v                                 v
单一检索管道                      Experience-RAG Skill
  |                                 |
  v                                 | (场景分析 + 记忆查找)
证据                                v
                                  检索器池
                                    |
                                    v
                                  证据
从单体检索管道到模块化技能层,核心转变是将策略选择视为可学习、可复用的能力,而非设计时配置。
专家评审
选题眼光: 真实缺口。
RAG 系统确实在异构任务上挣扎,将策略选择硬编码到智能体逻辑中很脆弱。
将其框定为”技能”很聪明——它与面向智能体的架构趋势对齐,让贡献感觉像设计模式,而非又一个路由方法。
方法成熟度: 主要是工程,非算法创新。
场景分析是启发式分类,经验记忆是查找表,检索器池是现成的。
洞见在于架构:封装很重要。
但论文没有探讨经验记忆如何构建(人工标注?
在线学习?)或如何泛化到未见场景。
“经验”框架暗示学习,但实现似乎更接近手工调优的调度表。
实验诚意: 基线公平(单一检索器、Adaptive-RAG),nDCG@10 为 0.8924 很扎实。
但评估仅限于三个 BeIR 任务。
没有场景分析质量的消融,没有失败案例分析,没有记忆更新策略的比较。
声称”与 Adaptive-RAG 保持竞争力”低估了自己——如果打平,为什么技能框架更好?
论文需要展示封装在原始性能之外的回报。
写作功力: 摘要和引言简洁,但方法部分含糊。
场景分析具体如何实现?
记忆查找用什么特征?
论文读起来像带初步结果的立场声明,而非完整系统描述。
第 3 节(方法)应该长一倍,包含具体算法和数据结构。
判决: 弱接收 — 架构洞见(检索策略作为可插拔技能)有价值,结果有希望,但论文需要更深入的技术阐述和更广泛的评估才能令人信服。
要点总结
核心思想可迁移:将策略选择封装为具有稳定接口的可复用模块。
如果你在构建任何系统,其中不同子任务需要不同工具(用多个 LLM 生成代码、用多个转换的数据管道、用多个框架的 UI 渲染),不要将调度逻辑硬编码到编排器中。
构建一个”技能”层,将任务特征映射到工具选择,让该层独立演化。
经验记忆模式也可移植:维护一个轻量级的(上下文、工具、性能)三元组查找表,对新上下文使用最近邻匹配。
不花哨,但它将工具选择与业务逻辑解耦,这通常是正确的举措。