Paper: 2602.21201 Authors: Tony Feng, Junehyuk Jung, Sang-hyun Kim, Carlo Pagano, Sergei Gukov, Chiang-Chiang Tsai, David Woodruff, Adel Javanmard, Aryan Mokhtari, Dawsen Hwang Categories: cs.AI, cs.CL, cs.LG
Abstract
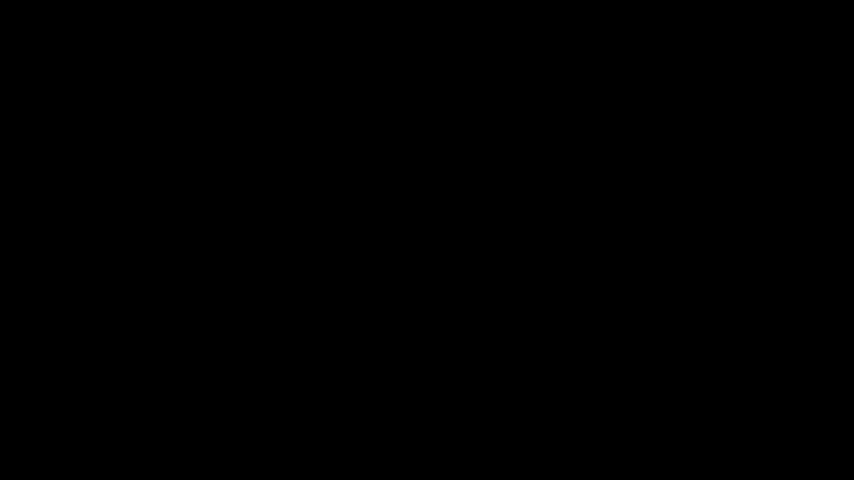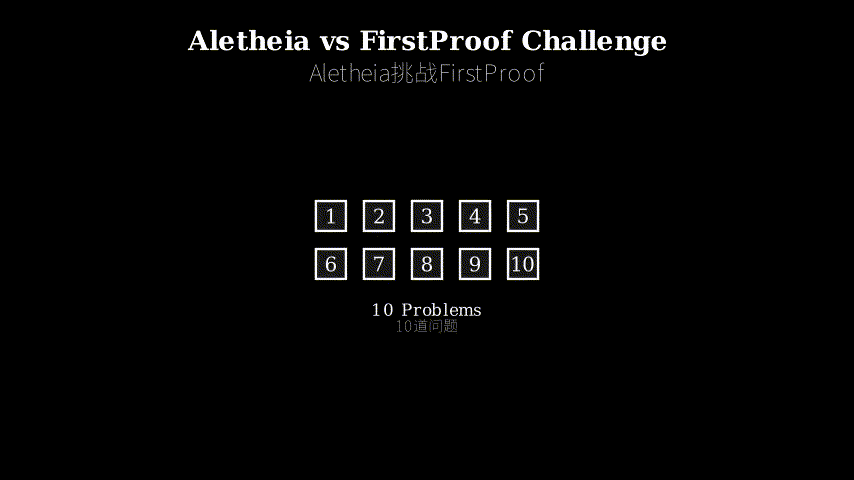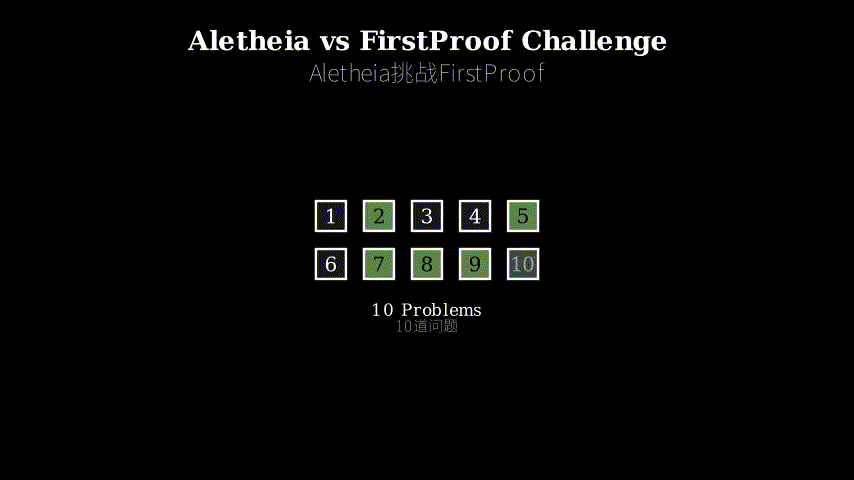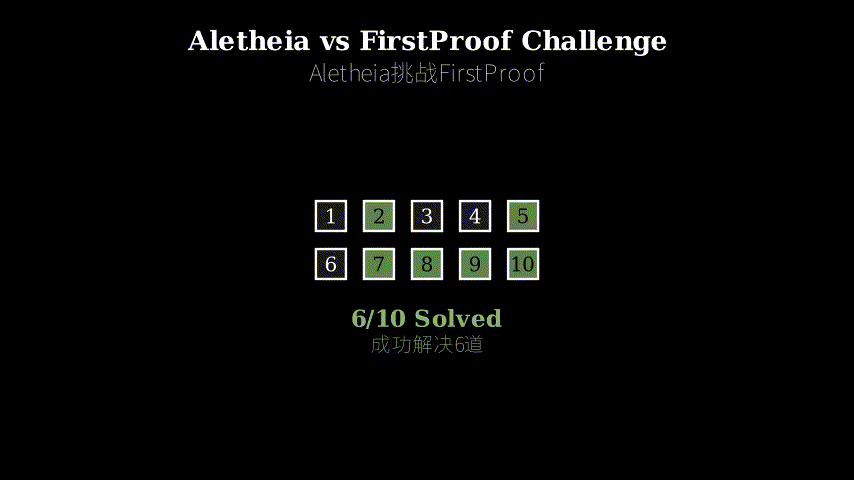
This paper presents the performance evaluation of Aletheia, a mathematics research agent powered by Gemini 3 Deep Think, on the inaugural FirstProof challenge. The challenge consisted of 10 mathematical research problems that required autonomous problem-solving capabilities. Aletheia successfully solved 6 problems (specifically problems 2, 5, 7, 8, 9, and 10) within the competition timeframe, as assessed by a majority of expert evaluators. The authors note that Problem 8 was the only case where expert consensus was not unanimous. The paper emphasizes transparency by providing detailed explanations of their interpretation of the FirstProof challenge, experimental methodology, and evaluation procedures. All raw prompts and outputs have been made publicly available on GitHub for reproducibility and further analysis.
Key Contributions
- Demonstrated autonomous mathematical problem-solving at research level, achieving a 60% success rate on the FirstProof challenge
- Leveraged Gemini 3 Deep Think’s advanced reasoning capabilities to tackle open-ended mathematical research problems
- Provided full transparency with publicly available prompts, outputs, and evaluation methodology
- Established a benchmark for AI agents in mathematical research, with detailed documentation of both successes and limitations
- Contributed to the understanding of AI capabilities in formal mathematical reasoning and proof generation
System Architecture and Methodology
Aletheia represents a significant advancement in AI-driven mathematical research agents. Built on top of Gemini 3 Deep Think, the system is designed to autonomously approach mathematical problems that typically require human-level research capabilities. The architecture integrates several key components:
The core reasoning engine utilizes Gemini 3 Deep Think’s extended thinking capabilities, allowing the system to engage in prolonged deliberation and exploration of mathematical concepts. This is crucial for research-level problems that cannot be solved through pattern matching or simple heuristics alone.
The agent operates autonomously within the FirstProof challenge framework, meaning it must interpret problem statements, formulate approaches, generate proofs or solutions, and verify its work without human intervention during the solving process. This end-to-end autonomy distinguishes Aletheia from systems that require human guidance or interactive refinement.
The experimental setup adhered strictly to the FirstProof challenge constraints, including time limits and resource allocations. The authors emphasize their interpretation of the challenge rules and how they configured Aletheia to operate within these boundaries, ensuring fair comparison with other potential approaches.
Results and Performance Analysis
Aletheia’s performance on the FirstProof challenge reveals both the capabilities and current limitations of AI in mathematical research:
Successful Problems (2, 5, 7, 8, 9, 10): The agent demonstrated strong performance across 60% of the challenge problems. These successes span different mathematical domains and problem types, suggesting that Aletheia’s capabilities are not narrowly specialized but rather exhibit some degree of generalization across mathematical reasoning tasks.
Problem 8 - Contested Assessment: Interestingly, Problem 8 was the only case where expert evaluators did not reach unanimous consensus on whether Aletheia’s solution was correct. This highlights an important aspect of research-level mathematics: even human experts may disagree on the validity or completeness of certain proofs or solutions. This ambiguity is characteristic of frontier mathematical research and represents a challenge for both AI systems and their evaluation.
Failed Problems (1, 3, 4, 6): The four problems that Aletheia did not solve represent important areas for future improvement. While the paper does not provide detailed analysis of these failures, they likely indicate specific types of mathematical reasoning or problem structures that remain challenging for current AI systems.
The 60% success rate is particularly impressive given that these are research-level problems designed to challenge the boundaries of AI mathematical capabilities. This performance suggests that AI agents are approaching a threshold where they can meaningfully contribute to mathematical research, though significant gaps remain.
Implications for AI and Mathematical Research
The results presented in this paper have several important implications for the future of AI in mathematics and scientific research more broadly:
Autonomous Research Capabilities: Aletheia’s performance demonstrates that AI systems can now tackle open-ended research problems with minimal human intervention. This represents a qualitative shift from previous systems that primarily assisted human mathematicians or solved well-defined problems with clear solution paths.
Transparency and Reproducibility: The authors’ commitment to full transparency, including public release of all prompts and outputs, sets an important precedent for AI research. This level of openness enables the community to scrutinize the system’s reasoning, identify failure modes, and build upon this work. The availability of raw data at the GitHub repository allows for independent verification and analysis.
Evaluation Challenges: The disagreement among experts on Problem 8 highlights the difficulty of evaluating AI systems on research-level tasks. Unlike benchmark problems with known solutions, research problems may have multiple valid approaches or solutions that are difficult to assess definitively. This suggests that future AI evaluation frameworks for mathematical research will need to incorporate mechanisms for handling ambiguity and expert disagreement.
Hybrid Human-AI Research: While Aletheia operates autonomously, the most promising path forward likely involves collaboration between AI systems and human mathematicians. AI agents like Aletheia could explore large solution spaces, generate candidate proofs, or identify promising research directions, while humans provide high-level guidance, intuition, and final verification.
Takeaways
-
Aletheia achieved a 60% success rate (6/10 problems) on the FirstProof challenge, demonstrating significant progress in autonomous mathematical reasoning at research level.
-
The system is powered by Gemini 3 Deep Think, leveraging advanced reasoning capabilities to tackle open-ended mathematical problems without human intervention during solving.
-
Problem 8 revealed evaluation challenges in AI mathematical research, as expert assessors did not reach unanimous consensus on the solution’s validity.
-
Full transparency is provided through public release of all prompts and outputs on GitHub, enabling community scrutiny and reproducibility.
-
The results suggest AI agents are approaching a threshold where they can meaningfully contribute to mathematical research, though significant challenges remain in the 40% of unsolved problems.
-
This work establishes an important benchmark for future AI systems in mathematical research and highlights the need for robust evaluation frameworks that can handle ambiguity in research-level problems.
论文: 2602.21201 作者: Tony Feng, Junehyuk Jung, Sang-hyun Kim, Carlo Pagano, Sergei Gukov, Chiang-Chiang Tsai, David Woodruff, Adel Javanmard, Aryan Mokhtari, Dawsen Hwang 分类: cs.AI, cs.CL, cs.LG
摘要
本文展示了由Gemini 3 Deep Think驱动的数学研究智能体Aletheia在首届FirstProof挑战赛中的表现评估。该挑战赛包含10道需要自主问题解决能力的数学研究问题。Aletheia在竞赛时间范围内成功解决了6道问题(具体为第2、5、7、8、9、10题),这一结果得到了大多数专家评估者的认可。作者指出,第8题是唯一一道专家未达成一致共识的问题。论文强调透明度,详细解释了他们对FirstProof挑战的理解、实验方法论和评估程序。所有原始提示词和输出结果已在GitHub上公开,以便复现和进一步分析。
主要贡献
- 展示了研究级别的自主数学问题解决能力,在FirstProof挑战中达到60%的成功率
- 利用Gemini 3 Deep Think的高级推理能力来处理开放式数学研究问题
- 通过公开提示词、输出和评估方法提供完全透明度
- 为数学研究中的AI智能体建立基准,详细记录成功和局限性
- 促进了对AI在形式化数学推理和证明生成方面能力的理解
系统架构与方法论
Aletheia代表了AI驱动数学研究智能体的重大进展。该系统构建在Gemini 3 Deep Think之上,旨在自主处理通常需要人类级别研究能力的数学问题。架构集成了几个关键组件:
核心推理引擎利用Gemini 3 Deep Think的扩展思考能力,使系统能够进行长时间的深思熟虑和数学概念探索。这对于无法通过模式匹配或简单启发式方法解决的研究级问题至关重要。
该智能体在FirstProof挑战框架内自主运行,这意味着它必须解释问题陈述、制定方法、生成证明或解决方案,并在求解过程中无需人工干预即可验证其工作。这种端到端的自主性使Aletheia区别于需要人类指导或交互式改进的系统。
实验设置严格遵守FirstProof挑战的约束条件,包括时间限制和资源分配。作者强调了他们对挑战规则的解释,以及如何配置Aletheia在这些边界内运行,确保与其他潜在方法的公平比较。
结果与性能分析
Aletheia在FirstProof挑战中的表现揭示了AI在数学研究中的能力和当前局限性:
成功解决的问题(2、5、7、8、9、10): 该智能体在60%的挑战问题上表现出色。这些成功跨越不同的数学领域和问题类型,表明Aletheia的能力并非狭隘专业化,而是在数学推理任务中展现出一定程度的泛化能力。
第8题-有争议的评估: 有趣的是,第8题是唯一一道专家评估者未达成一致共识的问题。这突显了研究级数学的一个重要方面:即使是人类专家也可能对某些证明或解决方案的有效性或完整性存在分歧。这种模糊性是前沿数学研究的特征,对AI系统及其评估都构成挑战。
未解决的问题(1、3、4、6): Aletheia未能解决的四道问题代表了未来改进的重要领域。虽然论文没有提供这些失败的详细分析,但它们可能表明某些类型的数学推理或问题结构对当前AI系统仍具挑战性。
考虑到这些是旨在挑战AI数学能力边界的研究级问题,60%的成功率尤其令人印象深刻。这一表现表明AI智能体正在接近一个阈值,在这个阈值上它们可以有意义地为数学研究做出贡献,尽管仍存在显著差距。
对AI和数学研究的影响
本文呈现的结果对AI在数学和更广泛的科学研究中的未来具有几个重要影响:
自主研究能力: Aletheia的表现表明,AI系统现在可以在最少人工干预的情况下处理开放式研究问题。这代表了从以前主要协助人类数学家或解决具有明确解决路径的明确定义问题的系统的质的转变。
透明度和可复现性: 作者对完全透明的承诺,包括公开发布所有提示词和输出,为AI研究树立了重要先例。这种开放程度使社区能够审查系统的推理、识别失败模式并在此工作基础上继续发展。GitHub仓库中原始数据的可用性允许独立验证和分析。
评估挑战: 专家在第8题上的分歧突显了在研究级任务上评估AI系统的难度。与具有已知解决方案的基准问题不同,研究问题可能有多种有效方法或难以明确评估的解决方案。这表明未来用于数学研究的AI评估框架需要纳入处理模糊性和专家分歧的机制。
人机混合研究: 虽然Aletheia自主运行,但最有前景的前进道路可能涉及AI系统与人类数学家之间的协作。像Aletheia这样的AI智能体可以探索大型解空间、生成候选证明或识别有前景的研究方向,而人类提供高层次指导、直觉和最终验证。
要点总结
-
Aletheia在FirstProof挑战中达到60%的成功率(6/10题),展示了研究级别自主数学推理的重大进展。
-
该系统由Gemini 3 Deep Think驱动,利用高级推理能力在求解过程中无需人工干预即可处理开放式数学问题。
-
第8题揭示了AI数学研究中的评估挑战,因为专家评估者未就解决方案的有效性达成一致共识。
-
通过在GitHub上公开发布所有提示词和输出提供完全透明度,使社区能够进行审查和复现。
-
结果表明AI智能体正在接近一个阈值,在这个阈值上它们可以有意义地为数学研究做出贡献,尽管在40%未解决问题中仍存在重大挑战。
-
这项工作为未来数学研究中的AI系统建立了重要基准,并强调需要能够处理研究级问题中模糊性的稳健评估框架。