Paper: 2605.06651 Authors: Daniel Zheng, Ingrid von Glehn, Yori Zwols, Iuliya Beloshapka, Lars Buesing, Daniel M. Roy, Martin Wattenberg, Bogdan Georgiev, Tatiana Schmidt, Andrew Cowie Categories: cs.AI
The Gap
Existing AI for mathematics has focused on narrow tasks: theorem proving (Lean, Coq), symbolic computation (Mathematica), or benchmark problem-solving. These tools treat mathematics as a linear pipeline—state a conjecture, prove it, done. But real mathematical research is exploratory and iterative: you chase hunches, hit dead ends, pivot based on computational experiments, search literature for related work, and refine vague intuitions into precise statements. Current AI systems don’t support this messy, asynchronous workflow. They’re calculators, not collaborators.
The gap: no system provides holistic support for the full research cycle—ideation, literature search, computational exploration, theorem proving, and theory building—while managing uncertainty, tracking failed attempts, and maintaining state across sessions.
Problem: Math research is exploratory          Assumption: AI can mirror human
         and iterative, not linear                        collaborative workflow
                |                                                |
                v                                                v
         Current AI: task-specific            Method: Stateful workbench with
         tools (provers, CAS)          -->    async agents + uncertainty mgmt
                                                               |
                                                               v
                                              Evidence: 48% on FrontierMath Tier 4
                                                       + open problem solutions
                                                               |
                                                               v
                                              Conclusion: AI can be research
                                                         partner, not just tool
The Increment
One sentence: Before this paper, AI helped mathematicians solve stated problems; after, AI helps mathematicians discover what problems to solve.
Core Mechanism
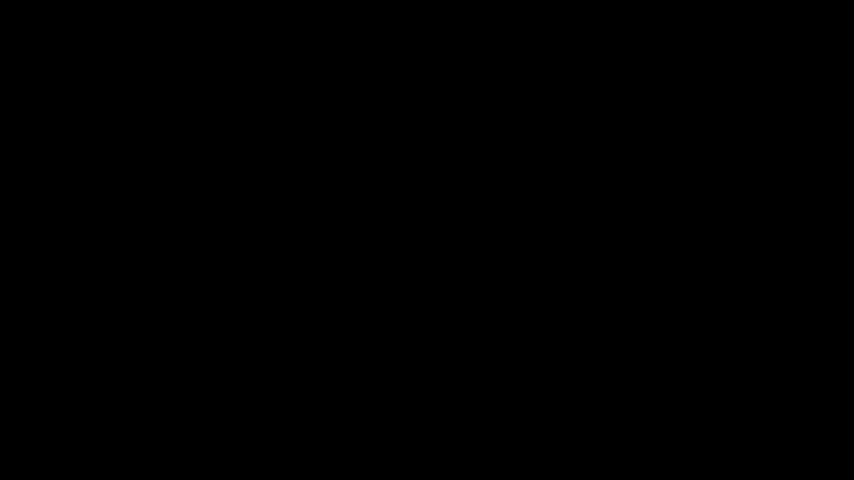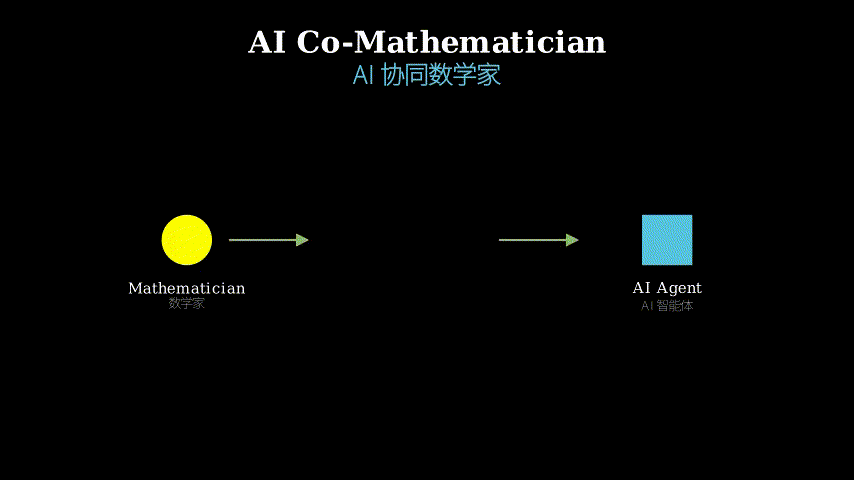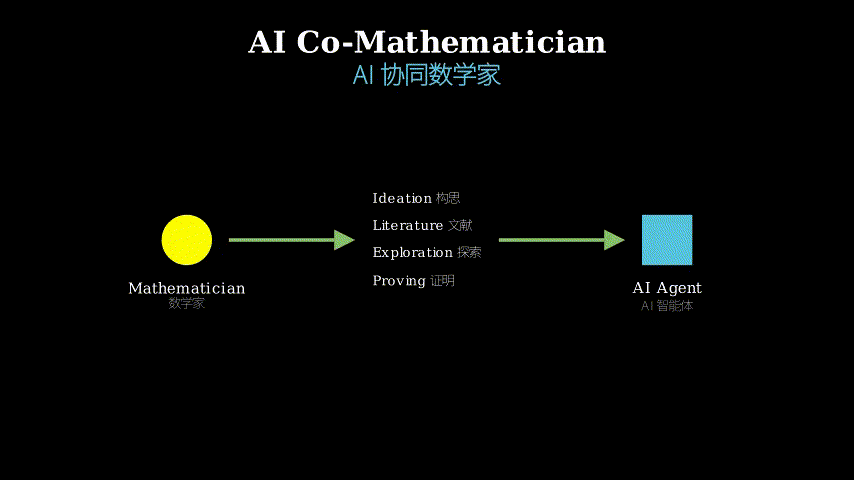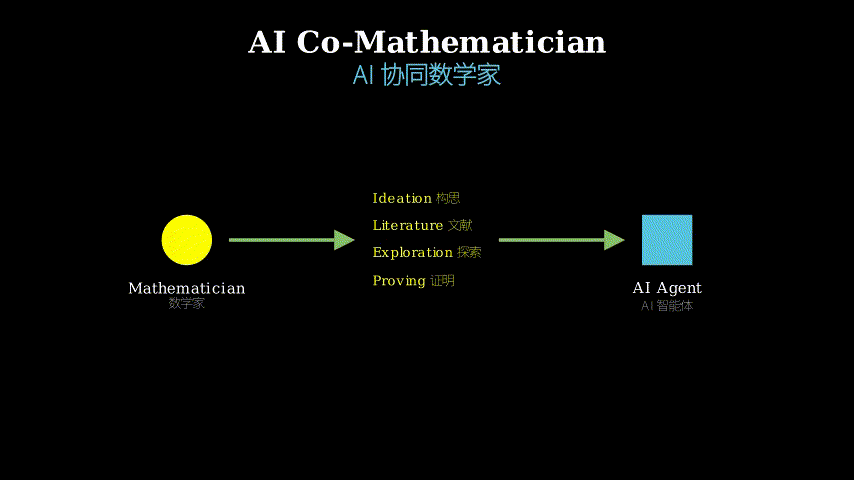
The AI co-mathematician is a stateful workspace where multiple AI agents operate asynchronously on behalf of the user. When you give it a vague research direction, it spawns agents to explore different angles: one searches literature, another runs computational experiments, a third attempts formal proofs. Each agent maintains its own state and can run for hours or days. The system tracks hypotheses, records failures (so you don’t repeat them), and refines your intent through interaction.
The workspace outputs native mathematical artifacts: Lean proofs, computational notebooks, literature summaries, conjectures with supporting evidence. Agents communicate through a shared context that includes your research notes, previous attempts, and domain knowledge. When an agent hits uncertainty (ambiguous notation, multiple interpretations), it flags the issue and asks for clarification rather than guessing.
User intent (vague)
        |
        v
   [Workspace State]
        |
        +---> Agent 1: Literature search -----> Papers, references
        |
        +---> Agent 2: Computation -----------> Numerical evidence
        |
        +---> Agent 3: Theorem proving -------> Lean proofs
        |
        +---> Agent 4: Theory building -------> Conjectures
        |
        v
   [Shared Context]
   - Research notes
   - Failed hypotheses
   - Refined intent
        |
        v
   Mathematical artifacts
   (proofs, notebooks, summaries)
Think of it like a research group where you’re the PI. You give a broad direction at a Monday meeting. Your grad students (agents) go off and work independently—one hits the library, another runs simulations, a third tries to formalize something in Lean. They don’t need you to micromanage every step. On Friday, they report back with results, questions, and dead ends. You refine the direction based on what worked, and the cycle continues. The key difference from a single AI assistant: parallelism, persistence, and memory of what didn’t work.
Key Concepts
-
Stateful workspace: Most AI interactions are stateless—each query starts from scratch. A stateful workspace remembers everything: your research notes, previous conversations, failed attempts, computational results. It’s like having a lab notebook that never closes. When you return after a week, the system knows where you left off and what you’ve already tried. This persistence is critical for research, where insights emerge over months, not minutes.
-
Asynchronous agents: Instead of waiting for one task to finish before starting the next, agents run in parallel and report back when done. If literature search takes 10 minutes and a proof attempt takes 2 hours, you don’t sit idle. The system manages multiple threads of exploration simultaneously, just like a human researcher juggling several subproblems. Agents can also run overnight or across sessions—you check in when convenient.
-
Uncertainty management: When an agent encounters ambiguity (e.g., “Does ‘smooth’ mean C^1 or C^∞?”), it doesn’t guess or hallucinate. It flags the uncertainty, presents options, and waits for clarification. This prevents the system from confidently pursuing the wrong interpretation. It’s the difference between a collaborator who asks “What did you mean by X?” and one who assumes and wastes a week on the wrong problem.
Framework Shift
Before (task-specific tools):        After (AI co-mathematician):

User: "Prove theorem X"              User: "I'm interested in property Y"
  |                                    |
  v                                    v
[Theorem Prover]                     [Workspace spawns agents]
  |                                    |
  v                                    +---> Literature
Success or failure                     +---> Computation
                                       +---> Proving
(One-shot, stateless)                  +---> Theory building
                                       |
                                       v
                                     [Shared context tracks progress]
                                       |
                                       v
                                     Artifacts + refined questions

                                     (Iterative, stateful, exploratory)
From single-task execution to multi-threaded exploration, the core shift is treating AI as a research partner that manages its own subgoals rather than a tool that executes your commands.
Expert Assessment
Problem choice: This is a real gap. Anyone who’s done mathematical research knows the pain of context-switching between Lean, Mathematica, Google Scholar, and scratch paper. The field has been stuck in “AI for X” mode (AI for theorem proving, AI for symbolic math) rather than “AI for research.” The timing is right—foundation models are finally capable enough to handle the reasoning required.
Method maturity: The architecture is sound but not groundbreaking. Stateful workspaces and asynchronous agents are well-understood in software engineering. The novelty is in the application and integration, not the underlying techniques. That said, the uncertainty management is clever—most systems either hallucinate or refuse to act, but flagging ambiguity and asking for clarification is the right middle ground.
Experimental integrity: The 48% on FrontierMath Tier 4 is impressive and verifiable. The open problem anecdotes are compelling but anecdotal—we don’t know how many problems were attempted vs solved. The paper would be stronger with failure rate analysis and a breakdown of where the system struggles. Baselines are fair (comparing to other AI systems on the same benchmark), but there’s no comparison to human mathematicians’ workflows, which would be the real test.
Writing quality: The abstract and introduction are strong. The technical sections are vague—how exactly do agents communicate? What’s the prompt structure? How is uncertainty represented? The paper reads like a product announcement more than a research contribution. Section 3 (system architecture) needs to be twice as long with concrete examples of agent interactions.
Verdict: weak accept — Addresses a real problem with a practical solution and strong benchmark results, but lacks technical depth and rigorous evaluation of the exploratory workflow claims.
Takeaways
Stateful context for long-running tasks: If you’re building AI assistants for any domain with iterative workflows (design, research, debugging), maintain state across sessions. Don’t make users re-explain context every time. Store failed attempts explicitly so the system doesn’t repeat mistakes.
Asynchronous agent architecture: For tasks with multiple independent subtasks, spawn parallel agents rather than sequential execution. This maps naturally to how humans work—we don’t finish one thing before starting another; we juggle.
Uncertainty as a first-class citizen: When your system encounters ambiguity, don’t guess. Flag it, present options, and ask. This prevents compounding errors and builds trust. Implement this as a structured output type, not just a text response.
Benchmark design insight: FrontierMath Tier 4 is interesting because it requires multi-step reasoning and exploration, not just pattern matching. If you’re evaluating AI for complex domains, design benchmarks that reward exploration and penalize lucky guesses.
论文: 2605.06651 作者: Daniel Zheng, Ingrid von Glehn, Yori Zwols, Iuliya Beloshapka, Lars Buesing, Daniel M. Roy, Martin Wattenberg, Bogdan Georgiev, Tatiana Schmidt, Andrew Cowie 分类: cs.AI
缺口
现有的数学 AI 专注于狭窄任务:定理证明(Lean、Coq)、符号计算(Mathematica)或基准问题求解。
这些工具把数学当作线性流水线——陈述猜想,证明它,完事。
但真实的数学研究是探索性和迭代性的:你追逐直觉,撞上死胡同,根据计算实验调整方向,搜索文献寻找相关工作,把模糊的想法打磨成精确的陈述。
当前的 AI 系统不支持这种混乱的、异步的工作流。
它们是计算器,不是合作者。
缺口:没有系统为完整的研究周期提供整体支持——构思、文献搜索、计算探索、定理证明和理论构建——同时管理不确定性、跟踪失败尝试、跨会话维护状态。
问题:数学研究是探索性          假设:AI 可以镜像人类
      和迭代性的,非线性                协作工作流
                |                                |
                v                                v
         当前 AI:任务特定            方法:有状态工作台 +
         工具(证明器、CAS)    -->    异步智能体 + 不确定性管理
                                                   |
                                                   v
                                      证据:FrontierMath Tier 4 达到 48%
                                           + 开放问题解决方案
                                                   |
                                                   v
                                      结论:AI 可以是研究伙伴
                                           而非仅仅是工具
增量
一句话: 这篇论文之前,AI 帮助数学家解决已陈述的问题;之后,AI 帮助数学家发现该解决什么问题。
核心机制
AI 协同数学家是一个有状态的工作空间,多个 AI 智能体代表用户异步运行。
当你给它一个模糊的研究方向时,它会生成智能体从不同角度探索:一个搜索文献,另一个运行计算实验,第三个尝试形式化证明。
每个智能体维护自己的状态,可以运行数小时或数天。
系统跟踪假设,记录失败(这样你不会重复它们),并通过交互细化你的意图。
工作空间输出原生数学产物:Lean 证明、计算笔记本、文献摘要、带支持证据的猜想。
智能体通过共享上下文通信,该上下文包括你的研究笔记、先前尝试和领域知识。
当智能体遇到不确定性(模糊的符号、多种解释)时,它会标记问题并请求澄清,而不是猜测。
用户意图(模糊)
        |
        v
   [工作空间状态]
        |
        +---> 智能体 1:文献搜索 -----> 论文、参考文献
        |
        +---> 智能体 2:计算 -----------> 数值证据
        |
        +---> 智能体 3:定理证明 -------> Lean 证明
        |
        +---> 智能体 4:理论构建 -------> 猜想
        |
        v
   [共享上下文]
   - 研究笔记
   - 失败的假设
   - 细化的意图
        |
        v
   数学产物
   (证明、笔记本、摘要)
把它想象成一个研究小组,你是 PI。
你在周一会议上给出一个宽泛的方向。
你的研究生(智能体)各自独立工作——一个去图书馆,另一个跑模拟,第三个尝试在 Lean 中形式化某些东西。
他们不需要你微观管理每一步。
周五,他们带着结果、问题和死胡同回来汇报。
你根据有效的内容细化方向,循环继续。
与单个 AI 助手的关键区别:并行性、持久性和对无效方法的记忆。
关键概念
- 有状态工作空间: 大多数 AI 交互是无状态的——每次查询从头开始。
有状态工作空间记住一切:你的研究笔记、先前对话、失败尝试、计算结果。
就像有一本永不关闭的实验室笔记本。
当你一周后回来时,系统知道你在哪里停下以及你已经尝试过什么。
这种持久性对研究至关重要,因为洞察力是在数月而非数分钟内出现的。
- 异步智能体: 智能体并行运行并在完成时报告,而不是等待一个任务完成后再开始下一个。
如果文献搜索需要 10 分钟,证明尝试需要 2 小时,你不会闲坐。
系统同时管理多个探索线程,就像人类研究者同时处理多个子问题一样。
智能体还可以通宵运行或跨会话运行——你在方便时检查。
- 不确定性管理: 当智能体遇到歧义时(例如,“光滑”是指 C^1 还是 C^∞?
),它不会猜测或产生幻觉。
它标记不确定性,呈现选项,并等待澄清。
这防止系统自信地追求错误的解释。
这是合作者问”你说的 X 是什么意思?
“和假设并在错误问题上浪费一周之间的区别。
框架转变
之前(任务特定工具):              之后(AI 协同数学家):

用户:"证明定理 X"                  用户:"我对性质 Y 感兴趣"
  |                                    |
  v                                    v
[定理证明器]                         [工作空间生成智能体]
  |                                    |
  v                                    +---> 文献
成功或失败                             +---> 计算
                                       +---> 证明
(一次性,无状态)                      +---> 理论构建
                                       |
                                       v
                                     [共享上下文跟踪进度]
                                       |
                                       v
                                     产物 + 细化的问题

                                     (迭代、有状态、探索性)
从单任务执行到多线程探索,核心转变是将 AI 视为管理自己子目标的研究伙伴,而不是执行你命令的工具。
专家评审
选题眼光: 这是一个真实的缺口。
任何做过数学研究的人都知道在 Lean、Mathematica、Google Scholar 和草稿纸之间切换上下文的痛苦。
该领域一直停留在”AI for X”模式(AI 用于定理证明,AI 用于符号数学),而不是”AI 用于研究”。
时机成熟——基础模型终于足够强大,可以处理所需的推理。
方法成熟度: 架构合理但不具突破性。
有状态工作空间和异步智能体在软件工程中是众所周知的。
新颖性在于应用和集成,而不是底层技术。
话虽如此,不确定性管理很巧妙——大多数系统要么产生幻觉,要么拒绝行动,但标记歧义并请求澄清是正确的中间地带。
实验诚意: FrontierMath Tier 4 上的 48% 令人印象深刻且可验证。
开放问题的轶事引人注目但仍是轶事——我们不知道尝试了多少问题与解决了多少问题。
如果有失败率分析和系统困难之处的细分,论文会更强。
基线是公平的(与其他 AI 系统在同一基准上比较),但没有与人类数学家工作流的比较,这才是真正的测试。
写作功力: 摘要和引言很强。
技术部分含糊——智能体究竟如何通信?
提示结构是什么?
不确定性如何表示?
论文读起来更像产品公告而非研究贡献。
第 3 节(系统架构)需要长两倍,并提供智能体交互的具体示例。
判决: 弱接收 — 用实用解决方案和强大的基准结果解决了真实问题,但缺乏技术深度和对探索性工作流声明的严格评估。
要点总结
长期任务的有状态上下文: 如果你正在为任何具有迭代工作流的领域(设计、研究、调试)构建 AI 助手,请跨会话维护状态。
不要让用户每次都重新解释上下文。
明确存储失败尝试,这样系统就不会重复错误。
异步智能体架构: 对于具有多个独立子任务的任务,生成并行智能体而不是顺序执行。
这自然映射到人类的工作方式——我们不会在开始另一件事之前完成一件事;我们同时处理。
不确定性作为一等公民: 当你的系统遇到歧义时,不要猜测。
标记它,呈现选项,并询问。
这防止复合错误并建立信任。
将其实现为结构化输出类型,而不仅仅是文本响应。
基准设计洞察: FrontierMath Tier 4 很有趣,因为它需要多步推理和探索,而不仅仅是模式匹配。
如果你正在评估复杂领域的 AI,设计奖励探索并惩罚幸运猜测的基准。