Paper: 2606.14674 Authors: Jixuan Chen, Jianzhi Shen, Haoqiang Kang, Zhi Hong, Qingyi Jiang, Soham Bose, Yiming Zhang, Leon Leng, Amit Vyas, Lingjun Mao Categories: cs.CL
The Gap
Existing research on LLM agents has been building increasingly sophisticated systems — think ReAct, Reflexion, Voyager, or AutoGPT. Each combines reasoning, memory, reflection, and action into a tightly-coupled pipeline. The problem? When you swap out the memory module for a fancier one and get +5% accuracy, you have no idea why. Was it the memory itself? Or did the new memory interact better with the existing reasoning module? Worse, different papers use wildly different interface conventions, so you can’t directly compare “memory” across systems.
The field is stuck at the black-box scaffold level: we know that adding components helps, but we can’t isolate *which part helps, under what conditions, and how parts interact. This paper says: standardize the interfaces, define the components formally, and then run controlled swap experiments.
[Problem: black-box scaffolds] - - - - - - - > [Assumption: component interactions dominate performance]
           |                                                      |
           v                                                      v
[Method: AgentSpec = typed components + standardized interfaces]
           |
           v
[Evidence: swap tests on 4 environments + 3 model backbones]
           |
           v
[Conclusion: scaffold compatibility matters more than individual module strength]
The Increment
One sentence: Before this paper, you could only test “does adding memory help?”; after this paper, you can test “which memory module, paired with which reasoning module, on which environment, gives the best cost-accuracy trade-off?” — and the answer is usually “it depends on the scaffold combination, not the isolated module.”
Core Mechanism
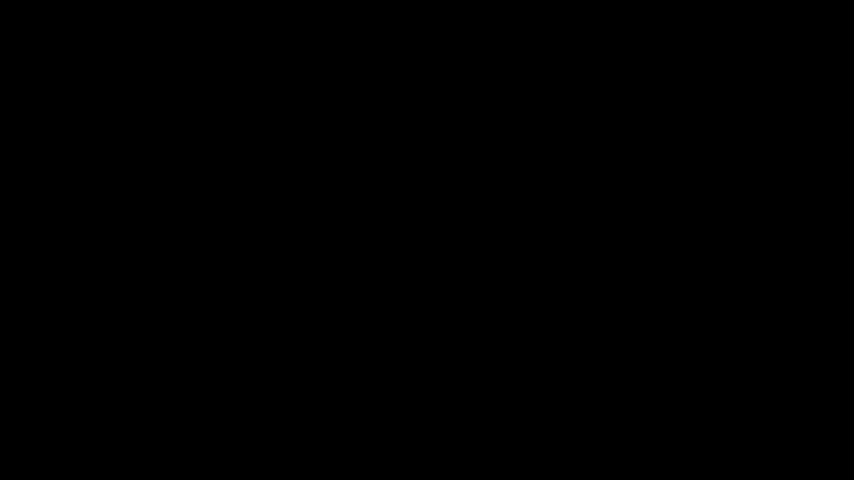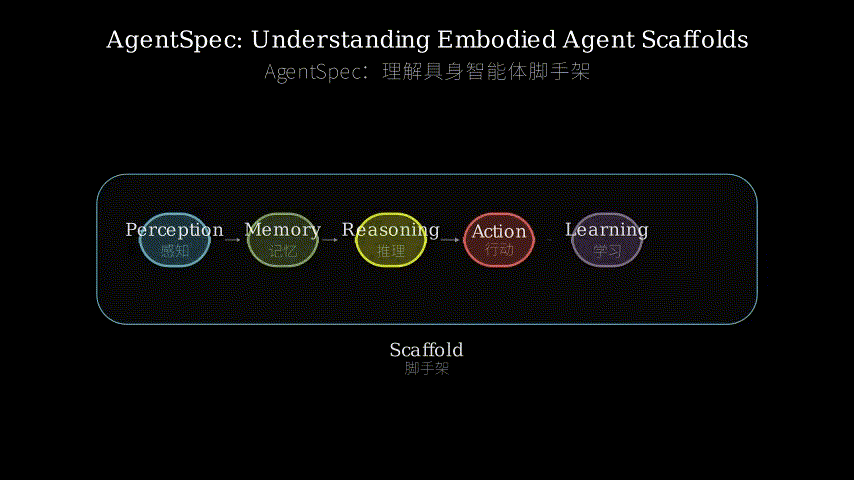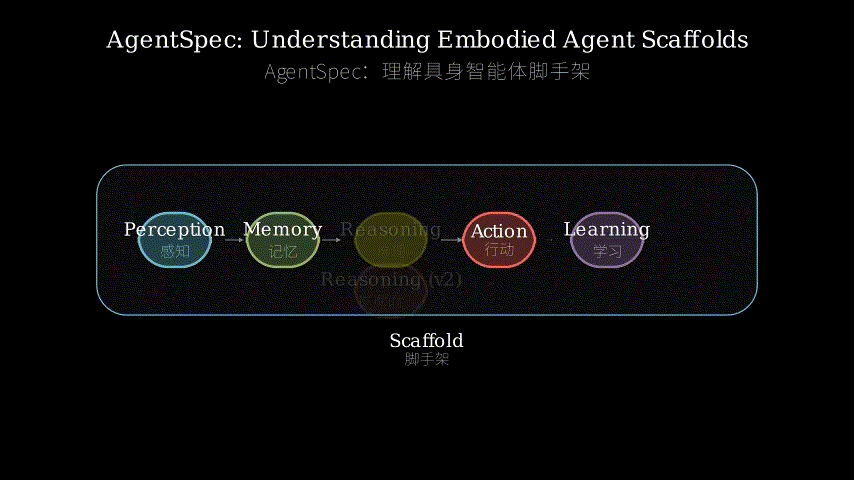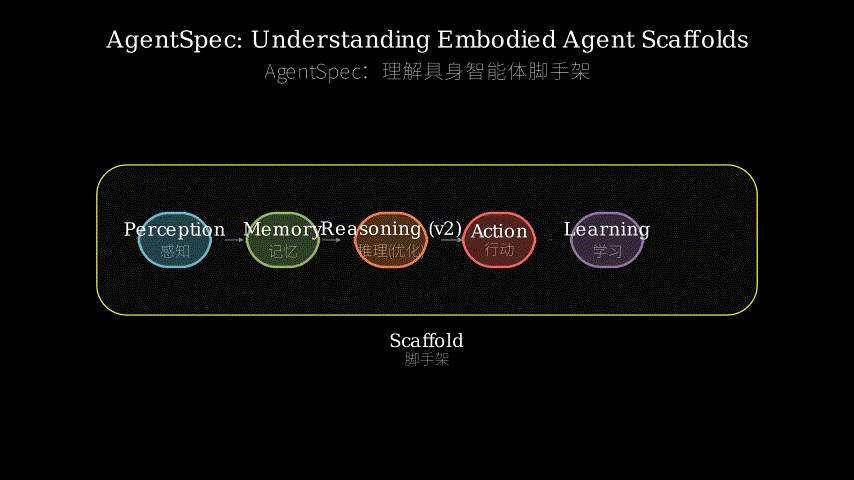
AgentSpec formalizes an LLM agent as a typed composition of policy components. Think of it as a circuit board where each component — memory, reasoning, reflection, action, learning — has a standardized pinout. You can pull out the “reflection” chip and plug in a different one, and the rest of the board still works.
The core abstraction is a module interface defined by three things: input type, output type, and a side-effect specification. For example, a memory module takes (state, observation) and outputs (retrieved context), optionally updating internal storage. A reasoning module takes (belief state, retrieved context) and outputs (plan). Because every module of the same type shares the same I/O shape, swapping becomes trivial.
Data flows through a control loop: perceive -> remember -> reason -> reflect -> act -> (optional) learn. Each step is a module call. The agent’s entire behavior is the composition of these modules. AgentSpec doesn’t prescribe *which module to use — it prescribes how modules must talk to each other.
+------------------+     +------------------+     +------------------+
| Perception       | --> | Memory           | --> | Reasoning        |
| (observe world)  |     | (retrieve/hold)  |     | (plan, decide)   |
+------------------+     +------------------+     +------------------+
                                                       |
                                                       v
+------------------+     +------------------+     +------------------+
| Action           | <-- | Reflection       | <-- | (from Reasoning) |
| (execute step)   |     | (critique plan)  |     |                  |
+------------------+     +------------------+     +------------------+
        |                                                ^
        v                                                |
+------------------+                                    |
| Learning         | (optional: update policy) ---------+
| (RL / feedback)  |
+------------------+
Here’s a load-bearing metaphor: think of AgentSpec as a chain restaurant kitchen.
- Receiving dock (Perception): ingredients arrive. Standardized crates, so the kitchen doesn’t care who grew the tomatoes.
- Walk-in cooler (Memory): stores ingredients and pre-prepped items. You can swap a single-door cooler for a walk-in freezer — same interface (“store and retrieve”), different capacity and speed.
- Head chef (Reasoning): reads the ticket and the inventory, decides what to cook and in what order.
- Sous chef with clipboard (Reflection): walks through the line, checks if the head chef’s plan makes sense, flags if we’re out of saffron or the grill is too hot.
- Line cooks (Action): execute. Flip the burger, plate the dish.
- Owner reviewing P&L (Learning): after service, looks at what sold and what got sent back, updates the menu.
The key insight: you can replace the walk-in cooler with a state-of-the-art cryogenic freezer — but if the head chef is used to pulling pre-chopped vegetables and now has to chop everything from frozen blocks, overall throughput might decrease. The scaffold compatibility is the kitchen workflow, not the individual appliance ratings.
Key Concepts
-
Scaffold Compatibility: The degree to which two modules work well together, measured by end-task performance. Not “memory X averages 80% accuracy” but “memory X paired with reasoning Y scores 85% on environment Z, but only 72% when swapped to reasoning W.” The paper’s central finding is that this interaction effect dominates. Example: structured multi-granularity memory (remembers at both scene-level and object-level) dramatically helps long-horizon tasks in ALFRED, but if paired with a shallow reasoning module that ignores fine-grained context, the extra memory granularity is wasted.
-
Module Typing: Each module is assigned a type that defines its I/O interface. Perception produces observations. Memory produces context. Reasoning produces plans. Reflection produces critiques. Action produces environment effects. This is like defining that all USB-C cables must carry 20V at 5A — doesn’t tell you what device is on the other end, but guarantees they’ll physically connect. In AgentSpec, “typed composition” means you can swap any memory module for any other memory module and the system won’t crash. It might perform worse, but it won’t *crash.
-
Compositional Ablation: Instead of “add memory and compare” (which conflates the memory itself with the fact that you added *something), AgentSpec enables “swap memory A for memory B while holding everything else fixed.” This reveals whether the new module’s benefit is robust (works across reasoning backbones) or brittle (only helps with one specific reasoning strategy). The paper shows that reflection, for example, is extremely brittle — it helps in some environments and hurts in others, depending on whether the reflection module’s critique style matches the reasoning module’s planning style.
Framework Shift
Before (mainstream approach):             After (this paper):

Agent X:                                   AgentSpec Framework:
+---------------+  +---------------+       +----------------------------+
| Reasoning     |  | Memory        |       | [Standard Interface Spec] |
| (custom impl) |  | (custom impl) |       |  Perception I/O            |
+-------+-------+  +-------+-------+       |  Memory I/O                |
        |                  |               |  Reasoning I/O             |
        v                  v               |  Reflection I/O            |
+-------+--------------------------------+ |  Action I/O                |
|            Action (tight coupling)      | |  Learning I/O              |
+-----------------------------------------+ +----------------------------+
                                                        |
                     vs                                  v
+-----------------------------------------+ +----------------------------+
| Agent X (custom wiring)                 | |  +------+ +-------+       |
| Component A ---> Component B            | |  | Mem  | | Reas  |       |
| If B changes, must rewire A             | |  +------+ +-------+       |
+-----------------------------------------+ |      ^        ^           |
                                            |      |        |           |
+-----------------------------------------+ |  +------+ +-------+       |
| Agent Y (different custom wiring)       | |  | Refl | | Learn |       |
| Component C ---> Component D ---> E     | |  +------+ +-------+       |
+-----------------------------------------+ |  (any standard module)    |
                                            +----------------------------+
                                  ^
                                  |
                     Both agents, now comparable
                     because they speak the same interface language
From proprietary pipelines to standardized modules: the core shift is from “building a specific agent” to “defining an agent construction kit where we can measure the effect of each part.”
Expert Assessment
Problem choice: Real and timely gap. The agent scaffolding problem is the single most under-studied aspect of LLM systems engineering. Every practitioner building a production agent has encountered this — “we added reflection and it helped, but we don’t know why, and it stopped helping when we upgraded the model.” This paper gives the field a vocabulary to talk about that experience rigorously. The gap isn’t manufactured; it’s the logical next step after the “add more components” phase of agent research.
Method maturity: Neither pure cleverness nor brute force — it’s infrastructure work that enables clever experiments. The contribution is more in the “standardized testbed” category than in a novel algorithm. Some might argue it’s “just engineering” — but that engineering is exactly what the field needs. The simpler approach would be a monolithic benchmark (which exists), but the insight here is that you need *compositional controls, not just benchmark numbers.
Experimental integrity: Baselines are fair — they compare their framework’s implementations against published results from the original papers. The cross-environment (DeliveryBench, ALFRED, MiniGrid, RoboTHOR) and cross-model (GPT-4o, Gemini, Claude) coverage is strong. One concern: the paper doesn’t fully control for compute cost differences across module combinations, though they do report costs. The reflection section’s finding that “reflection trades off correction and cost” is honestly reported but the raw numbers suggest reflection is expensive enough that its practical value is questionable outside high-stakes domains. No red flags, but the sample size per condition could be larger (they report 500 episodes per condition in ALFRED).
Writing quality: The paper is well-structured but the methods section is dense. Figure 3 (the module interface specification) in the actual paper is crucial and should have been more prominent. The authors cut corners on explaining *why they chose the specific interface definitions they did — the answer is “we iterated until components from different papers could be plugged in,” but reading the paper, it feels like they arrived at the interfaces by fiat rather than principled design. If the “Design Rationale” section were rewritten to show failed interface designs and what broke, the paper would feel more grounded.
Verdict: Weak accept — solid infrastructure contribution that the field needs, but the empirical findings are more “systematizing what practitioners already suspect” than “surprising new discovery.” It’s worth attention because it gives you the *tools to ask better questions, even if it doesn’t answer all of them itself.
Takeaways
Three specific things you can steal from this paper:
-
The “swap, don’t add” ablation methodology: When evaluating a new module, never compare “with” vs “without.” Always swap it with a baseline module of the same type. This isolates the module’s specific contribution from the artifact of “having more stuff.” Apply this to RAG pipeline components, tool-use strategies, or any multi-step LLM system.
-
Structured multi-granularity memory: The paper shows that storing both coarse (scene-level) and fine (object-level) memories, and retrieving the right one based on task horizon, works better than monolithic memory. The concrete technique — separate memory stores for different granularities with a routing mechanism — transfers directly to any long-context task like document QA or code repository understanding.
-
The cost-accuracy Pareto frontier for reflection: The paper’s analysis shows you should measure reflection not as “does it improve accuracy?” but as “what’s the slope of accuracy per extra dollar?” For most environments, reflection gives diminishing returns after the first pass. A practitioner can directly use this framing to decide: “I will only reflect on the first 20% of my agent’s actions, not all of them” — a specific, measurably justified heuristic.
论文: 2606.14674 作者: Jixuan Chen, Jianzhi Shen, Haoqiang Kang, Zhi Hong, Qingyi Jiang, Soham Bose, Yiming Zhang, Leon Leng, Amit Vyas, Lingjun Mao 分类: cs.CL
缺口
现有LLM智能体研究在构建越来越复杂的系统——ReAct、Reflexion、Voyager、AutoGPT。 每种系统都把推理、记忆、反思和动作捆绑成一个紧耦合的管线。 问题在于:当你把记忆模块换成更高级的,准确率提升了5%,你根本不知道为什么。 是记忆本身变好了?还是新记忆和现有推理模组配合得更默契? 更糟的是,不同论文用着截然不同的接口约定,你没法公平比较不同系统里的”记忆”。
这个领域卡在黑箱脚手架层面:我们知道加组件有用,但无法分离出**哪个部件*有用、在什么条件下有用、部件之间如何互相影响。 这篇论文说:标准化接口,形式化定义组件,然后做受控的互换实验。
[问题: 黑箱脚手架] - - - - - - - > [假设: 组件交互决定性能]
         |                                    |
         v                                    v
[方法: AgentSpec = 类型化组件 + 标准化接口]
         |
         v
[证据: 在4个环境 + 3个模型后端上做互换测试]
         |
         v
[结论: 脚手架兼容性比单一模块强度更重要]
增量
一句话: 这篇论文之前,你只能问”加记忆有没有帮助”; 这篇论文之后,你可以问”哪个记忆模块搭配哪个推理模块、在哪个环境上、给出什么样的成本-准确率权衡?” ——答案通常是”取决于脚手架组合,而非孤立模块”。
核心机制
AgentSpec 将LLM智能体形式化为策略组件的类型化组合。 把它想象成一块电路板——每个组件(记忆、推理、反思、动作、学习)都有标准化的引脚定义。 你可以拔掉”反思”芯片,插上另一个,电路板其余部分照常工作。
核心抽象是模块接口,由三样东西定义:输入类型、输出类型、副作用规格。 例如,记忆模块输入(状态,观察),输出(检索到的上下文),可选地更新内部存储。 推理模块输入(信念状态,检索到的上下文),输出(计划)。 因为同一类型的所有模块共享同样的 I/O 形状,互换变得微不足道。
数据流经控制循环:感知 -> 记忆 -> 推理 -> 反思 -> 动作 -> (可选)学习。 每一步都是一个模块调用。 智能体的整个行为就是这些模块的组合。 AgentSpec 不指定用哪个模块——它只规定模块之间如何通信。
+------------------+    +------------------+    +------------------+
| 感知             | -> | 记忆             | -> | 推理             |
| (观察世界)       |    | (检索/持有)      |    | (规划、决策)     |
+------------------+    +------------------+    +------------------+
                                                    |
                                                    v
+------------------+    +------------------+    +------------------+
| 动作             | <- | 反思             | <- | (来自推理)       |
| (执行步骤)       |    | (批评计划)       |    |                  |
+------------------+    +------------------+    +------------------+
        |                                              ^
        v                                              |
+------------------+                                   |
| 学习             | (可选: 更新策略) -----------------+
| (RL / 反馈)      |
+------------------+
这里用一个承重比喻:把 AgentSpec 想象成连锁餐厅的后厨。
- 收货平台(感知):原料到货。标准化周转箱,厨房不在乎西红柿是谁种的。
- 冷库(记忆):存放原料和半成品。你可以把单门冷柜换成步入式冷冻库——同样的接口(“存和取”),不同的容量和速度。
- 主厨(推理):看订单、查库存,决定做什么菜、按什么顺序做。
- 拿夹板的副厨(反思):在操作台之间走动,检查主厨的计划是否合理,如果没藏红花或者烤架太热就举手。
- 炒菜师傅(动作):执行。翻汉堡、装盘。
- 看报表的老板(学习):打烊后看什么卖得好、什么被退回,更新菜单。
关键洞见:你可以把冷库换成最先进的低温冷冻柜——但如果主厨习惯用预切蔬菜,现在必须从冷冻块切起,整体出餐速度反而可能下降。 脚手架兼容性是厨房的工作流程,不是单个电器的评分。
关键概念
-
脚手架兼容性:两个模块配合良好的程度,用最终任务性能衡量。 不是”记忆 X 平均准确率 80%“,而是”记忆 X 搭配推理 Y 在环境 Z 上得 85%,但换到推理 W 上只有 72%”。 这篇论文的核心发现就是这个交互效应占主导。 举个例子:结构化多粒度记忆(同时记住场景级别和物体级别的信息)在 ALFRED 的长期任务中帮助极大;但如果搭配一个忽略细粒度上下文的浅层推理模块,额外的记忆粒度就白费了。
-
模块类型化:每个模块被分配一个类型,定义其 I/O 接口。 感知产生观察。 记忆产生上下文。 推理产生计划。 反思产生批评。 动作产生环境效果。 这就像规定所有 USB-C 线都必须支持 20V/5A——不告诉你另一端连着什么设备,但保证它们物理上能插上。 在 AgentSpec 里,“类型化组合”意味着你可以把任意记忆模块换成另一个记忆模块,系统不会崩溃。性能可能变差,但不会崩溃。
-
组合式消融:不是”加记忆然后比较”(这混淆了记忆本身和”多了一个东西”),AgentSpec 允许”保持其他一切不变,把记忆 A 换成记忆 B”。 这能揭示新模块的好处是稳健的(跨推理后端都有效)还是脆弱的(只对某种特定推理策略有用)。 论文展示反思就极其脆弱——在某些环境上有帮助,在其他环境上有害,取决于反思模块的批评风格是否匹配推理模块的规划风格。
框架转变
之前(主流方法):                    之后(本文方法):

智能体 X:                              AgentSpec 框架:
+---------------+  +---------------+    +----------------------------+
| 推理           |  | 记忆          |    | [标准接口规范]              |
| (自定实现)     |  | (自定实现)    |    |  感知 I/O                   |
+-------+-------+  +-------+----+--+    |  记忆 I/O                   |
        |                  |          |  |  推理 I/O                   |
        v                  v          |  |  反思 I/O                   |
+-------+--------------------------+  |  |  动作 I/O                   |
|            动作 (紧耦合)          |  |  |  学习 I/O                   |
+----------------------------------+  +----------------------------+
                                                 |
                 vs                                v
+----------------------------------+  +----------------------------+
| 智能体 X (自定连线)              |  |  +------+ +-------+       |
| 组件 A ---> 组件 B              |  |  | 记忆 | | 推理  |       |
| 如果 B 变了,必须重连 A          |  |  +------+ +-------+       |
+----------------------------------+  |      ^        ^           |
                                       |      |        |           |
+----------------------------------+  |  +------+ +-------+       |
| 智能体 Y (不同的自定连线)        |  |  | 反思 | | 学习  |       |
| 组件 C ---> 组件 D ---> E        |  |  +------+ +-------+       |
+----------------------------------+  |  (任何标准模块)           |
                                       +----------------------------+
                             ^
                             |
                两个智能体现在可以比较了,
                因为它们说同一种接口语言
从专有管线到标准化模块:核心转变是从”构建某个具体的智能体”到”定义一个智能体的乐高套装,让我们能够测量每个部件的效果”。
专家评审
选题眼光:这是真缺口,而且是LLM系统工程中最被低估的一个问题。 每个在生产环境中构建智能体的实践者都遇到过——“我们加了反思,确实有帮助,但不知道为什么,而且换了模型之后帮助就消失了。” 这篇论文给整个领域提供了一套谈论这种经验的语言。 缺口不是制造出来的,而是”加组件”阶段的智能体研究之后的逻辑下一步。
方法成熟度:既不是纯粹的巧劲也不是蛮力——这是基础设施工作,使得巧妙的实验成为可能。 贡献更多在”标准化测试平台”类别,而非新算法。 有人可能会说”这只是工程”——但恰恰是当前领域需要的工程。 更简单的方法是做一个单一的基准测试(已经有了),但这里的洞见是你需要组合控制,而不仅仅是基准数字。
实验诚意:基线公平——他们将框架实现的版本与原始论文的已发表结果进行了比较。 跨环境(DeliveryBench、ALFRED、MiniGrid、RoboTHOR)和跨模型(GPT-4o、Gemini、Claude)的覆盖很强。 一个担忧:论文没有完全控制不同模块组合之间的计算成本差异,尽管他们确实报告了成本。 反思部分的结论”反思是校正和成本之间的权衡”诚实报告,但原始数字暗示反思的代价足够大,以至于在非高风险场景中其实际价值存疑。 没有值得警惕的红旗,但每个条件的样本量可以更大(ALFRED上他们报告每个条件500个回合)。
写作功力:论文结构清晰,但方法部分很密集。 正式论文中的图3(模块接口规范)至关重要,本应更突出。 作者在解释为什么选择这些具体接口定义时走了捷径——答案可能是”我们反复迭代直到不同论文的组件都能插进来”,但读论文时感觉接口像是凭权威设定而非经过原理性设计。 如果把”设计原理”部分重写,展示失败的接口设计以及什么崩塌了,整篇论文会更有说服力。
判决:弱接收——领域需要的基础设施贡献,但实证发现更多是”系统化了实践者已经怀疑的事”,而非”令人惊讶的新发现”。 值得关注,因为它给了你提问更好问题的工具,即使它本身没有回答所有问题。
要点总结
你可以从这篇论文”偷走”三样具体的东西:
-
“互换而非添加”的消融方法论:评估新模块时,永远不要比较”有”vs”没有”。 总是把它和同类型的基线模块互换。 这能分离出模块的具体贡献,而不是”多了一个东西”的人工效应。 将此方法应用于RAG管线组件、工具使用策略,或任何多步LLM系统的评估。
-
结构化多粒度记忆:论文显示同时存储粗粒度(场景级别)和细粒度(物体级别)的记忆,并根据任务时间跨度检索正确的那个,效果优于单一记忆。 具体技术——不同粒度使用独立的记忆存储,加上路由机制——可以直接迁移到长上下文任务,如文档问答或代码仓库理解。
-
反思的成本-准确率帕累托前沿:论文的分析显示,你应该把反思视为”准确率每额外一美元的斜率”,而不是”是否提高准确率”。 在大多数环境中,第一次反思之后收益递减非常严重。 实践者可以直接使用这个框架来决策:“我只对智能体前20%的动作做反思,而不是全部”——这是一个具体的、可测量的、有依据的启发式规则。