Paper: 2603.04384 Authors: Zijian Chen, Xueguang Ma, Shengyao Zhuang, Jimmy Lin, Akari Asai, Victor Zhong Categories: cs.CL
The Gap
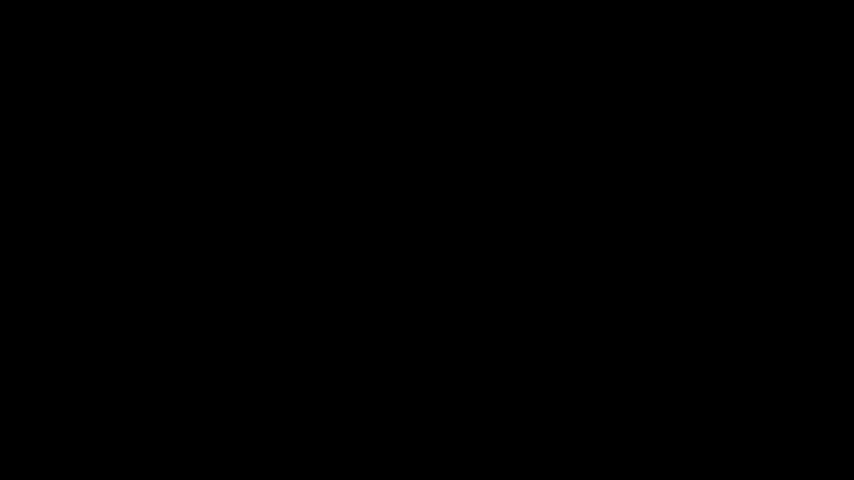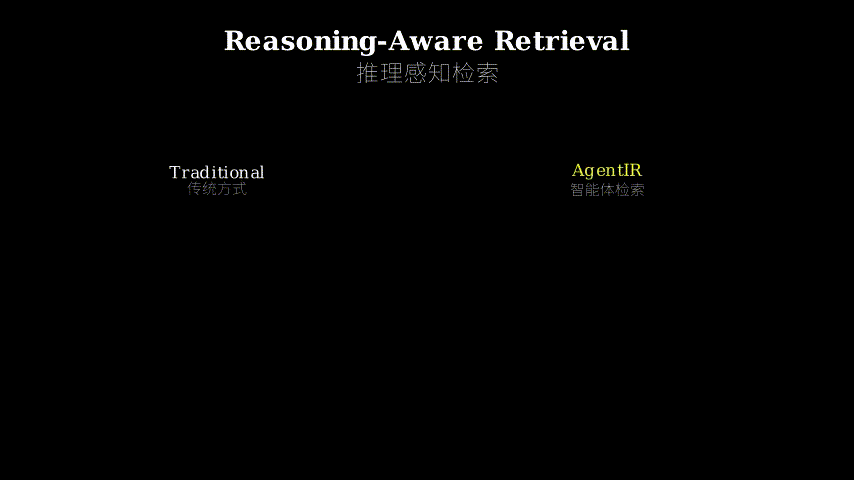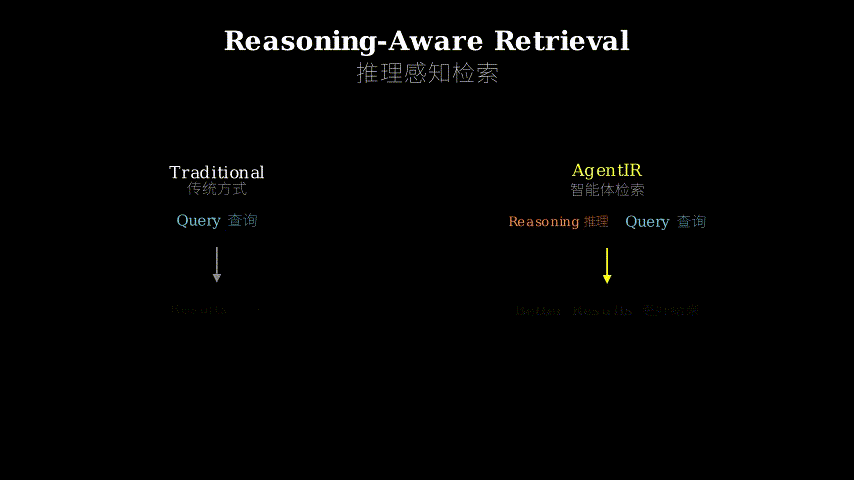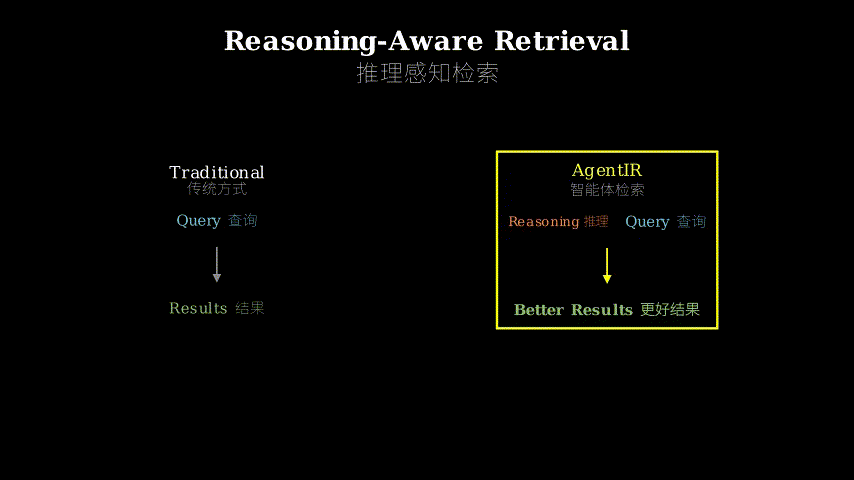
Retrieval systems were built for humans who type queries and hit enter. But AI research agents are different — they think out loud before searching. They generate explicit reasoning traces like “I need to verify the claim about GDP growth, so I should search for economic data from 2020-2023.” Current retrievers (BM25, dense embeddings like BGE, Contriever) treat this reasoning as noise and only encode the final query. They’re leaving money on the table.
The core assumption: if an agent bothers to write down why it’s searching, that context contains signal about what documents would actually help. Prior work on query expansion and conversational search tried to use context, but they focused on human conversation history, not agent reasoning chains. No one trained a retriever specifically for the agent use case.
Problem: Retrievers ignore agent reasoning traces
   |
   v
Assumption: Reasoning reveals intent better than query alone
   |
   v
Method: Joint embedding of [reasoning + query]
   |
   v
Evidence: 68% vs 50% accuracy on BrowseComp-Plus
   |
   v
Conclusion: Reasoning-aware retrieval works
The Increment
One sentence: Before AgentIR, retrievers saw only the query; after AgentIR, they see the agent’s thought process too.
Core Mechanism
AgentIR has two components working together. First is the retrieval paradigm shift: instead of embedding just the query, you concatenate the agent’s reasoning trace with the query and embed the whole thing. The encoder sees “I need to verify GDP claims [SEP] economic data 2020-2023” instead of just “economic data 2020-2023.” This is reasoning-aware retrieval.
Second is the data problem. You can’t just grab existing retrieval datasets because they don’t have agent reasoning traces. So they built DR-Synth, a synthetic data generator. It takes standard QA datasets, uses an LLM to generate fake agent reasoning traces that lead to each query, then creates training triplets of (reasoning + query, positive doc, negative doc). The LLM essentially role-plays as a research agent working backwards from the answer.
The trained model, AgentIR-4B, is a 4-billion parameter encoder that learned to weight reasoning context appropriately. During inference, the agent generates reasoning, appends its query, and AgentIR embeds the combined text to retrieve documents.
Agent generates:                    AgentIR processes:

[Reasoning trace]                   +------------------+
      |                             | Reasoning trace  |
      v                             +------------------+
"I need to verify..."                       |
      |                                     v
      +----------> Concatenate -----> [Encoder 4B]
      |                                     |
[Query]                                     v
      |                             +------------------+
      v                             | Joint embedding  |
"economic data 2020"                +------------------+
                                            |
                                            v
                                    Retrieve documents
Think of it like a librarian who can read your research notes. Old retrievers are like librarians who only hear your final question: “Do you have books on economic data?” They hand you generic economics books. AgentIR is like a librarian who reads your entire research outline first: “I’m writing a paper on post-pandemic recovery, specifically challenging claims about GDP growth rates in developing nations, and I need primary sources from 2020-2023.” Now they know exactly which shelf to point you to. The reasoning trace is the research outline — it constrains the search space and reveals your actual information need.
Key Concepts
-
Reasoning Trace: When an AI agent decides to search, it first generates natural language explaining its thought process. For example, if asked “What’s the tallest building in 2024?”, the agent might write “The user is asking about current information. I should search for recent records of tall buildings to get up-to-date data.” This trace is typically 1-3 sentences that appear before the actual search query. Humans don’t do this — we just type “tallest building 2024” — but agents do because they’re trained to show their work. AgentIR is the first retriever to actually use this signal instead of discarding it.
-
DR-Synth (Deep Research Synthesis): You can’t train a reasoning-aware retriever without training data that has reasoning traces. But existing datasets like MS MARCO only have queries and documents. DR-Synth solves this by using an LLM to generate synthetic reasoning traces. Given a question and answer, it prompts the LLM to role-play as an agent: “You’re researching this question. What would you think before searching?” The LLM generates plausible reasoning, and now you have (reasoning, query, document) triplets for training. It’s data augmentation specifically for the agent retrieval task.
-
Joint Embedding: Traditional retrievers embed queries and documents separately, then compute similarity. AgentIR embeds the concatenation of reasoning and query as a single unit. This lets the encoder learn interactions between reasoning context and query terms. For instance, the word “recent” in the reasoning trace might boost the importance of date-related terms in the query. You can’t capture this if you embed reasoning and query separately then combine them — the encoder needs to see both at once to learn these cross-dependencies.
Framework Shift
Before (mainstream approach):        After (this paper):

Agent reasoning:                     Agent reasoning:
"I need to verify..."                "I need to verify..."
       |                                    |
       | (discarded)                       | (used as input)
       v                                    v
Query: "GDP 2020"                    [Reasoning + Query]
       |                                    |
       v                                    v
  [Encoder]                            [Encoder]
       |                                    |
       v                                    v
  Embedding -----> Retrieve           Embedding -----> Retrieve

  (Context lost)                      (Context preserved)
From treating agents like humans who only provide queries, to treating them like collaborators who explain their intent.
Expert Assessment
Problem choice: This is a real gap that emerged organically. As AI agents became primary users of retrieval systems (think Perplexity, ChatGPT search, research assistants), the mismatch between human-centric retrievers and agent behavior became obvious. The timing is right — this paper rides the wave of agentic AI without forcing it. It’s not a manufactured problem.
Method maturity: The core idea is simple and elegant: just concatenate reasoning with query. No fancy architectures, no multi-stage pipelines. DR-Synth is clever — using LLMs to generate training data is becoming standard practice, but applying it specifically to create reasoning traces is a nice twist. However, I’m skeptical about one thing: they don’t explore whether simpler approaches like query expansion with reasoning keywords would close the gap. Did they really need to retrain a 4B model, or would fine-tuning existing encoders work?
Experimental integrity: The numbers look solid. BrowseComp-Plus is a legitimate benchmark for multi-hop research tasks. Comparing against BGE-large (twice the size) and BM25 is fair. The 68% vs 50% vs 37% progression is dramatic enough to be convincing. But I’d want to see ablations: what if you only use reasoning without the query? What if you use reasoning as a separate encoder tower? They show both components (reasoning-aware retrieval + DR-Synth) help independently, which is good, but the paper lacks depth on failure modes. When does reasoning hurt retrieval?
Writing quality: The abstract and intro are crisp. The method section is clear. But the related work section feels rushed — they don’t adequately position this against conversational search and query reformulation literature. The evaluation section could use more error analysis. What types of reasoning traces help most? Which ones confuse the retriever? A case study section would elevate this from a solid systems paper to an insightful one.
Verdict: weak accept — The idea is sound, the execution is competent, and the results are strong, but it lacks the depth of analysis that would make it a strong accept.
Takeaways
If you’re building any system where an LLM generates intermediate reasoning before taking actions, don’t throw that reasoning away. Treat it as first-class input to downstream components. This applies beyond retrieval: if your agent reasons before calling APIs, feed that reasoning to the API selector. If it reasons before generating code, feed it to the code completion model.
The DR-Synth pattern is reusable: when you need training data for a new task variant but only have data for the standard task, use an LLM to generate the missing pieces. Just be careful about distribution shift — synthetic reasoning might not match real agent reasoning.
Concretely, if you’re using RAG with agents: modify your retrieval pipeline to accept both the agent’s chain-of-thought and its query. Even without retraining AgentIR, you can experiment with prompt engineering to make existing retrievers reasoning-aware (e.g., “Given this context: [reasoning], find documents about: [query]”). The paper proves the signal is there; you don’t need their exact model to exploit it.
论文: 2603.04384 作者: Zijian Chen, Xueguang Ma, Shengyao Zhuang, Jimmy Lin, Akari Asai, Victor Zhong 分类: cs.CL
缺口
检索系统是为人类设计的——人类输入查询词然后回车。 但AI研究智能体不一样,它们在搜索前会”自言自语”。 它们会生成明确的推理轨迹,比如”我需要验证GDP增长的说法,所以应该搜索2020-2023年的经济数据”。 现有检索器(BM25、BGE、Contriever等密集嵌入模型)把这些推理当噪音,只编码最终查询。 它们在浪费宝贵信号。
核心假设:如果智能体费心写下搜索原因,那段上下文就包含了什么文档真正有用的信号。 之前关于查询扩展和对话式搜索的工作尝试利用上下文,但它们关注的是人类对话历史,不是智能体推理链。 没人专门为智能体用例训练过检索器。
问题: 检索器忽略智能体推理轨迹
   |
   v
假设: 推理比单独查询更能揭示意图
   |
   v
方法: 联合嵌入[推理+查询]
   |
   v
证据: BrowseComp-Plus上68% vs 50%准确率
   |
   v
结论: 推理感知检索有效
增量
一句话: AgentIR之前,检索器只看查询; AgentIR之后,它们也看智能体的思考过程。
核心机制
AgentIR有两个协同工作的组件。 第一个是检索范式转变:不是只嵌入查询,而是把智能体的推理轨迹和查询拼接起来,嵌入整个文本。 编码器看到的是”我需要验证GDP声明[SEP]2020-2023经济数据”,而不只是”2020-2023经济数据”。 这就是推理感知检索。
第二个是数据问题。 你不能直接用现有检索数据集,因为它们没有智能体推理轨迹。 所以他们构建了DR-Synth,一个合成数据生成器。 它拿标准QA数据集,用LLM生成导向每个查询的假智能体推理轨迹,然后创建(推理+查询,正文档,负文档)的训练三元组。 LLM本质上是从答案反推,扮演研究智能体的角色。
训练出的模型AgentIR-4B是一个40亿参数的编码器,学会了恰当地权衡推理上下文。 推理时,智能体生成推理,附加查询,AgentIR嵌入组合文本来检索文档。
智能体生成:                        AgentIR处理:

[推理轨迹]                          +------------------+
      |                             | 推理轨迹         |
      v                             +------------------+
"我需要验证..."                            |
      |                                     v
      +----------> 拼接 ----------> [编码器 4B]
      |                                     |
[查询]                                      v
      |                             +------------------+
      v                             | 联合嵌入         |
"2020经济数据"                      +------------------+
                                            |
                                            v
                                    检索文档
把它想象成能读你研究笔记的图书管理员。 旧检索器像只听你最终问题的管理员:“有经济数据的书吗?”他们递给你通用经济学书籍。 AgentIR像先读你整个研究大纲的管理员:“我在写疫情后复苏的论文,专门质疑发展中国家GDP增长率的说法,需要2020-2023年的一手资料。 “现在他们知道该指你去哪个书架了。 推理轨迹就是研究大纲——它约束搜索空间,揭示你真正的信息需求。
关键概念
-
推理轨迹: 当AI智能体决定搜索时,它先生成自然语言解释思考过程。 比如被问”2024年最高建筑是什么? “,智能体可能写”用户在问当前信息。 我应该搜索高楼的最新记录来获取最新数据。 “这个轨迹通常是1-3句话,出现在实际搜索查询之前。 人类不这么做——我们直接输”2024最高建筑”——但智能体这么做,因为它们被训练成要展示工作过程。 AgentIR是第一个真正利用这个信号而不是丢弃它的检索器。
-
DR-Synth(深度研究合成): 没有带推理轨迹的训练数据,你就训练不出推理感知检索器。 但现有数据集如MS MARCO只有查询和文档。 DR-Synth通过用LLM生成合成推理轨迹来解决这个问题。 给定问题和答案,它提示LLM扮演智能体:“你在研究这个问题。 搜索前你会想什么? “LLM生成合理的推理,现在你就有了(推理,查询,文档)三元组用于训练。 这是专门针对智能体检索任务的数据增强。
-
联合嵌入: 传统检索器分别嵌入查询和文档,然后计算相似度。 AgentIR把推理和查询的拼接作为单个单元嵌入。 这让编码器学习推理上下文和查询词之间的交互。 比如,推理轨迹中的”最近”一词可能提升查询中日期相关词的重要性。 如果你分别嵌入推理和查询再组合,就捕捉不到这个——编码器需要同时看到两者才能学习这些交叉依赖。
框架转变
之前(主流方法):                    之后(本文方法):

智能体推理:                        智能体推理:
"我需要验证..."                    "我需要验证..."
       |                                  |
       | (丢弃)                           | (用作输入)
       v                                  v
查询: "2020 GDP"                   [推理+查询]
       |                                  |
       v                                  v
  [编码器]                            [编码器]
       |                                  |
       v                                  v
  嵌入 -----> 检索                   嵌入 -----> 检索

  (上下文丢失)                       (上下文保留)
从把智能体当成只提供查询的人类,到把它们当成解释意图的协作者。
专家评审
选题眼光: 这是自然涌现的真实缺口。 随着AI智能体成为检索系统的主要用户(想想Perplexity、ChatGPT搜索、研究助手),以人为中心的检索器与智能体行为之间的不匹配变得明显。 时机恰当——这篇论文顺应智能体AI的浪潮而不是强行制造问题。 不是人造缺口。
方法成熟度: 核心想法简单优雅:就是把推理和查询拼接起来。 没有花哨架构,没有多阶段流水线。 DR-Synth很巧妙——用LLM生成训练数据正在成为标准做法,但专门应用它来创建推理轨迹是个不错的转折。 但我对一点持怀疑态度:他们没探索更简单的方法,比如用推理关键词做查询扩展是否能缩小差距。 他们真的需要重新训练一个4B模型吗,还是微调现有编码器就行?
实验诚意: 数字看起来扎实。 BrowseComp-Plus是多跳研究任务的合法基准。 与BGE-large(两倍大小)和BM25比较是公平的。 68% vs 50% vs 37%的递进足够戏剧化,令人信服。 但我想看消融实验:如果只用推理不用查询会怎样? 如果把推理用作单独的编码器塔呢? 他们展示了两个组件(推理感知检索+DR-Synth)独立有效,这很好,但论文缺乏对失败模式的深度分析。 什么时候推理会损害检索?
写作功力: 摘要和引言简洁。 方法部分清晰。 但相关工作部分感觉仓促——他们没有充分定位这项工作相对于对话式搜索和查询重构文献的位置。 评估部分可以用更多错误分析。 什么类型的推理轨迹最有帮助? 哪些会混淆检索器? 一个案例研究部分会把这篇论文从扎实的系统论文提升为有洞察力的论文。
判决: 弱接收——想法合理,执行称职,结果强劲,但缺乏能让它成为强接收的分析深度。
要点总结
如果你在构建任何LLM在采取行动前生成中间推理的系统,别扔掉那些推理。 把它当作下游组件的一等输入。 这适用于检索之外:如果你的智能体在调用API前推理,把推理喂给API选择器。 如果它在生成代码前推理,喂给代码补全模型。
DR-Synth模式可复用:当你需要新任务变体的训练数据但只有标准任务的数据时,用LLM生成缺失部分。 只是要小心分布偏移——合成推理可能不匹配真实智能体推理。
具体来说,如果你在用带智能体的RAG:修改检索流水线,让它同时接受智能体的思维链和查询。 即使不重新训练AgentIR,你也可以实验提示工程来让现有检索器具备推理感知能力(比如”给定这个上下文:[推理],找关于:[查询]的文档”)。 论文证明了信号在那里; 你不需要他们的确切模型来利用它。