Paper: 2604.12999 Authors: Jaywon Koo, Jefferson Hernandez, Ruozhen He, Hanjie Chen, Chen Wei, Vicente Ordonez Categories: cs.CV
The Gap
Neural Architecture Search (NAS) has evolved from random search to sophisticated optimization methods, but existing approaches treat architecture discovery as a black-box optimization problem. Methods like DARTS, ENAS, and evolutionary algorithms explore design spaces efficiently but don’t accumulate knowledge about why certain design choices work. Each search run starts from scratch, discarding the reasoning behind successful architectures. The field has reached high performance but lacks interpretability and transferability of design principles.
Problem: NAS finds good architectures but not design understanding
    |
    v
Assumption: Architecture discovery can mirror scientific inquiry
    |
    v
Method: Hypothesis-driven evolution with confidence tracking
    |
    v
Evidence: 18.91% -> 94.11% on CIFAR-10, principles transfer across runs
    |
    v
Conclusion: Explicit hypothesis tracking builds reusable knowledge
The Increment
One sentence: Before this paper, NAS found architectures through opaque optimization; after, it generates and tests explicit hypotheses that accumulate into transferable design principles.
Core Mechanism
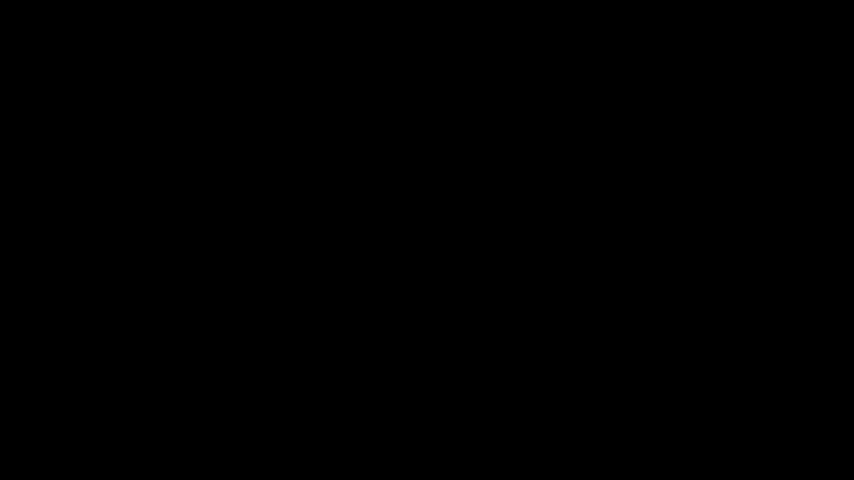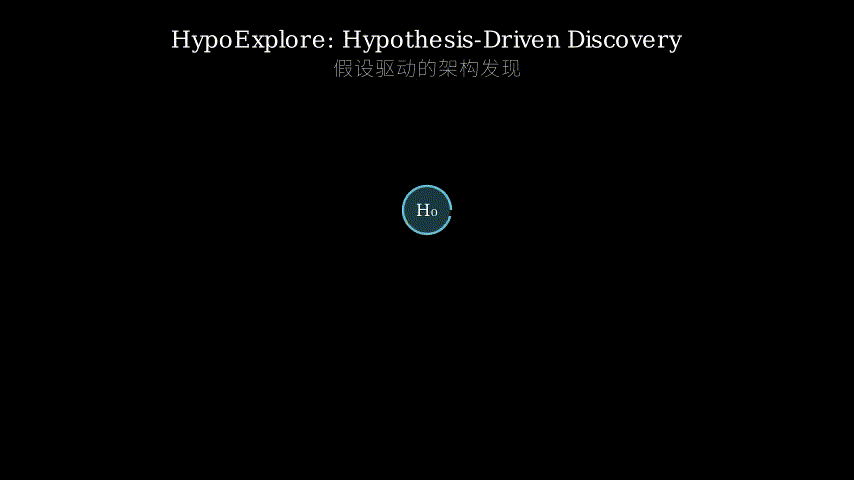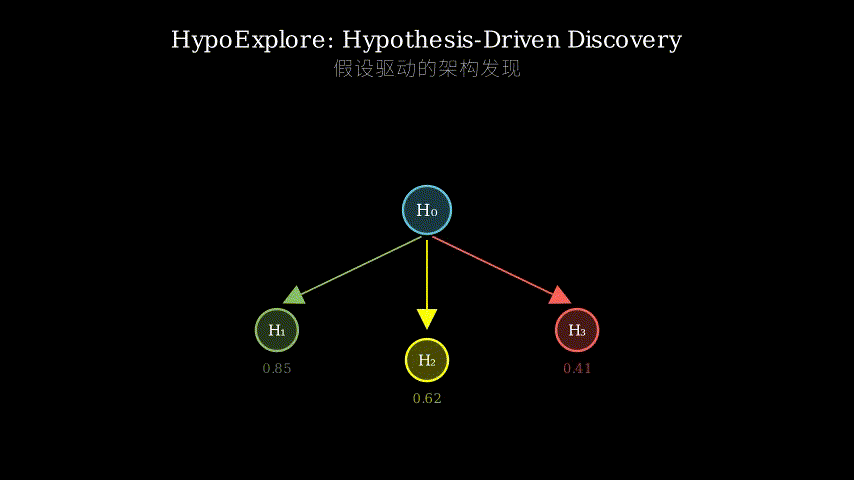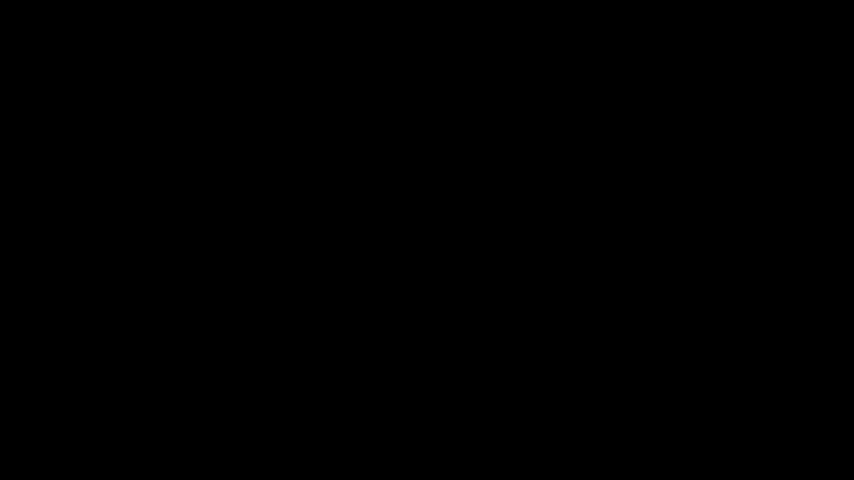
HypoExplore maintains two core data structures: a Trajectory Tree recording the lineage of all proposed architectures, and a Hypothesis Memory Bank tracking confidence scores for design principles. Each node in the tree represents an architecture with its associated hypothesis (e.g., “adding depthwise separable convolutions improves efficiency”). The system operates in cycles: an LLM selects a parent hypothesis using a dual strategy that balances exploitation (building on validated ideas) and exploration (testing uncertain ones), proposes a modification, implements it as code, trains the architecture, and collects results.
After each experiment, multiple specialized feedback agents analyze results from different angles—one examines accuracy trends, another checks parameter efficiency, a third looks at training stability. These agents consolidate their observations into confidence updates for the hypothesis. If “depthwise separable convolutions improve efficiency” consistently correlates with better results, its confidence score rises. If it fails in certain contexts, the score adjusts accordingly. The confidence scores guide future parent selection, creating a feedback loop where the system learns which principles are robust.
                    Hypothesis Memory Bank
                    [principle_1: conf=0.8]
                    [principle_2: conf=0.3]
                           |
                           v
    LLM selects parent --> Generate new hypothesis
           |                       |
           v                       v
    Implement code <-------- Modify architecture
           |
           v
    Train & Evaluate
           |
           v
    Feedback Agents (accuracy, efficiency, stability)
           |
           v
    Update confidence scores --> Back to Memory Bank
           |
           v
    Add to Trajectory Tree (parent-child link preserved)
Think of HypoExplore as a research lab with a persistent lab notebook. Traditional NAS is like hiring a new researcher for each project who tries random experiments and reports the best result but leaves no notes. HypoExplore is a lab where each experiment is documented with its rationale (hypothesis), results are analyzed by a committee (feedback agents), and findings are recorded in a shared notebook (Memory Bank) with confidence ratings. When starting a new experiment, researchers consult the notebook to see which approaches have strong evidence and which need more testing. The family tree of experiments (Trajectory Tree) shows which ideas descended from which, so you can trace successful architectures back to their conceptual ancestors. Over time, the lab builds institutional knowledge—not just “architecture X works” but “principle Y tends to work because Z.”
Key Concepts
-
Hypothesis Confidence Score: Instead of just tracking whether an architecture performed well, HypoExplore tracks confidence in the *principle behind it. Imagine you’re learning to cook. You try adding garlic to three dishes—two turn out great, one mediocre. Your confidence in “garlic improves flavor” is high but not absolute. If you later try garlic in desserts and it fails, your confidence becomes context-dependent: “garlic improves savory dishes.” HypoExplore does this for architecture principles. A hypothesis like “residual connections help deep networks” starts with neutral confidence. As experiments accumulate, the score rises if residual connections consistently improve results, or becomes nuanced if they only help in certain depth ranges. The score is Bayesian—it updates with evidence and can represent uncertainty.
-
Dual Exploration Strategy: The system must balance two competing goals: exploit validated principles (build on what works) versus explore uncertain ones (test unproven ideas). Pure exploitation leads to local optima—you keep refining the same idea. Pure exploration wastes time on random guesses. HypoExplore uses confidence scores to balance both. High-confidence hypotheses are selected more often (exploitation), but medium-confidence ones get chances too (exploration). It’s like a scientist who mostly builds on established theories but occasionally tests fringe ideas that might be breakthroughs. The selection probability is proportional to confidence, but not deterministic—even low-confidence hypotheses can be chosen, just rarely.
-
Trajectory Tree: This isn’t just a log of experiments; it’s a genealogy of ideas. Each node is an architecture, and edges show parent-child relationships. If architecture B was created by modifying architecture A based on hypothesis H, there’s an edge A→B labeled with H. This structure reveals which principles are fertile (many successful descendants) versus dead ends. You can trace any successful architecture back to its conceptual roots and see the sequence of insights that led there. It also enables transfer learning of principles: if two independent branches both discover that “attention mechanisms improve accuracy,” the Memory Bank aggregates evidence from both lineages, strengthening confidence faster than either branch alone could.
Framework Shift
Before (mainstream NAS):              After (HypoExplore):

Search Space                          Hypothesis Space
     |                                      |
     v                                      v
Random/Gradient Sampling              LLM-Guided Ideation
     |                                      |
     v                                      v
Train & Evaluate                      Train & Multi-Agent Analysis
     |                                      |
     v                                      v
Keep Best Architecture                Update Principle Confidence
     |                                      |
     v                                      v
[Discard reasoning]                   Accumulate in Memory Bank
                                             |
                                             v
                                      Transfer to New Searches
From implicit optimization to explicit reasoning, the core shift is making design principles first-class citizens that persist and transfer across search runs.
Expert Assessment
Problem choice: This is a real gap. NAS has matured in performance but remains a black box. The field is ready for interpretability—practitioners want to understand *why architectures work, not just which ones work. The timing is right given LLMs’ reasoning capabilities. However, the problem is somewhat manufactured in that many researchers already informally track design principles; this paper formalizes it.
Method maturity: The core insight—treating architecture search as hypothesis testing—is elegant. The dual exploration strategy and confidence tracking are well-motivated. However, the reliance on LLMs for hypothesis generation is a double-edged sword: it enables rich reasoning but introduces brittleness (prompt sensitivity, hallucination risk). The multi-agent feedback mechanism feels slightly over-engineered; simpler confidence update rules might suffice. The method is more “clever orchestration” than “novel algorithm.”
Experimental integrity: The 18.91% → 94.11% improvement is dramatic but starts from a deliberately weak baseline (likely a shallow network). More informative would be starting from a reasonable baseline like ResNet-18. The CIFAR-10 results are solid, and generalization to CIFAR-100, Tiny-ImageNet, and MedMNIST strengthens the claims. The claim that “hypothesis confidence scores grow increasingly predictive” is supported but not rigorously quantified—correlation plots would help. Baselines are fair but not exhaustive; comparison to recent NAS methods like AutoFormer or OFA would be valuable.
Writing quality: The paper is well-structured and clearly written. The Trajectory Tree and Memory Bank concepts are explained intuitively. However, Section 3.2 (feedback agents) is vague—what exactly do these agents compute? The paper would benefit from showing example hypotheses and their confidence trajectories over time. The related work section is thorough but could better position this work relative to meta-learning and neural architecture transfer.
Verdict: weak accept — The hypothesis-driven framing is a valuable contribution to NAS interpretability, and the results demonstrate feasibility, but the method’s complexity and LLM dependence raise questions about practical adoption and reproducibility.
Takeaways
Confidence-weighted exploration: The dual strategy of balancing exploitation and exploration via confidence scores is broadly applicable. In hyperparameter tuning, you could track confidence in “learning rate schedules” or “regularization strategies” and prioritize well-validated approaches while occasionally testing uncertain ones. This beats pure grid search or random search.
Genealogy tracking for iterative design: The Trajectory Tree concept transfers to any iterative design process. In prompt engineering, track which prompt modifications descended from which, and which principles (e.g., “adding examples improves accuracy”) have strong evidence across branches. In A/B testing, maintain a tree of feature variants and their rationales.
Multi-perspective evaluation: Using specialized agents to analyze results from different angles (accuracy, efficiency, stability) is a pattern worth stealing. In model evaluation, don’t just look at aggregate metrics—have separate “agents” check for fairness, robustness, calibration, and latency. Consolidate findings into actionable insights.
Explicit principle extraction: The biggest takeaway is making implicit knowledge explicit. Most practitioners informally track “what works,” but formalizing it into a queryable knowledge base with confidence scores enables transfer and collaboration. If you’re doing any form of iterative experimentation, maintain a structured log of hypotheses, evidence, and confidence—not just results.
论文: 2604.12999 作者: Jaywon Koo, Jefferson Hernandez, Ruozhen He, Hanjie Chen, Chen Wei, Vicente Ordonez 分类: cs.CV
缺口
神经架构搜索(NAS)已经从随机搜索演化到复杂的优化方法,但现有方法把架构发现当作黑盒优化问题。
DARTS、ENAS 和演化算法等方法能高效探索设计空间,但不积累关于为什么某些设计选择有效的知识。
每次搜索都从零开始,丢弃成功架构背后的推理。
该领域已经达到高性能,但缺乏设计原则的可解释性和可迁移性。
问题:NAS 找到好架构但不理解设计原理
    |
    v
假设:架构发现可以模仿科学探究
    |
    v
方法:假设驱动的演化 + 置信度追踪
    |
    v
证据:CIFAR-10 上从 18.91% 到 94.11%,原则跨运行迁移
    |
    v
结论:显式假设追踪构建可复用知识
增量
一句话: 这篇论文之前,NAS 通过不透明的优化找架构;之后,它生成和测试显式假设,积累成可迁移的设计原则。
核心机制
HypoExplore 维护两个核心数据结构:记录所有提议架构谱系的轨迹树(Trajectory Tree),以及追踪设计原则置信度分数的假设记忆库(Hypothesis Memory Bank)。
树中的每个节点代表一个架构及其关联假设(例如”添加深度可分离卷积提高效率”)。
系统循环运作:LLM 使用双重策略选择父假设,该策略平衡利用(基于已验证想法)和探索(测试不确定想法),提出修改,实现为代码,训练架构,收集结果。
每次实验后,多个专门的反馈智能体从不同角度分析结果——一个检查准确率趋势,另一个检查参数效率,第三个查看训练稳定性。
这些智能体将观察结果整合为假设的置信度更新。
如果”深度可分离卷积提高效率”持续与更好的结果相关,其置信度分数上升。
如果在某些情况下失败,分数相应调整。
置信度分数指导未来的父节点选择,创建一个反馈循环,系统学习哪些原则是稳健的。
                    假设记忆库
                    [原则_1: 置信度=0.8]
                    [原则_2: 置信度=0.3]
                           |
                           v
    LLM 选择父节点 --> 生成新假设
           |                       |
           v                       v
    实现代码 <-------- 修改架构
           |
           v
    训练与评估
           |
           v
    反馈智能体(准确率、效率、稳定性)
           |
           v
    更新置信度分数 --> 回到记忆库
           |
           v
    添加到轨迹树(保留父子链接)
把 HypoExplore 想象成一个有持久实验记录本的研究实验室。
传统 NAS 就像为每个项目雇佣一个新研究员,他尝试随机实验,报告最佳结果,但不留笔记。
HypoExplore 是一个实验室,每个实验都记录其理由(假设),结果由委员会分析(反馈智能体),发现记录在共享笔记本(记忆库)中并带有置信度评级。
开始新实验时,研究员查阅笔记本,看哪些方法有强证据,哪些需要更多测试。
实验的家族树(轨迹树)显示哪些想法源自哪些,所以你可以追溯成功架构到其概念祖先。
随着时间推移,实验室建立机构知识——不只是”架构 X 有效”,而是”原则 Y 往往有效因为 Z”。
关键概念
- 假设置信度分数: HypoExplore 不只追踪架构是否表现良好,而是追踪对其背后**原则*的置信度。
想象你在学做饭。
你尝试在三道菜里加大蒜——两道很棒,一道一般。
你对”大蒜改善风味”的置信度高但不绝对。
如果后来你在甜点里试大蒜失败了,你的置信度变得依赖上下文:“大蒜改善咸味菜”。
HypoExplore 对架构原则做同样的事。
像”残差连接帮助深层网络”这样的假设从中性置信度开始。
随着实验积累,如果残差连接持续改善结果,分数上升,或者如果它们只在某些深度范围有帮助,分数变得细致。
分数是贝叶斯的——它随证据更新,可以表示不确定性。
- 双重探索策略: 系统必须平衡两个竞争目标:利用已验证原则(基于有效方法)与探索不确定原则(测试未经证实的想法)。
纯利用导致局部最优——你不断精炼同一想法。
纯探索浪费时间在随机猜测上。
HypoExplore 使用置信度分数平衡两者。
高置信度假设更常被选中(利用),但中等置信度的也有机会(探索)。
这就像科学家主要基于既定理论构建,但偶尔测试可能是突破的边缘想法。
选择概率与置信度成正比,但不是确定性的——即使低置信度假设也能被选中,只是很少。
- 轨迹树: 这不只是实验日志;它是想法的谱系。
每个节点是一个架构,边显示父子关系。
如果架构 B 是通过基于假设 H 修改架构 A 创建的,就有一条边 A→B 标记为 H。
这个结构揭示哪些原则是肥沃的(许多成功后代)与死胡同。
你可以追溯任何成功架构到其概念根源,看到导致那里的洞察序列。
它还支持原则的迁移学习:如果两个独立分支都发现”注意力机制提高准确率”,记忆库聚合来自两个谱系的证据,比任一分支单独更快地增强置信度。
框架转变
之前(主流 NAS):                之后(HypoExplore):

搜索空间                          假设空间
     |                                      |
     v                                      v
随机/梯度采样                      LLM 引导的构思
     |                                      |
     v                                      v
训练与评估                        训练与多智能体分析
     |                                      |
     v                                      v
保留最佳架构                      更新原则置信度
     |                                      |
     v                                      v
[丢弃推理]                        积累到记忆库
                                             |
                                             v
                                      迁移到新搜索
从隐式优化到显式推理,核心转变是让设计原则成为一等公民,在搜索运行中持久存在并迁移。
专家评审
选题眼光: 这是真实的缺口。
NAS 在性能上已经成熟,但仍是黑盒。
该领域已准备好可解释性——实践者想理解架构为什么有效,而不只是哪些有效。
考虑到 LLM 的推理能力,时机是对的。
然而,这个问题在某种程度上是人造的,因为许多研究者已经非正式地追踪设计原则;这篇论文将其形式化。
方法成熟度: 核心洞察——将架构搜索视为假设检验——是优雅的。
双重探索策略和置信度追踪有充分动机。
然而,对 LLM 进行假设生成的依赖是双刃剑:它支持丰富的推理,但引入脆弱性(提示敏感性、幻觉风险)。
多智能体反馈机制感觉略微过度设计;更简单的置信度更新规则可能就足够了。
该方法更多是”巧妙编排”而非”新颖算法”。
实验诚意: 18.91% → 94.11% 的改进很显著,但从故意弱的基线开始(可能是浅层网络)。
更有信息量的是从合理基线如 ResNet-18 开始。
CIFAR-10 结果是扎实的,泛化到 CIFAR-100、Tiny-ImageNet 和 MedMNIST 增强了主张。
“假设置信度分数变得越来越有预测性”的主张得到支持但未严格量化——相关性图会有帮助。
基线公平但不详尽;与最近的 NAS 方法如 AutoFormer 或 OFA 的比较会有价值。
写作功力: 论文结构良好,表达清晰。
轨迹树和记忆库概念解释直观。
然而,第 3.2 节(反馈智能体)含糊——这些智能体到底计算什么?论文将受益于展示示例假设及其随时间的置信度轨迹。
相关工作部分全面,但可以更好地将这项工作相对于元学习和神经架构迁移定位。
判决: 弱接收 — 假设驱动的框架是对 NAS 可解释性的有价值贡献,结果证明了可行性,但方法的复杂性和 LLM 依赖性引发了关于实际采用和可重复性的问题。
要点总结
置信度加权探索: 通过置信度分数平衡利用和探索的双重策略广泛适用。
在超参数调优中,你可以追踪对”学习率调度”或”正则化策略”的置信度,优先考虑经过充分验证的方法,同时偶尔测试不确定的方法。
这胜过纯网格搜索或随机搜索。
迭代设计的谱系追踪: 轨迹树概念迁移到任何迭代设计过程。
在提示工程中,追踪哪些提示修改源自哪些,以及哪些原则(例如”添加示例提高准确率”)在分支间有强证据。
在 A/B 测试中,维护功能变体及其理由的树。
多视角评估: 使用专门智能体从不同角度分析结果(准确率、效率、稳定性)是值得借鉴的模式。
在模型评估中,不只看聚合指标——让单独的”智能体”检查公平性、鲁棒性、校准和延迟。
将发现整合为可操作的洞察。
显式原则提取: 最大的收获是让隐性知识显性化。
大多数实践者非正式地追踪”什么有效”,但将其形式化为带置信度分数的可查询知识库支持迁移和协作。
如果你在做任何形式的迭代实验,维护假设、证据和置信度的结构化日志——不只是结果。