Paper: 2606.03965 Authors: Yu Xia, Zhouhang Xie, Xin Xu, Byungkyu Kang, Prarit Lamba, Xiang Gao, Julian McAuley Categories: cs.CL, cs.AI
The Gap
Current chain-of-thought reasoning lets models think longer for better accuracy, but wastes tokens on redundant steps and offers no inference-time control. Existing efficiency methods (shortening, early-stopping, compression) control how long the model thinks without controlling how it thinks—the reasoning strategy remains implicit in the frozen model weights. Users face a binary choice: full reasoning with high accuracy but wasteful tokens, or aggressive shortening with unpredictable quality loss.
Problem: CoT reasoning is token-inefficient + uncontrollable
    |
    v
Assumption: Strategy selection can be separated from reasoning execution
    |
    v
Method: MDP formulation with controller agent issuing (strategy, phrase) actions
    |
    v
Evidence: Matches full-thinking accuracy at 30-50% token cost across benchmarks
    |
    v
Conclusion: Explicit steering enables budget-aware controllable reasoning
The Increment
One sentence: Before—reasoning strategy is implicit and token budgets are enforced via crude length limits; after—an external controller explicitly steers strategy step-by-step within a budget.
Core Mechanism
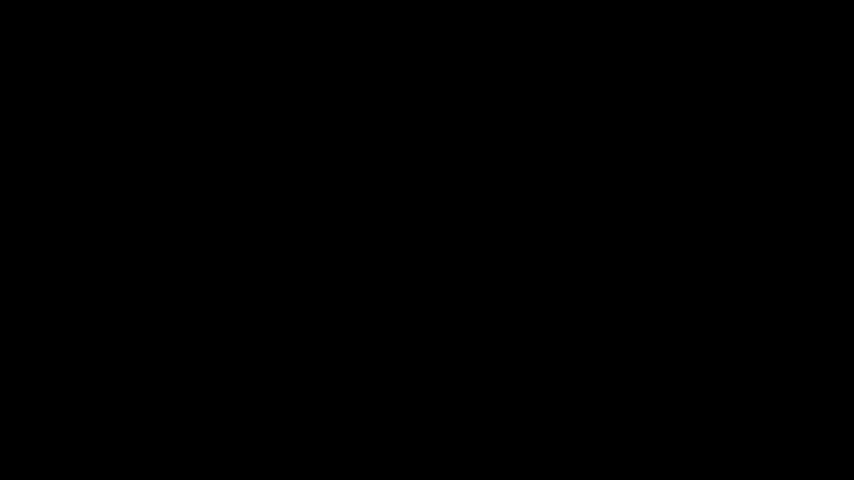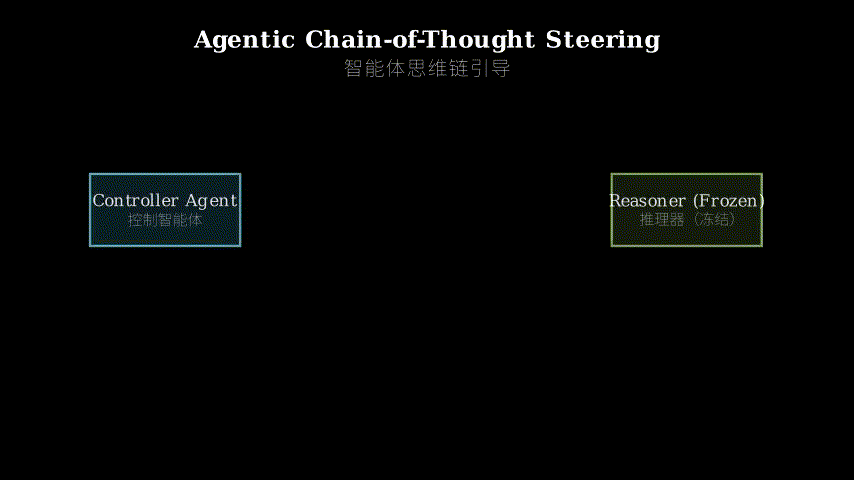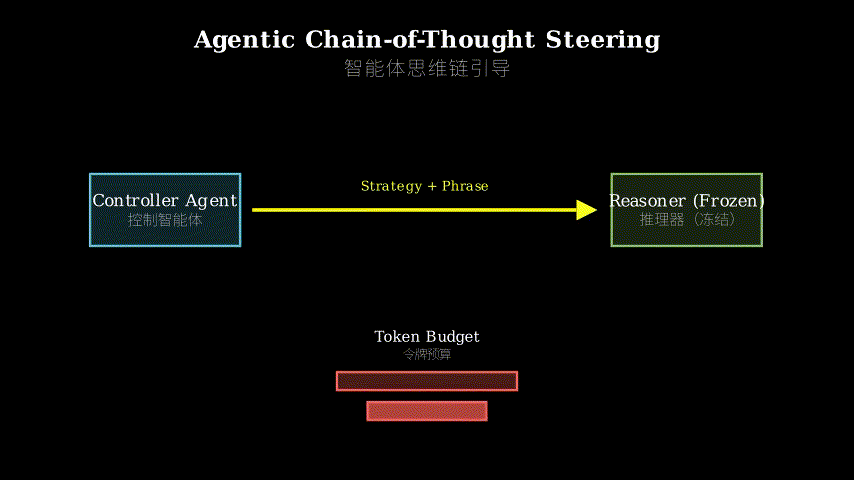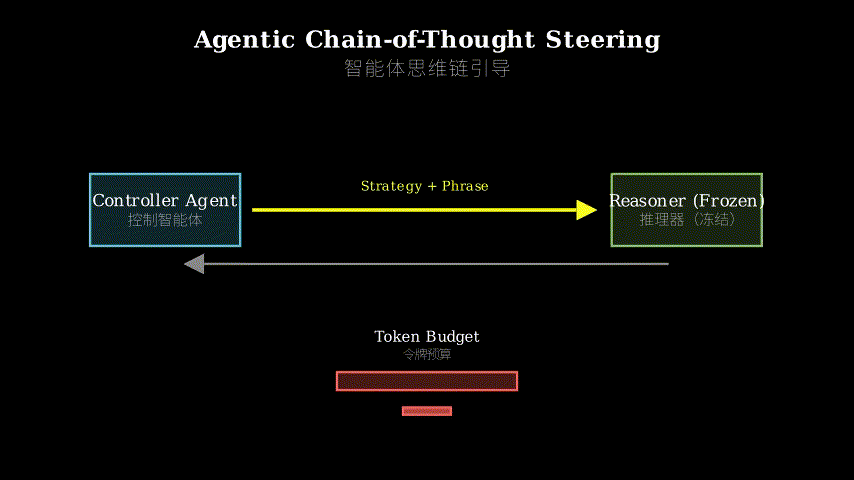
ACTS splits reasoning into two agents: a frozen reasoner (the LLM doing the thinking) and a trainable controller (the decision-maker). At each reasoning step, the controller observes the current trace and remaining token budget, then outputs a steering action: a reasoning strategy (e.g., “decompose problem,” “verify answer”) paired with a natural language steering phrase that initiates the reasoner’s next generation. The reasoner continues from this phrase, unaware it’s being steered. The controller is initialized on synthetic trajectories annotated with strategies, then optimized via reinforcement learning where reward incorporates both accuracy and budget adherence.
           Controller Agent
                  |
     [observe: trace + budget]
                  |
                  v
        +-------------------+
        | Select Strategy   |
        | Generate Phrase   |
        +-------------------+
                  |
          (strategy, phrase)
                  |
                  v
           Reasoner (frozen)
                  |
      [generate next reasoning step]
                  |
                  v
         Updated Trace ----> repeat until done
Think of ACTS like directing a method actor. The actor (reasoner) has the talent to deliver lines, but the director (controller) calls the shots: “Try a skeptical tone here,” “Now pivot to analyzing motives.” The director hands the actor a line to start from (“But what if the witness lied?”), and the actor improvises from there, staying in character. The director watches how much film stock (token budget) remains and adjusts pacing accordingly—sometimes letting the actor explore, sometimes cutting to the conclusion. The actor never breaks the fourth wall; from their perspective, each new line feels like a natural continuation of their performance.
Key Concepts
-
Steering phrase: A short text fragment (e.g., “Let’s verify:”, “Breaking this down:”) that the reasoner continues generating from. Unlike prompts that prepend instructions, steering phrases are inserted mid-reasoning to nudge direction without explicit commands. The reasoner treats them as its own thoughts, maintaining generation continuity. Example: After computing an intermediate result, the controller injects “Wait, let me double-check:” to trigger verification without telling the model “you must verify now.”
-
Budget-conditioned control: The controller receives the remaining token budget as part of its observation state and learns strategy policies conditional on budget. With plenty of budget, it selects exploratory strategies (decomposition, multiple verification passes); near the limit, it shifts to conclusive strategies (direct answering, skipping redundant checks). This differs from post-hoc early stopping—the controller proactively adapts its steering decisions based on budget, not reactively halting generation.
-
Multi-budget augmentation: During training, each reasoning trajectory is synthetically relabeled with multiple hypothetical budgets to teach the controller budget-aware behavior. A single trajectory becomes multiple training examples: “If you had 100 tokens, you’d reach this step,” “If you had 50, you’d skip verification here.” This augmentation bootstraps budget sensitivity without requiring expensive human annotation of budget-specific trajectories.
Framework Shift
Before (implicit strategy):          After (explicit steering):

User Query                           User Query + Budget
     |                                      |
     v                                      v
+------------+                       +------------+
|  Reasoner  |                       | Controller | <--+
| (generates |                       | (observes  |    |
|  full CoT) |                       |  + decides)|    |
+------------+                       +------------+    |
     |                                      |          |
     v                                      v          |
 Full trace                          Steering action   |
 (wasteful)                                 |          |
                                            v          |
                                      +------------+   |
                                      |  Reasoner  |   |
                                      | (executes  |   |
                                      |   step)    |   |
                                      +------------+   |
                                            |          |
                                            +----------+
                                       (loop until done)
From monolithic generation to stepwise steering, the core shift is separating strategy selection from execution.
Expert Assessment
Problem choice: Real gap, well-motivated. The tension between CoT’s accuracy gains and token costs is a genuine deployment blocker. Framing it as controllability—not just efficiency—positions this at the intersection of inference optimization and human-AI collaboration, which is timely.
Method maturity: The MDP formulation is clever but not groundbreaking—applying RL to control generation has precedent. The steering phrase mechanism is the genuinely novel part: it maintains generation fluency while enabling external control. However, the reliance on synthetic trajectory construction feels brittle—quality depends heavily on the strategy taxonomy design, which seems manually engineered rather than discovered.
Experimental integrity: Baselines are reasonable (standard CoT, static shortening, speculative decoding variants). The multi-budget evaluation across MATH, GSM8K, and reasoning benchmarks is thorough. Token savings (30-50%) are substantial and consistent. One concern: the controller is initialized on synthetic data generated by the same model family it later steers—this could inflate results if synthetic trajectories overfit to the reasoner’s quirks. Cross-model steering experiments (train controller on Llama, steer Gemini) would strengthen claims.
Writing quality: The method section is dense—packing MDP formulation, trajectory construction, and RL training into compact paragraphs. Splitting this into “System Design” and “Training Pipeline” subsections would improve clarity. The synthetic data generation process (Section 3.2) glosses over how strategy labels are assigned—is it rule-based matching or manual annotation? This ambiguity undermines reproducibility.
Verdict: weak accept — Solid execution on a real problem with measurable gains, but incremental architecture relying on manual strategy engineering limits generalizability.
Takeaways
Practitioners can steal the steering phrase pattern: instead of prepending control instructions to prompts, inject short continuation seeds mid-generation to nudge direction while preserving fluency. This applies beyond efficiency—use it for style control (injecting “In simpler terms:” for readability), safety (inserting “Let me reconsider the ethical implications:” mid-response), or debugging (adding “Show intermediate calculations:” during math reasoning).
The budget-conditioned RL reward shaping is portable: when optimizing any generation process with resource constraints (API cost, latency, memory), frame the controller’s reward as a weighted sum of task success and budget adherence, then vary the budget during training via augmentation. This teaches adaptive behavior without needing separate models for each budget tier.
Avoid the trap: Don’t build elaborate strategy taxonomies manually. If you go down this path, start minimal (3-4 strategies like “continue,” “verify,” “conclude”) and let interaction data reveal when finer-grained control is needed. Over-engineering the action space upfront leads to sparse learning signals and brittle policies.
论文: 2606.03965 作者: Yu Xia, Zhouhang Xie, Xin Xu, Byungkyu Kang, Prarit Lamba, Xiang Gao, Julian McAuley 分类: cs.CL, cs.AI
缺口
当前的思维链推理让模型通过延长思考来提高准确率,但在冗余步骤上浪费 token,且缺乏推理时控制。
现有的效率方法(缩短、提前停止、压缩)控制模型思考的时长,却不控制方式——推理策略隐藏在冻结的模型权重中。
用户面临二选一:完整推理带来高准确率但浪费 token,或激进缩短导致质量损失难以预测。
问题:CoT 推理 token 效率低 + 不可控
    |
    v
假设:策略选择可以与推理执行分离
    |
    v
方法:MDP 建模,控制器发出(策略,短语)动作
    |
    v
证据:多个基准测试上以 30-50% token 成本达到完整思考准确率
    |
    v
结论:显式引导实现预算感知的可控推理
增量
一句话: 之前——推理策略隐式,token 预算靠粗暴的长度限制强制执行;
之后——外部控制器在预算内逐步显式引导策略。
核心机制
ACTS 将推理拆分为两个智能体:冻结的推理器(执行思考的 LLM)和可训练的控制器(决策者)。
每一推理步,控制器观察当前轨迹和剩余 token 预算,然后输出一个引导动作:一个推理策略(如”分解问题”、“验证答案”)配对一个自然语言引导短语,用来启动推理器的下一次生成。
推理器从这个短语继续,对引导毫无察觉。
控制器先在标注了策略的合成轨迹上初始化,然后通过强化学习优化,奖励同时考虑准确率和预算遵守。
           控制器智能体
                  |
     [观察:轨迹 + 预算]
                  |
                  v
        +-------------------+
        | 选择策略          |
        | 生成短语          |
        +-------------------+
                  |
          (策略,短语)
                  |
                  v
           推理器(冻结)
                  |
      [生成下一推理步骤]
                  |
                  v
         更新轨迹 ----> 循环直到完成
把 ACTS 想象成导演指挥方法派演员。
演员(推理器)有台词功力,但导演(控制器)喊节奏:“这里试试怀疑的语气”、“现在转向分析动机”。
导演递给演员一句开场白(“但如果证人撒谎了呢?
”),演员即兴发挥,保持角色。
导演盯着胶片余量(token 预算)调整节奏——有时让演员探索,有时直接切到结论。
演员从不打破第四堵墙;
在他们视角里,每句新台词都像是表演的自然延续。
关键概念
- 引导短语: 推理器继续生成的短文本片段(如”让我们验证一下:”、“拆解来看:”)。
不同于在开头加指令的提示,引导短语插入推理中途来调整方向,不用显式命令。
推理器把它们当作自己的想法,保持生成连贯性。
例子:计算出中间结果后,控制器注入”等等,我再检查一遍:“触发验证,而不是告诉模型”你现在必须验证”。
- 预算条件控制: 控制器接收剩余 token 预算作为观察状态的一部分,学习基于预算的策略。
预算充足时,选探索性策略(分解、多次验证);
接近上限时,转向结论性策略(直接回答、跳过冗余检查)。
这不同于事后提前停止——控制器基于预算主动调整引导决策,而非被动截断生成。
- 多预算增强: 训练时,每条推理轨迹被合成地重标注多个假设预算,教会控制器预算感知行为。
一条轨迹变成多个训练样本:“如果你有 100 token,你会走到这一步”、“如果只有 50,你会跳过这里的验证”。
这种增强在不需要昂贵的人工标注预算特定轨迹的情况下,引导出预算敏感性。
框架转变
之前(隐式策略):               之后(显式引导):

用户查询                          用户查询 + 预算
     |                                      |
     v                                      v
+------------+                       +------------+
|  推理器    |                       | 控制器     | <--+
| (生成完整  |                       | (观察      |    |
|   CoT)     |                       |  + 决策)   |    |
+------------+                       +------------+    |
     |                                      |          |
     v                                      v          |
 完整轨迹                            引导动作           |
 (浪费)                                    |          |
                                           v          |
                                     +------------+   |
                                     |  推理器    |   |
                                     | (执行步骤) |   |
                                     +------------+   |
                                           |          |
                                           +----------+
                                      (循环直到完成)
从单体生成到逐步引导,核心转变是策略选择与执行分离。
专家评审
选题眼光: 真缺口,动机充分。
CoT 的准确率收益与 token 成本之间的张力是实际部署的拦路虎。
把它框定为可控性——而非单纯效率——把问题放在推理优化和人机协作的交叉点,很合时宜。
方法成熟度: MDP 建模巧妙但不算开创——用 RL 控制生成有先例。
引导短语机制是真正的新意:在保持生成流畅性的同时实现外部控制。
但对合成轨迹构建的依赖显得脆弱——质量高度依赖策略分类体系的设计,看起来是手工设计而非自动发现的。
实验诚意: 基线合理(标准 CoT、静态缩短、推测解码变体)。
在 MATH、GSM8K 和推理基准上的多预算评估很全面。
token 节省(30-50%)可观且一致。
一个担忧:控制器在同一模型家族生成的合成数据上初始化,然后去引导它——如果合成轨迹过拟合推理器的特性,可能虚高结果。
跨模型引导实验(在 Llama 上训练控制器,引导 Gemini)会强化结论。
写作功力: 方法部分密度大——把 MDP 建模、轨迹构建、RL 训练塞进紧凑的段落。
拆成”系统设计”和”训练流程”两个小节会更清晰。
合成数据生成过程(3.2 节)含糊其辞地略过策略标签如何分配——是基于规则匹配还是人工标注?
这种模糊损害了可复现性。
判决: 弱接收 — 在真实问题上扎实执行并有可测量收益,但架构渐进且依赖人工策略工程,限制了泛化性。
要点总结
实践者可以偷走引导短语模式:不在提示开头加控制指令,而是在生成中途注入短的续写种子来调整方向,同时保持流畅性。
这超越效率优化——用于风格控制(注入”简单来说:“提升可读性)、安全(插入”让我重新考虑伦理影响:“在响应中途)或调试(在数学推理时加”展示中间计算:”)。
预算条件 RL 奖励塑造是可移植的:优化任何有资源约束(API 成本、延迟、内存)的生成过程时,把控制器奖励框定为任务成功和预算遵守的加权和,然后训练时通过增强变化预算。
这教会自适应行为,不需要为每个预算层级准备单独模型。
避开陷阱:不要人工构建精细的策略分类体系。
如果走这条路,从最小集合开始(3-4 个策略如”继续”、“验证”、“结论”),让交互数据揭示何时需要更细粒度控制。
前期过度设计动作空间导致稀疏学习信号和脆弱策略。