Paper: 2603.18000 Authors: Zhang Zhang, Shuqi Lu, Hongjin Qian, Di He, Zheng Liu Categories: cs.AI
The Gap
LM-based agent self-evolution has been an active area for a couple of years now. The dominant approach — used in systems like Reflexion, ExpeL, and various memory-augmented agents — is to record what worked as natural language: a reflection, a lesson, a summarized strategy. The idea is that the agent reads these notes next time and does better.
The problem is that natural language is losy and ambiguous. “Remember to check edge cases before returning” is not the same as actually checking edge cases. When a task is complex and multi-step, a textual note about how to do it is a far cry from a working implementation. The agent still has to re-derive the solution from scratch, guided only by a vague hint. That’s fragile, especially when the task involves precise tool calls, data transformations, or orchestration logic.
This paper’s bet: if the solution worked, save the solution itself — as runable code — not a description of it.
Problem:
  Textual experience = losy compression of working solutions
  Re-execution from text = re-derivation under uncertainty
        |
        v
Assumption:
  Executable code is a lossless, portable, refinable artifact
        |
        v
Method:
  Save successful task solutions as Python subagent code
  Refine subagents via execution feedback over time
  Retrieve + compose subagents for new tasks
        |
        v
Evidence:
  Benchmark tasks solved faster + more reliably
  Subagent library grows; similar tasks cost less effort
        |
        v
Conclusion:
  Code-as-memory compounds; text-as-memory plateaus
The Increment
One sentence: Before this paper, agent self-evolution stored lessons as prose; after it, the system stores working programs that get better with use.
Core Mechanism
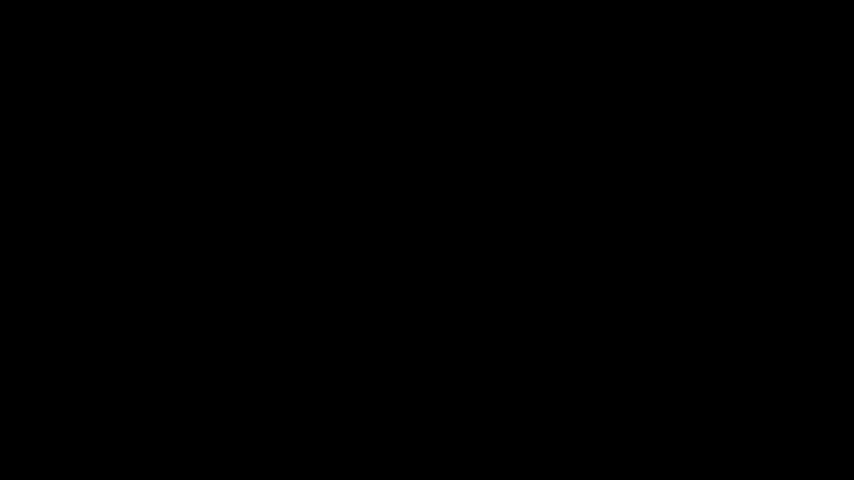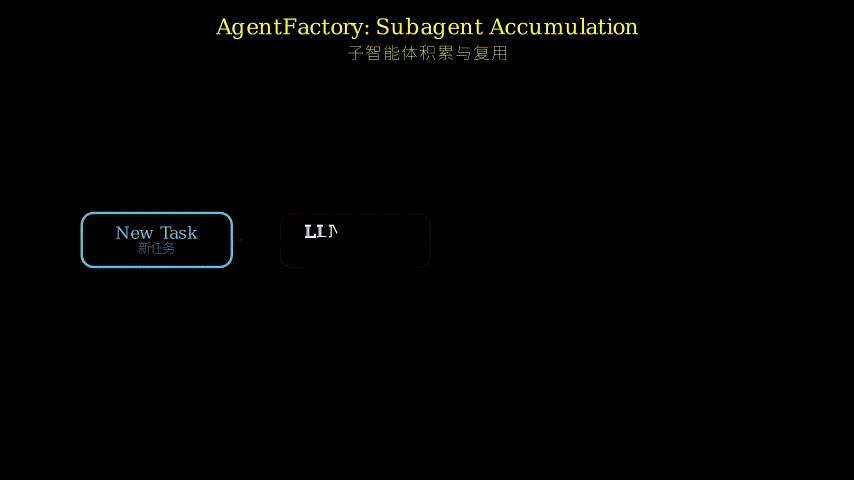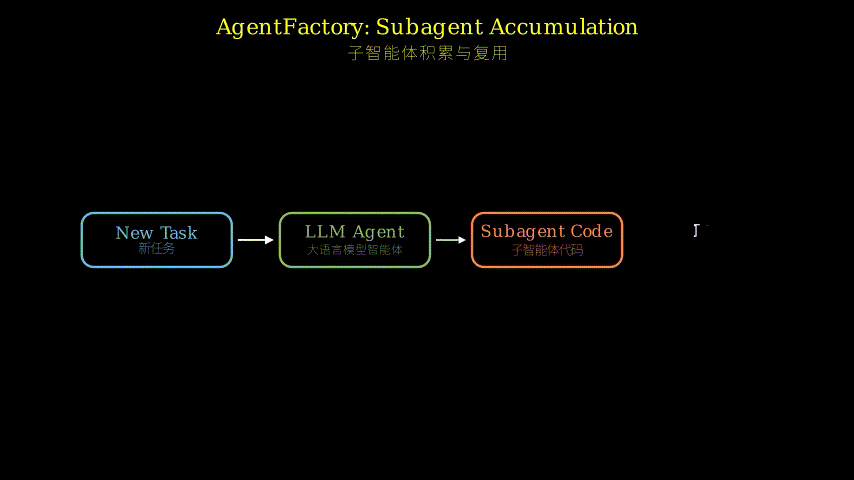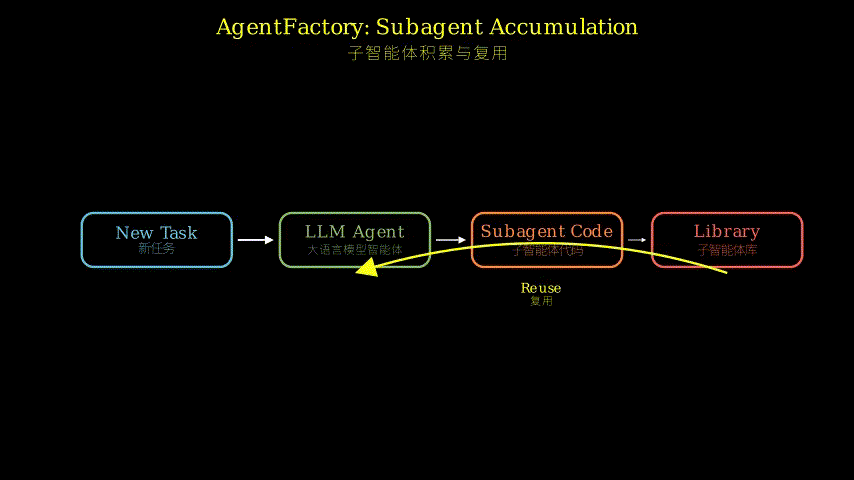
AgentFactory has three interlocking parts. First, when an agent successfully solves a task, the solution is serialized as a Python function or class — a subagent — with standardized docstrings describing what it does, what it expects, and what it returns. This goes into a library. Second, when a new task arrives, a retrieval step searches the library for relevant subagents using semantic similarity over the documentation. The orchestrator can then compose or adapt these subagents rather than generating everything from scratch. Third, after each execution, feedback (errors, partial failures, edge cases hit) is used to refine the subagent in place — the code gets patched, the docstring gets updated, and the library entry is replaced with the improved version.
The refinement loop is what makes this compound rather than just accumulate. A subagent that handles file parsing might start britle — it breaks on empty files. After encountering that case, it gets patched. Next time, it’s more robust. The library is not a static archive; it’s a living codebase that improves as the system encounters more variety.
Portability is a genuine design choice here. Because subagents are pure Python with no hidden state, they can be moved to any Python-capable environment. The library is not tied to a specific LM session or memory store — it’s just files.
New Task
   |
   v
[Retrieval] <--- Subagent Library (Python files + docs)
   |                ^
   v                    | refine / patch
[Orchestrator LM]      |
   |                    |
   +---> compose / adapt subagents
   |
   v
[Execution] --> feedback (errors, results)
   |
   v
[Refinement LM] ---> updated subagent code
                |
                            v
                back into Library
Think of it like a software team’s internal tooling repo. The first time someone needs to parse a weird CSV format, they write a one-off script. If it works, a good team member commits it to the shared utils folder with a docstring. Next time someone needs something similar, they search the repo, find it, maybe adapt it. Over time, the utils folder becomes genuinely useful — not because anyone planned it, but because each solved problem left a reusable artifact. AgentFactory is that process, automated. The LM is the developer, the subagent library is the utils repo, and the refinement loop is code review plus bug fixes happening automatically after each run.
Key Concepts
-
Executable subagent: A self-contained Python function or class that encodes a complete solution to a task type. The key word is “executable” — it’s not a description of what to do, it’s the thing that does it. When retrieved, it can be called directly or used as a template. Think of it as the difference between a recipe written in prose (“add flour until it feels right”) and an actual tested recipe with gram measurements.
-
Execution feedback refinement: After a subagent runs, the system captures what went wrong — exceptions, wrong outputs, missed edge cases — and feeds that back to an LLM to patch the code. This is automated debugging. The subagent doesn’t just accumulate runs; it gets fixed by them. The analogy is a function in a production codebase that gets bug reports filed against it and patches merged over time.
-
Capability compounding: Because subagents are reused and refined, the marginal cost of solving a task that resembles a previously solved one decreases over time. The system doesn’t start from zero each time. This is the core claim — not just that it works, but that it gets cheaper to operate as the library grows.
Framework Shift
Before (mainstream approach):        After (this paper):

Task solved                Task solved
   |                                    |
   v                                    v
Write reflection / lesson            Serialize solution as Python subagent
   |                                    |
   v                                    v
Store as text in memory              Store in executable library
   |                                    |
   v                                    v
Next similar task:                   Next similar task:
  LM reads notes                      Retrieve subagent by semantic search
  Re-derives solution                  Compose / adapt existing code
  (still starts near zero)             (starts from working solution)
   |                                    |
   v                                    v
No improvement to stored note        Execution feedback refines subagent
(static memory)                      (library improves over time)
From text-as-memory to code-as-memory, the core shift is treating successful solutions as first-class software artifacts rather than compressed summaries.
Expert Assessment
Problem choice: This is a real gap. The brittleness of textual self-reflection in agents is well-documented and genuinely annoying in practice. The paper is positioned at the right moment — agent frameworks are mature enough that the “store prompts and hope” approach is visibly hitting a ceiling. It’s not a manufactured problem.
Method maturity: The core idea is clean and the analogy to software engineering practices (shared utils, automated testing, code review) is load-bearing. That said, the retrieval and composition steps are doing a lot of work that the paper may underspecify. How does the orchestrator decide when to adapt vs. call a subagent directly? How are conflicts between subagents resolved? These feel like the hard parts, and short paper can over them.
Experimental integrity: Without seeing the full paper, the abstract’s framing — “progressively reducing effort for similar tasks” — is the right metric to test, but it’s also easy to cherry-pick. The honest question is whether the baselines include strong textual memory systems (not just vanilla LLMs) and whether the task distribution in evaluation is genuinely diverse or clustered around cases where code reuse is obviously helpful. The open-source release is a good sign for reproducibility.
Writing quality: The abstract is doing too much work justifying the premise and not enough showing the mechanism. The section that most needs rewriting is probably the subagent refinement loop — that’s where the real novelty lives, and it deserves a precise algorithmic description rather than a high-level narrative.
Verdict: weak accept — the idea is right and timely, but the paper needs to be more rigorous about the retrieval and composition mechanics, and the evaluation needs stronger baselines to be fully convincing.
Takeaways
A few things worth stealing:
The “save solutions as code, not prose” principle transfers directly to any system where you’re tempted to log LM outputs as text for future retrieval. If the output is structured or executable, serialize it that way. Retrieval over code with docstrings is more reliable than retrieval over free-form reflections.
The refinement-on-failure loop is a concrete pattern: run code, catch exceptions and wrong outputs, feed them back to an LLM with the original code and ask for a patch. This is implementable today in any agent framework and doesn’t require the full AgentFactory setup.
The portability constraint — pure Python, no hidden state — is a design discipline worth adopting. It forces you to make the knowledge artifact self-contained, which makes it testable, versionable, and transferable. That’s just good software engineering applied to agent memory.
论文: 2603.18000 作者: Zhang Zhang, Shuqi Lu, Hongjin Qian, Di He, Zheng Liu 分类: cs.AI
缺口
基于大语言模型的智能体自我进化已经研究了好几年。 主流做法——Reflexion、ExpeL 以及各种记忆增强智能体都在用——是把”什么方法有效”记录成自然语言:一段反思、一条经验、一个总结出来的策略。 逻辑是:下次遇到类似任务,智能体读一读这些笔记,就能做得更好。
问题在于,自然语言是有损压缩。 “记得在返回结果前检查边界情况”和真正去检查边界情况,是两回事。 当任务复杂、步骤繁多时,一段关于”如何做”的文字描述,和一个能跑起来的实现之间,差距巨大。 智能体仍然需要从头推导解法,只是多了一个模糊的提示而已。 这很脆弱,尤其是当任务涉及精确的工具调用、数据变换或编排逻辑时。
这篇论文的赌注是:如果一个解法有效,就把解法本身保存下来——以可运行代码的形式——而不是对它的描述。
问题:
  文本经验 = 有效解法的有损压缩
  从文本重新执行 = 在不确定性下重新推导
        |
        v
假设:
  可执行代码是无损、可移植、可精炼的制品
        |
        v
方法:
  将成功的任务解法保存为 Python 子智能体代码
  通过执行反馈持续精炼子智能体
  检索并组合子智能体来处理新任务
        |
        v
证据:
  基准任务解决得更快、更可靠
  子智能体库增长;相似任务所需努力递减
        |
        v
结论:
  代码记忆会复利增长;文本记忆会触及天花板
增量
一句话:这篇论文之前,智能体自我进化把经验存成散文;之后,系统存储的是会随使用而变好的可运行程序。
核心机制
AgentFactory 有三个相互咬合的部分。
第一,当智能体成功解决一个任务时,解法被序列化为一个 Python 函数或类——即子智能体——并附有标准化的文档字符串,描述它做什么、期望什么输入、返回什么输出。 这个子智能体进入一个库。
第二,当新任务到来时,系统通过对文档的语义相似度检索,在库中找到相关的子智能体。 编排器可以直接组合或适配这些子智能体,而不是从零生成所有内容。
第三,每次执行后,反馈信息(报错、部分失败、遇到的边界情况)被用来就地精炼子智能体——代码被打补丁,文档被更新,库中的条目被替换为改进后的版本。
精炼循环是让系统”复利增长”而不只是”线性积累”的关键。 一个处理文件解析的子智能体一开始可能很脆弱——遇到空文件就崩。 遇到这个情况后,它被打了补丁。 下次,它更健壮了。 这个库不是静态档案,而是一个随着系统遇到更多变化而持续改进的活代码库。
可移植性是一个真实的设计选择。 因为子智能体是纯 Python、没有隐藏状态,它们可以被迁移到任何支持 Python 的环境。 库不依赖特定的 LLM 会话或记忆存储——它就是一堆文件。
新任务
   |
   v
[检索模块] <--- 子智能体库(Python 文件 + 文档)
   |                    ^
   v                    | 精炼 / 打补丁
[编排器 LLM]            |
   |                    |
   +---> 组合 / 适配子智能体
   |
   v
[执行] ---> 反馈(报错、结果)
   |
   v
[精炼 LLM] ---> 更新后的子智能体代码
                      |
                      v
               写回子智能体库
把它想象成一个软件团队的内部工具库。 第一次有人需要解析一种奇怪的 CSV 格式,他们写了一个临时脚本。 如果跑通了,一个好的团队成员会把它提交到共享的 utils 文件夹,附上文档注释。 下次有人需要类似功能,他们搜索仓库,找到它,也许稍作修改就能用。 随着时间推移,utils 文件夹变得真正有用——不是因为有人事先规划,而是因为每个被解决的问题都留下了一个可复用的制品。
AgentFactory 就是这个过程的自动化版本。 LM 是开发者,子智能体库是 utils 仓库,精炼循环是每次运行后自动发生的代码审查加 bug 修复。
关键概念
-
可执行子智能体:一个自包含的 Python 函数或类,编码了某类任务的完整解法。关键词是”可执行”——它不是对”该怎么做”的描述,而是真正去做这件事的东西。被检索到时,可以直接调用,也可以作为模板使用。就像散文食谱(“加面粉直到手感合适”)和一份经过测试、有克重的精确食谱之间的区别。
-
执行反馈精炼:子智能体运行后,系统捕获出错的地方——异常、错误输出、遗漏的边界情况——并将其反馈给 LLM 来打补丁。这是自动化调试。子智能体不只是积累运行次数,而是被这些运行修复。类比是生产代码库中的一个函数,持续收到 bug 报告并合并补丁。
-
能力复利:因为子智能体被复用和精炼,解决一个与之前已解决任务相似的新任务的边际成本会随时间下降。系统不是每次都从零开始。这是核心主张——不只是”它有效”,而是”随着库的增长,运营成本越来越低”。
框架转变
之前(主流方法):                之后(本文方法):

任务解决                              任务解决
   |                     |
   v                                     v
写反思 / 经验总结                     将解法序列化为 Python 子智能体
   |                                     |
   v                                     v
以文本形式存入记忆                    存入可执行库
   |                                     |
   v                                     v
下次遇到相似任务:                    下次遇到相似任务:
  LM 读笔记                            语义检索子智能体
  重新推导解法                          组合 / 适配现有代码
  (仍然接近从零开始)                  (从有效解法出发)
   |                                     |
   v                                     v
存储的笔记没有改进                    执行反馈精炼子智能体
(静态记忆)                          (库随时间改进)
从文本记忆到代码记忆,核心转变是把成功的解法当作一等软件制品来对待,而不是压缩后的摘要。
专家评审
选题眼光:这是真实的缺口。 文本自我反思在智能体中的脆弱性有充分记录,在实践中确实令人头疼。 论文的时机选得好——智能体框架已经足够成熟,“存提示词然后祈祷”的方式明显在触碰天花板。 这不是人造问题。
方法成熟度:核心思路干净,与软件工程实践(共享工具库、自动测试、代码审查)的类比是承重的。 但检索和组合步骤承担了大量工作,论文可能规格说明不足。 编排器如何决定何时适配、何时直接调用子智能体? 子智能体之间的冲突如何解决? 这些感觉是难点,短篇论文容易在这里一笔带过。
实验诚意:不看全文的情况下,摘要的表述——“相似任务所需努力递减”——是正确的评估指标,但也很容易挑好看的案例展示。 诚实的问题是:基线是否包含强文本记忆系统(而不只是普通 LLM),评估中的任务分布是否真正多样,还是集中在代码复用明显有利的场景。 开源发布对可复现性是个好信号。
写作功力:摘要花了太多篇幅论证前提,展示机制的笔墨不够。 最需要重写的部分大概是子智能体精炼循环——那是真正的新颖性所在,值得一个精确的算法描述,而不是高层次的叙述。
判决:弱接收——思路正确且时机合适,但论文需要对检索和组合机制更严格,评估也需要更强的基线才能真正令人信服。
要点总结
几个值得借鉴的具体做法:
“把解法存为代码而非散文”这个原则,可以直接迁移到任何你想把 LM 输出记录为文本以备将来检索的系统。 如果输出是结构化的或可执行的,就用那种形式序列化。 对带文档字符串的代码做检索,比对自由格式的反思做检索更可靠。
失败时精炼的循环是一个具体的模式:运行代码,捕获异常和错误输出,把它们连同原始代码一起反馈给 LLM,请它打补丁。 这在任何智能体框架中今天就能实现,不需要完整的 AgentFactory 架构。
可移植性约束——纯 Python、无隐藏状态——是一种值得采用的设计纪律。 它迫使你让知识制品自包含,从而可测试、可版本化、可迁移。 这本质上是把良好的软件工程实践应用到智能体记忆上。