Paper: 2603.11044 Authors: Siyi Qian, Xiongfei Bai, Bingtao Fu, Yichen Lu, Gaoyang Zhang, Xudong Yang, Peng Zhang Categories: cs.CV
The Gap
Existing document parsing systems treat PDFs as sequences of independent pages. This works fine for simple documents, but financial reports—think 200-page annual reports with tables spanning multiple pages, nested section hierarchies, and the need to trace every number back to its source cell—break this paradigm. Prior approaches like LayoutLM, Donut, and Nougat parse page-by-page, which means a table split across pages becomes two disconnected fragments. You lose the thread of “this row continues from the previous page” and “this section is a subsection of something 50 pages back.”
The core problem: page boundaries are typographic artifacts, not semantic ones. But most parsers treat them as hard walls.
Problem: Financial PDFs with cross-page structures
    |
    v
Assumption: Document-level context > page-level context
    |
    v
Method: Cross-page consolidation + global TOC tree + curriculum learning
    |
    v
Evidence: FinDocBench benchmark shows improved continuity metrics
    |
    v
Conclusion: Document-level parsing enables auditing-grade provenance
The Increment
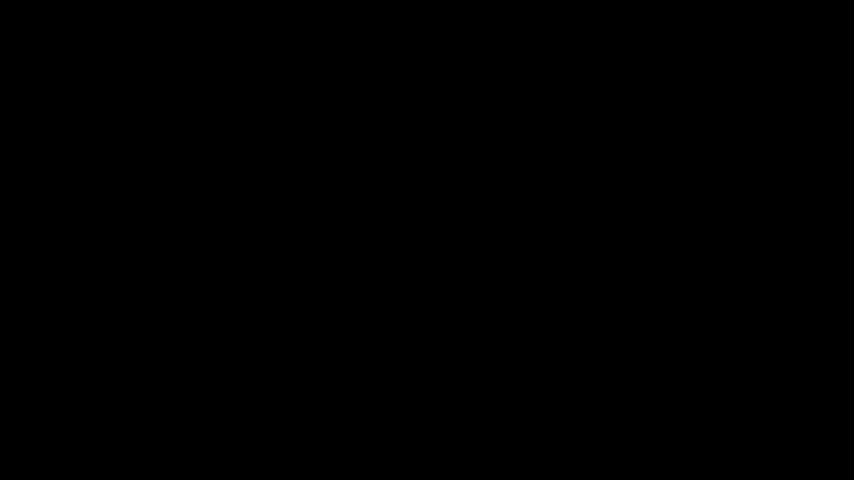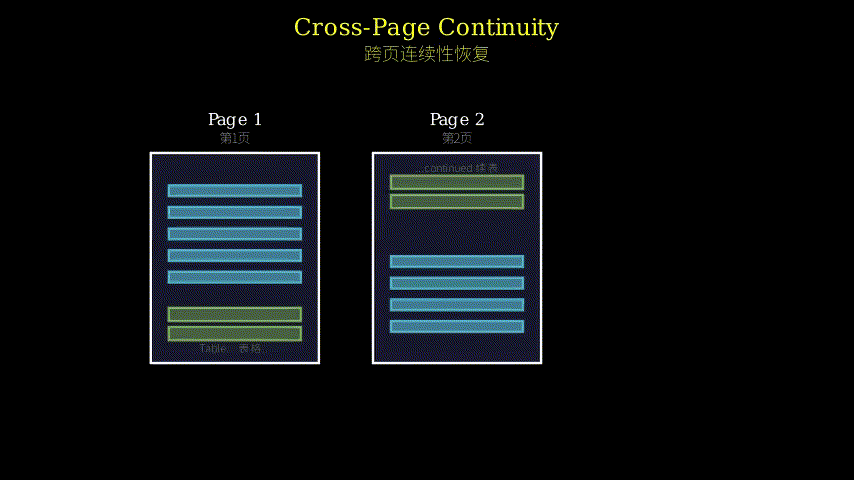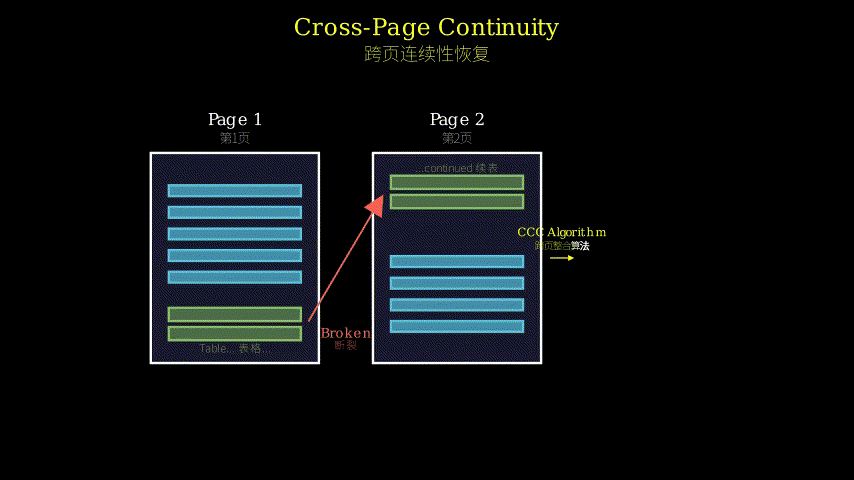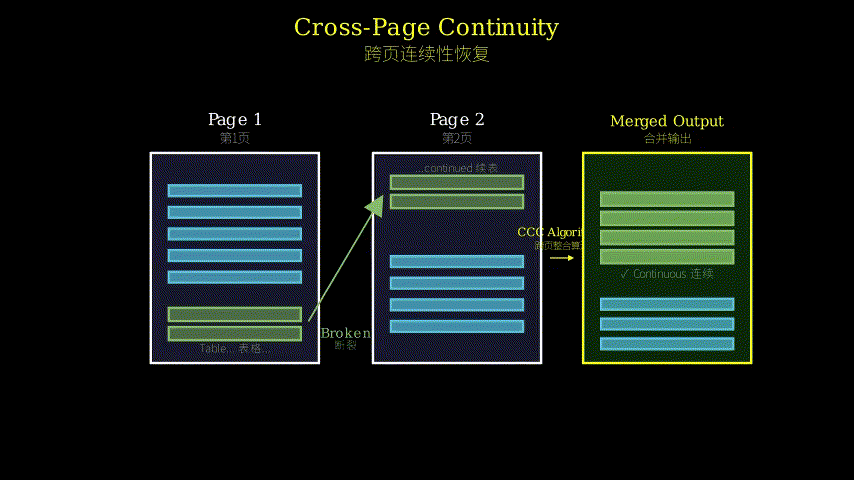
One sentence: Before this paper, you got fragmented page-by-page outputs; after, you get a continuous document-level structure where tables and sections flow across page breaks.
Core Mechanism
The system has four main components working in sequence. First, a Cross-page Contents Consolidation algorithm scans for structural elements (tables, lists, sections) that are split across page boundaries and stitches them back together. Second, a Document-level Heading Hierarchy Reconstruction (DHR) module analyzes all headings across the entire document to build a global Table of Contents tree—not just “this page has these headings” but “heading 3.2.1 is nested under 3.2 which is under 3.”
Third, for table parsing specifically, they use difficulty-adaptive curriculum learning: train the model on simple tables first (few rows, clear borders), then gradually introduce harder cases (merged cells, no borders, complex layouts). Fourth, the CellBBoxRegressor module is the clever bit—instead of using an external object detector to find table cells, it uses structural anchor tokens embedded in the decoder’s hidden states. The decoder learns to emit special tokens that mark cell boundaries, and these tokens’ hidden states are used to regress bounding boxes directly.
Input PDF (200 pages)
    |
    v
[Cross-page Consolidation]  <-- Reconnects split tables/sections
    |
    v
[DHR Module]  <-- Builds global TOC tree
    |
    v
[Table Parser + Curriculum Learning]  <-- Easy -> Hard training
    |
    v
[CellBBoxRegressor]  <-- Anchor tokens -> bounding boxes
    |
    v
Structured Output (continuous, hierarchical)
Think of it like reassembling a book that was arbitrarily chopped into page-sized chunks and scattered. The cross-page consolidation is like finding pieces that clearly belong together—“this sentence ends mid-word on page 47 and continues on page 48.” The DHR module is like rebuilding the original table of contents by looking at all chapter and section markers across the entire book, not just within each chunk. The curriculum learning is like training a cataloger by starting with children’s books (simple structure) before moving to academic texts (complex nested sections). And the anchor tokens are like using the book’s own internal bookmarks (chapter markers, section dividers) to navigate, rather than needing an external GPS to tell you where each paragraph is.
Key Concepts
-
Cross-page Consolidation: Imagine you’re reading a financial table, and the page ends mid-row. The next page starts with what looks like a continuation, but how do you know for sure? Cross-page consolidation uses heuristics—matching column structures, checking for continuation markers, analyzing whitespace patterns—to decide “yes, these two table fragments are actually one table.” It’s not just concatenation; it’s semantic stitching. Example: Page 47 ends with “Revenue | 2023 | 1.5M”—same column structure, clearly a continuation.
-
Document-level TOC Tree: Most parsers see headings locally: “this page has a heading that looks like level 2.” But is it 2.1 or 3.2 or 5.4? A document-level TOC tree tracks the entire hierarchy across all pages. It knows that “Risk Factors” on page 30 is section 3, and “Market Risk” on page 35 is subsection 3.1, and “Interest Rate Risk” on page 37 is 3.1.1. This enables structure-aware retrieval: “give me everything under section 3” means pages 30-50, not just page 30.
-
Structural Anchor Tokens: Traditional table parsing uses an object detector to draw boxes around cells, then feeds those boxes to a model. Anchor tokens flip this: the decoder itself emits special tokens (like
<cell_start>,<cell_end>) as it generates the table structure, and these tokens’ hidden states encode spatial information. You train a small regressor on top of these hidden states to predict bounding boxes. Why is this better? One less module to maintain, and the spatial information is grounded in the decoder’s understanding of table structure, not a separate vision model.
Framework Shift
Before (page-level):                After (document-level):

Page 1 -> Parse -> Output 1         Entire PDF
Page 2 -> Parse -> Output 2             |
Page 3 -> Parse -> Output 3             v
  ...                               [Build Global Context]
Page N -> Parse -> Output N             |
                                        v
(Fragments, no continuity)          [Parse with Continuity]
                                        |
                                        v
                                    Single Structured Output
                                    (Tables intact, TOC tree)
From isolated page processing to holistic document understanding, the core shift is treating page breaks as noise to be removed rather than natural boundaries to respect.
Expert Assessment
Problem choice: This is a real gap, not manufactured. Anyone who’s tried to extract data from a 300-page financial report knows the pain of tables split across pages. The “auditing-grade provenance” framing is smart—it’s not just about accuracy, but traceability, which matters in finance. The problem sits at the intersection of document AI and domain-specific needs, which is a productive space.
Method maturity: Mix of solid engineering (cross-page consolidation is mostly heuristics and rules) and ML innovation (anchor tokens, curriculum learning). The anchor token approach is genuinely clever—avoiding external detectors simplifies the pipeline. But I’m skeptical about how much the curriculum learning actually helps versus just training longer. The paper doesn’t ablate this clearly.
Experimental integrity: They created their own benchmark (FinDocBench), which is necessary for domain-specific evaluation but raises questions about generalization. The baselines include strong models (Nougat, Donut), but it’s unclear if those models were fine-tuned on financial documents or used zero-shot. The metrics (TocEDS, cross-page TEDS, C-IoU) are reasonable but custom, making it hard to compare to other work. I’d want to see results on a public benchmark too.
Writing quality: The abstract is acronym soup (DHR, TOC, TEDS, C-IoU) without enough motivation upfront. The paper would benefit from a clearer “here’s a real financial document and here’s what breaks” example in the intro. The method section is dense—probably could split the table parsing and document structure parts into separate sections for clarity.
Verdict: Weak accept — solid engineering work addressing a real problem with some clever ideas (anchor tokens), but the evaluation is limited to a custom benchmark and the writing could be clearer.
Takeaways
Curriculum learning for structured parsing: Start training on simple examples (clean tables, clear hierarchies) and gradually introduce complexity. This isn’t just for tables—you could apply it to any structured extraction task where examples vary widely in difficulty.
Decoder-based localization: Instead of using external object detectors, embed spatial information in the decoder’s hidden states via special tokens. This reduces pipeline complexity and grounds spatial understanding in semantic structure.
Document-level vs page-level processing: For any multi-page document task, ask: “Are page boundaries semantically meaningful?” If not, design your system to operate at document level, treating pages as an artifact to be abstracted away.
Domain-specific benchmarks: When existing benchmarks don’t capture your domain’s challenges (cross-page continuity, cell-level provenance), build your own. But make sure to also report on public benchmarks for comparability.
论文: 2603.11044 作者: Siyi Qian, Xiongfei Bai, Bingtao Fu, Yichen Lu, Gaoyang Zhang, Xudong Yang, Peng Zhang 分类: cs.CV
缺口
现有的文档解析系统把PDF当作一系列独立页面来处理。
这对简单文档没问题,但金融报告——想想200页的年报,表格跨越多页,嵌套的章节层次,还需要把每个数字追溯到源单元格——会打破这种范式。
LayoutLM、Donut、Nougat等先前方法都是逐页解析,这意味着跨页分割的表格会变成两个断开的碎片。
你会失去”这一行从上一页延续而来”和”这个章节是50页前某个章节的子章节”这样的线索。
核心问题:页面边界是排版产物,不是语义边界。
但大多数解析器把它们当作硬墙。
问题:带有跨页结构的金融PDF
    |
    v
假设:文档级上下文 > 页面级上下文
    |
    v
方法:跨页合并 + 全局目录树 + 课程学习
    |
    v
证据:FinDocBench基准显示连续性指标改善
    |
    v
结论:文档级解析实现审计级溯源
增量
一句话: 这篇论文之前,你得到的是碎片化的逐页输出;之后,你得到连续的文档级结构,表格和章节在页面边界间流畅衔接。
核心机制
系统有四个主要组件按顺序工作。
首先,跨页内容合并算法扫描被页面边界分割的结构元素(表格、列表、章节),把它们重新拼接起来。
其次,文档级标题层次重建(DHR)模块分析整个文档的所有标题,构建全局目录树——不只是”这一页有这些标题”,而是”标题3.2.1嵌套在3.2下,3.2又在3下”。
第三,专门针对表格解析,他们使用难度自适应课程学习:先在简单表格上训练模型(少量行、清晰边框),然后逐渐引入更难的情况(合并单元格、无边框、复杂布局)。
第四,CellBBoxRegressor模块是巧妙之处——它不使用外部目标检测器来查找表格单元格,而是使用嵌入在解码器隐藏状态中的结构锚点标记。
解码器学会发出标记单元格边界的特殊标记,这些标记的隐藏状态被直接用于回归边界框。
输入PDF(200页)
    |
    v
[跨页合并]  <-- 重连分割的表格/章节
    |
    v
[DHR模块]  <-- 构建全局目录树
    |
    v
[表格解析器 + 课程学习]  <-- 简单 -> 困难训练
    |
    v
[CellBBoxRegressor]  <-- 锚点标记 -> 边界框
    |
    v
结构化输出(连续、分层)
把它想象成重新组装一本被任意切成页面大小碎片并打散的书。
跨页合并就像找到明显属于一起的碎片——“这个句子在第47页中间断开,在第48页继续”。
DHR模块就像通过查看整本书的所有章节和小节标记来重建原始目录,而不只是看每个碎片内部。
课程学习就像训练图书管理员,从儿童读物(简单结构)开始,然后再处理学术文本(复杂嵌套章节)。
锚点标记就像使用书本自己的内部书签(章节标记、小节分隔符)来导航,而不需要外部GPS告诉你每段在哪里。
关键概念
- 跨页合并: 想象你在读一张金融表格,页面在行中间结束。
下一页看起来像是延续,但你怎么确定?跨页合并使用启发式方法——匹配列结构、检查延续标记、分析空白模式——来判断”是的,这两个表格碎片实际上是一张表”。
这不只是拼接;这是语义缝合。
例子:第47页以”收入 | 2023 | 1.5M”开始——相同的列结构,显然是延续。
- 文档级目录树: 大多数解析器局部地看标题:“这一页有个看起来像2级的标题”。
但它是2.1还是3.2还是5.4?文档级目录树跟踪所有页面的整个层次结构。
它知道第30页的”风险因素”是第3节,第35页的”市场风险”是3.1小节,第37页的”利率风险”是3.1.1。
这使得结构感知检索成为可能:“给我第3节下的所有内容”意味着第30-50页,而不只是第30页。
- 结构锚点标记: 传统表格解析使用目标检测器在单元格周围画框,然后把这些框送给模型。
锚点标记翻转了这个过程:解码器本身在生成表格结构时发出特殊标记(如<cell_start>、<cell_end>),这些标记的隐藏状态编码空间信息。
你在这些隐藏状态之上训练一个小型回归器来预测边界框。
为什么更好?少维护一个模块,而且空间信息基于解码器对表格结构的理解,而不是单独的视觉模型。
框架转变
之前(页面级):                  之后(文档级):

第1页 -> 解析 -> 输出1            整个PDF
第2页 -> 解析 -> 输出2                |
第3页 -> 解析 -> 输出3                v
  ...                           [构建全局上下文]
第N页 -> 解析 -> 输出N                |
                                      v
(碎片,无连续性)                [带连续性解析]
                                      |
                                      v
                                  单一结构化输出
                                  (表格完整,目录树)
从孤立的页面处理到整体的文档理解,核心转变是把页面边界当作需要消除的噪声,而不是需要尊重的自然边界。
专家评审
选题眼光: 这是真实缺口,不是人造的。
任何试图从300页金融报告中提取数据的人都知道跨页分割表格的痛苦。
“审计级溯源”的框架很聪明——不只是准确性,还有可追溯性,这在金融领域很重要。
这个问题处于文档AI和领域特定需求的交叉点,是个富有成效的空间。
方法成熟度: 扎实工程(跨页合并主要是启发式和规则)和机器学习创新(锚点标记、课程学习)的混合。
锚点标记方法确实巧妙——避免外部检测器简化了流程。
但我对课程学习实际帮助有多大持怀疑态度,相比只是训练更长时间。
论文没有清楚地消融这一点。
实验诚意: 他们创建了自己的基准(FinDocBench),这对领域特定评估是必要的,但引发了泛化性问题。
基线包括强模型(Nougat、Donut),但不清楚这些模型是在金融文档上微调还是零样本使用。
指标(TocEDS、跨页TEDS、C-IoU)合理但定制,使得与其他工作比较困难。
我希望看到在公开基准上的结果。
写作功力: 摘要是缩写词汤(DHR、TOC、TEDS、C-IoU),前面没有足够的动机。
论文会受益于在引言中有更清晰的”这是一个真实金融文档,这是什么会出错”的例子。
方法部分很密集——可能可以把表格解析和文档结构部分分成独立章节以提高清晰度。
判决: 弱接收 — 解决真实问题的扎实工程工作,有一些巧妙想法(锚点标记),但评估局限于定制基准,写作可以更清晰。
要点总结
结构化解析的课程学习: 从简单示例(干净表格、清晰层次)开始训练,逐渐引入复杂性。
这不只适用于表格——你可以把它应用到任何示例难度差异很大的结构化提取任务。
基于解码器的定位: 不使用外部目标检测器,而是通过特殊标记在解码器隐藏状态中嵌入空间信息。
这减少了流程复杂性,并将空间理解基于语义结构。
文档级vs页面级处理: 对于任何多页文档任务,问:“页面边界在语义上有意义吗?“如果没有,设计你的系统在文档级操作,把页面当作需要抽象掉的产物。
领域特定基准: 当现有基准无法捕捉你领域的挑战(跨页连续性、单元格级溯源)时,构建自己的。
但确保也在公开基准上报告结果以便比较。