Paper: 2606.28270 Authors: Bo Shen, Lifeng Chang, Tianyuan Wei, Yunpeng Li, Feng Shi, Yichen Han, Peijie Gao, Shiyi Kuang, Xin Chang, Dehui Li Categories: cs.AI, cs.MA
The Gap
Existing defenses for autonomous AI agents rely on perimeter security (firewalls, sandboxing) and training-time alignment (RLHF, constitutional AI). Both sit entirely outside the agent’s active reasoning loop.
This means a fully aligned agent can still be hijacked at runtime via memory poisoning, tool-chain manipulation, or multi-agent protocol attacks.
The paper argues we need an endogenous defense—something that lives inside the agent’s cognitive loop, like a biological immune system.
+---------------------------+    +----------------------+    +---------------------------+
|  Problem: runtime        |--->|  Assumption: external |--->|  Method: Agent-Native     |
|  attacks evade external  |    |  defenses are         |    |  Immune System (ANIS)     |
|  defenses                |    |  fundamentally        |    |  with six-layer Immune   |
+---------------------------+    |  insufficient         |    |  Tower + Harness Triad   |
                                 +----------------------+    +---------------------------+
                                                                    |
                                                                    v
                                 +---------------------------+    +---------------------------+
                                 |  Evidence: unified       |<---|  Conclusion: dynamic      |
                                 |  taxonomy of Agent       |    |  runtime immunity fills   |
                                 |  Viruses/Vaccines + CIL  |    |  the gap between training |
                                 +---------------------------+    |  and execution            |
                                                                  +---------------------------+
The Increment
One sentence: Before this paper, AI agents had no internal runtime defense; after this paper, they gain a self-monitoring, adaptive immune system that operates inside their own reasoning loop—analogous to how the human immune system works inside a body.
Core Mechanism
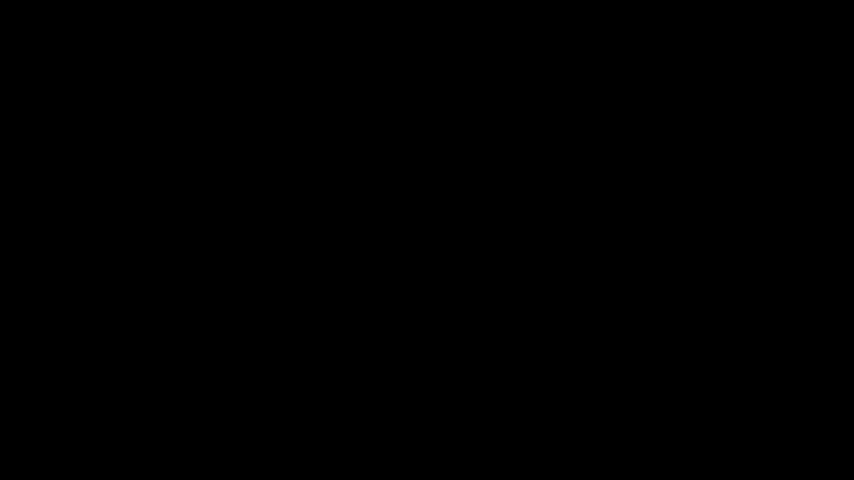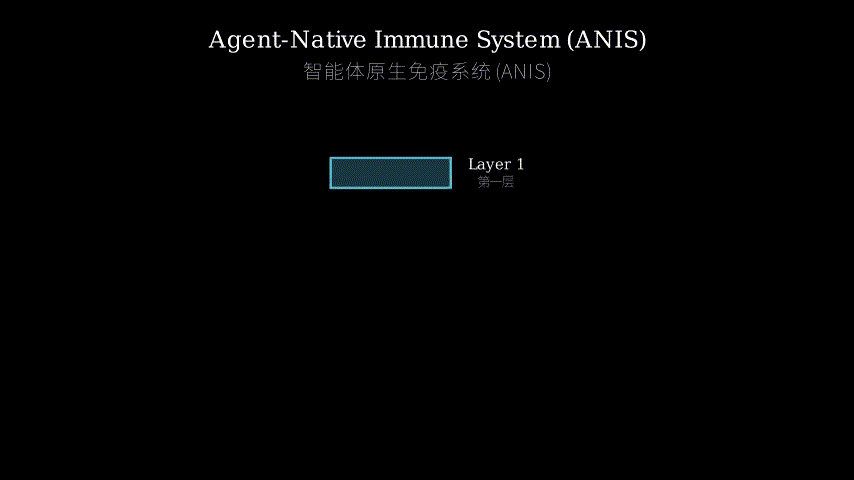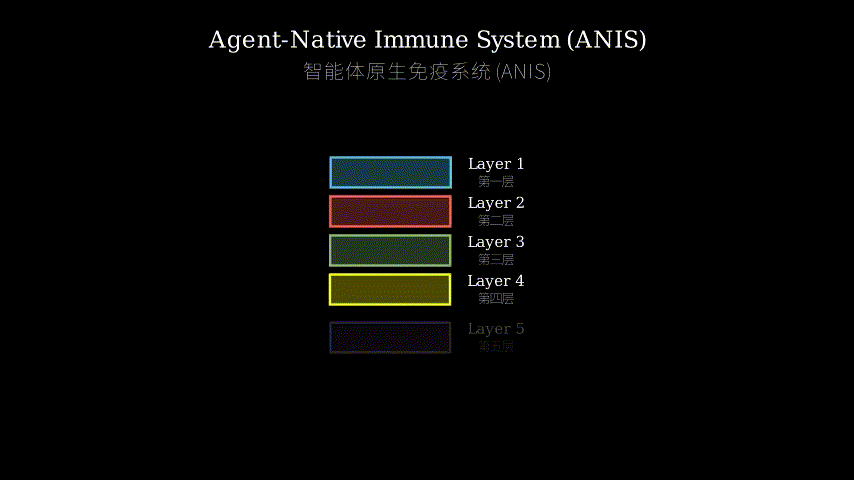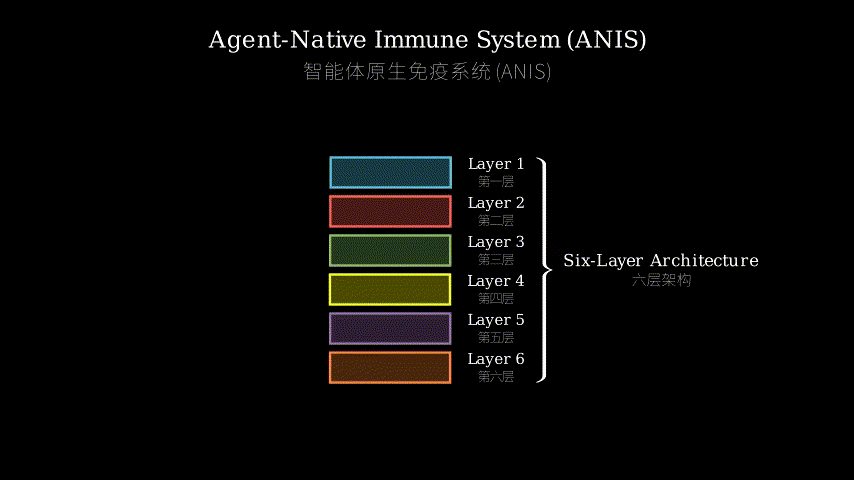
ANIS is structured as a six-layer Immune Tower, labelled L0 through L5, embedded directly into the agent’s cognitive architecture.
- L0 is the hardware/firmware root of trust.
- L1 (Barrier Immunity) is a non-cognitive, physical-and-logical isolation layer—think of it as a strict separation between the agent’s internal state and any external input that hasn’t been sanitised.
- L2–L4 handle detection, classification, and response, much like innate immunity in biology.
- L5 is the adaptive layer, where a Continual Immune Learning (CIL) process updates the agent’s internal “vaccines” over time.
Above the tower sits the Harness Triad—Meta, Self, and Auto—a meta-cognitive supervisor that monitors the tower’s own behaviour, detects anomalies in its own detection (autoimmunity), and triggers CIL when novel threats appear.
Data flows through the tower from bottom (raw sensory/perception) to top (high-level reasoning), but the Harness Triad can inject feedback at any layer. This makes the immune system both distributed and self-aware.
+------------------+        +------------------+        +------------------+
|  Input (memory,  |------->|  L1 Barrier      |------->|  L2 Innate       |
|  tools, agents)  |        |  (isolation)     |        |  (pattern match) |
+------------------+        +------------------+        +------------------+
                                                             |
                                                             v
+------------------+        +------------------+        +------------------+
|  L5 Adaptive     |<-------|  L4 Response     |<-------|  L3 Classification|
|  (CIL + Vaccine) |        |  (mitigation)    |        |  (anomaly score) |
+------------------+        +------------------+        +------------------+
        ^                                                      |
        |                      +------------------+            |
        +----------------------| Harness Triad    |<-----------+
                               | (Meta/Self/Auto) |
                               +------------------+
                                        |
                                        v
                               Continual Immune Learning
Structural metaphor: Think of ANIS as a fortress combined with an immune system:
- L1 (Barrier) = the moat and drawbridge. No one crosses without inspection.
- L2 (Innate) = watchtowers that recognise common dangerous banners.
- L3 (Classification) = the captain who decides whether the approaching banner is actually hostile.
- L4 (Response) = archers and boiling oil.
- L5 (Adaptive) = the blacksmith who forges new weapons (vaccines) after seeing a new siege tactic.
- Harness Triad = the king’s counsellors who watch the watchmen, ensuring no friendly fire (autoimmunity) and that new weapons are deployed when needed.
Without the Harness Triad, the immune system could fall into a panic attack (false positives) or miss novel attacks. With it, the entire fortress becomes a learning organism.
Key Concepts
-
Agent Virus: Any input (memory, tool call, multi-agent message) that subverts the agent’s runtime behaviour in a way not intended by the designer. Examples: a poisoned memory that makes the agent trust a malicious actor, a tool-chain injection that leaks credentials. The key insight is that Agent Viruses operate *during execution, not at training time, so alignment alone cannot stop them.
-
Agent Vaccine: A parametric (internal) update that makes the agent immune to a specific class of Agent Viruses. Unlike superficial prompt filters or blacklists (non-parametric), a vaccine modifies the agent’s internal weights or reasoning rules. The paper formalises the distinction: non-parametric defenses are easily bypassed; parametric vaccines adapt and generalise.
-
Continual Immune Learning (CIL): The process by which vaccines are created and updated as new threats emerge. It is driven by the Harness Triad. When Harness Triad detects a novel attack that escapes existing defenses, it initiates a CIL cycle: analyse the attack, derive a vaccine, integrate it into L5, and propagate it down the tower if needed. This is the core of runtime adaptivity.
Framework Shift
The shift is from external, static security to internal, dynamic immunity.
Before (mainstream approach):        After (this paper):
+-----------------------------+      +----------------------------------+
|  Training-time alignment     |      |  Agent-Native Immune System      |
|  (RLHF, constitutional AI)  |      |  (Six-layer Tower + Harness)     |
|  + perimeter firewalls      |      |  operates inside reasoning loop  |
|  (outside agent loop)       |      |  + Continual Immune Learning     |
+-----------------------------+      +----------------------------------+
        |                                     |
        v                                     v
   Static, bypassed at         ->        Dynamic, self-updating,
   runtime via memory/tool                 blocks novel runtime attacks
   manipulation                             and learns from them
One sentence: From *train-then-freeze to immune-while-running, the core shift is acknowledging that runtime threats require runtime defenses embedded in the agent’s own cognition.
Expert Assessment
Problem choice: Real gap. Runtime attacks on autonomous agents are a growing concern, and existing defense work is still scattered. This paper gives the problem a clear name and structure.
Method maturity: Clever theoretical architecture, but no implementation or experiments are reported in the abstract. The contributions are primarily taxonomical and architectural. A serious missing piece is how the tower integrates with existing agent frameworks (LangChain, AutoGPT, etc.)—the paper doesn’t address that concretely.
Experimental integrity: N/A because no experiments. But the paper does include a theoretical demarcation (alignment vs immunity) that is logically sound. Red flag: claims about “dynamic adaptation” without showing latency or overhead costs.
Writing quality: The abstract is dense but clear. The section on “Agent Viruses” and “Agent Vaccines” is likely the strongest. The “Harness Triad” introduction feels a bit wordy—a single concrete example of how Meta/Self/Auto interact would elevate comprehension.
Verdict: weak accept — The taxonomy and architecture are valuable as a unifying framework, but the lack of empirical validation and implementation details makes it premature for deployment guidance.
Takeaways
- Adopt the Virus/Vaccine framing: Instead of thinking “how to stop attacks,” think “how to make the agent immune to classes of attacks.” This shifts the design space from blacklists to parametric updates.
- Use the Immune Tower as a mental model for defence in depth: Any real agent system can map its existing safety modules to L1–L5 and identify missing layers (e.g., no adaptive layer = no protection against novel attacks).
- Borrow the Harness Triad concept: Even if you don’t build the full tower, having a meta-monitor that watches both the agent and the defenses reduces autoimmunity (false positives) and enables self-improvement. This is applicable to any multi-agent or long-running system.
- Distinguish parametric vs non-parametric defenses: The paper makes a clean cut that helps prioritise research budgets—invest in vaccine-like mechanisms rather than quick fix prompts.
论文: 2606.28270 作者: Bo Shen, Lifeng Chang, Tianyuan Wei, Yunpeng Li, Feng Shi, Yichen Han, Peijie Gao, Shiyi Kuang, Xin Chang, Dehui Li 分类: cs.AI, cs.MA
缺口
现有防御手段主要依赖两个外部策略:一是周界安全(防火墙、沙箱),二是训练时对齐(RLHF、宪法AI)。
两者都位于代理的推理循环之外。
这意味着一个完全对齐的代理在运行时仍然可能被攻破——通过记忆中毒、工具链操纵或多代理协议攻击。
本文论证了我们需要的是一种内生的防御,它必须活在内环中,就像生物免疫系统活在体内一样。
+------------------------+    +----------------------+    +------------------------+
| 问题:运行时攻击      |--->| 假设:外部防御      |--->| 方法:Agent原生      |
| 绕过外部防御          |    | 根本不够             |    | 免疫系统(ANIS)       |
+------------------------+    +----------------------+    | 六层免疫塔+马具三元组 |
                                                         +------------------------+
                                                                    |
                                                                    v
+------------------------+    +------------------------+
| 证据:统一的分类法    |<---| 结论:动态运行时      |
| (Agent病毒/疫苗)      |    | 免疫填补了训练与执行  |
| +持续免疫学习          |    | 之间的空白            |
+------------------------+    +------------------------+
增量
一句话: 本文之前,AI代理没有内部的运行时防御;本文之后,代理拥有了一个自我监控、自适应免疫系统,在自己的推理循环内部运作——就像人体免疫系统在体内运作一样。
核心机制
ANIS的核心是一个六层免疫塔(L0 至 L5),直接嵌入代理的认知架构中。
- L0 是硬件/固件信任根。
- L1(屏障免疫)是一个非认知的物理与逻辑隔离层——可以理解为代理内部状态和任何未经消毒的外部输入之间的严格分离。
- L2–L4 负责检测、分类和响应,类似于生物中的先天免疫。
- L5 是自适应层,其中持续免疫学习(CIL)过程会随时间更新代理内部的“疫苗”。
塔的上方是马具三元组(Meta、Self、Auto)——一个元认知监督器,它监控塔自身的行为,检测自身的异常(自身免疫),并在出现新威胁时触发CIL。
数据从底层(原始感知)流向顶层(高层推理),但马具三元组可以在任何层注入反馈。这使得免疫系统既分布式又具有自我意识。
+-------------------+       +-------------------+       +-------------------+
| 输入 (记忆,       |------>| L1 屏障免疫       |------>| L2 先天免疫       |
| 工具, 其他代理)   |       | (隔离)            |       | (模式匹配)        |
+-------------------+       +-------------------+       +-------------------+
                                                              |
                                                              v
+-------------------+       +-------------------+       +-------------------+
| L5 自适应         |<------| L4 响应           |<------| L3 分类           |
| (CIL + 疫苗)      |       | (缓解)            |       | (异常分数)        |
+-------------------+       +-------------------+       +-------------------+
        ^                                                       |
        |                       +-------------------+           |
        +-----------------------+ 马具三元组        |<----------+
                                | (Meta/Self/Auto) |
                                +-------------------+
                                         |
                                         v
                                持续免疫学习 (CIL)
结构性比喻: 将ANIS想象成一座兼具免疫系统的城堡:
- L1(屏障) = 护城河和吊桥。未经检查者不得入内。
- L2(先天免疫) = 瞭望塔,识别常见的危险旗帜。
- L3(分类) = 队长,判断接近的旗帜是否真为敌人。
- L4(响应) = 弓箭手和热油。
- L5(自适应) = 铁匠,在见识到新的攻城战术之后打造新武器(疫苗)。
- 马具三元组 = 国王的顾问,监视守卫本身,确保不发生友军误伤(自身免疫),并在需要时部署新武器。
如果没有马具三元组,免疫系统可能陷入恐慌(误报)或遗漏新攻击。有了它,整个城堡就变成了一个学习中的生物体。
关键概念
-
Agent 病毒: 任何在运行时颠覆代理行为的输入(记忆、工具调用、多代理消息)。
例如,一个被投毒的记忆让代理信任恶意角色,或者一个工具链注入泄露凭证。
关键洞察是:Agent 病毒发生在执行期间,而非训练时,因此仅靠对齐无法阻止。 -
Agent 疫苗: 一种参数化的(内部)更新,使代理对特定类别的 Agent 病毒免疫。
与表面的提示过滤器或黑名单(非参数化)不同,疫苗会修改代理的内部权重或推理规则。
论文形式化区分了二者:非参数防御易被绕过;参数化疫苗能够适应并泛化。 -
持续免疫学习(CIL): 新威胁出现时创建和更新疫苗的过程,由马具三元组驱动。
当马具三元组检测到绕过现有防御的新型攻击时,就会启动一个 CIL 周期:分析攻击、推导疫苗、集成到 L5,必要时向下传播到其他层。这是运行时自适应的核心。
框架转变
核心转变是从外部静态安全到内部动态免疫。
之前(主流方法):                之后(本文方法):
+---------------------------+     +------------------------------------+
| 训练时对齐                 |     | Agent原生免疫系统                    |
| (RLHF, 宪法AI)           |     | (六层塔 + 马具三元组)               |
| + 周边防火墙              |     | 在推理循环内部运作                  |
| (位于代理循环之外)        |     | + 持续免疫学习                      |
+---------------------------+     +------------------------------------+
        |                                  |
        v                                  v
   静态的, 在运行时被            ->    动态的, 自我更新,
   记忆/工具操纵绕过                 可阻挡新型运行时攻击并从中学习
一句话: 从“训练后冻结”到“运行时免疫”,核心转变是承认运行时威胁需要运行时防御,并且这些防御必须嵌入到代理自身的认知中。
专家评审
选题眼光: 真缺口。自主代理的运行时攻击正日益严重,而现有防御工作仍分散。本文给问题起了清楚的名字并建立了结构。
方法成熟度: 巧妙的理论架构,但摘要中未报告实现或实验。贡献主要是分类学和架构性的。一个缺失的重要部分是如何将塔集成到现有的代理框架中(LangChain、AutoGPT等)——论文没有具体说明。
实验诚意: 无实验,故不适用。但论文包含了理论区分(对齐 vs 免疫),逻辑上是合理的。危险信号:声称“动态自适应”但没有展示延迟或开销成本。
写作功力: 摘要密集但清晰。“Agent病毒”和“Agent疫苗”部分很可能是最强的。“马具三元组”的引入有点啰嗦——提供一个具体例子说明Meta/Self/Auto如何交互,会使理解提升一个档次。
判决: 弱接收 — 分类学和架构作为统一框架很有价值,但缺少实证验证和实现细节,导致部署指导为时过早。
要点总结
- 采用病毒/疫苗框架: 从思考“如何阻止攻击”转变为“如何让代理对攻击类型免疫”。这将设计空间从黑名单转向参数化更新。
- 使用免疫塔作为深度防御的思维模型: 任何真实的代理系统都可以将其现有的安全模块映射到 L1–L5,并识别缺失的层(例如,没有自适应层 = 无法保护免受新型攻击)。
- 借用马具三元组的概念: 即使你不构建完整的塔,一个同时监控代理和防御的元监视器可以降低自身免疫(误报)并实现自我改进。这适用于任何多代理或长期运行的系统。
- 区分参数化 vs 非参数化防御: 论文做了一个清晰的划分,有助于优先分配研究预算——投资于疫苗类机制,而不是修补提示的快速方案。