Paper: 2605.21470 Authors: Caleb Winston, Ron Yifeng Wang, Azalia Mirhoseini, Christos Kozyrakis Categories: cs.LG, cs.AI
The Gap
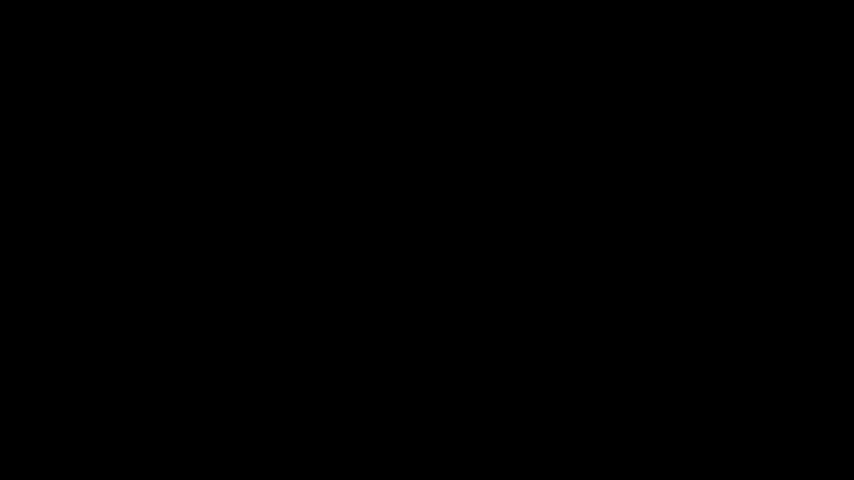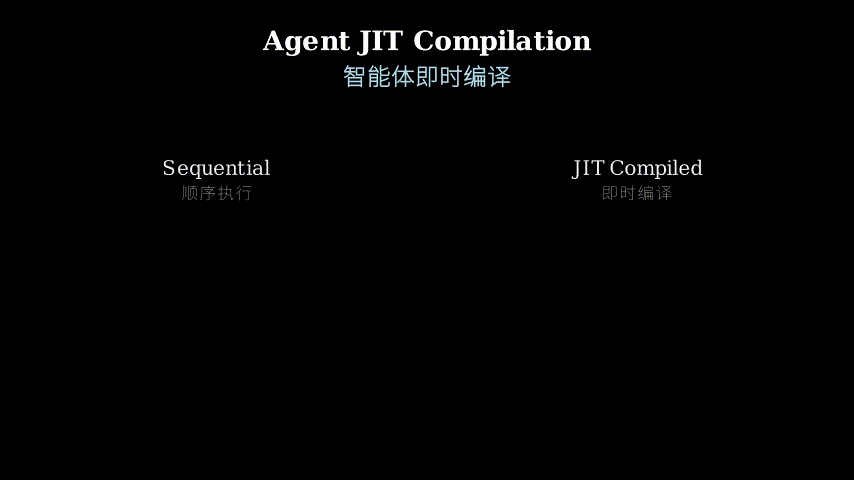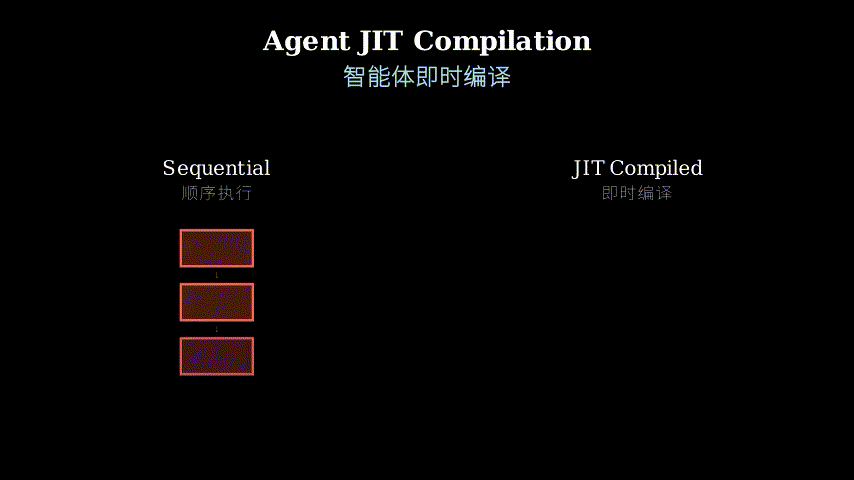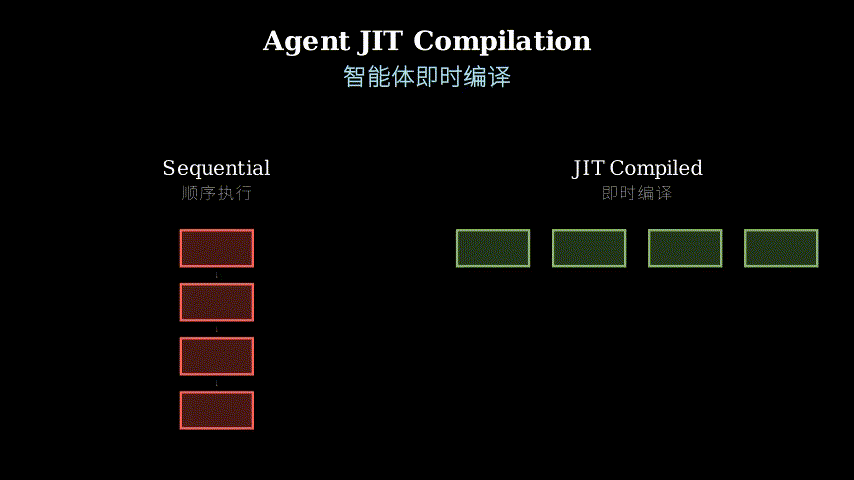
Computer-use agents (CUA) like Browser-Use and OpenAI’s agent follow a fetch-screenshot-execute loop: take screenshot → call LLM → execute one action → repeat. This sequential pattern has two problems: (1) every action requires a full LLM roundtrip, causing high latency, and (2) the LLM generates raw tool calls without validation, leading to frequent errors from incorrect API usage (e.g., clicking before a page loads).
The core limitation is treating the agent as an interpreter that executes one instruction at a time, rather than a compiler that can reason about the entire task structure upfront.
Problem: Sequential execution + no validation
   |
   v
Assumption: Task structure can be analyzed before execution
   |
   v
Method: Compile task → validated code plan → parallel schedule
   |
   v
Evidence: 10.4x speedup (JIT-Planner), 2.4x speedup (JIT-Scheduler)
   |
   v
Conclusion: Compilation beats interpretation for web automation
The Increment
One sentence: Before this paper, web agents executed one action per LLM call in sequence; after, they compile tasks into validated code that parallelizes independent operations.
Core Mechanism
The system has three components working in sequence. JIT-Planner takes a natural language task and generates multiple candidate code plans (Python functions containing LLM calls, tool calls, and control flow). Each plan is validated against tool specifications—preconditions and postconditions that define valid usage patterns (e.g., “click requires element to be visible”). The planner selects the minimum-cost candidate based on estimated LLM and tool latencies.
JIT-Scheduler then analyzes the selected plan to find parallelization opportunities. It identifies independent operations (e.g., filling two unrelated form fields) and uses Monte Carlo simulation over learned latency distributions to estimate the cost of different execution orders. The scheduler outputs an optimized execution graph.
Finally, the tool protocol enforces invariants at runtime. Each tool (click, type, scroll) declares its preconditions and postconditions as executable checks. Before executing a tool call, the runtime verifies preconditions; after execution, it verifies postconditions. This catches errors early and provides structured feedback for plan regeneration.
Task description
   |
   v
JIT-Planner: Generate N plans → Validate → Select min-cost
   |
   v
JIT-Scheduler: Find independent ops → MC simulation → Optimize order
   |
   v
Runtime: Check preconditions → Execute → Check postconditions
Think of this like a restaurant kitchen. The old approach (sequential agents) is a single cook who reads one recipe step, performs it, then reads the next step—no prep work, no parallelization. JIT compilation is a head chef who reads the entire order, breaks it into prep tasks (chop vegetables, boil water, marinate meat), assigns tasks to different stations that can work in parallel, and validates each station’s output before the next step (e.g., “water must be boiling before adding pasta”). The head chef (planner) creates the execution plan, the sous chef (scheduler) optimizes station assignments, and each station (tool protocol) has a checklist to verify their work meets requirements.
Key Concepts
-
Tool Protocol with Invariants: Instead of treating tools as black-box functions, each tool declares what must be true before it runs (preconditions) and what will be true after (postconditions). For example,
click(element)has precondition “element must be visible on screen” and postcondition “element’s click handler has fired.” These are executable checks, not documentation. When a plan violates a precondition, the system catches it before execution and can regenerate the plan with feedback. This is like type checking for agent actions—it prevents a whole class of runtime errors by validating the plan structure upfront. -
Monte Carlo Cost Estimation: The scheduler needs to decide execution order for parallel operations, but tool latencies are stochastic (network delays, page load times vary). Instead of using average latencies, the scheduler samples from learned latency distributions and simulates thousands of execution traces. For each candidate schedule, it computes the distribution of total completion times and selects the schedule with the lowest expected cost. This accounts for variance—a schedule that’s fast on average but occasionally very slow might be worse than a slightly slower but more consistent schedule.
-
Code Plan Validation: Generated code plans are validated against tool specifications before execution. The validator parses the Python AST, extracts all tool calls, and checks that each call’s arguments match the tool’s type signature and that the call appears in a context where its preconditions can be satisfied. For example, if the plan calls
click(element)but never callsscroll_to(element)first, andelementis off-screen, the validator rejects the plan. This is static analysis for agent code—catching bugs at compile time rather than runtime.
Framework Shift
Before (sequential interpretation):        After (JIT compilation):

Task --> LLM --> Action --> Screenshot     Task --> Planner --> Code Plan
         ^                      |                      |
         |                      |                      v
         +----------------------+                  Validator
                                                       |
    (repeat for each action)                          v
                                                  Scheduler
                                                       |
                                                       v
                                                  Parallel Execution
                                                  (with invariant checks)
From interpreting one action at a time to compiling the entire task into validated, parallelizable code, the core shift is moving reasoning from runtime to compile time.
Expert Assessment
Problem choice: Real gap. Sequential execution is a genuine bottleneck in current CUA systems—Browser-Use’s median task takes 60+ seconds. The problem sits at the intersection of LLM agents and systems optimization, which is timely given the recent push toward agentic workflows.
Method maturity: The planner and validator are straightforward applications of existing techniques (multi-candidate generation, AST parsing). The scheduler’s Monte Carlo approach is clever but not novel—similar methods exist in compiler optimization. The real contribution is recognizing that web automation is a compilation problem, not an interpretation problem. However, the paper doesn’t explore simpler baselines like caching plans for similar tasks or using a faster LLM for action selection.
Experimental integrity: Baselines are fair—Browser-Use and OpenAI CUA are state-of-the-art. The 5 web applications cover diverse interaction patterns (forms, search, navigation). However, the paper doesn’t report failure modes in detail. What happens when the planner generates invalid code that passes validation? How often does the scheduler’s cost model mispredict? The accuracy gains (+28%, +9%) are substantial but not broken down by error type (tool misuse vs. task misunderstanding).
Writing quality: The abstract and introduction are crisp. The method section is dense—Figure 2 (system architecture) does heavy lifting but isn’t explained incrementally. The related work section is thin and doesn’t position this against compiler optimization literature, which would strengthen the framing. The evaluation section could use a failure analysis subsection.
Verdict: weak accept — Solid systems contribution with clear practical impact, but the novelty is more in problem framing than algorithmic innovation.
Takeaways
Steal the invariant protocol pattern: If you’re building any agent system with tool use, declare preconditions and postconditions for each tool. Validate plans against these specs before execution. This catches a huge class of errors (wrong argument types, missing dependencies, invalid state transitions) at “compile time” instead of discovering them mid-execution. The implementation is straightforward—just Python decorators and AST parsing.
Compilation beats interpretation for structured tasks: If your agent’s task has analyzable structure (dependencies between actions, parallelizable subtasks), generate a full execution plan upfront rather than deciding each action on-the-fly. You get two wins: (1) validate the entire plan before committing resources, and (2) optimize the execution schedule globally rather than locally. This applies beyond web automation—think data pipelines, infrastructure provisioning, multi-step API workflows.
Monte Carlo scheduling for stochastic operations: When optimizing execution order under uncertainty, don’t use average latencies—sample from distributions and simulate. This is especially valuable when variance is high (network operations, LLM calls, user-facing systems). The overhead of simulation is negligible compared to the cost of a bad schedule.
论文: 2605.21470 作者: Caleb Winston, Ron Yifeng Wang, Azalia Mirhoseini, Christos Kozyrakis 分类: cs.LG, cs.AI
缺口
当前的计算机使用智能体(CUA)如Browser-Use和OpenAI的智能体遵循”截图-调用-执行”循环:截屏 → 调用LLM → 执行一个动作 → 重复。
这种顺序模式有两个问题:(1)每个动作都需要完整的LLM往返,导致高延迟;(2)LLM生成原始工具调用而不验证,导致API使用错误频发(例如在页面加载前点击)。
核心局限在于将智能体视为逐条执行指令的解释器,而非能提前推理整个任务结构的编译器。
问题:顺序执行 + 无验证
   |
   v
假设:任务结构可在执行前分析
   |
   v
方法:编译任务 → 验证代码计划 → 并行调度
   |
   v
证据:10.4倍加速(JIT-Planner),2.4倍加速(JIT-Scheduler)
   |
   v
结论:编译优于解释(针对网页自动化)
增量
一句话:这篇论文之前,网页智能体每次LLM调用执行一个动作;之后,它们将任务编译为经过验证的代码,并行化独立操作。
核心机制
系统有三个依次工作的组件。
JIT-Planner接收自然语言任务,生成多个候选代码计划(包含LLM调用、工具调用和控制流的Python函数)。
每个计划根据工具规范进行验证——前置条件和后置条件定义了有效的使用模式(例如”点击要求元素可见”)。
规划器根据估计的LLM和工具延迟选择成本最低的候选。
JIT-Scheduler随后分析选定的计划以寻找并行化机会。
它识别独立操作(例如填写两个无关的表单字段),并使用蒙特卡洛模拟(基于学习的延迟分布)来估计不同执行顺序的成本。
调度器输出优化的执行图。
最后,工具协议在运行时强制执行不变量。
每个工具(点击、输入、滚动)声明其前置条件和后置条件作为可执行检查。
执行工具调用前,运行时验证前置条件;执行后验证后置条件。
这能及早捕获错误,并为计划重新生成提供结构化反馈。
任务描述
   |
   v
JIT-Planner:生成N个计划 → 验证 → 选择最低成本
   |
   v
JIT-Scheduler:找独立操作 → MC模拟 → 优化顺序
   |
   v
运行时:检查前置条件 → 执行 → 检查后置条件
把这想象成餐厅厨房。
旧方法(顺序智能体)是单个厨师读一步菜谱、执行、再读下一步——没有准备工作,没有并行化。
JIT编译是主厨读完整个订单,将其分解为准备任务(切菜、烧水、腌肉),分配给可并行工作的不同工位,并在下一步前验证每个工位的输出(例如”水必须沸腾才能加面条”)。
主厨(规划器)创建执行计划,副厨(调度器)优化工位分配,每个工位(工具协议)有检查清单验证工作符合要求。
关键概念
- 带不变量的工具协议:不将工具视为黑盒函数,每个工具声明运行前必须为真的条件(前置条件)和运行后将为真的条件(后置条件)。
例如click(element)的前置条件是”元素必须在屏幕上可见”,后置条件是”元素的点击处理器已触发”。
这些是可执行检查,不是文档。
当计划违反前置条件时,系统在执行前捕获它,并可根据反馈重新生成计划。
这就像智能体动作的类型检查——通过提前验证计划结构来防止一整类运行时错误。
- 蒙特卡洛成本估计:调度器需要决定并行操作的执行顺序,但工具延迟是随机的(网络延迟、页面加载时间变化)。
调度器不使用平均延迟,而是从学习的延迟分布中采样,模拟数千条执行轨迹。
对每个候选调度,它计算总完成时间的分布,选择期望成本最低的调度。
这考虑了方差——平均快但偶尔很慢的调度可能不如稍慢但更一致的调度。
- 代码计划验证:生成的代码计划在执行前根据工具规范验证。
验证器解析Python AST,提取所有工具调用,检查每个调用的参数是否匹配工具的类型签名,以及调用是否出现在可满足其前置条件的上下文中。
例如,如果计划调用click(element)但从未先调用scroll_to(element),且element在屏幕外,验证器拒绝该计划。
这是智能体代码的静态分析——在编译时而非运行时捕获错误。
框架转变
之前(顺序解释):                    之后(JIT编译):

任务 --> LLM --> 动作 --> 截图        任务 --> 规划器 --> 代码计划
         ^              |                        |
         |              |                        v
         +--------------+                    验证器
                                                |
    (每个动作重复)                            v
                                            调度器
                                                |
                                                v
                                            并行执行
                                          (带不变量检查)
从逐个动作解释到将整个任务编译为经验证的可并行化代码,核心转变是将推理从运行时移至编译时。
专家评审
选题眼光:真实缺口。
顺序执行是当前CUA系统的真正瓶颈——Browser-Use的中位任务耗时60秒以上。
问题位于LLM智能体和系统优化的交叉点,鉴于最近对智能体工作流的推动,这很及时。
方法成熟度:规划器和验证器是现有技术的直接应用(多候选生成、AST解析)。
调度器的蒙特卡洛方法巧妙但不新颖——编译器优化中存在类似方法。
真正的贡献是认识到网页自动化是编译问题,而非解释问题。
然而,论文没有探索更简单的基线,如为相似任务缓存计划或使用更快的LLM进行动作选择。
实验诚意:基线公平——Browser-Use和OpenAI CUA是最先进的。
5个网页应用涵盖多样的交互模式(表单、搜索、导航)。
但论文没有详细报告失败模式。
当规划器生成通过验证的无效代码时会发生什么?调度器的成本模型多久预测错误一次?准确率提升(+28%,+9%)可观,但未按错误类型(工具误用vs任务误解)细分。
写作功力:摘要和引言简洁。
方法部分密集——图2(系统架构)承担重任但未逐步解释。
相关工作部分单薄,未将此与编译器优化文献对比,这会加强框架。
评估部分可增加失败分析小节。
判决:弱接收 — 扎实的系统贡献,实际影响明确,但新颖性更多在问题框架而非算法创新。
要点总结
偷走不变量协议模式:如果你在构建任何带工具使用的智能体系统,为每个工具声明前置条件和后置条件。
在执行前根据这些规范验证计划。
这在”编译时”捕获一大类错误(错误参数类型、缺失依赖、无效状态转换),而非在执行中途发现它们。
实现很直接——只需Python装饰器和AST解析。
编译优于解释(针对结构化任务):如果你的智能体任务有可分析的结构(动作间依赖、可并行化子任务),提前生成完整执行计划,而非逐个决定每个动作。
你获得两个好处:(1)在投入资源前验证整个计划,(2)全局而非局部优化执行调度。
这适用于网页自动化之外——想想数据管道、基础设施配置、多步API工作流。
蒙特卡洛调度(针对随机操作):在不确定性下优化执行顺序时,不要使用平均延迟——从分布中采样并模拟。
当方差高时(网络操作、LLM调用、面向用户的系统)这尤其有价值。
模拟开销相比糟糕调度的成本可忽略不计。