Paper: 2604.28177 Authors: Bo Zhang, Tzu-Yen Ma, Zichen Tang, Junpeng Ding, Zirui Wang, Yizhuo Zhao, Peilin Gao, Zijie Xi, Zixin Ding, Haiyang Sun Categories: cs.CV, cs.CY
The Gap
Existing deepfake detection benchmarks focus on faces and natural images. They test binary classification (real vs fake) on consumer content. But academic fraud operates differently: researchers splice gel bands, duplicate microscopy regions, enhance contrast in Western blots. These manipulations are subtle, domain-specific, and often partial — not wholesale generation.
Current benchmarks like FaceForensics++ and DFDC miss this entirely. They don’t cover scientific imagery. They don’t test localization (where is the forgery?). They don’t evaluate reasoning (why is this suspicious?). And they don’t model the actual forgery strategies academics use: copy-paste, enhancement, inpainting, full generation.
The gap: no benchmark tests whether detectors can handle the forensic complexity of academic image fraud across diverse scientific domains with realistic manipulation patterns.
Problem: Academic fraud uses domain-specific, partial manipulations
         Current benchmarks test wholesale fakes on consumer images
                                |
                                v
Assumption: Forensic difficulty comes from domain complexity +
            forgery diversity + multi-task evaluation
                                |
                                v
Method: Build AEGIS with 7 academic domains, 4 forgery types,
        25 generators, test detection + reasoning + localization
                                |
                                v
Evidence: GPT-5.1 at 48.80% overall, expert models IoU 30.09%,
          11/25 generators fool detectors >50% of the time
                                |
                                v
Conclusion: Academic forensics lags behind generative advances;
            no single model excels across all forensic dimensions
The Increment
One sentence: Before AEGIS, we had no way to measure whether AI detectors could handle academic image fraud; after AEGIS, we know they mostly can’t.
Core Mechanism
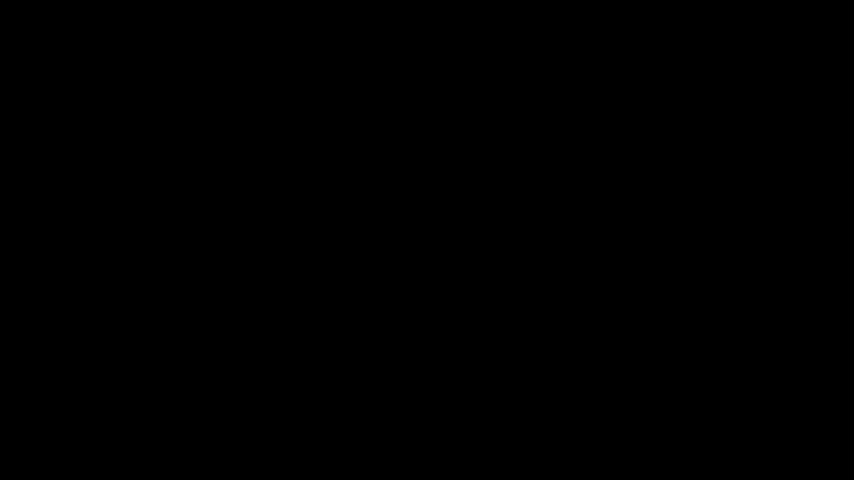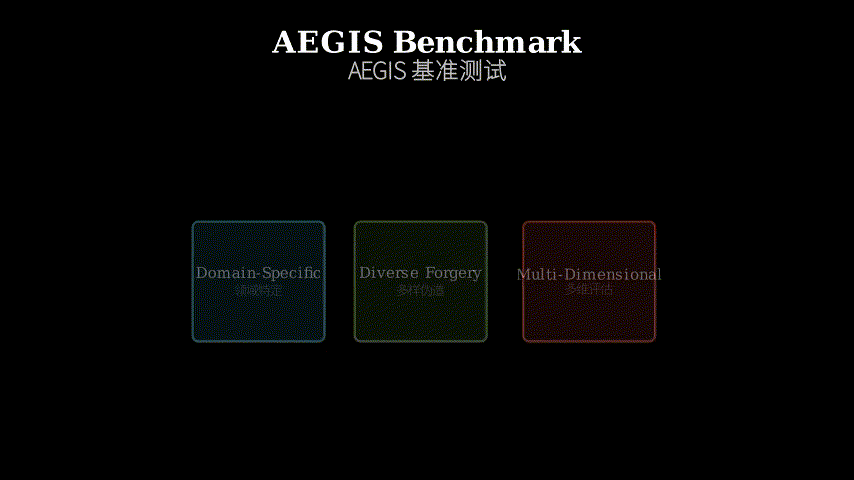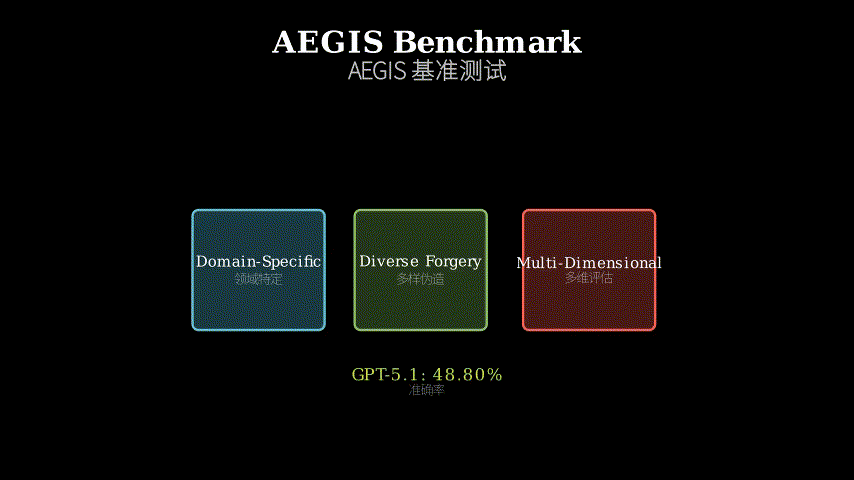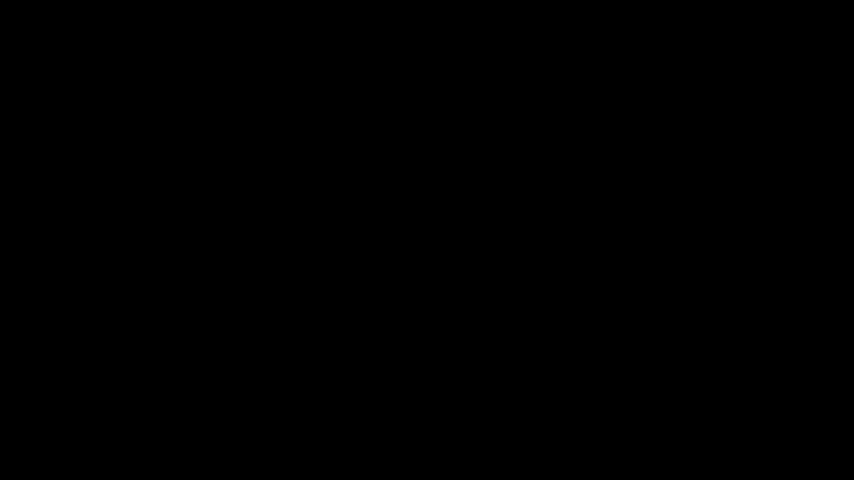
AEGIS constructs a three-layer evaluation architecture. First layer: domain coverage. It samples images from seven academic fields (biology, chemistry, physics, medicine, materials science, earth science, astronomy) with 39 fine-grained subtypes (gel electrophoresis, mass spectra, circuit diagrams, CT scans, etc.). This captures the intrinsic visual complexity of scientific imagery.
Second layer: forgery simulation. For each real image, AEGIS applies four manipulation strategies matching actual academic fraud patterns: copy-paste (duplicating regions), enhancement (adjusting brightness/contrast), inpainting (filling regions with AI), and full generation (creating entire fake images). It uses 25 different generative models spanning diffusion models, GANs, and multimodal generators to create forgeries.
Third layer: multi-dimensional evaluation. Instead of just asking “real or fake?”, AEGIS tests three forensic capabilities: binary detection (is it manipulated?), textual reasoning (describe the suspicious artifacts), and spatial localization (draw a mask around the forgery). Each task probes a different aspect of forensic understanding. The benchmark evaluates 25 MLLMs, 9 expert detectors, and 1 unified model across all three dimensions.
Real Academic Images (7 domains, 39 subtypes)
         |
         v
    +---+---+---+---+
    |   |   |   |   |
    v   v   v   v   v
  Copy Enhance Inpaint Generate  <-- 4 forgery strategies
  Paste                              25 models each
    |   |   |   |   |
    +---+---+---+---+
         |
         v
   Forged Dataset
         |
    +----+----+----+
    |    |    |    |
    v    v    v    v
 Detect Reason Localize  <-- 3 evaluation tasks
  (binary) (text) (mask)
    |    |    |    |
    +----+----+----+
         |
         v
  Performance Metrics
  (accuracy, IoU, etc.)
Think of AEGIS as a medical licensing exam for forensic AI. A real medical exam doesn’t just show you photos of skin rashes and ask “cancer or not?” It tests anatomy knowledge, diagnostic reasoning, and surgical planning across diverse cases. Similarly, AEGIS doesn’t just flash images and ask for verdicts. It tests whether models understand scientific imagery (domain knowledge), can articulate what looks wrong (reasoning), and can pinpoint the problem (localization). The exam is hard because it covers seven “medical specialties” (academic domains), uses realistic “patient presentations” (actual forgery strategies), and requires three types of competence (detection, reasoning, localization). Just as a doctor who only memorized rash photos would fail, a detector trained only on face swaps fails here.
Key Concepts
-
Forensic Localization vs Detection: Detection answers “is this image manipulated?” — a binary yes/no. Localization answers “where exactly is the manipulation?” — drawing a pixel-level mask around the forged region. Detection is easier: you can spot something’s off without knowing where. Localization is harder: you need to understand the image structure well enough to say “this gel band is duplicated from that one” or “this microscopy patch has different noise statistics.” In AEGIS, expert models hit 79.54% detection accuracy but only 30.09% IoU (intersection over union) on localization. That’s like a doctor saying “you’re sick” but unable to point to the affected organ. The gap reveals that models recognize global inconsistencies but lack fine-grained spatial understanding.
-
Domain-Specific Complexity: A face has consistent structure: two eyes, one nose, skin texture. A gel electrophoresis image has variable band patterns, lane boundaries, background gradients. A mass spectrum has peaks at arbitrary positions with varying intensities. Each scientific domain has its own visual grammar. AEGIS’s 39 subtypes capture this diversity. The result: even GPT-5.1 struggles, hitting 48.80% overall. Why? Because models trained on natural images haven’t learned the visual rules of scientific imagery. They don’t know that gel bands should align vertically, or that mass spec peaks should have smooth baselines. Domain-specific complexity means you can’t just fine-tune a face detector and call it done.
-
Forgery Strategy Modeling: Academic fraud isn’t random. Researchers don’t generate entire fake papers. They copy-paste a gel band to fake a replicate. They enhance contrast to make a weak signal look strong. They inpaint a region to remove an inconvenient artifact. AEGIS models these four strategies because they match real-world fraud patterns. The payoff: 11 out of 25 generative models produce forgeries that fool detectors more than 50% of the time. This isn’t a bug — it’s a feature. It shows that as generative models improve, forensic detection falls behind. The benchmark’s value is in exposing this arms race, not in declaring a winner.
Framework Shift
Before (mainstream approach):        After (this paper):

Natural Images                       Academic Images
     |                                    |
     v                                    v
Binary Task                          Multi-Task Evaluation
(real/fake)                          (detect + reason + localize)
     |                                    |
     v                                    v
Single Metric                        Complementary Strengths
(accuracy)                           (MLLMs reason, experts detect)
     |                                    |
     v                                    v
Face/Object Focus                    Domain-Specific Complexity
(consumer content)                   (7 fields, 39 subtypes)
From monolithic evaluation to diagnostic profiling, the core shift is treating forensics as a multi-dimensional capability rather than a single accuracy number.
Expert Assessment
Problem choice: Real and urgent. Academic image fraud is a documented crisis (retraction rates climbing, high-profile cases in Nature/Science). Existing benchmarks genuinely don’t cover this. The gap isn’t manufactured — it’s a blind spot in the forensics community.
Method maturity: Solid engineering, not groundbreaking insight. The three-layer architecture (domains + forgeries + tasks) is straightforward. The value is in execution: curating 39 subtypes, implementing 4 forgery strategies across 25 models, evaluating 35 detectors. This is infrastructure work, not algorithmic innovation. That’s fine — benchmarks should be infrastructure.
Experimental integrity: Baselines are fair. They test leading MLLMs (GPT-5.1, Claude, Gemini) and expert detectors (NPR, PSCC-Net, TruFor). The 30.09% IoU for localization is believable — spatial grounding is hard. One concern: no ablation on forgery difficulty. Are all four strategies equally hard, or does copy-paste dominate the failure cases? The paper doesn’t break this down. Also, the 48.80% GPT-5.1 accuracy is striking, but we don’t see error analysis. What types of images trip it up?
Writing quality: The abstract oversells (“holistic benchmark”) when it’s really “academic image benchmark.” Section 3 (dataset construction) is dense with tables but light on design rationale. Why these 39 subtypes and not others? How were forgery parameters chosen? Section 4 (experiments) dumps numbers without narrative. A rewrite of Section 5 (analysis) that clusters failure modes and proposes forensic strategies would elevate the paper from “here’s a benchmark” to “here’s what we learned.”
Verdict: weak accept — Fills a real gap with solid execution, but lacks analytical depth beyond “detectors struggle.”
Takeaways
Steal the multi-task evaluation framework. If you’re building any kind of AI auditing system (not just forensics), test multiple capabilities (detection, reasoning, localization) rather than collapsing everything into accuracy. AEGIS shows that models have complementary strengths: MLLMs excel at textual reasoning (84.74%), expert detectors at binary classification (79.54%). A production system should ensemble them, not pick one.
Steal the forgery strategy taxonomy. The four types (copy-paste, enhancement, inpainting, generation) transfer to other fraud domains. Financial document fraud? Same strategies. Medical record tampering? Same strategies. Use this as a checklist when red-teaming your own systems.
Steal the domain-specific complexity insight. If your detector works on consumer images but fails on specialized content (medical, satellite, industrial), don’t just add more data. Audit whether your model understands the domain’s visual grammar. AEGIS’s 39 subtypes are a template for how to structure domain coverage.
Don’t steal the benchmark as a training set. AEGIS is for evaluation, not fine-tuning. If you train on it, you’re teaching models to pass the test, not to do forensics.
论文: 2604.28177 作者: Bo Zhang, Tzu-Yen Ma, Zichen Tang, Junpeng Ding, Zirui Wang, Yizhuo Zhao, Peilin Gao, Zijie Xi, Zixin Ding, Haiyang Sun 分类: cs.CV, cs.CY
缺口
现有的深度伪造检测基准聚焦于人脸和自然图像。
它们在消费内容上测试二分类(真实vs伪造)。
但学术造假的运作方式不同:研究者拼接凝胶条带、复制显微镜区域、增强Western blot的对比度。
这些篡改是微妙的、领域特定的、往往是局部的——而非整体生成。
当前的基准如FaceForensics++和DFDC完全错过了这一点。
它们不覆盖科学图像。
它们不测试定位(伪造在哪里?)。
它们不评估推理(为什么这可疑?)。
它们也不模拟学术界实际使用的伪造策略:复制粘贴、增强、修复、完全生成。
缺口:没有基准测试检测器能否处理跨多个科学领域、具有真实篡改模式的学术图像欺诈的法医学复杂性。
问题:学术造假使用领域特定的局部篡改
     当前基准在消费图像上测试整体伪造
                                |
                                v
假设:法医学难度来自领域复杂性 +
     伪造多样性 + 多任务评估
                                |
                                v
方法:构建AEGIS,包含7个学术领域、4种伪造类型、
     25个生成器,测试检测+推理+定位
                                |
                                v
证据:GPT-5.1总体48.80%,专家模型IoU 30.09%,
     25个生成器中11个骗过检测器>50%
                                |
                                v
结论:学术法医学落后于生成技术进展;
     没有单一模型在所有法医学维度上表现出色
增量
一句话:AEGIS之前,我们无法衡量AI检测器能否处理学术图像欺诈;AEGIS之后,我们知道它们大多做不到。
核心机制
AEGIS构建了一个三层评估架构。
第一层:领域覆盖。
它从七个学术领域(生物学、化学、物理学、医学、材料科学、地球科学、天文学)采样图像,包含39个细粒度子类型(凝胶电泳、质谱、电路图、CT扫描等)。
这捕获了科学图像的内在视觉复杂性。
第二层:伪造模拟。
对于每张真实图像,AEGIS应用四种与实际学术欺诈模式匹配的篡改策略:复制粘贴(复制区域)、增强(调整亮度/对比度)、修复(用AI填充区域)、完全生成(创建整个假图像)。
它使用25个不同的生成模型,涵盖扩散模型、GAN和多模态生成器来创建伪造品。
第三层:多维评估。
AEGIS不只是问”真还是假?“,而是测试三种法医学能力:二元检测(是否被篡改?)、文本推理(描述可疑伪影)、空间定位(在伪造周围画一个掩码)。
每个任务探测法医学理解的不同方面。
该基准在所有三个维度上评估25个MLLM、9个专家检测器和1个统一模型。
真实学术图像(7个领域,39个子类型)
         |
         v
    +---+---+---+---+
    |   |   |   |   |
    v   v   v   v   v
  复制 增强 修复 生成  <-- 4种伪造策略
  粘贴                    每种25个模型
    |   |   |   |   |
    +---+---+---+---+
         |
         v
   伪造数据集
         |
    +----+----+----+
    |    |    |    |
    v    v    v    v
 检测 推理 定位  <-- 3个评估任务
 (二元) (文本) (掩码)
    |    |    |    |
    +----+----+----+
         |
         v
  性能指标
  (准确率、IoU等)
把AEGIS想象成法医学AI的医师执照考试。
真正的医学考试不只是给你看皮疹照片然后问”癌症还是不是?“它测试解剖知识、诊断推理和跨多样案例的手术规划。
类似地,AEGIS不只是闪现图像并要求判决。
它测试模型是否理解科学图像(领域知识)、能否阐明哪里看起来不对(推理)、能否精确定位问题(定位)。
考试很难,因为它覆盖七个”医学专科”(学术领域),使用真实的”患者表现”(实际伪造策略),并要求三种能力(检测、推理、定位)。
就像只记住皮疹照片的医生会不及格一样,只在人脸交换上训练的检测器在这里也会失败。
关键概念
- 法医学定位vs检测:检测回答”这张图像被篡改了吗?“——一个二元是/否。
定位回答”篡改到底在哪里?“——在伪造区域周围画一个像素级掩码。
检测更容易:你可以发现有些不对劲而不知道在哪里。
定位更难:你需要足够理解图像结构才能说”这个凝胶条带是从那个复制的”或”这个显微镜补丁有不同的噪声统计”。
在AEGIS中,专家模型达到79.54%的检测准确率,但定位的IoU(交并比)只有30.09%。
这就像医生说”你病了”但无法指出受影响的器官。
这个差距揭示了模型识别全局不一致性,但缺乏细粒度的空间理解。
- 领域特定复杂性:人脸有一致的结构:两只眼睛、一个鼻子、皮肤纹理。
凝胶电泳图像有可变的条带模式、泳道边界、背景梯度。
质谱有任意位置的峰,强度各异。
每个科学领域都有自己的视觉语法。
AEGIS的39个子类型捕获了这种多样性。
结果:即使GPT-5.1也挣扎,总体达到48.80%。
为什么?因为在自然图像上训练的模型没有学习科学图像的视觉规则。
它们不知道凝胶条带应该垂直对齐,或者质谱峰应该有平滑的基线。
领域特定复杂性意味着你不能只是微调一个人脸检测器就完事。
- 伪造策略建模:学术欺诈不是随机的。
研究者不会生成整篇假论文。
他们复制粘贴一个凝胶条带来伪造一个重复。
他们增强对比度使弱信号看起来强。
他们修复一个区域以移除不方便的伪影。
AEGIS建模这四种策略,因为它们匹配真实世界的欺诈模式。
回报:25个生成模型中有11个产生的伪造品在超过50%的时间里骗过检测器。
这不是bug——这是特性。
它表明随着生成模型的改进,法医学检测落后了。
基准的价值在于揭示这场军备竞赛,而不是宣布赢家。
框架转变
之前(主流方法):                之后(本文方法):

自然图像                          学术图像
     |                                |
     v                                v
二元任务                          多任务评估
(真/假)                          (检测+推理+定位)
     |                                |
     v                                v
单一指标                          互补优势
(准确率)                         (MLLM推理,专家检测)
     |                                |
     v                                v
人脸/物体焦点                     领域特定复杂性
(消费内容)                       (7个领域,39个子类型)
从整体评估到诊断画像,核心转变是将法医学视为多维能力而非单一准确率数字。
专家评审
选题眼光:真实且紧迫。
学术图像欺诈是有记录的危机(撤稿率攀升,Nature/Science的高调案例)。
现有基准确实不覆盖这一点。
这个缺口不是人造的——它是法医学界的盲点。
方法成熟度:扎实的工程,不是突破性的洞见。
三层架构(领域+伪造+任务)很直接。
价值在于执行:策划39个子类型,在25个模型上实现4种伪造策略,评估35个检测器。
这是基础设施工作,不是算法创新。
这没问题——基准应该是基础设施。
实验诚意:基线公平。
他们测试了领先的MLLM(GPT-5.1、Claude、Gemini)和专家检测器(NPR、PSCC-Net、TruFor)。
定位的30.09% IoU是可信的——空间定位很难。
一个担忧:没有关于伪造难度的消融。
所有四种策略都同样难吗,还是复制粘贴主导失败案例?论文没有分解这一点。
此外,GPT-5.1的48.80%准确率很引人注目,但我们没有看到错误分析。
什么类型的图像让它出错?
写作功力:摘要过度推销(“整体基准”),而实际上是”学术图像基准”。
第3节(数据集构建)表格密集但设计理由不足。
为什么是这39个子类型而不是其他?伪造参数是如何选择的?第4节(实验)倾倒数字而没有叙述。
重写第5节(分析),聚类失败模式并提出法医学策略,将使论文从”这是一个基准”提升到”这是我们学到的”。
判决:弱接收——用扎实的执行填补了真实的缺口,但缺乏超越”检测器挣扎”的分析深度。
要点总结
偷走多任务评估框架。
如果你正在构建任何类型的AI审计系统(不仅仅是法医学),测试多种能力(检测、推理、定位)而不是将所有内容折叠成准确率。
AEGIS表明模型有互补优势:MLLM在文本推理上表现出色(84.74%),专家检测器在二元分类上表现出色(79.54%)。
生产系统应该集成它们,而不是选一个。
偷走伪造策略分类法。
四种类型(复制粘贴、增强、修复、生成)可迁移到其他欺诈领域。
金融文件欺诈?同样的策略。
医疗记录篡改?同样的策略。
在红队测试你自己的系统时,将此用作检查清单。
偷走领域特定复杂性的洞见。
如果你的检测器在消费图像上有效但在专业内容(医疗、卫星、工业)上失败,不要只是添加更多数据。
审计你的模型是否理解该领域的视觉语法。
AEGIS的39个子类型是如何构建领域覆盖的模板。
不要把基准当作训练集偷走。
AEGIS用于评估,不是微调。
如果你在上面训练,你是在教模型通过测试,而不是做法医学。