Paper: 2605.30349 Authors: Yusuf Dalva, Pinar Yanardag Categories: cs.CV
The Gap
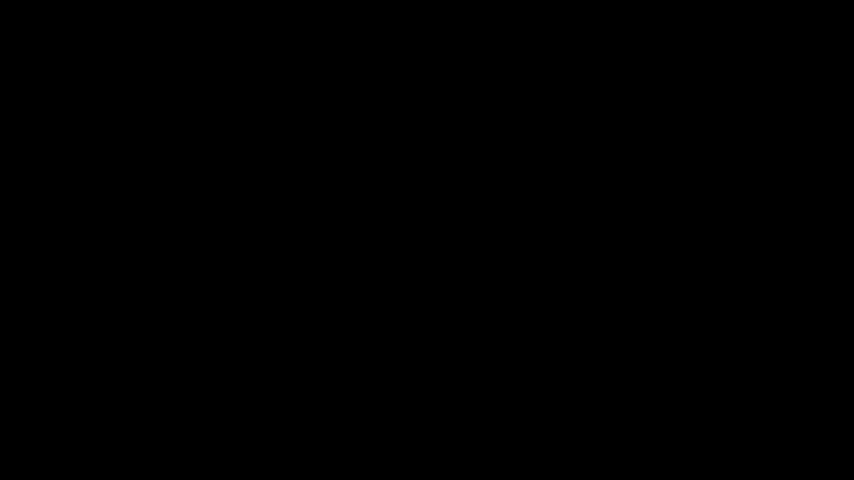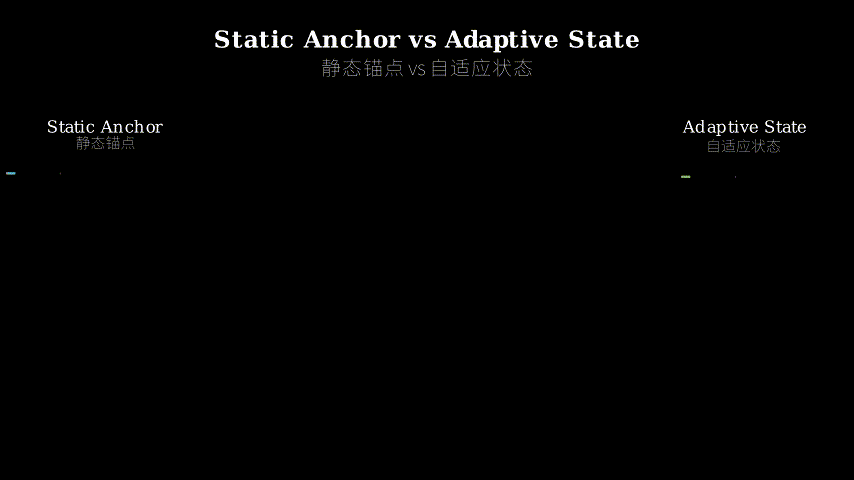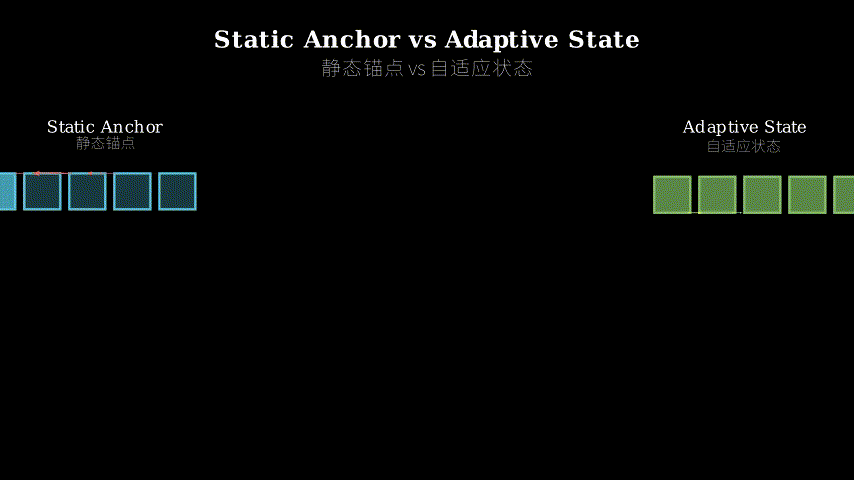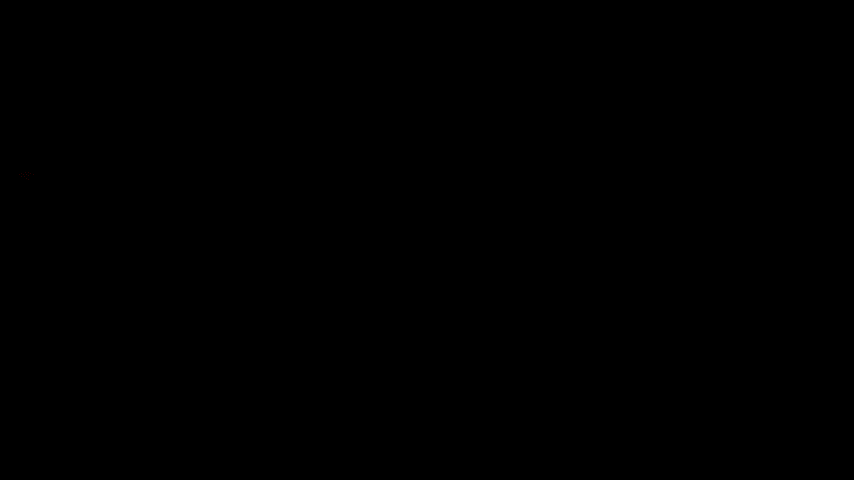
Autoregressive video diffusion models generate video chunk by chunk, conditioning each new segment on previously generated frames stored in an attention cache. The standard approach anchors the entire generation process to the first frame: its key-value representation sits permanently in the cache as the primary scene reference. Because the first frame is the cleanest (never corrupted by generation errors), the attention mechanism gravitates toward it disproportionately. This creates a structural bias: the model keeps referencing a frozen initial viewpoint even as the scene should naturally evolve. The result is temporally shallow videos where motion is dampened, camera movement is restricted, and scene composition remains locked to the starting configuration.
Prior work has focused on improving temporal consistency or extending generation length, but the fundamental architectural bias toward the first frame remains unaddressed. The gap is structural: the attention cache treats the first frame as privileged, creating an asymmetry that conflicts with the goal of generating videos with natural temporal dynamics.
Problem: Static first-frame anchor
   |
   v
Observation: Attention gravitates to cleanest cache position
   |
   v
Hypothesis: Anchor should evolve with content
   |
   v
Method: Replace first frame with adaptive hidden state
   |
   v
Evidence: Improved motion dynamics, natural scene progression
   |
   v
Conclusion: Recurrent state enables temporal depth
The Increment
One sentence: Before this paper, autoregressive video models were structurally anchored to a static first frame; after, the anchor becomes a hidden state that evolves alongside generated content, enabling richer temporal dynamics.
Core Mechanism
AdaState replaces the first frame in the attention cache with an adaptive state—a hidden latent that the model denoises at every generation step but never renders into pixels. At each chunk, the model attends to both the previous adaptive state and the current content being generated. Instead of denoising only the visible frames, the model jointly denoises the adaptive state and the new content frames. The adaptive state transitions forward through the same diffusion process that generates visible content, creating a recurrence where the state at step t becomes the reference for step t+1.
The key architectural change is treating time as relative rather than absolute. In standard autoregressive generation, each chunk has a different positional encoding reflecting its absolute position in the sequence. AdaState uses the same positional structure at every step: the adaptive state always occupies position 0, and the current chunk always occupies positions 1 through N. This positional invariance means the model sees the same structural pattern regardless of how far generation has progressed. The denoising operation itself becomes the state transition function, and the KV cache becomes the carrier of recurrent information—no external RNN or memory module required.
Data flows like this: at step t, the model receives the adaptive state from step t-1 and generates chunk t. During denoising, attention operates over the adaptive state and the current chunk. The model outputs both the denoised chunk (which gets rendered) and the updated adaptive state (which gets stored for step t+1). The adaptive state never becomes pixels—it exists purely as a latent reference that evolves to track scene progression.
Step t-1:                    Step t:
                                |
Adaptive State (t-1) -----> Attention <----- Current Chunk (t)
     |                          |                    |
     |                          v                    |
     |                    Joint Denoising            |
     |                          |                    |
     |                    +-----+-----+              |
     |                    |           |              |
     v                    v           v              v
Stored in Cache --> Adaptive State (t)  Rendered Frames (t)
                         |
                         +---> (feeds into step t+1)

Positional encoding (same at every step):
[State: 0] [Chunk: 1, 2, ..., N]
Think of it like a tour guide leading a group through a museum. A traditional autoregressive model is like a guide who stands at the entrance and shouts directions to the group as they move through rooms—the reference point never moves, so instructions become increasingly disconnected from where the group actually is. AdaState is like a guide who walks with the group: at each room, the guide observes both where they just were and where they are now, updates their mental model of the tour’s progression, and uses that updated understanding to lead into the next room. The guide’s “mental model” is the adaptive state—it’s not a physical location (not rendered) but an evolving representation of the tour’s trajectory. The guide sees each transition as structurally identical (room-to-room) even though the absolute position in the museum keeps changing.
Key Concepts
-
Adaptive State: A hidden latent vector that occupies the anchor position in the attention cache but is never rendered into pixels. Unlike the first frame in standard models (which is generated once and frozen), the adaptive state is denoised at every generation step alongside visible content. It evolves through the same diffusion process that generates frames, allowing it to track scene progression rather than locking to an initial configuration. Think of it as the model’s “working memory” of where the scene has been and where it’s going—it’s not a snapshot but a continuously updated summary.
-
Relative Time Encoding: Standard autoregressive models use absolute positional encodings where chunk 1 is at positions 1-N, chunk 2 at positions N+1-2N, and so on. AdaState uses the same positional structure at every step: the adaptive state is always position 0, the current chunk is always positions 1-N. This makes every generation step look structurally identical to the model, regardless of how many chunks have been generated. It’s like resetting the coordinate system at each step so the model always sees “here and now” rather than “frame 347 of an infinite sequence.” This positional invariance is what enables the recurrence—the state transition is the same operation repeated at every step.
-
Recurrence Through Denoising: Traditional recurrent models (RNNs, LSTMs) have an explicit state transition function separate from their main computation. AdaState achieves recurrence by making the denoising operation itself serve as the transition function. At each step, the model denoises both the adaptive state and the current content, producing an updated state that feeds into the next step. The KV cache acts as the carrier of recurrent information—no separate memory module needed. It’s like using the same tool for two jobs: the diffusion process generates visible frames and simultaneously updates the hidden state that guides future generation.
Framework Shift
Before (static anchor):              After (adaptive state):

First Frame (frozen)                 Adaptive State (t-1)
     |                                      |
     +---> Chunk 1                          +---> Denoising
     +---> Chunk 2                          |         |
     +---> Chunk 3                          v         v
     +---> ...                         State (t)  Chunk (t)
                                            |
Attention always references              (feeds forward)
the same frozen anchor
                                      Attention references
Absolute positions:                   evolving anchor
[0] [1..N] [N+1..2N] ...
                                      Relative positions (repeated):
                                      [0] [1..N] [0] [1..N] ...
One sentence: From a fixed reference point that suppresses dynamics to an evolving reference that moves with the content, the core shift is from spatial anchoring to temporal recurrence.
Expert Assessment
Problem choice: This is a real gap. The first-frame bias in autoregressive video models is a known issue but has been treated as an inevitable tradeoff rather than a solvable architectural problem. The paper correctly identifies that the issue is structural—the attention mechanism’s preference for clean cache positions—rather than a tuning problem. The timing is good: as video generation scales up, temporal depth becomes the bottleneck.
Method maturity: The core insight is elegant: use the diffusion process itself as the state transition function rather than adding external modules. The relative time encoding is clever and well-motivated. However, the paper doesn’t deeply explore failure modes—what happens when the adaptive state drifts or accumulates errors over long sequences? The method feels like a strong v1 that will need refinement for production use. The simplicity is a feature, not a bug, but it also means there’s less room for tuning when things go wrong.
Experimental integrity: The baselines are fair and the improvements are substantial. The paper shows both quantitative metrics (motion scores, scene progression) and qualitative examples. One concern: the experiments focus on relatively short sequences (up to 10 seconds). The recurrent nature of the method raises questions about long-term stability that aren’t fully addressed. The ablations are solid—showing that both the adaptive state and relative time encoding are necessary—but I’d like to see stress tests on longer sequences and more diverse scene types.
Writing quality: The abstract and introduction are strong—they clearly articulate the problem and the solution. The method section is dense and could benefit from more visual aids to show the data flow. The related work section is adequate but doesn’t deeply engage with prior work on temporal consistency or recurrent video models. The conclusion is too brief and doesn’t discuss limitations or failure cases. Rewriting the method section with clearer diagrams and a step-by-step walkthrough would elevate the paper significantly.
Verdict: weak accept — The core idea is sound and the results are promising, but the paper needs more thorough evaluation on long sequences and failure modes before it’s a strong accept. The method is simple enough to implement and test, which is a plus for reproducibility.
Takeaways
The big transferable idea: when your model has a structural bias toward a fixed reference point, consider making that reference point recurrent. This applies beyond video generation—any autoregressive model that anchors to an initial state (text generation with a fixed prompt embedding, audio generation with a static conditioning vector) could benefit from letting that anchor evolve. The specific technique of using the same positional structure at every step to enable recurrence is worth stealing for other sequential generation tasks.
A smaller but concrete takeaway: the KV cache can serve as a recurrent memory without adding external modules. If you’re working with transformer-based generation and need temporal coherence, look at what’s already in the cache before adding new components.
Finally, a framing insight: treating time as relative rather than absolute can simplify recurrent architectures. Instead of tracking absolute position in a potentially infinite sequence, reset the coordinate system at each step. This makes the model’s job easier (same structure every time) and enables weight sharing across steps.
论文: 2605.30349 作者: Yusuf Dalva, Pinar Yanardag 分类: cs.CV
缺口
自回归视频扩散模型逐块生成视频,每个新片段都以存储在注意力缓存中的先前生成帧为条件。
标准做法是将整个生成过程锚定在第一帧上:它的键值表示永久驻留在缓存中,作为主要的场景参考。
因为第一帧最干净(从未被生成误差污染),注意力机制会不成比例地向它倾斜。
这造成了结构性偏差:即使场景本应自然演化,模型仍持续参考一个冻结的初始视角。
结果是时间上浅薄的视频——运动被抑制,镜头移动受限,场景构图锁死在起始配置上。
先前工作聚焦于改善时间一致性或延长生成长度,但对第一帧的根本性架构偏差仍未触及。
缺口是结构性的:注意力缓存将第一帧视为特权位置,造成的不对称性与生成具有自然时间动态的视频这一目标相冲突。
问题:静态首帧锚点
   |
   v
观察:注意力向最干净的缓存位置倾斜
   |
   v
假设:锚点应随内容演化
   |
   v
方法:用自适应隐藏状态替代首帧
   |
   v
证据:运动动态改善,场景自然演进
   |
   v
结论:循环状态使能时间深度
增量
一句话:这篇论文之前,自回归视频模型在结构上锚定于静态首帧;之后,锚点变成随生成内容共同演化的隐藏状态,使能更丰富的时间动态。
核心机制
AdaState 用自适应状态替换注意力缓存中的首帧——这是一个隐藏潜变量,模型在每个生成步骤都对其去噪,但从不渲染成像素。
在每个块,模型同时关注先前的自适应状态和当前正在生成的内容。
模型不只对可见帧去噪,而是联合去噪自适应状态和新内容帧。
自适应状态通过生成可见内容的同一扩散过程向前转移,形成循环:步骤 t 的状态成为步骤 t+1 的参考。
关键的架构变化是将时间视为相对而非绝对。
在标准自回归生成中,每个块有不同的位置编码,反映其在序列中的绝对位置。
AdaState 在每步使用相同的位置结构:自适应状态总是占据位置 0,当前块总是占据位置 1 到 N。
这种位置不变性意味着无论生成进行到多远,模型看到的都是相同的结构模式。
去噪操作本身成为状态转移函数,KV 缓存成为循环信息的载体——不需要外部 RNN 或记忆模块。
数据流动如下:在步骤 t,模型接收步骤 t-1 的自适应状态并生成块 t。
去噪期间,注意力在自适应状态和当前块上操作。
模型输出去噪后的块(被渲染)和更新后的自适应状态(存储用于步骤 t+1)。
自适应状态从不变成像素——它纯粹作为演化的潜在参考存在,追踪场景演进。
步骤 t-1:                    步骤 t:
                                |
自适应状态 (t-1) -----> 注意力 <----- 当前块 (t)
     |                          |                    |
     |                          v                    |
     |                    联合去噪                   |
     |                          |                    |
     |                    +-----+-----+              |
     |                    |           |              |
     v                    v           v              v
存入缓存 ----------> 自适应状态 (t)  渲染帧 (t)
                         |
                         +---> (输入步骤 t+1)

位置编码(每步相同):
[状态: 0] [块: 1, 2, ..., N]
把它想象成导游带团参观博物馆。
传统自回归模型像站在入口处向团队喊指令的导游——随着团队穿过各个展厅,参考点从不移动,所以指令与团队实际位置越来越脱节。
AdaState 像与团队同行的导游:在每个展厅,导游观察他们刚去过哪里和现在在哪里,更新对游览进程的心智模型,用这个更新后的理解引导进入下一个展厅。
导游的”心智模型”就是自适应状态——它不是物理位置(不被渲染),而是游览轨迹的演化表示。
导游将每次转移视为结构上相同的(展厅到展厅),即使在博物馆中的绝对位置不断变化。
关键概念
- 自适应状态:占据注意力缓存锚点位置但从不渲染成像素的隐藏潜向量。
不同于标准模型中的首帧(生成一次后冻结),自适应状态在每个生成步骤都与可见内容一起去噪。
它通过生成帧的同一扩散过程演化,使其能追踪场景演进而非锁定在初始配置上。
把它想象成模型对场景去过哪里、要去哪里的”工作记忆”——它不是快照,而是持续更新的摘要。
- 相对时间编码:标准自回归模型使用绝对位置编码,块 1 在位置 1-N,块 2 在位置 N+1-2N,依此类推。
AdaState 在每步使用相同的位置结构:自适应状态总是位置 0,当前块总是位置 1-N。
这使每个生成步骤对模型来说在结构上看起来相同,无论已生成多少块。
就像在每步重置坐标系,让模型总是看到”此时此地”而非”无限序列的第 347 帧”。
这种位置不变性是使能循环的关键——状态转移是在每步重复的相同操作。
- 通过去噪实现循环:传统循环模型(RNN、LSTM)有与主计算分离的显式状态转移函数。
AdaState 通过让去噪操作本身充当转移函数来实现循环。
在每步,模型对自适应状态和当前内容去噪,产生输入下一步的更新状态。
KV 缓存充当循环信息的载体——不需要单独的记忆模块。
就像用同一工具做两件事:扩散过程生成可见帧,同时更新指导未来生成的隐藏状态。
框架转变
之前(静态锚点):              之后(自适应状态):

首帧(冻结)                     自适应状态 (t-1)
     |                                      |
     +---> 块 1                             +---> 去噪
     +---> 块 2                             |         |
     +---> 块 3                             v         v
     +---> ...                         状态 (t)  块 (t)
                                            |
注意力总是参考                          (向前传递)
同一个冻结锚点
                                      注意力参考
绝对位置:                            演化锚点
[0] [1..N] [N+1..2N] ...
                                      相对位置(重复):
                                      [0] [1..N] [0] [1..N] ...
一句话:从抑制动态的固定参考点到随内容移动的演化参考,核心转变是从空间锚定到时间循环。
专家评审
选题眼光:这是真缺口。
自回归视频模型中的首帧偏差是已知问题,但一直被视为不可避免的权衡而非可解决的架构问题。
论文正确识别出问题是结构性的——注意力机制对干净缓存位置的偏好——而非调参问题。
时机很好:随着视频生成规模扩大,时间深度成为瓶颈。
方法成熟度:核心洞见优雅:用扩散过程本身作为状态转移函数,而非添加外部模块。
相对时间编码巧妙且动机充分。
但论文未深入探索失败模式——当自适应状态在长序列上漂移或累积误差时会发生什么?方法感觉像强力的 v1 版本,生产使用需要改进。
简洁性是特点而非缺陷,但也意味着出问题时调整空间较小。
实验诚意:基线公平,改进显著。
论文展示了定量指标(运动分数、场景演进)和定性示例。
一个担忧:实验聚焦于相对短的序列(最多 10 秒)。
方法的循环性质引发关于长期稳定性的问题,未被充分解决。
消融实验扎实——显示自适应状态和相对时间编码都是必需的——但我想看到更长序列和更多样场景类型的压力测试。
写作功力:摘要和引言强——清晰阐述问题和解决方案。
方法部分密集,需要更多视觉辅助来展示数据流。
相关工作部分足够但未深入讨论时间一致性或循环视频模型的先前工作。
结论过于简短,未讨论局限或失败案例。
用更清晰的图表和逐步演练重写方法部分会显著提升论文。
判决:弱接收——核心想法可靠,结果有希望,但论文需要对长序列和失败模式进行更彻底的评估才能成为强接收。
方法足够简单,易于实现和测试,这对可复现性是加分项。
要点总结
可迁移的大想法:当你的模型对固定参考点有结构性偏差时,考虑让那个参考点循环起来。
这超越视频生成——任何锚定于初始状态的自回归模型(带固定提示嵌入的文本生成、带静态条件向量的音频生成)都能从让锚点演化中受益。
在每步使用相同位置结构来使能循环的具体技术,值得为其他序列生成任务借鉴。
更小但具体的要点:KV 缓存可以充当循环记忆,无需添加外部模块。
如果你在做基于 Transformer 的生成并需要时间连贯性,在添加新组件前先看看缓存中已有什么。
最后,一个框架洞见:将时间视为相对而非绝对可以简化循环架构。
不追踪潜在无限序列中的绝对位置,而是在每步重置坐标系。
这让模型的工作更简单(每次相同结构)并使能跨步骤的权重共享。