Paper: 2603.02200 Authors: Moru Liu, Hao Dong, Olga Fink, Mario Trapp Categories: cs.CV, cs.AI, cs.LG
The Gap
Multimodal models are everywhere now — self-driving cars fusing camera and lidar, medical systems combining scans and patient records. They perform well on average, but here’s the problem: nobody’s seriously tackled how to detect when these systems are about to fail. Existing work focuses on unimodal failure detection (one sensor goes bad) or out-of-distribution detection (weird inputs), but multimodal failure is different. When you combine modalities, new failure modes emerge that don’t exist in isolation.
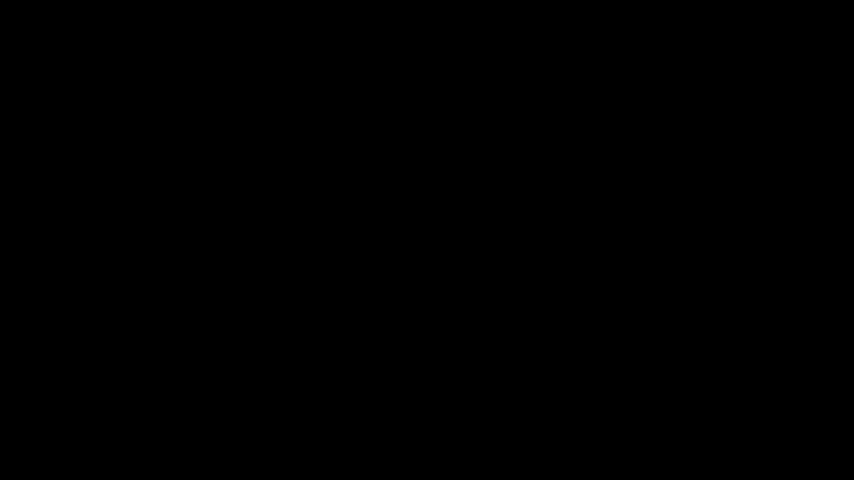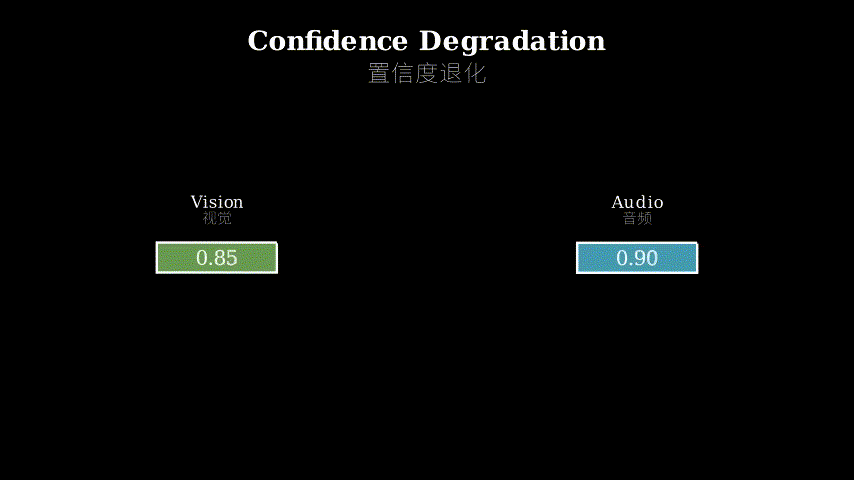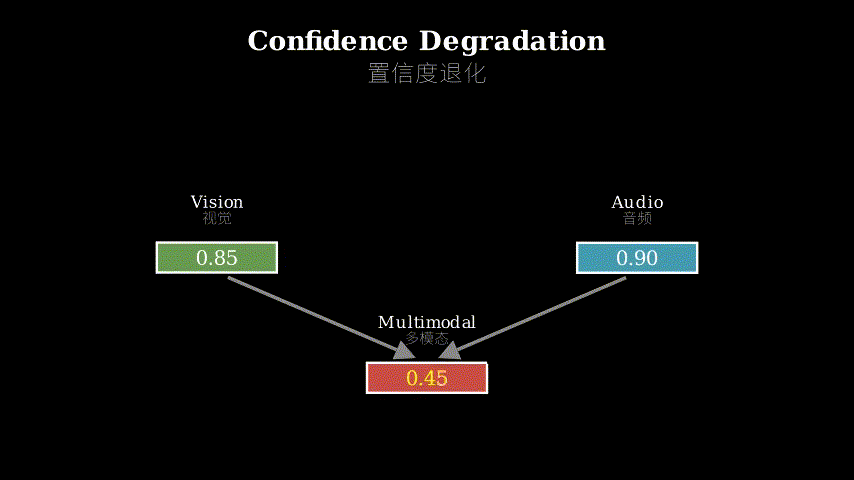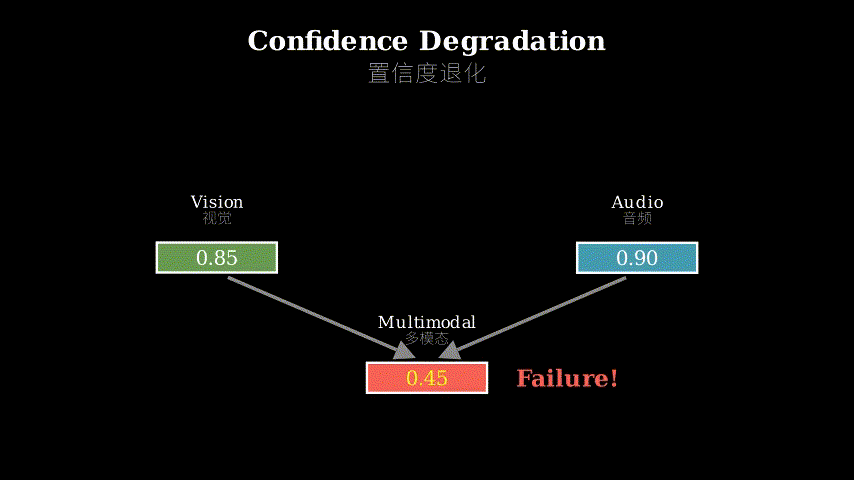
Prior approaches treat multimodal models as black boxes, applying generic uncertainty estimation or OOD detection. They miss a crucial signal: when fusion goes wrong, the combined prediction often becomes less confident than the individual modalities. It’s like three experts disagreeing — the committee becomes uncertain even though each expert is confident. No one’s exploited this pattern systematically.
Problem: Multimodal systems fail silently in high-stakes domains
   |
   v
Observation: Fusion failures show "confidence degradation"
             (combined < max individual confidence)
   |
   v
Method: ACR = Adaptive Confidence Loss + Synthetic Failure Training
   |
   v
Evidence: Consistent gains across 4 datasets, 3 modalities
   |
   v
Conclusion: Confidence degradation is a reliable failure signal
The Increment
One sentence: Before, multimodal failure detection was an afterthought using generic uncertainty methods; now, there’s a training framework that explicitly teaches models to recognize and reject fusion failures.
Core Mechanism
ACR has two components working in tandem. First, the Adaptive Confidence Loss monitors the gap between multimodal confidence and the maximum unimodal confidence during training. When this gap becomes negative (fusion is less confident than the best individual branch), the loss penalizes it. The penalty adapts based on how severe the degradation is — small gaps get light penalties, large gaps get hammered.
Second, Multimodal Feature Swapping generates synthetic failures during training. It takes feature representations from different samples and swaps them between modalities. Imagine taking the visual features from a cat image and pairing them with audio features from a dog bark — the model sees mismatched inputs that look plausible individually but are nonsensical together. This forces the model to learn what fusion failures feel like.
At inference, the model outputs both a prediction and a confidence score. The key insight: if the multimodal confidence drops below the maximum unimodal confidence by more than a learned threshold, flag it as a potential failure. The model has been trained to recognize this pattern through both the regularization loss and exposure to synthetic failures.
Training Flow:

  [Image] ---> Encoder ---> Features_img ----+
                                             |
                                             v
                                        [ Fusion ] ---> Prediction
                                             ^          + Confidence
                                             |
  [Audio] ---> Encoder ---> Features_aud ----+

       |                                     |
       |  Feature Swapping (synthetic fail)  |
       +-------------------------------------+

       Adaptive Confidence Loss:
       If conf_fusion < max(conf_img, conf_aud):
           penalty ~ |degradation|
Think of ACR like training a pilot with a flight simulator. The Adaptive Confidence Loss is like an instructor watching over your shoulder, tapping you on the head whenever your combined instrument reading (fusion) becomes less trustworthy than your best individual gauge. The harder you ignore the warning signs, the harder the tap.
Multimodal Feature Swapping is the simulator throwing impossible scenarios at you — instruments that individually look fine but together tell contradictory stories (altitude says you’re climbing, but airspeed says you’re diving). You can’t encounter every real failure mode in training, so you practice on synthetic ones that share the same structural signature: confident parts, confused whole.
At test time, you’ve internalized the pattern. When your fused reading becomes shakier than your best individual instrument, you’ve learned to distrust it. The threshold for “how much shakier” was learned from all those simulated failures.
Key Concepts
-
Confidence Degradation: Imagine you’re buying a used car. The mechanic says it’s great (90% confident), the body shop says it’s great (85% confident), but when they both look at it together, they’re only 60% confident. That drop — from 90% to 60% — is confidence degradation. It signals that combining information revealed something problematic that wasn’t obvious in isolation. In multimodal models, this happens when fusion creates internal contradictions. The model’s individual branches are confident, but the fusion layer detects inconsistency and becomes uncertain. ACR treats this as a red flag for potential failure.
-
Synthetic Failure Generation: You can’t wait for rare failures to happen naturally during training — there aren’t enough examples. So you manufacture them. Feature swapping creates “Frankenstein samples” by mixing features from different inputs. Take a chest X-ray’s visual features and pair them with a different patient’s medical history features. Individually, each looks normal (in-distribution), but together they’re nonsensical. This teaches the model what internal inconsistency feels like without needing real failure cases. It’s like a vaccine — exposing the model to weakened versions of the disease so it builds immunity.
-
Adaptive Penalty: Not all confidence degradations are equal. Sometimes fusion is slightly less confident than the best branch because of benign noise. Other times, it’s a massive drop signaling catastrophic disagreement. A fixed penalty would either ignore real problems or cry wolf constantly. The adaptive penalty scales with degradation magnitude — gentle nudge for small drops, strong correction for large ones. It’s like a thermostat that adjusts heating based on how cold it is, not just “on/off.”
Framework Shift
Before (mainstream approach):        After (this paper):

Train normally:                      Train with awareness:

[Img] --\                            [Img] --\
         +-> Fusion -> Pred                   +-> Fusion -> Pred
[Aud] --/                            [Aud] --/      |
                                                    v
                                            Confidence Monitor
                                                    |
At test:                                           v
Generic uncertainty                         If degraded: PENALTY
or OOD detection                                   +
(ignores fusion structure)                  Synthetic failures
                                            (swapped features)
From treating multimodal models as opaque boxes to explicitly modeling the fusion process as a potential failure point, the core shift is making confidence degradation a first-class training signal.
Expert Assessment
Problem choice: This is a real gap. Multimodal failure detection matters for deployment, and the existing approaches (generic uncertainty, OOD detection) weren’t designed for fusion-specific failures. The observation about confidence degradation is simple but overlooked. It sits at a sweet spot — practical enough for immediate use, novel enough to be interesting.
Method maturity: The core insight (confidence degradation as failure signal) is clever and well-motivated. The execution is straightforward — adaptive loss and feature swapping are both simple techniques. That’s a strength, not a weakness. However, the paper doesn’t deeply explore why feature swapping works better than other augmentation strategies, or whether the adaptive penalty schedule is optimal. It feels like the first iteration of an idea that could be refined.
Experimental integrity: Four datasets, three modalities (vision-language, vision-audio, vision-depth), multiple baselines. The numbers are convincing and consistent. The baselines include recent uncertainty methods and OOD detectors, which is fair. One concern: the paper doesn’t show failure cases where ACR itself fails. What happens when both unimodal branches are confidently wrong in the same direction? The method assumes at least one branch is reliable, but that’s not always true.
Writing quality: The paper is clear and well-structured. The motivation section is strong. However, the related work section lumps together disparate approaches without clearly positioning ACR’s unique contribution. The ablation studies are thorough but buried in the appendix — moving some to the main text would strengthen the narrative. The discussion of limitations is minimal.
Verdict: weak accept — Solid contribution with a simple, effective idea and convincing experiments, but lacks depth in analysis and doesn’t fully explore failure modes of the method itself.
Takeaways
The big steal here is the confidence degradation signal. If you’re working with any ensemble or fusion system, monitor whether the combined output is less confident than the best individual component. That’s a cheap, model-agnostic failure detector you can add to existing systems without retraining.
The feature swapping technique is also portable. If you need to generate synthetic failures for any multi-input system, swapping representations between samples creates plausible-but-wrong combinations. It’s more targeted than random noise and doesn’t require domain knowledge about what “wrong” looks like.
Finally, the adaptive penalty idea generalizes beyond this paper. Whenever you want to regularize a quantity that varies in magnitude (not just binary), scale your penalty with the violation size. Fixed penalties either underfit or overfit the problem.
论文: 2603.02200 作者: Moru Liu, Hao Dong, Olga Fink, Mario Trapp 分类: cs.CV, cs.AI, cs.LG
缺口
多模态模型现在无处不在——自动驾驶汽车融合摄像头和激光雷达,医疗系统结合扫描图像和病历。
它们平均表现不错,但问题在于:没人认真解决过如何检测这些系统何时会失效。
现有工作聚焦于单模态故障检测(一个传感器坏了)或分布外检测(奇怪的输入),但多模态故障不同。
当你组合多个模态时,会出现孤立状态下不存在的新故障模式。
以往方法把多模态模型当黑盒,套用通用的不确定性估计或OOD检测。
它们错过了一个关键信号:当融合出错时,组合预测的置信度往往低于单个模态。
就像三个专家意见不合——委员会变得不确定,尽管每个专家都很自信。
没人系统性地利用过这个模式。
问题: 多模态系统在高风险领域静默失效
   |
   v
观察: 融合失败表现出"置信度退化"
     (组合置信度 < 单模态最大置信度)
   |
   v
方法: ACR = 自适应置信度损失 + 合成故障训练
   |
   v
证据: 在4个数据集、3种模态上持续提升
   |
   v
结论: 置信度退化是可靠的故障信号
增量
一句话: 之前多模态故障检测是用通用不确定性方法的事后补救; 现在有了专门的训练框架,显式教会模型识别和拒绝融合失败。
核心机制
ACR有两个协同工作的组件。
首先,自适应置信度损失在训练期间监控多模态置信度与单模态最大置信度之间的差距。
当这个差距变为负值(融合的置信度低于最佳单分支),损失就会惩罚它。
惩罚力度根据退化严重程度自适应调整——小差距轻微惩罚,大差距重锤。
其次,多模态特征交换在训练期间生成合成故障。
它从不同样本中提取特征表示,在模态之间交换它们。
想象把猫图像的视觉特征与狗叫声的音频特征配对——模型看到的是单独看起来合理但组合起来毫无意义的不匹配输入。
这迫使模型学习融合失败的感觉。
在推理时,模型输出预测和置信度分数。
关键洞察:如果多模态置信度低于单模态最大置信度超过一个学习到的阈值,就标记为潜在故障。
模型通过正则化损失和暴露于合成故障,已经训练出识别这种模式的能力。
训练流程:

  [图像] ---> 编码器 ---> 特征_图像 ----+
                                       |
                                       v
                                  [ 融合 ] ---> 预测
                                       ^        + 置信度
                                       |
  [音频] ---> 编码器 ---> 特征_音频 ----+

       |                               |
       |  特征交换(合成故障)             |
       +-------------------------------+

       自适应置信度损失:
       如果 置信度_融合 < max(置信度_图像, 置信度_音频):
           惩罚 ~ |退化程度|
把ACR想象成用飞行模拟器训练飞行员。
自适应置信度损失就像教练在你身后监督,每当你的组合仪表读数(融合)变得不如最佳单个仪表可靠时,就拍你的头。
你越忽视警告信号,拍得越重。
多模态特征交换是模拟器向你抛出不可能的场景——单独看起来都正常的仪表,但组合起来讲述矛盾的故事(高度表说你在爬升,但空速表说你在下降)。
你无法在训练中遇到每一种真实故障模式,所以你在具有相同结构特征的合成故障上练习:部分自信,整体困惑。
在测试时,你已经内化了这个模式。
当你的融合读数比最佳单个仪表更不稳定时,你学会了不信任它。
“多不稳定”的阈值是从所有那些模拟故障中学到的。
关键概念
- 置信度退化: 想象你在买二手车。
机械师说车很好(90%自信),车身修理工说车很好(85%自信),但当他们一起看时,只有60%自信。
这个下降——从90%到60%——就是置信度退化。
它表明组合信息揭示了孤立状态下不明显的问题。
在多模态模型中,当融合产生内部矛盾时就会发生这种情况。
模型的各个分支很自信,但融合层检测到不一致性而变得不确定。
ACR把这当作潜在故障的红旗。
- 合成故障生成: 你不能等待罕见故障在训练期间自然发生——样本不够。
所以你制造它们。
特征交换通过混合不同输入的特征创建”弗兰肯斯坦样本”。
拿一张胸部X光的视觉特征,与另一个患者的病史特征配对。
单独看,每个都正常(分布内),但组合起来毫无意义。
这教会模型内部不一致的感觉,而不需要真实的故障案例。
就像疫苗——让模型接触弱化版本的疾病,以便建立免疫力。
- 自适应惩罚: 并非所有置信度退化都相同。
有时融合的置信度略低于最佳分支,是因为良性噪声。
其他时候,是大幅下降,表明灾难性分歧。
固定惩罚要么忽略真实问题,要么不断误报。
自适应惩罚根据退化幅度缩放——小幅下降轻推,大幅下降强力纠正。
就像根据有多冷调节供暖的恒温器,而不只是”开/关”。
框架转变
之前(主流方法):                  之后(本文方法):

正常训练:                        带意识训练:

[图像] --\                          [图像] --\
          +-> 融合 -> 预测                    +-> 融合 -> 预测
[音频] --/                          [音频] --/      |
                                                   v
                                           置信度监控器
                                                   |
测试时:                                            v
通用不确定性                                如果退化: 惩罚
或OOD检测                                          +
(忽略融合结构)                              合成故障
                                           (交换特征)
从把多模态模型当不透明盒子,到显式建模融合过程为潜在故障点,核心转变是让置信度退化成为一等训练信号。
专家评审
选题眼光: 这是真缺口。
多模态故障检测对部署很重要,而现有方法(通用不确定性、OOD检测)不是为融合特定故障设计的。
关于置信度退化的观察简单但被忽视了。
它处于甜蜜点——足够实用可立即使用,足够新颖值得关注。
方法成熟度: 核心洞察(置信度退化作为故障信号)巧妙且动机充分。
执行很直接——自适应损失和特征交换都是简单技术。
这是优势,不是劣势。
然而,论文没有深入探讨为什么特征交换比其他增强策略效果更好,或自适应惩罚计划是否最优。
感觉像是可以改进的想法的第一次迭代。
实验诚意: 四个数据集,三种模态(视觉-语言、视觉-音频、视觉-深度),多个基线。
数字令人信服且一致。
基线包括最近的不确定性方法和OOD检测器,这很公平。
一个担忧:论文没有展示ACR本身失败的案例。
当两个单模态分支都朝同一方向自信地错误时会发生什么?该方法假设至少有一个分支可靠,但这并非总是如此。
写作功力: 论文清晰且结构良好。
动机部分很强。
然而,相关工作部分把不同方法混在一起,没有清楚定位ACR的独特贡献。
消融研究很彻底但埋在附录里——把一些移到正文会加强叙述。
对局限性的讨论很少。
判决: 弱接收——用简单有效的想法和令人信服的实验做出扎实贡献,但分析缺乏深度,没有充分探索方法本身的失败模式。
要点总结
这里最大的收获是置信度退化信号。
如果你在做任何集成或融合系统,监控组合输出是否比最佳单个组件的置信度低。
这是一个廉价的、模型无关的故障检测器,你可以添加到现有系统而无需重新训练。
特征交换技术也可移植。
如果你需要为任何多输入系统生成合成故障,在样本之间交换表示可以创建看似合理但错误的组合。
它比随机噪声更有针对性,不需要关于”错误”长什么样的领域知识。
最后,自适应惩罚的想法超越了本文。
每当你想正则化一个幅度变化的量(不只是二元),用违规大小缩放你的惩罚。
固定惩罚要么欠拟合要么过拟合问题。