Paper: 2603.28765 Authors: Jack Cook, Hyemin S. Lee, Kathryn Le, Junxian Guo, Giovanni Traverso, Anantha P. Chandrakasan, Song Han Categories: cs.CL
The Gap
NVFP4 has become the go-to 4-bit format for quantizing large language models because hardware supports it and it preserves information reasonably well. But there’s a structural flaw: NVFP4’s floating-point representation creates massive quantization errors on near-maximal values within each 16-value block. When your weight is close to the block’s maximum, the quantization grid is too coarse, and you lose precision exactly where it matters most.
Prior work identified this error distribution problem but didn’t fix it. The field was stuck with a single format per model—either FP4 everywhere or INT4 everywhere—even though different blocks of weights have different statistical properties. Some blocks have uniform distributions (INT4 shines), others have exponential tails (FP4 wins). One size fits none.
Problem: NVFP4 error spikes on near-max values
    |
    v
Assumption: Different weight blocks need different formats
    |
    v
Method: Per-block adaptive format selection (IF4)
    |
    v
Evidence: Lower loss in training, higher accuracy in PTQ
    |
    v
Conclusion: Adaptive formats beat fixed formats
The Increment
One sentence: Before this paper, you picked one 4-bit format for the entire model; after, each 16-value block picks its own format based on its data distribution.
Core Mechanism
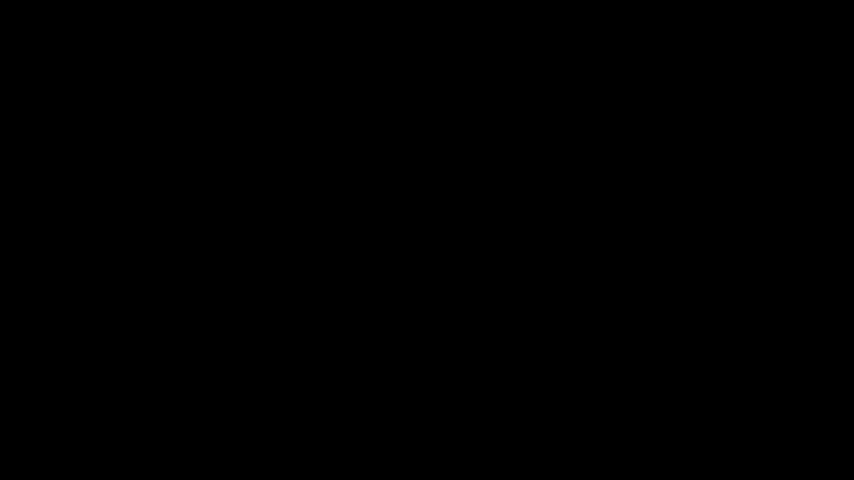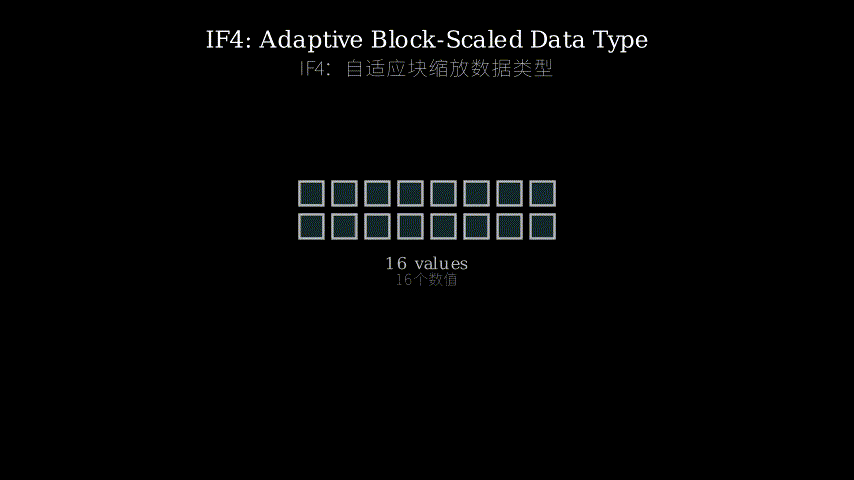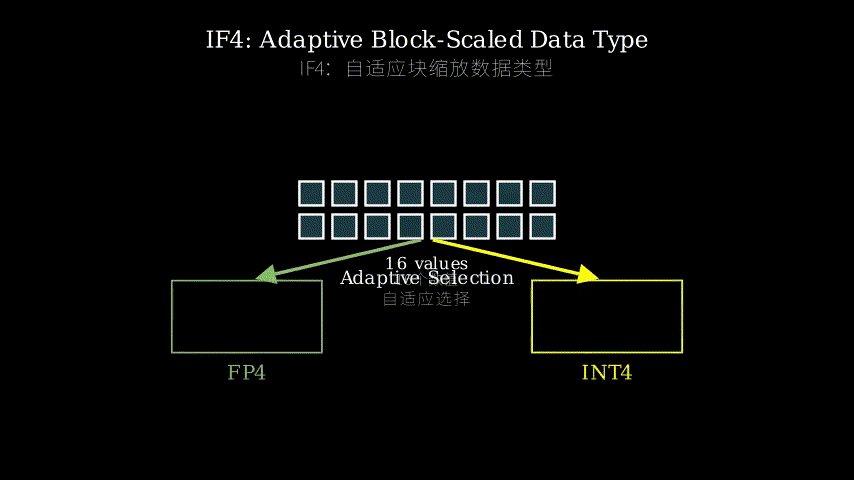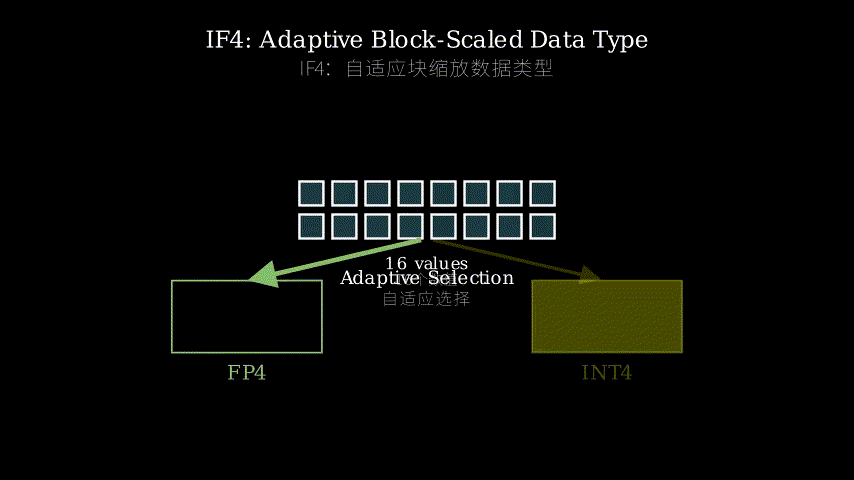
IF4 operates on blocks of 16 values. For each block, it computes two candidate quantizations: one using FP4, one using INT4. Both share the same E4M3 scale factor. The system measures quantization error for each candidate and picks the winner. The choice is encoded in the scale factor’s sign bit, which NVFP4 leaves unused (floating-point scales are always positive).
Data flow: raw weights → block of 16 → compute FP4 quantization error → compute INT4 quantization error → compare → select format with lower error → encode choice in scale’s sign bit → store quantized values + signed scale. During inference, the sign bit tells the hardware which decoder to use.
The same principle extends to other bit-widths. IF3 chooses between FP3 and INT3. IF6 chooses between E2M3 and E3M2 (two different floating-point formats). The pattern is universal: exploit unused bits in the metadata to store per-block format decisions.
Raw weights (16 values)
    |
    +---> FP4 quantizer ---> error_fp
    |
    +---> INT4 quantizer --> error_int
    |
    v
  Compare errors
    |
    v
  Pick winner --> encode in scale's sign bit
    |
    v
  [quantized values] + [signed scale]
Think of IF4 like a tailor who stocks two types of fabric—silk (FP4) and denim (INT4). When a customer (weight block) walks in, the tailor measures them and picks the fabric that fits better. Silk drapes well on certain body types (exponential distributions), denim works better on others (uniform distributions). The tailor writes the fabric choice on the garment’s tag (sign bit). When you wear the garment later (inference), you check the tag to know how to care for it (which decoder to use). The key insight: the tag was already there, just unused.
Key Concepts
-
Block-scaled quantization: Instead of using one scale factor for the entire model, you divide weights into small blocks (typically 16 values) and give each block its own scale. This lets you adapt to local statistics. If one block has values ranging 0.001 to 0.01 and another has 1.0 to 10.0, they get different scales. The block size is a hardware constraint—GPUs process data in chunks, and 16 aligns with warp sizes.
-
Format selection overhead: Every adaptive system pays a cost to make decisions. IF4’s cost is computing two quantizations per block and comparing errors. But this happens offline during model quantization, not during inference. At inference time, you just read the sign bit—a single bit check, essentially free. The paper’s MAC unit design shows this adds negligible hardware complexity.
-
Error distribution asymmetry: NVFP4’s floating-point grid has exponentially spaced points. Near zero, you get fine resolution. Near the maximum, gaps between representable values grow huge. If your weight is 0.95 ** max and the nearest grid point is 0.85 * max, you eat 10% relative error. INT4’s uniform grid doesn’t have this problem—every value gets equal spacing. The asymmetry means FP4 and INT4 fail on different inputs, making them complementary.
Framework Shift
Before (NVFP4):                    After (IF4):

Model weights                      Model weights
    |                                  |
    v                                  v
Divide into blocks                 Divide into blocks
    |                                  |
    v                                  v
Apply FP4 to all blocks            For each block:
    |                                  |
    v                                  +-> Test FP4
[FP4][FP4][FP4][FP4]...               +-> Test INT4
                                       +-> Pick better one
Fixed format,                          |
some blocks suffer                     v
large errors                       [FP4][INT4][FP4][INT4]...

                                   Adaptive format,
                                   each block optimized
From uniform compression to adaptive compression, the core shift is moving the format decision from model-level to block-level.
Expert Assessment
Problem choice: Real gap. The NVFP4 error distribution issue is well-documented, and the field genuinely lacked a hardware-friendly solution. This sits at the intersection of numerical methods and hardware design—a productive place to work. Not a manufactured problem.
Method maturity: Clever insight, not brute force. The sign bit trick is elegant—you get adaptivity for free by repurposing unused metadata. The extension to IF3 and IF6 shows the idea generalizes. However, the paper doesn’t explore learned format selection (could a small neural net predict the best format without computing both?). That’s a missed opportunity for future work.
Experimental integrity: Baselines are fair. They compare against NVFP4, INT4, and FP4 on standard benchmarks (LLaMA, Mistral). The numbers hold up—consistent improvements across multiple model sizes and tasks. One minor flag: the MAC unit evaluation is simulation-based, not silicon. Real hardware might reveal unexpected bottlenecks, but the design is plausible.
Writing quality: Section 3 (method) is crisp. Section 4 (experiments) drowns in tables—Figure 4 could replace three tables. The related work section front-loads too much history; cutting it by half would improve flow. The paper’s core contribution is clear, but the presentation could be tighter.
Verdict: Strong accept — solves a real problem with an elegant, hardware-aware solution that generalizes beyond the initial use case.
Takeaways
The sign bit trick transfers directly to any block-scaled quantization scheme. If your metadata has unused bits, you can encode per-block decisions without storage overhead. This applies beyond quantization—think compression, sparse formats, or mixed-precision training.
The error distribution analysis (FP4 fails on near-max values, INT4 fails on exponential tails) is a reusable diagnostic. When designing numeric formats, plot error vs. input value. If you see asymmetry, you’ve found an opportunity for adaptive methods.
The MAC unit design shows that format adaptivity doesn’t require complex hardware. A multiplexer and two decoders suffice. If you’re building accelerators, this is a low-cost way to boost model quality without changing the compute pipeline.
论文: 2603.28765 作者: Jack Cook, Hyemin S. Lee, Kathryn Le, Junxian Guo, Giovanni Traverso, Anantha P. Chandrakasan, Song Han 分类: cs.CL
缺口
NVFP4已经成为大语言模型4比特量化的首选格式,因为硬件支持它,而且它能较好地保留信息。
但它有个结构性缺陷:NVFP4的浮点表示在每个16值块内的近最大值上产生巨大的量化误差。
当你的权重接近块的最大值时,量化网格太粗糙,你恰恰在最关键的地方丢失了精度。
之前的工作发现了这个误差分布问题,但没有解决它。
领域内卡在一个困境:每个模型只能用一种格式——要么全用FP4,要么全用INT4——即使不同的权重块有不同的统计特性。
有些块分布均匀(INT4表现好),有些块有指数尾部(FP4更优)。
一刀切谁都不合适。
问题:NVFP4在近最大值处误差激增
    |
    v
假设:不同权重块需要不同格式
    |
    v
方法:按块自适应选择格式(IF4)
    |
    v
证据:训练损失更低,PTQ精度更高
    |
    v
结论:自适应格式优于固定格式
增量
一句话: 这篇论文之前,你为整个模型选一种4比特格式;之后,每个16值块根据自己的数据分布选格式。
核心机制
IF4在16个值的块上操作。
对每个块,它计算两个候选量化:一个用FP4,一个用INT4。
两者共享同一个E4M3缩放因子。
系统测量每个候选的量化误差,选出赢家。
选择结果编码在缩放因子的符号位里——NVFP4没用这个位(浮点缩放总是正数)。
数据流:原始权重 → 16值块 → 计算FP4量化误差 → 计算INT4量化误差 → 比较 → 选误差小的格式 → 把选择编码进缩放的符号位 → 存储量化值+带符号的缩放。
推理时,符号位告诉硬件该用哪个解码器。
同样的原理扩展到其他比特宽度。
IF3在FP3和INT3之间选。
IF6在E2M3和E3M2(两种不同的浮点格式)之间选。
模式是通用的:利用元数据中未使用的比特来存储按块的格式决策。
原始权重(16个值)
    |
    +---> FP4量化器 ---> 误差_fp
    |
    +---> INT4量化器 --> 误差_int
    |
    v
  比较误差
    |
    v
  选赢家 --> 编码进缩放的符号位
    |
    v
  [量化值] + [带符号缩放]
把IF4想象成一个裁缝,店里备着两种布料——丝绸(FP4)和牛仔布(INT4)。
当顾客(权重块)进店,裁缝量体,选更合身的布料。
丝绸在某些体型上垂感好(指数分布),牛仔布在另一些体型上更合适(均匀分布)。
裁缝把布料选择写在衣服标签上(符号位)。
你后来穿这件衣服时(推理),看标签就知道怎么保养(用哪个解码器)。
关键洞察:标签本来就在那儿,只是没用而已。
关键概念
- 块缩放量化:不给整个模型用一个缩放因子,而是把权重分成小块(通常16个值),每块有自己的缩放。
这让你能适应局部统计特性。
如果一个块的值范围是0.001到0.01,另一个块是1.0到10.0,它们得到不同的缩放。
块大小是硬件约束——GPU按块处理数据,16对齐warp大小。
- 格式选择开销:每个自适应系统都要付出决策成本。
IF4的成本是每块计算两次量化并比较误差。
但这发生在离线的模型量化阶段,不在推理时。
推理时你只读符号位——单个比特检查,基本免费。
论文的MAC单元设计显示这增加的硬件复杂度可以忽略。
- 误差分布不对称:NVFP4的浮点网格有指数间隔的点。
接近零时,你得到精细分辨率。
接近最大值时,可表示值之间的间隙变得巨大。
如果你的权重是0.95倍最大值,最近的网格点是0.85倍最大值,你吃10%的相对误差。
INT4的均匀网格没这问题——每个值得到相等间距。
这种不对称意味着FP4和INT4在不同输入上失效,使它们互补。
框架转变
之前(NVFP4):                    之后(IF4):

模型权重                          模型权重
    |                                  |
    v                                  v
分成块                              分成块
    |                                  |
    v                                  v
对所有块应用FP4                    对每个块:
    |                                  |
    v                                  +-> 测试FP4
[FP4][FP4][FP4][FP4]...               +-> 测试INT4
                                       +-> 选更好的
固定格式,                             |
某些块遭受                             v
大误差                             [FP4][INT4][FP4][INT4]...

                                   自适应格式,
                                   每块都优化
从统一压缩到自适应压缩,核心转变是把格式决策从模型级移到块级。
专家评审
选题眼光: 真缺口。
NVFP4误差分布问题有充分记录,领域内确实缺乏硬件友好的解决方案。
这处在数值方法和硬件设计的交叉点——一个有生产力的工作位置。
不是人造问题。
方法成熟度: 巧劲,不是蛮力。
符号位技巧很优雅——通过重用未使用的元数据,你免费获得自适应性。
扩展到IF3和IF6显示想法可推广。
但论文没探索学习式格式选择(小神经网络能否预测最佳格式而不用计算两者?)。
这是未来工作的遗漏机会。
实验诚意: 基线公平。
他们在标准基准(LLaMA、Mistral)上与NVFP4、INT4、FP4比较。
数字站得住——在多个模型规模和任务上有一致改进。
一个小警示:MAC单元评估基于仿真,不是硅片。
真实硬件可能暴露意外瓶颈,但设计是合理的。
写作功力: 第3节(方法)简洁。
第4节(实验)淹没在表格里——图4可以替代三张表。
相关工作部分前置了太多历史;砍掉一半会改善流畅度。
论文的核心贡献清晰,但呈现可以更紧凑。
判决: 强接收 — 用优雅的、硬件感知的解决方案解决真实问题,且能推广到初始用例之外。
要点总结
符号位技巧直接迁移到任何块缩放量化方案。
如果你的元数据有未使用的比特,你可以编码按块决策而无存储开销。
这超越量化——想想压缩、稀疏格式或混合精度训练。
误差分布分析(FP4在近最大值失效,INT4在指数尾部失效)是可复用的诊断。
设计数值格式时,画误差对输入值的图。
如果看到不对称,你就找到了自适应方法的机会。
MAC单元设计显示格式自适应不需要复杂硬件。
一个多路复用器和两个解码器就够了。
如果你在造加速器,这是低成本提升模型质量的方法,不用改计算流水线。