Paper: 2604.28173 Authors: Genki Kinoshita, Shu Nakamura, Ryo Kawahara, Shohei Nobuhara, Yasutomo Kawanishi, Ko Nishino Categories: cs.CV
The Gap
Existing human action recognition treats movements as monolithic sequences. Methods like temporal CNNs and Transformers process entire pose sequences end-to-end, learning representations tied to specific action labels. This ignores a fundamental property of human movement: compositionality. A “wave” and a “throw” both contain an “arm raise” segment. Current approaches learn these redundant patterns separately for each action class, missing the reusable building blocks.
The problem: no method explicitly discovers and represents these atomic, reusable movement segments in a hierarchy. Prior work either operates at frame-level (too granular) or action-level (too coarse), with no intermediate structure capturing meaningful temporal spans that recur across different actions.
Problem: Monolithic action modeling
   |
   v
Assumption: Human movement is compositional
   |                (reusable segments exist)
   v
Method: Hierarchical latent tokens
   |      (Action Atoms -> Action Motifs)
   v
Evidence: Motifs emerge without labels,
   |       transfer across tasks
   v
Conclusion: Compositionality improves
            behavior modeling
The Increment
One sentence: Before this paper, action representations were flat sequences of frames; after, we have a two-level hierarchy where atomic movements (Action Atoms) compose into reusable patterns (Action Motifs) discovered without supervision.
Core Mechanism
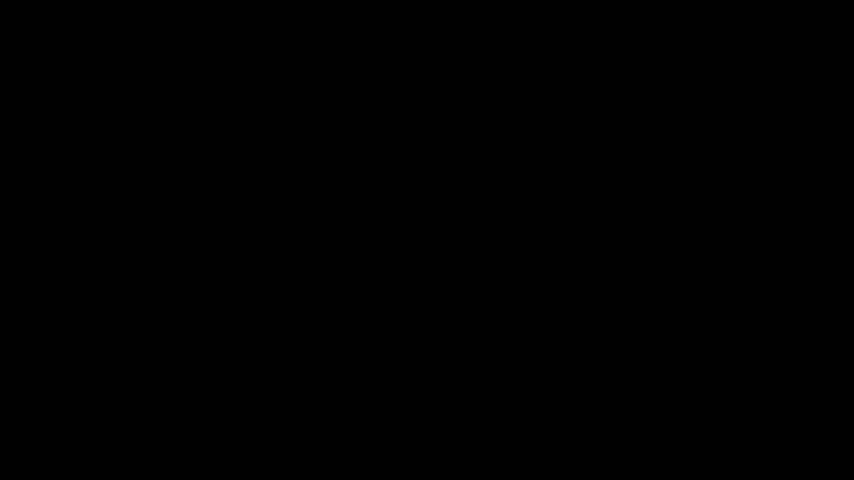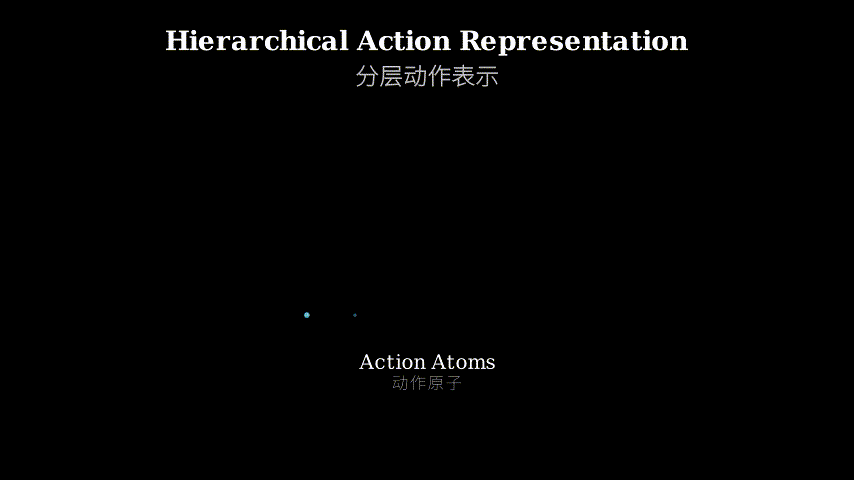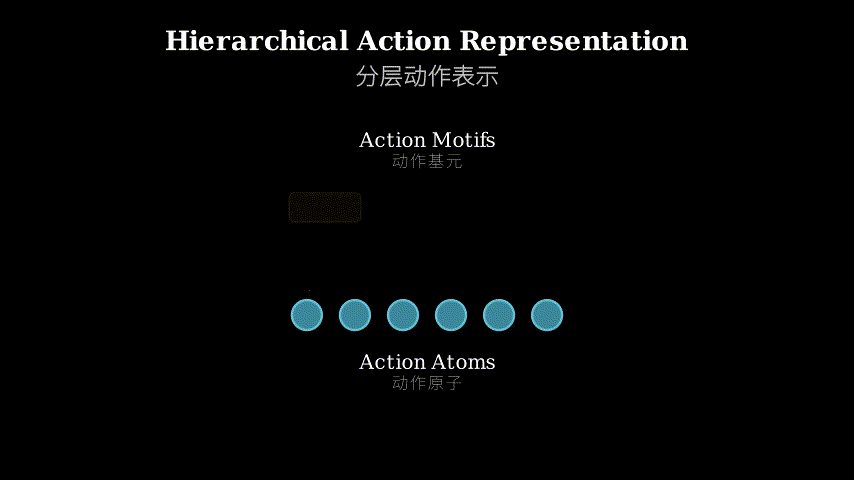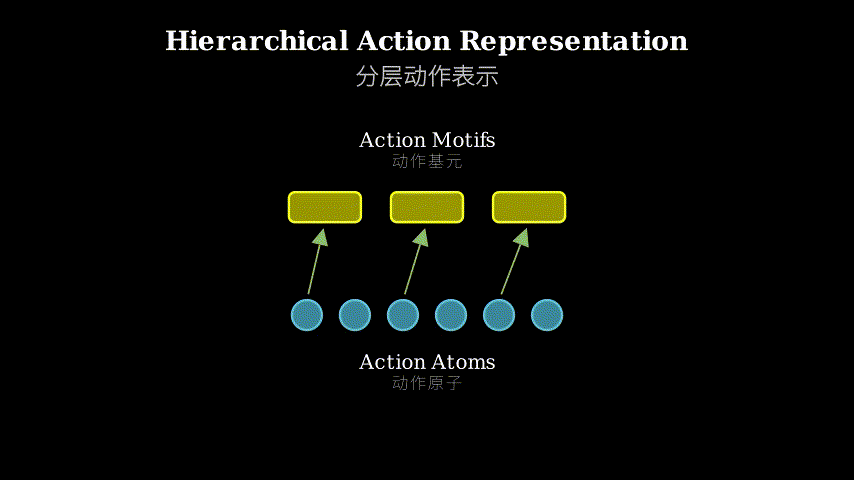
A4Mer uses nested Transformers operating in latent space. The bottom level segments a pose sequence into variable-length chunks, each represented as a single latent token (Action Atom). These tokens capture atomic joint movements like “elbow bend” or “knee lift.” The top level groups these Action Atoms into higher-level tokens (Action Motifs) that encode temporal patterns like “wind-up motion” or “weight shift.”
Both levels learn through masked token prediction. Mask some Action Atoms, predict them from context. Mask some Action Motifs, predict them from their constituent atoms. No action labels needed. The model learns to compress pose sequences into a hierarchy where similar movement patterns across different actions map to the same tokens.
Input: 3D pose sequence (T frames)
   |
   v
[Segment into variable chunks]
   |
   +---> Chunk 1 ---> [Encoder] ---> Action Atom token a1
   +---> Chunk 2 ---> [Encoder] ---> Action Atom token a2
   +---> Chunk 3 ---> [Encoder] ---> Action Atom token a3
   |
   v
Action Atom sequence: [a1, a2, a3, ...]
   |
   v
[Group atoms temporally]
   |
   +---> [a1,a2] ---> [Encoder] ---> Action Motif token m1
   +---> [a3,a4] ---> [Encoder] ---> Action Motif token m2
   |
   v
Action Motif sequence: [m1, m2, ...]

Training: Mask tokens at both levels, predict from context
Think of it like learning language. Action Atoms are morphemes (smallest meaningful units: “un-”, “break”, “-able”). Action Motifs are phrases (“break the ice,” “make a point”). You don’t learn every sentence from scratch. You learn morphemes, then learn how they combine into reusable phrases, then compose phrases into sentences. A4Mer does this for movement: learn atomic joint motions, discover how they combine into reusable movement phrases, then use those phrases to understand full actions. The key insight: by forcing the model to compress sequences into discrete tokens at two levels, it must discover the compositional structure to minimize reconstruction error.
Key Concepts
-
Variable-length segmentation: Instead of fixed windows, A4Mer learns where to split the pose sequence. Some movements are quick (a finger snap), others extended (a squat). Fixed windows would chop a squat in half or waste capacity on a snap. Variable segmentation lets each Action Atom capture a semantically complete atomic movement, however long it takes. The model learns segmentation boundaries jointly with token representations through the reconstruction objective.
-
Latent token hierarchy: Each Action Atom is not a pose or a feature vector, but a discrete token in a learned codebook. Same for Action Motifs. This discretization forces the model to cluster similar movements into the same token, making the representation compositional. If “arm raise” appears in both “wave” and “throw,” it should map to the same Action Atom token. The hierarchy emerges because Motif tokens are predicted from Atom tokens, creating a natural abstraction ladder.
Framework Shift
Before (mainstream approach):        After (this paper):

Pose sequence                        Pose sequence
     |                                    |
     v                                    v
[Frame-level features]               [Segment boundaries]
     |                                    |
     v                                    v
[Temporal model]                     [Action Atoms]
     |                              (discrete tokens)
     v                                    |
Action label                             v
                                     [Action Motifs]
                                    (discrete tokens)
                                         |
                                         v
                                    Action label

Flat: frames -> action              Hierarchical: frames -> atoms
                                                  -> motifs -> action
From end-to-end sequence modeling to explicit compositional structure, the core shift is discovering reusable movement building blocks without supervision.
Expert Assessment
Problem choice: Real gap. Compositionality in human movement is well-established in motor control literature, but underexploited in computer vision. The field has been stuck in the “bigger model, more data” paradigm for action recognition. This paper asks a more fundamental question about representation structure.
Method maturity: The nested Transformer design is elegant, but the variable-length segmentation mechanism is underspecified in the abstract. How are boundaries learned? Differentiable? Discrete? This is critical to reproducibility. The self-supervised pretext task (masked prediction at two levels) is straightforward, which is good—no baroque training tricks.
Experimental integrity: The introduction of AMD (Action Motif Dataset) with foot-mounted cameras is clever for handling occlusions, but raises questions. Are foot-view poses representative of typical action recognition scenarios? The claim that Action Motifs “naturally emerge” needs ablation studies showing they don’t emerge with flat architectures or single-level hierarchies. The abstract doesn’t mention baselines, which is a red flag.
Writing quality: The abstract front-loads architectural details before motivating the problem. Flip it: start with compositionality, then show why existing methods fail to capture it, then introduce the hierarchy. The phrase “fully self-supervised manner” is overused in CV—just say “without action labels.” The AMD section feels like a separate contribution bolted on; integrate it better or split into two papers.
Verdict: weak accept — The core idea (hierarchical discrete tokens for compositional movement) is sound and addresses a real gap, but the abstract lacks experimental rigor details and the writing prioritizes architecture over insight. Needs stronger baselines and clearer segmentation mechanism description.
Takeaways
Steal the two-level discrete token idea for any sequential data with compositional structure. If you’re modeling music, don’t just encode notes—learn “note motifs” (short melodic patterns) and “phrase motifs” (how motifs combine). If you’re modeling code, learn “statement atoms” and “block motifs.” The key transferable technique: force your model to compress sequences into discrete tokens at multiple timescales, and the compositional structure will emerge from the reconstruction pressure.
The variable-length segmentation is also worth stealing. Fixed windows are a lazy default. If your data has natural boundaries (sentence breaks, movement transitions, scene cuts), let the model learn where they are instead of imposing a grid.
Finally, the foot-mounted camera trick for dense SMPL annotation is a practical hack for any dataset with heavy occlusions. Mount cameras on the occluding object itself.
论文: 2604.28173 作者: Genki Kinoshita, Shu Nakamura, Ryo Kawahara, Shohei Nobuhara, Yasutomo Kawanishi, Ko Nishino 分类: cs.CV
缺口
现有的人体动作识别方法把运动当作整体序列处理。
时序CNN和Transformer这类方法端到端地处理整个姿态序列,学到的表示与特定动作标签绑定。
这忽略了人体运动的基本属性:组合性。
“挥手”和”投掷”都包含”抬臂”这个片段。
当前方法为每个动作类别分别学习这些冗余模式,错过了可复用的构建块。
问题核心:没有方法显式地发现并表示这些原子级、可复用的运动片段,也没有构建层次结构。
先前工作要么在帧级别操作(太细碎),要么在动作级别操作(太粗糙),缺少中间结构来捕捉跨不同动作反复出现的有意义时序片段。
问题:整体式动作建模
   |
   v
假设:人体运动具有组合性
   |    (存在可复用片段)
   v
方法:层次化潜在token
   |    (动作原子 -> 动作基元)
   v
证据:基元无监督涌现,
   |    可跨任务迁移
   v
结论:组合性改进
      行为建模
增量
一句话:这篇论文之前,动作表示是扁平的帧序列;之后,我们有了两层层次结构,原子运动(动作原子)组合成可复用模式(动作基元),且无需监督即可发现。
核心机制
A4Mer使用嵌套的Transformer在潜在空间操作。
底层将姿态序列分割成变长块,每块表示为单个潜在token(动作原子)。
这些token捕捉原子级关节运动,比如”肘部弯曲”或”膝盖抬起”。
顶层将这些动作原子分组为更高层token(动作基元),编码时序模式,比如”蓄力动作”或”重心转移”。
两层都通过掩码token预测来学习。
掩盖一些动作原子,从上下文预测它们。
掩盖一些动作基元,从其组成原子预测它们。
不需要动作标签。
模型学会将姿态序列压缩成层次结构,其中不同动作中的相似运动模式映射到相同token。
输入:3D姿态序列(T帧)
   |
   v
[分割成变长块]
   |
   +---> 块1 ---> [编码器] ---> 动作原子token a1
   +---> 块2 ---> [编码器] ---> 动作原子token a2
   +---> 块3 ---> [编码器] ---> 动作原子token a3
   |
   v
动作原子序列:[a1, a2, a3, ...]
   |
   v
[时序分组原子]
   |
   +---> [a1,a2] ---> [编码器] ---> 动作基元token m1
   +---> [a3,a4] ---> [编码器] ---> 动作基元token m2
   |
   v
动作基元序列:[m1, m2, ...]

训练:在两层掩盖token,从上下文预测
把它想象成学语言。
动作原子是词素(最小有意义单元:“un-”、“break”、“-able”)。
动作基元是短语(“break the ice”、“make a point”)。
你不会从零学习每个句子。
你学词素,然后学它们如何组合成可复用短语,再把短语组合成句子。
A4Mer对运动做同样的事:学原子级关节运动,发现它们如何组合成可复用运动短语,然后用这些短语理解完整动作。
关键洞察:通过强制模型在两层将序列压缩成离散token,它必须发现组合结构才能最小化重建误差。
关键概念
- 变长分割:A4Mer不用固定窗口,而是学习在哪里切分姿态序列。
有些运动很快(打响指),有些很长(深蹲)。
固定窗口会把深蹲切成两半,或在响指上浪费容量。
变长分割让每个动作原子捕捉语义完整的原子运动,无论需要多长时间。
模型通过重建目标联合学习分割边界和token表示。
- 潜在token层次:每个动作原子不是姿态或特征向量,而是学习码本中的离散token。
动作基元也一样。
这种离散化迫使模型将相似运动聚类到同一token,使表示具有组合性。
如果”抬臂”同时出现在”挥手”和”投掷”中,它应该映射到同一个动作原子token。
层次结构之所以涌现,是因为基元token从原子token预测,创建了自然的抽象阶梯。
框架转变
之前(主流方法):              之后(本文方法):

姿态序列                        姿态序列
     |                              |
     v                              v
[帧级特征]                      [分割边界]
     |                              |
     v                              v
[时序模型]                      [动作原子]
     |                          (离散token)
     v                              |
动作标签                            v
                                [动作基元]
                               (离散token)
                                    |
                                    v
                                动作标签

扁平:帧 -> 动作                层次:帧 -> 原子
                                        -> 基元 -> 动作
从端到端序列建模到显式组合结构,核心转变是无监督发现可复用运动构建块。
专家评审
选题眼光:真实缺口。
人体运动的组合性在运动控制文献中已被充分证实,但在计算机视觉中利用不足。
该领域一直困在”更大模型、更多数据”的范式中做动作识别。
这篇论文问了一个关于表示结构的更根本问题。
方法成熟度:嵌套Transformer设计优雅,但摘要中变长分割机制描述不足。
边界如何学习?可微?离散?这对可复现性至关重要。
自监督前置任务(两层掩码预测)很直接,这是好事——没有花哨的训练技巧。
实验诚意:引入AMD(动作基元数据集)并用脚部安装相机处理遮挡很巧妙,但引发疑问。
脚部视角的姿态能代表典型动作识别场景吗?声称动作基元”自然涌现”需要消融研究,证明它们不会在扁平架构或单层层次中涌现。
摘要没提基线,这是个危险信号。
写作功力:摘要在阐明问题之前就堆砌架构细节。
应该倒过来:从组合性开始,然后展示现有方法为何无法捕捉它,再引入层次结构。
“完全自监督方式”这个短语在CV中被滥用——直接说”无需动作标签”。
AMD部分感觉像是硬拼上去的独立贡献;要么更好地整合,要么拆成两篇论文。
判决:弱接收 — 核心想法(用于组合运动的层次化离散token)扎实且解决了真实缺口,但摘要缺少实验严谨性细节,写作优先展示架构而非洞察。
需要更强的基线和更清晰的分割机制描述。
要点总结
把两层离散token的想法偷走,用在任何具有组合结构的序列数据上。
如果你在建模音乐,不要只编码音符——学习”音符基元”(短旋律模式)和”乐句基元”(基元如何组合)。
如果你在建模代码,学习”语句原子”和”代码块基元”。
可迁移的关键技术:强制模型在多个时间尺度上将序列压缩成离散token,组合结构会从重建压力中涌现。
变长分割也值得偷。
固定窗口是偷懒的默认选择。
如果你的数据有自然边界(句子断点、运动转换、场景切换),让模型学习边界在哪里,而不是强加网格。
最后,脚部安装相机用于密集SMPL标注的技巧,对任何有严重遮挡的数据集都很实用。
把相机装在遮挡物本身上。