Paper: 2604.08545
Authors: Shilin Yan, Jintao Tong, Hongwei Xue, et al. (Alibaba Group, Huazhong University)
Categories: cs.CV
The Gap
Agentic multimodal models can now interact with external tools—cropping images, executing code, searching the web. But they suffer from a profound meta-cognitive deficit: they cannot distinguish between queries they can answer directly and queries that genuinely require external help. The result is blind tool invocation: reflexive tool execution even when the answer is already visible in the raw image or resolvable from internal knowledge.
This pathological behavior creates two concrete problems. First, it introduces severe latency bottlenecks. Every tool call serializes the reasoning process, turning what could be a single forward pass into a multi-round API orchestration nightmare. Second, redundant tool interactions inject extraneous noise that derails otherwise sound reasoning trajectories. The model crops an already clear image, searches for facts it already knows, or executes code for trivial arithmetic—and each unnecessary step is a new opportunity for environmental errors to corrupt the final answer.
Existing reinforcement learning approaches try to fix this by adding a scalar penalty for tool usage. But this creates an irreconcilable optimization dilemma. An aggressive penalty suppresses essential tool use on hard problems, sacrificing correctness. A mild penalty gets entirely washed out by the variance of the accuracy reward during advantage normalization, rendering it impotent against tool overuse. The core issue is reward coupling: when you scalarize accuracy and efficiency into one mixed reward, the shared variance entangles their gradients, creating semantic ambiguity where a correct-but-inefficient trajectory becomes mathematically indistinguishable from an incorrect-but-efficient one.
[Problem: Blind tool invocation]
      |
[Existing fix: Scalarized reward = accuracy + α × efficiency]
      |
[Failure mode: Variance entanglement]
      |
[Consequence: Either suppress essential tools or fail to curb overuse]
      |
[Gap: Need orthogonal optimization channels]
The Increment
One sentence: Before this paper, agents learned how to use tools; after this paper, they learn the meta-cognitive wisdom of when to abstain from using them.
Core Mechanism
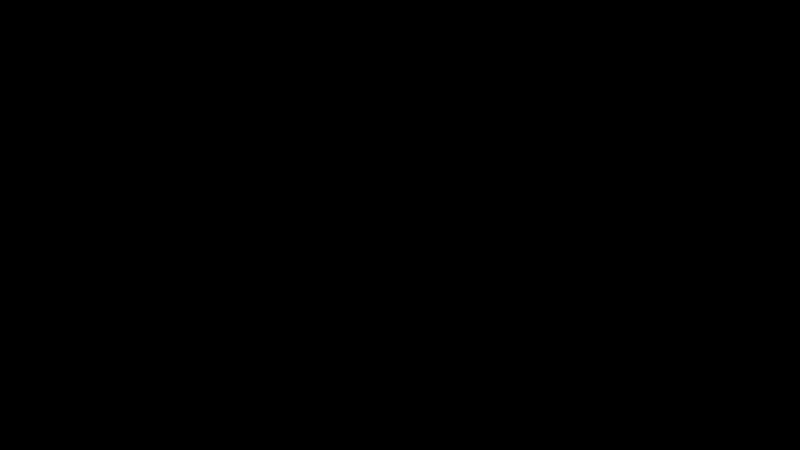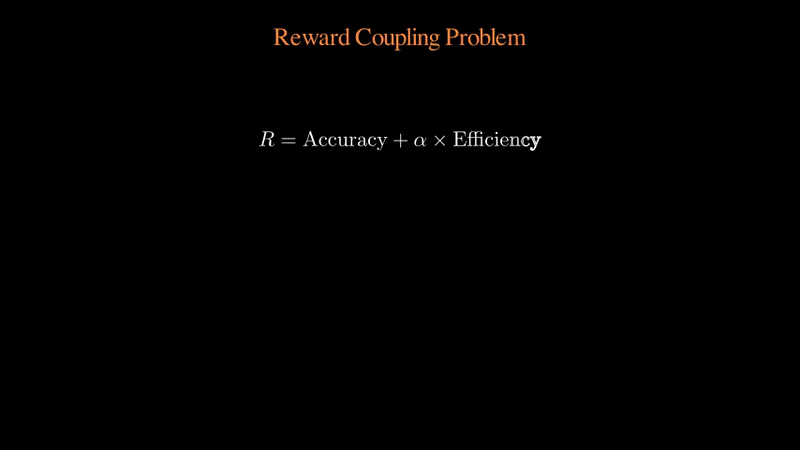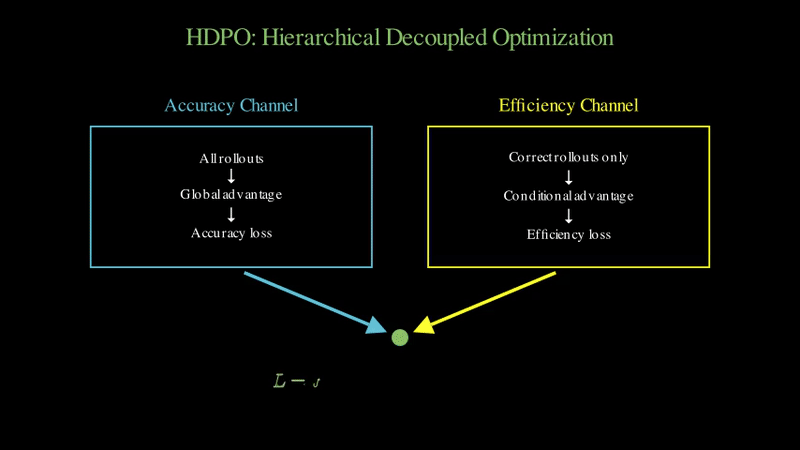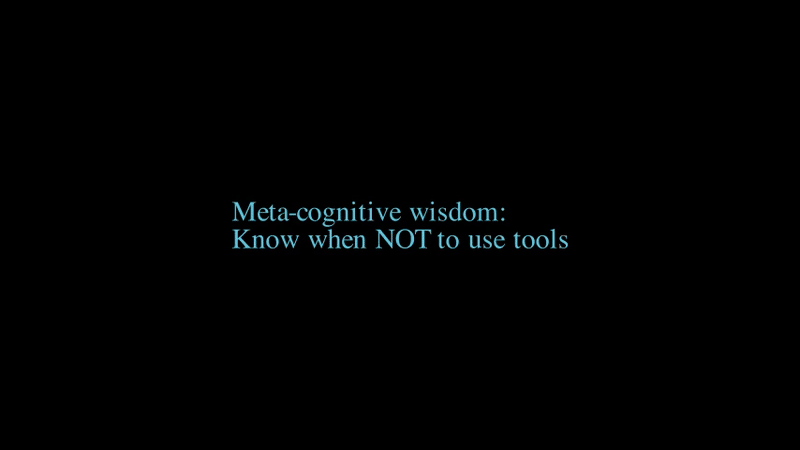
The paper proposes HDPO (Hierarchical Decoupled Policy Optimization), which reframes tool efficiency from a competing scalar objective to a strictly conditional one. Instead of mixing accuracy and efficiency into one reward before normalization, HDPO maintains two independent optimization channels:
-
Accuracy Channel: Maximizes task correctness across all rollouts using standard GRPO advantage estimation. The reward is simply: correct answer (+0.9) + format compliance (+0.1).
-
Efficiency Channel: Enforces tool parsimony exclusively within correct trajectories via conditional advantage estimation. The tool reward is
1/(T+1)where T is the number of tool calls—but only for correct answers. Incorrect rollouts get zero tool reward, preventing the agent from gaming the system by terminating early.
The key innovation is the conditional advantage mechanism. The efficiency advantage is computed only relative to other correct solutions in the same batch. If fewer than two rollouts are correct, no efficiency comparison is made. This ensures the efficiency signal remains strictly grounded in intra-task relative performance, never rewarding speed at the expense of correctness.
The final loss is a weighted sum: L = w_acc × L_GRPO(A_acc) + w_tool × L_GRPO(A_tool). Because the advantages are normalized independently across distinct semantic baselines, the policy gradient decomposes cleanly. Each component delivers a targeted, orthogonal learning signal, eliminating the destructive covariance interference of coupled formulations.
[All rollouts] → [Accuracy advantage via standard GRPO]
                        ↓
                  [Accuracy loss]
                        ↓
[Correct rollouts only] → [Efficiency advantage (conditional)]
                        ↓
                  [Efficiency loss]
                        ↓
            [Combined via weighted sum]
Structural Metaphor: The Surgical Resident Training Protocol.
Think of training a surgical resident. In the old approach (coupled reward), you give them a single score that mixes “Did the patient survive?” with “Did you use too many instruments?” The resident learns confused heuristics: maybe skip the retractor to save points, even if it makes the procedure riskier.
In HDPO, you separate the evaluation. First criterion: patient outcome. If the patient didn’t survive, nothing else matters—no points for “efficient failure.” Second criterion: among successful surgeries, which resident used the minimal necessary toolset? This creates a natural curriculum: first master the procedure, then refine your efficiency. The resident never learns to sacrifice correctness for speed because speed is only evaluated after correctness is proven.
Map it back:
- Patient survival = task accuracy
- Instrument count = tool invocations
- Successful surgeries only = qualifying set Q
- Efficiency comparison among successes = conditional advantage
- Natural curriculum = implicit learning progression
Key Concepts
-
Meta-cognitive arbitration: The ability to dynamically decide between leveraging internal knowledge and querying external utilities. This requires calibrating epistemic uncertainty against the sufficiency of available context—a sophisticated skill that standard supervised fine-tuning cannot instill.
-
Conditional advantage estimation: Computing the efficiency advantage exclusively relative to other correct solutions, ensuring that tool parsimony is optimized only within accurate trajectories. This prevents the agent from gaming the reward by prematurely terminating.
-
Implicit cognitive curriculum: An emergent property of the decoupled design. Early in training, when few rollouts are correct, optimization is dominated by the accuracy objective. As reasoning capabilities mature, more rollouts qualify for efficiency comparison, smoothly scaling up the tool-parsimony signal. The agent naturally learns: first be correct, then be efficient.
Framework Shift
Before (Coupled Reward):              After (HDPO):

[Accuracy + α × Efficiency]          [Accuracy Channel]
         ↓                                    ↓
  [Mixed advantage]                    [Global advantage]
         ↓                                    ↓
[Gradient entanglement]               [Accuracy loss]
         ↓
[Optimization dilemma]                [Efficiency Channel]
                                              ↓
                                      [Conditional advantage]
                                       (correct rollouts only)
                                              ↓
                                       [Efficiency loss]
                                              ↓
                                       [Orthogonal gradients]
From competing objectives to hierarchical objectives: accuracy is global, efficiency is conditional. The shift eliminates the fundamental trade-off by making efficiency a refinement criterion rather than a competing goal.
Expert Assessment
Problem choice: Exceptionally well-motivated. As multimodal agents enter production, latency and reliability become first-order concerns. The observation that current agents invoke tools 80-98% of the time while achieving mediocre accuracy is damning evidence of a real pathology, not a manufactured problem.
Method maturity: The mathematical formulation is elegant. The conditional advantage mechanism is a genuinely clever solution to the reward coupling problem. The implicit curriculum is an emergent property, not a hand-tuned schedule, which suggests the method captures something fundamental about the learning dynamics. However, the approach is tightly coupled to the GRPO framework and requires careful tuning of the efficiency weight (w_tool = 0.15 is optimal, but 0.20 already degrades performance).
Experimental integrity: The results are striking. Metis reduces tool usage from 98% to 2% on V*Bench while improving accuracy from 88.7% to 91.1%. The ablation study clearly demonstrates that HDPO outperforms standard GRPO, and the sensitivity analysis on w_tool shows the expected inverted-U curve. The qualitative cases (Figures 4-5, 7-9 in the paper) effectively illustrate the meta-cognitive behavior. My main concern is benchmark concentration: most evaluation is on perception and math tasks where tool necessity is relatively clear-cut. How does this generalize to more ambiguous scenarios where the boundary between “can solve directly” and “needs tool” is fuzzy?
Writing quality: The paper is well-structured with clear motivation and strong empirical evidence. The mathematical exposition of the reward coupling problem (Equations 3-5) is particularly effective. The system prompt (Appendix A) is a valuable practical contribution. However, the paper could benefit from deeper analysis of what kinds of tokens are eliminated—is it repetition, verification loops, or unnecessary tool setup?
Verdict: Strong Accept — This is a principled solution to a real problem, with compelling evidence and immediate practical value. The meta-cognitive framing is the right level of abstraction for the field.
Takeaways
-
Decouple competing objectives before they reach the loss function. When two goals conflict, don’t scalarize them into one reward. Maintain separate optimization channels and combine them only at the final gradient step. This principle applies beyond tool use to any multi-objective RL problem.
-
Use conditional rewards to enforce hierarchies. If objective B only matters when objective A is satisfied, compute B’s advantage exclusively over the subset where A succeeds. This prevents gaming and creates natural curricula.
-
Audit your data for hallucinated environmental dynamics. The paper’s data curation pipeline is as important as HDPO itself. They rigorously execute all code in sandboxed environments and discard trajectories with execution failures or feedback inconsistencies. Without this, the RL environment provides corrupted signals.
-
Filter out legacy tool dependencies. Many existing datasets were annotated using weaker models that needed tools for simple queries. As base model capabilities improve, retaining these annotations actively conditions models toward blind tool invocation. Use pass@k on the base model to identify and remove unnecessarily tool-heavy examples.
-
Meta-cognitive tool use is a production requirement, not a research curiosity. If you’re deploying agentic systems, measure tool invocation rates alongside accuracy. A model that achieves 85% accuracy with 10% tool usage is often more valuable than one that achieves 87% accuracy with 95% tool usage, because latency and reliability compound in production.
论文: 2604.08545
作者: Shilin Yan, Jintao Tong, Hongwei Xue 等(阿里巴巴集团、华中科技大学)
分类: cs.CV
缺口
多模态智能体现在可以调用外部工具了——裁剪图像、执行代码、搜索网络。但它们有一个致命的元认知缺陷:无法区分哪些问题可以直接回答,哪些问题真正需要外部帮助。结果就是盲目工具调用:即使答案已经在原始图像中清晰可见,或者可以从内部知识直接推理出来,模型也会反射性地执行工具调用。
这种病态行为造成两个具体问题。第一,它引入严重的延迟瓶颈。每次工具调用都会将推理过程串行化,把本可以一次前向传播完成的任务变成多轮 API 编排噩梦。第二,冗余的工具交互会注入额外噪声,破坏原本正确的推理轨迹。模型会裁剪一张本来就很清晰的图像,搜索它已经知道的事实,或者为简单算术执行代码——每一个不必要的步骤都是环境错误污染最终答案的新机会。
现有的强化学习方法试图通过为工具使用添加标量惩罚来解决这个问题。但这造成了一个无法调和的优化困境。激进的惩罚会抑制困难问题上的必要工具使用,牺牲正确性。温和的惩罚则在优势归一化过程中被准确率奖励的方差完全淹没,对工具过度使用毫无作用。核心问题是奖励耦合:当你把准确率和效率标量化为一个混合奖励时,共享的方差会纠缠它们的梯度,造成语义歧义——一个正确但低效的轨迹在数学上变得与一个错误但高效的轨迹无法区分。
[问题:盲目工具调用]
      |
[现有修复:标量化奖励 = 准确率 + α × 效率]
      |
[失败模式:方差纠缠]
      |
[后果:要么抑制必要工具,要么无法遏制过度使用]
      |
[缺口:需要正交的优化通道]
增量
一句话: 这篇论文之前,智能体学习如何使用工具;这篇论文之后,它们学习何时弃用工具的元认知智慧。
核心机制
论文提出了 HDPO(层次解耦策略优化),将工具效率从竞争性标量目标重构为严格的条件目标。HDPO 不是在归一化之前将准确率和效率混合为一个奖励,而是维护两个独立的优化通道:
-
准确率通道:使用标准 GRPO 优势估计在所有轨迹上最大化任务正确性。奖励很简单:正确答案(+0.9)+ 格式合规(+0.1)。
-
效率通道:通过条件优势估计,专门在正确轨迹内强制工具节约。工具奖励是
1/(T+1),其中 T 是工具调用次数——但仅针对正确答案。错误的轨迹获得零工具奖励,防止智能体通过提前终止来欺骗系统。
关键创新是条件优势机制。效率优势仅相对于同一批次中的其他正确解决方案计算。如果少于两个轨迹正确,则不进行效率比较。这确保效率信号严格基于任务内相对性能,永远不会以牺牲正确性为代价奖励速度。
最终损失是加权和:L = w_acc × L_GRPO(A_acc) + w_tool × L_GRPO(A_tool)。因为优势在不同的语义基线上独立归一化,策略梯度干净地分解。每个组件提供有针对性的正交学习信号,消除了耦合公式的破坏性协方差干扰。
[所有轨迹] → [通过标准 GRPO 计算准确率优势]
                        ↓
                  [准确率损失]
                        ↓
[仅正确轨迹] → [效率优势(条件性)]
                        ↓
                  [效率损失]
                        ↓
            [通过加权和组合]
结构隐喻:外科住院医师培训协议。
想象培训一名外科住院医师。在旧方法(耦合奖励)中,你给他们一个混合了”患者是否存活?“和”是否使用了太多器械?“的单一分数。住院医师学到混乱的启发式:也许跳过牵开器来节省分数,即使这会使手术更危险。
在 HDPO 中,你分离评估。第一标准:患者结果。如果患者没有存活,其他都不重要——“高效的失败”不得分。第二标准:在成功的手术中,哪位住院医师使用了最少的必要工具集?这创造了一个自然的课程:首先掌握手术,然后优化效率。住院医师永远不会学会为速度牺牲正确性,因为速度只在正确性被证明后才被评估。
映射回来:
- 患者存活 = 任务准确率
- 器械数量 = 工具调用
- 仅成功的手术 = 合格集 Q
- 成功者之间的效率比较 = 条件优势
- 自然课程 = 隐式学习进程
关键概念
-
元认知仲裁: 在利用内部知识和查询外部工具之间动态决策的能力。这需要根据可用上下文的充分性校准认知不确定性——这是标准监督微调无法灌输的复杂技能。
-
条件优势估计: 专门相对于其他正确解决方案计算效率优势,确保工具节约仅在准确轨迹内优化。这防止智能体通过提前终止来欺骗奖励。
-
隐式认知课程: 解耦设计的涌现属性。训练早期,当很少轨迹正确时,优化由准确率目标主导。随着推理能力成熟,更多轨迹有资格进行效率比较,平滑地扩大工具节约信号。智能体自然学习:首先正确,然后高效。
框架转变
之前(耦合奖励):                  之后(HDPO):

[准确率 + α × 效率]                [准确率通道]
         ↓                                ↓
    [混合优势]                        [全局优势]
         ↓                                ↓
    [梯度纠缠]                        [准确率损失]
         ↓
    [优化困境]                        [效率通道]
                                          ↓
                                    [条件优势]
                                   (仅正确轨迹)
                                          ↓
                                    [效率损失]
                                          ↓
                                    [正交梯度]
从竞争目标到层次目标:准确率是全局的,效率是条件的。这种转变通过将效率变成优化标准而非竞争目标,消除了根本性权衡。
专家评审
选题眼光: 动机极其充分。随着多模态智能体进入生产环境,延迟和可靠性成为一阶关注点。观察到当前智能体在 80-98% 的时间调用工具却只达到平庸准确率,这是真实病理的确凿证据,而非人为制造的问题。
方法成熟度: 数学表述优雅。条件优势机制是对奖励耦合问题的真正巧妙解决方案。隐式课程是涌现属性而非手工调整的时间表,这表明该方法捕捉了学习动力学的某些基本特性。然而,该方法与 GRPO 框架紧密耦合,需要仔细调整效率权重(w_tool = 0.15 是最优的,但 0.20 已经会降低性能)。
实验诚意: 结果令人震撼。Metis 在 V*Bench 上将工具使用从 98% 降至 2%,同时将准确率从 88.7% 提升至 91.1%。消融研究清楚地证明 HDPO 优于标准 GRPO,w_tool 的敏感性分析显示了预期的倒 U 型曲线。定性案例(论文中的图 4-5、7-9)有效地说明了元认知行为。我的主要担忧是基准集中度:大部分评估集中在感知和数学任务上,这些任务的工具必要性相对明确。这如何推广到”可以直接解决”和”需要工具”之间边界模糊的更模糊场景?
写作功力: 论文结构良好,动机清晰,实证证据有力。奖励耦合问题的数学阐述(方程 3-5)特别有效。系统提示(附录 A)是有价值的实践贡献。然而,论文可以从更深入分析被消除的 token 类型中受益——是重复、验证循环,还是不必要的工具设置?
判决: 强接收 — 这是对真实问题的原则性解决方案,具有令人信服的证据和直接的实用价值。元认知框架是该领域的正确抽象层次。
要点总结
-
在目标到达损失函数之前解耦竞争目标。 当两个目标冲突时,不要将它们标量化为一个奖励。维护独立的优化通道,仅在最终梯度步骤组合它们。这个原则适用于任何多目标 RL 问题,不仅仅是工具使用。
-
使用条件奖励来强制层次结构。 如果目标 B 仅在目标 A 满足时才重要,则专门在 A 成功的子集上计算 B 的优势。这防止欺骗并创造自然课程。
-
审计数据中的幻觉环境动力学。 论文的数据整理流程与 HDPO 本身同样重要。他们在沙盒环境中严格执行所有代码,并丢弃具有执行失败或反馈不一致的轨迹。没有这个,RL 环境会提供损坏的信号。
-
过滤掉遗留的工具依赖。 许多现有数据集是使用较弱模型标注的,这些模型需要工具来处理简单查询。随着基础模型能力提高,保留这些标注会主动使模型倾向于盲目工具调用。使用基础模型上的 pass@k 来识别和删除不必要的工具密集型示例。
-
元认知工具使用是生产要求,而非研究好奇心。 如果你正在部署智能体系统,请在准确率之外测量工具调用率。一个以 10% 工具使用率达到 85% 准确率的模型,通常比以 95% 工具使用率达到 87% 准确率的模型更有价值,因为延迟和可靠性在生产中会复合。