Paper: 2604.12989 Authors: Liran Ringel, Yaniv Romano Categories: cs.CL
The Gap
Speculative decoding speeds up large language models by having a cheap drafter propose tokens that an expensive target model verifies in parallel. DFlash introduced block diffusion drafters that generate entire token blocks in one pass, beating autoregressive drafters like EAGLE-3. But DFlash only verifies one drafted sequence per round—it generates a block, the target checks it, accepts what matches, and repeats. This single-path verification leaves parallel verification capacity on the table.
Tree-based methods like SpecInfer and Medusa verify multiple candidate paths simultaneously, but they rely on autoregressive drafters that generate tokens sequentially. The gap: block diffusion drafters output full probability distributions over entire blocks, but existing methods throw away this rich information by sampling just one trajectory.
Problem: DFlash's single-path verification underutilizes target model capacity
    |
    v
Observation: Block diffusion outputs per-position distributions, not just samples
    |
    v
Method: Build draft tree from distributions using best-first search
    |
    v
Evidence: Higher acceptance length than single-path on same node budget
    |
    v
Conclusion: Tree construction extracts more value from diffusion drafters
The Increment
One sentence: Before DDTree, block diffusion drafters verified one sequence per round; after DDTree, they verify a tree of candidates selected by likelihood, increasing accepted tokens per target model call.
Core Mechanism
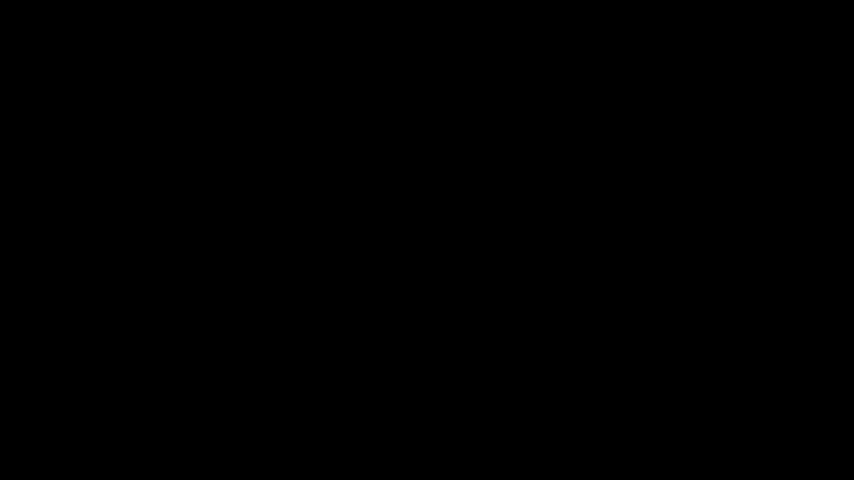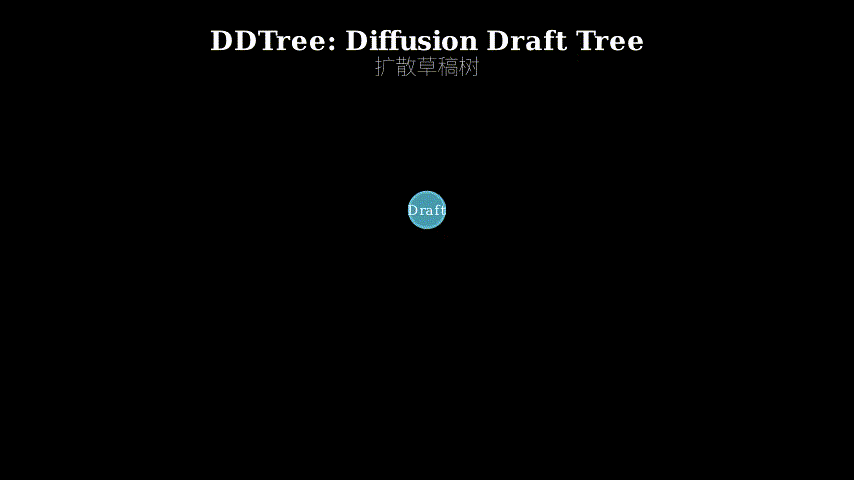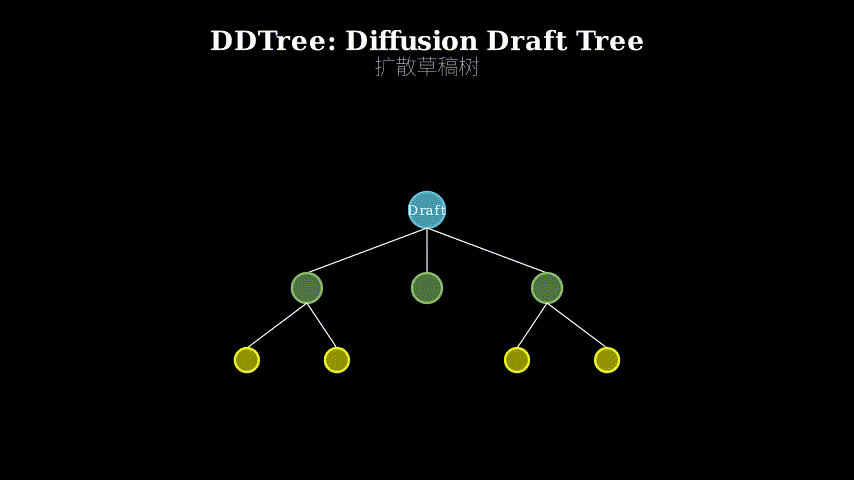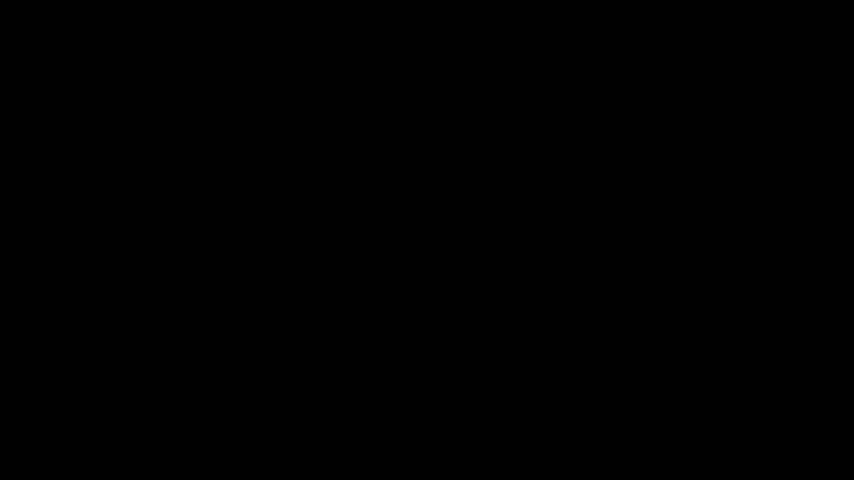
DDTree takes a block diffusion drafter’s output—probability distributions over tokens at each position—and builds a tree of candidate continuations. It starts with the most likely token at position 1, then uses a best-first heap to iteratively add the next most promising node. The “promise” of a node is its cumulative log-probability under the draft model, acting as a surrogate for target model agreement.
The heap maintains candidate nodes sorted by score. At each step, DDTree pops the highest-scoring node, expands it by considering all possible next tokens, and pushes the children back into the heap. This continues until a fixed node budget is exhausted. The result is a tree where high-probability paths get more branches, and low-probability paths get pruned early.
Verification happens in one target model forward pass using an ancestor-only attention mask. Each tree node only attends to its ancestors, allowing the target to process all candidates in parallel. The target’s outputs determine which paths match, and the longest matching prefix is accepted.
Draft Model Output:
  Position 1: [P(token_1), P(token_2), ...]
  Position 2: [P(token_1|pos1), P(token_2|pos1), ...]
  ...
    |
    v
Best-First Tree Construction:
  Heap: [(score, node), ...]
  Pop highest score -> Expand -> Push children
  Repeat until budget exhausted
    |
    v
Tree Structure:
       [root]
      /  |  \
    [A] [B] [C]  <- high prob branches
    / \     |
  [D] [E]  [F]   <- expanded further
    |
    v
Target Verification (parallel):
  Ancestor-only attention mask
  All paths checked in one forward pass
  Longest matching prefix accepted
Think of DDTree like a river delta. The block diffusion drafter is a water source releasing flow in all directions—it gives you probabilities for every possible token at every position. A single-path sampler is like digging one canal: you pick one route and ignore the rest of the water. DDTree instead carves multiple channels, but intelligently: it digs deeper where the water flows strongest (high probability), and abandons weak trickles early (low probability). The node budget is your excavation capacity—you can’t dig everywhere, so you prioritize channels that carry the most flow. When the target model verifies, it’s like checking which channels actually connect to the ocean (match the target’s distribution). You accept the longest connected waterway.
Key Concepts
-
Block Diffusion Drafter: Traditional autoregressive drafters generate tokens one at a time: predict token 1, then use it to predict token 2, etc. Block diffusion drafters flip this: they generate an entire block of tokens in one forward pass using a diffusion process. Instead of sequential dependencies, they model the joint distribution over the whole block. The output isn’t just samples—it’s full probability distributions at each position. This is crucial because DDTree needs those distributions to build its tree. Think of it like the difference between drawing a picture stroke-by-stroke versus generating the whole image at once with probabilities for each pixel.
-
Best-First Heap Algorithm: A heap is a data structure that keeps elements sorted by priority, letting you efficiently grab the highest-priority item. DDTree’s heap stores tree nodes, each scored by cumulative log-probability (sum of log-probs along the path from root to that node). “Best-first” means always expanding the most promising node next. Why? Because the draft model’s probabilities are a proxy for target model agreement—paths the drafter thinks are likely are more likely to be accepted. By expanding high-probability nodes first, DDTree builds a tree that concentrates budget where it matters. It’s like triaging patients: treat the most critical cases first, not in random order.
-
Ancestor-Only Attention Mask: In transformer verification, each token needs context from previous tokens. In a tree, “previous” is ambiguous—which path did you take? The ancestor-only mask solves this: each node only attends to tokens along its path from the root. Node D (child of A, child of root) attends to [root, A, D], not to sibling B or cousin E. This lets the target model process all tree nodes in one forward pass without mixing contexts between branches. It’s like parallel universes: each branch has its own timeline, and you don’t let events from one timeline leak into another.
Framework Shift
Before (DFlash single-path):        After (DDTree):

Draft Model                         Draft Model
    |                                   |
    v                                   v
Sample one                          Full distributions
sequence                                |
    |                                   v
    v                               Best-first tree
[A]->[B]->[C]->[D]                  construction
    |                                   |
    v                                   v
Target verifies                         [root]
linear path                            / | \
    |                                 A  B  C
    v                                /|   |
Accept prefix                      D E   F
                                      |
                                      v
                                  Target verifies
                                  all paths (parallel)
                                      |
                                      v
                                  Accept longest
                                  matching path
From single-path sampling to tree-based exploration, the core shift is extracting multiple candidates from the same draft model output instead of committing to one trajectory upfront.
Expert Assessment
Problem choice: Real gap. DFlash demonstrated that block diffusion drafters are competitive, but the single-path verification is an obvious bottleneck—you’re generating rich distributional information and then collapsing it to one sample. The problem sits at the intersection of two active areas: speculative decoding and diffusion models for discrete data. It’s incremental but well-motivated.
Method maturity: The best-first heap is simple and effective, but not particularly novel—it’s a standard search algorithm applied to a new domain. The key insight is recognizing that block diffusion outputs can be treated as a search space. The ancestor-only attention mask is borrowed from existing tree-based speculative decoding work. The contribution is more about integration than invention. A simpler approach might be top-k sampling at each position to build a fixed-width tree, but best-first is more principled.
Experimental integrity: The paper claims “state-of-the-art” performance but doesn’t provide full experimental details in the abstract. The comparison to EAGLE-3 is promising, but we’d need to see ablations (does the tree actually help, or is it just DFlash being good?), sensitivity to node budget, and results across different model sizes and tasks. The ancestor-only mask is efficient, but what’s the actual wall-clock speedup versus single-path? Red flag: no mention of failure modes or when DDTree underperforms.
Writing quality: The abstract is clear but oversells (“leading approaches” appears twice). The method description is solid, but the paper likely buries important details in appendices—how exactly are the per-position distributions extracted from the diffusion process? How sensitive is the surrogate score to calibration? The related work section probably needs tightening to clearly position DDTree relative to both tree-based methods (SpecInfer, Medusa) and diffusion drafters (DFlash).
Verdict: weak accept — Solid incremental contribution that combines existing ideas (block diffusion, tree verification) in a natural way, but needs stronger empirical validation and clearer positioning to be compelling.
Takeaways
Surrogate scoring for tree search: When you have a cheap model that outputs distributions and an expensive model that verifies, you can use the cheap model’s probabilities as a heuristic to guide search. This applies beyond language models—anywhere you have a fast approximator and a slow oracle (e.g., neural architecture search, molecular design).
Exploiting distributional outputs: If your draft model gives you full distributions instead of just samples, you’re leaving value on the table by sampling once. Build a tree, beam search, or other structured exploration. This is relevant for any generative model that outputs probabilities (VAEs, diffusion models, flow models).
Ancestor-only masking pattern: The technique of letting each tree node attend only to its ancestors is a clean way to do parallel verification of multiple hypotheses in transformers. Useful for any scenario where you want to evaluate multiple continuations without recomputing shared prefixes (e.g., dialogue systems exploring multiple responses, code completion with multiple suggestions).
论文: 2604.12989 作者: Liran Ringel, Yaniv Romano 分类: cs.CL
缺口
推测解码通过让廉价的草稿器提出候选词元、昂贵的目标模型并行验证来加速大语言模型。
DFlash 引入了块扩散草稿器,一次生成整个词元块,击败了 EAGLE-3 等自回归草稿器。
但 DFlash 每轮只验证一条草稿序列——生成一个块,目标模型检查,接受匹配部分,然后重复。
这种单路径验证浪费了并行验证容量。
SpecInfer 和 Medusa 等基于树的方法同时验证多条候选路径,但它们依赖顺序生成词元的自回归草稿器。
缺口在于:块扩散草稿器输出整个块的完整概率分布,但现有方法只采样一条轨迹,丢弃了这些丰富信息。
问题:DFlash 的单路径验证未充分利用目标模型容量
    |
    v
观察:块扩散输出每个位置的分布,而非仅仅采样
    |
    v
方法:用最佳优先搜索从分布构建草稿树
    |
    v
证据:相同节点预算下接受长度更高
    |
    v
结论:树构建从扩散草稿器中提取更多价值
增量
一句话: DDTree 之前,块扩散草稿器每轮验证一条序列;DDTree 之后,它们验证一棵按似然选择的候选树,每次目标模型调用接受更多词元。
核心机制
DDTree 接收块扩散草稿器的输出——每个位置上词元的概率分布——并构建一棵候选延续树。
它从位置 1 最可能的词元开始,然后用最佳优先堆迭代添加下一个最有希望的节点。
节点的”希望值”是其在草稿模型下的累积对数概率,作为目标模型一致性的代理。
堆维护按分数排序的候选节点。
每一步,DDTree 弹出得分最高的节点,通过考虑所有可能的下一个词元来扩展它,并将子节点推回堆中。
这持续到固定节点预算耗尽。
结果是一棵树,高概率路径获得更多分支,低概率路径被提前剪枝。
验证在一次目标模型前向传播中完成,使用祖先注意力掩码。
每个树节点只关注其祖先,允许目标并行处理所有候选。
目标的输出决定哪些路径匹配,接受最长匹配前缀。
草稿模型输出:
  位置 1: [P(词元_1), P(词元_2), ...]
  位置 2: [P(词元_1|位置1), P(词元_2|位置1), ...]
  ...
    |
    v
最佳优先树构建:
  堆:[(分数, 节点), ...]
  弹出最高分 -> 扩展 -> 推入子节点
  重复直到预算耗尽
    |
    v
树结构:
       [根]
      /  |  \
    [A] [B] [C]  <- 高概率分支
    / \     |
  [D] [E]  [F]   <- 进一步扩展
    |
    v
目标验证(并行):
  祖先注意力掩码
  一次前向传播检查所有路径
  接受最长匹配前缀
把 DDTree 想象成河流三角洲。
块扩散草稿器是向所有方向释放水流的水源——它给你每个位置上每个可能词元的概率。
单路径采样器像挖一条运河:你选一条路线,忽略其余的水。
DDTree 则开凿多条水道,但很聪明:它在水流最强的地方(高概率)挖得更深,提前放弃弱涓流(低概率)。
节点预算是你的挖掘能力——你不能到处挖,所以优先考虑承载最多水流的水道。
当目标模型验证时,就像检查哪些水道真正连接到海洋(匹配目标分布)。
你接受最长的连通水道。
关键概念
- 块扩散草稿器: 传统自回归草稿器逐个生成词元:预测词元 1,然后用它预测词元 2,依此类推。
块扩散草稿器翻转了这一点:它用扩散过程一次前向传播生成整个词元块。
它不是顺序依赖,而是对整个块的联合分布建模。
输出不仅仅是采样——而是每个位置的完整概率分布。
这很关键,因为 DDTree 需要这些分布来构建树。
想象一下逐笔画画和一次生成整幅图像(每个像素都有概率)的区别。
- 最佳优先堆算法: 堆是一种按优先级保持元素排序的数据结构,让你高效地抓取最高优先级项。
DDTree 的堆存储树节点,每个节点按累积对数概率(从根到该节点路径上对数概率之和)评分。
“最佳优先”意味着总是下一个扩展最有希望的节点。
为什么?因为草稿模型的概率是目标模型一致性的代理——草稿器认为可能的路径更可能被接受。
通过首先扩展高概率节点,DDTree 构建一棵将预算集中在重要位置的树。
这就像分诊病人:先治疗最危急的病例,而不是随机顺序。
- 祖先注意力掩码: 在 transformer 验证中,每个词元需要来自先前词元的上下文。
在树中,“先前”是模糊的——你走了哪条路径?祖先掩码解决了这个问题:每个节点只关注从根到它的路径上的词元。
节点 D(A 的子节点,根的孙节点)关注 [根, A, D],而不是兄弟 B 或堂兄 E。
这让目标模型在一次前向传播中处理所有树节点,而不会混合分支之间的上下文。
这就像平行宇宙:每个分支都有自己的时间线,你不让一个时间线的事件泄漏到另一个时间线。
框架转变
之前(DFlash 单路径):          之后(DDTree):

草稿模型                         草稿模型
    |                                |
    v                                v
采样一条                          完整分布
序列                                 |
    |                                v
    v                            最佳优先树
[A]->[B]->[C]->[D]               构建
    |                                |
    v                                v
目标验证                             [根]
线性路径                            / | \
    |                              A  B  C
    v                             /|   |
接受前缀                         D E   F
                                   |
                                   v
                               目标验证
                               所有路径(并行)
                                   |
                                   v
                               接受最长
                               匹配路径
从单路径采样到基于树的探索,核心转变是从同一草稿模型输出中提取多个候选,而不是预先承诺一条轨迹。
专家评审
选题眼光: 真实缺口。
DFlash 证明了块扩散草稿器有竞争力,但单路径验证是明显的瓶颈——你生成了丰富的分布信息,然后将其折叠为一个样本。
问题位于两个活跃领域的交叉点:推测解码和离散数据的扩散模型。
这是渐进式的,但动机充分。
方法成熟度: 最佳优先堆简单有效,但不是特别新颖——它是应用于新领域的标准搜索算法。
关键洞察是认识到块扩散输出可以被视为搜索空间。
祖先注意力掩码借鉴自现有的基于树的推测解码工作。
贡献更多是关于集成而非发明。
更简单的方法可能是在每个位置进行 top-k 采样以构建固定宽度的树,但最佳优先更有原则。
实验诚意: 论文声称”最先进”性能,但摘要中没有提供完整的实验细节。
与 EAGLE-3 的比较很有希望,但我们需要看到消融实验(树真的有帮助,还是只是 DFlash 本身好?)、对节点预算的敏感性,以及跨不同模型大小和任务的结果。
祖先掩码是高效的,但与单路径相比,实际的墙钟加速是多少?警示信号:没有提及失败模式或 DDTree 表现不佳的情况。
写作功力: 摘要清晰但过度推销(“领先方法”出现两次)。
方法描述扎实,但论文可能将重要细节埋在附录中——如何从扩散过程中提取每个位置的分布?代理分数对校准的敏感性如何?相关工作部分可能需要收紧,以清楚地将 DDTree 相对于基于树的方法(SpecInfer、Medusa)和扩散草稿器(DFlash)定位。
判决: 弱接收 — 扎实的渐进式贡献,以自然的方式结合现有想法(块扩散、树验证),但需要更强的实证验证和更清晰的定位才能令人信服。
要点总结
树搜索的代理评分: 当你有一个输出分布的廉价模型和一个验证的昂贵模型时,你可以使用廉价模型的概率作为启发式来指导搜索。
这适用于语言模型之外——任何有快速近似器和慢速预言机的地方(例如神经架构搜索、分子设计)。
利用分布输出: 如果你的草稿模型给你完整分布而不仅仅是样本,采样一次就是在浪费价值。
构建树、束搜索或其他结构化探索。
这与任何输出概率的生成模型相关(VAE、扩散模型、流模型)。
祖先掩码模式: 让每个树节点只关注其祖先的技术是在 transformer 中并行验证多个假设的简洁方法。
适用于任何想要评估多个延续而不重新计算共享前缀的场景(例如探索多个响应的对话系统、具有多个建议的代码补全)。