Paper: 2602.20159 Authors: Maijunxian Wang, Ruisi Wang, Juyi Lin, Ran Ji, Thaddäus Wiedemer, Qingying Gao, Dezhi Luo, Yaoyao Qian, Lianyu Huang, Zelong Hong Categories: cs.CV, cs.AI, cs.LG, cs.MM, cs.RO
Abstract
While video generation models have made impressive strides in visual quality, their reasoning capabilities remain largely unexplored. This paper addresses a critical gap in video understanding research by introducing the Very Big Video Reasoning (VBVR) Dataset, containing over one million video clips spanning 200 carefully curated reasoning tasks. The dataset is approximately three orders of magnitude larger than existing video reasoning benchmarks, enabling systematic study of scaling behavior in video reasoning models. Alongside the dataset, the authors present VBVR-Bench, a verifiable evaluation framework that uses rule-based, human-aligned scorers instead of model-based judging, ensuring reproducible and interpretable assessment. Through large-scale experiments, the research reveals early signs of emergent generalization to unseen reasoning tasks, suggesting that video reasoning capabilities may scale with data and model size in ways similar to language models.
Key Contributions
- Unprecedented Scale: VBVR contains over 1 million video clips across 200 reasoning tasks, roughly 1000× larger than existing video reasoning datasets
- Principled Taxonomy: A structured categorization of video reasoning tasks covering spatiotemporal continuity, object interactions, causal relationships, and physical dynamics
- Verifiable Evaluation: VBVR-Bench introduces rule-based scoring mechanisms that eliminate the subjectivity and inconsistency of model-based evaluation
- Scaling Study: First large-scale empirical investigation of how video reasoning capabilities emerge and generalize with increased data and model capacity
- Open Resources: Complete dataset, benchmark toolkit, and trained models publicly released at https://video-reason.com/
The Video Reasoning Gap
Current video models excel at generating visually coherent content but struggle with fundamental reasoning tasks that require understanding spatiotemporal structure. Unlike text, video provides grounded visual environments where reasoning must account for:
- Temporal Continuity: Understanding how scenes evolve consistently over time
- Spatial Relationships: Tracking object positions, orientations, and interactions in 3D space
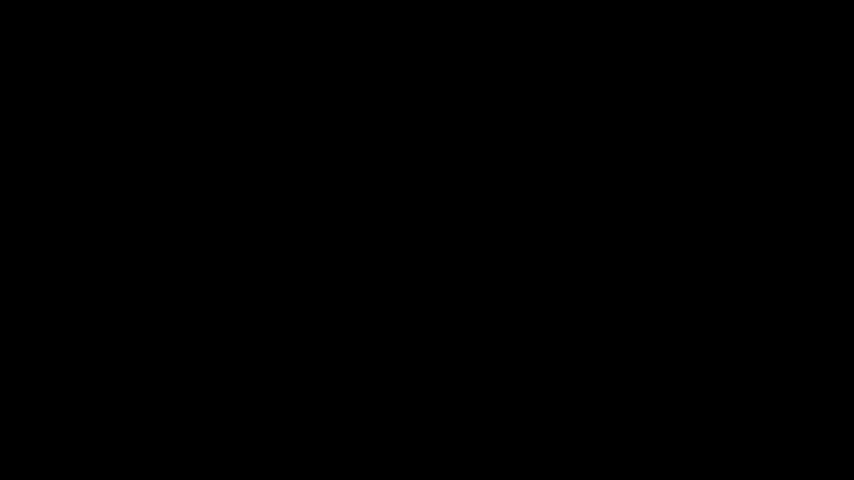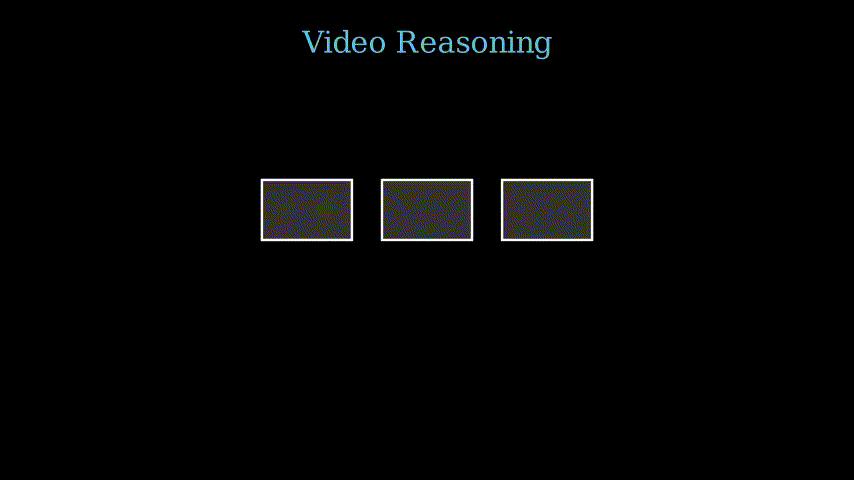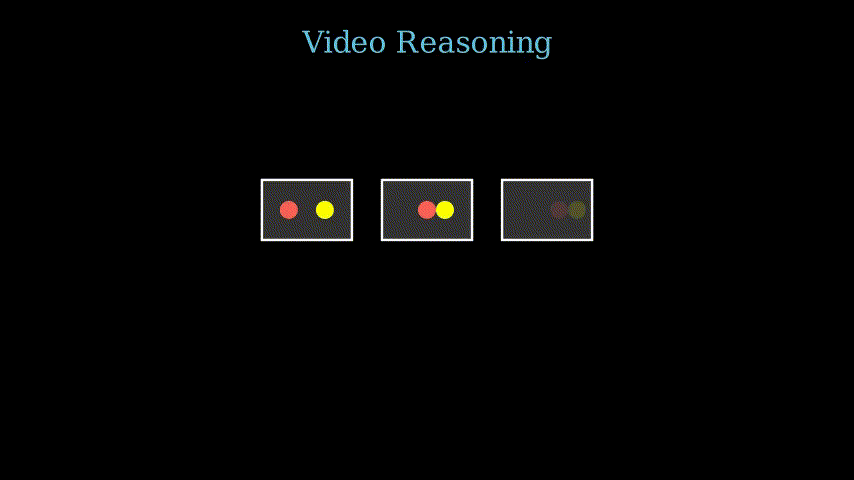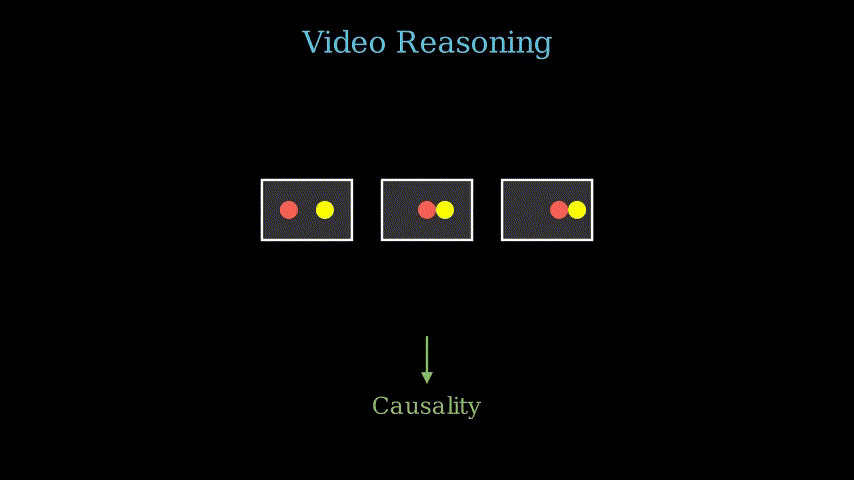
- Causal Dynamics: Inferring cause-and-effect relationships from observed physical events
- Counterfactual Reasoning: Predicting alternative outcomes under different conditions
The lack of large-scale training data has prevented systematic study of these capabilities. Existing video reasoning datasets typically contain hundreds to thousands of examples, insufficient for training modern deep learning models or studying scaling laws. VBVR bridges this gap by providing a resource comparable in scale to language model pretraining datasets.
Dataset Design and Taxonomy
VBVR organizes its 200 reasoning tasks into a hierarchical taxonomy based on cognitive complexity and reasoning type:
Physical Reasoning: Tasks involving understanding of physics, including object dynamics, collision prediction, stability assessment, and force inference. These tasks test whether models grasp fundamental physical laws governing motion and interaction.
Temporal Reasoning: Tasks requiring understanding of event sequences, temporal ordering, duration estimation, and change detection. Models must track how states evolve and identify temporal dependencies.
Spatial Reasoning: Tasks focused on 3D understanding, including depth perception, occlusion reasoning, viewpoint transformation, and spatial relationship inference.
Causal Reasoning: Tasks that require identifying cause-effect relationships, predicting consequences, and understanding intervention effects in dynamic scenes.
Compositional Reasoning: Complex tasks combining multiple reasoning types, testing the model’s ability to integrate different cognitive capabilities.
Each task includes multiple difficulty levels, enabling fine-grained analysis of model capabilities. The dataset construction process involved careful curation to ensure diversity in visual content, scene complexity, and reasoning requirements.
VBVR-Bench: Verifiable Evaluation Framework
A critical innovation is the evaluation methodology. Traditional video understanding benchmarks often rely on model-based judges (e.g., using GPT-4 to score responses), which introduces several problems:
- Inconsistency: Model judges can produce different scores for identical inputs across runs
- Bias: Judges may favor certain response styles or exhibit systematic preferences
- Opacity: The scoring rationale is often unclear, making debugging difficult
- Cost: API-based evaluation can be expensive at scale
VBVR-Bench addresses these issues through rule-based, programmatic scorers aligned with human judgment. For each task, the framework defines explicit success criteria that can be automatically verified. This approach provides:
- Reproducibility: Identical inputs always produce identical scores
- Interpretability: Clear explanation of why a response succeeded or failed
- Efficiency: Fast evaluation without API calls or model inference
- Reliability: No dependence on external services or model availability
The human alignment process involved extensive validation to ensure rule-based scores correlate strongly with expert human judgments across diverse reasoning tasks.
Scaling Behavior and Emergent Generalization
Using VBVR, the authors conducted extensive scaling experiments varying:
- Data Scale: Training on subsets ranging from to examples
- Model Size: Testing architectures from small (millions of parameters) to large (billions of parameters)
- Task Diversity: Evaluating on held-out reasoning tasks not seen during training
Key findings include:
Power Law Scaling: Performance on video reasoning tasks follows power law relationships with both data size and model capacity, similar to language model scaling laws. This suggests that continued scaling may yield substantial improvements.
Emergent Generalization: Models trained on diverse reasoning tasks show non-trivial transfer to completely unseen task types. This zero-shot generalization emerges primarily in larger models trained on more diverse data, indicating that video reasoning may exhibit emergent capabilities analogous to those observed in large language models.
Task Composition: Models demonstrate ability to solve complex compositional tasks by combining simpler reasoning primitives learned during training, suggesting hierarchical learning of reasoning skills.
Bottlenecks: Physical reasoning tasks involving precise dynamics prediction remain challenging even for the largest models, indicating areas where current architectures may need architectural innovations beyond pure scaling.
Implications for Video AI
VBVR establishes video reasoning as a distinct research direction with unique challenges and opportunities:
Beyond Visual Quality: The field must move beyond perceptual metrics to evaluate genuine understanding of spatiotemporal structure and causal relationships.
Grounded Intelligence: Video provides a natural testbed for grounded reasoning that connects perception to physical understanding, potentially bridging vision and robotics.
Scaling Paradigm: The observed scaling behavior suggests that video reasoning may benefit from the same data-driven scaling approach that transformed language models, but requires domain-specific datasets like VBVR.
Evaluation Rigor: The success of rule-based evaluation demonstrates the importance of verifiable, interpretable benchmarks in AI research, especially as models become more capable.
Takeaways
- VBVR provides the first dataset at sufficient scale (1M+ videos, 200 tasks) to enable systematic study of video reasoning and its scaling properties
- Video reasoning exhibits early signs of emergent generalization to unseen tasks, suggesting that scaling laws may apply beyond language models
- Rule-based evaluation frameworks can provide more reliable and interpretable assessment than model-based judges for structured reasoning tasks
- Physical reasoning remains a significant challenge even for large models, indicating opportunities for architectural innovation
- The principled taxonomy and open resources establish a foundation for the next generation of video understanding research focused on reasoning rather than just perception
论文: 2602.20159 作者: Maijunxian Wang, Ruisi Wang, Juyi Lin, Ran Ji, Thaddäus Wiedemer, Qingying Gao, Dezhi Luo, Yaoyao Qian, Lianyu Huang, Zelong Hong 分类: cs.CV, cs.AI, cs.LG, cs.MM, cs.RO
摘要
尽管视频生成模型在视觉质量方面取得了显著进展,但其推理能力仍未得到充分探索。本文通过引入超大规模视频推理(VBVR)数据集,填补了视频理解研究中的关键空白。该数据集包含超过100万个视频片段,涵盖200个精心设计的推理任务,比现有视频推理基准大约三个数量级。这使得系统性研究视频推理模型的规模化行为成为可能。除数据集外,作者还提出了VBVR-Bench可验证评估框架,采用基于规则的人类对齐评分器而非模型评判,确保可重现和可解释的评估。通过大规模实验,研究揭示了模型对未见推理任务的涌现泛化能力的早期迹象,表明视频推理能力可能以类似语言模型的方式随数据和模型规模扩展。
主要贡献
- 前所未有的规模: VBVR包含超过100万视频片段和200个推理任务,比现有视频推理数据集大约1000倍
- 系统化分类体系: 建立了结构化的视频推理任务分类,涵盖时空连续性、物体交互、因果关系和物理动力学
- 可验证评估: VBVR-Bench引入基于规则的评分机制,消除了模型评估的主观性和不一致性
- 规模化研究: 首次对视频推理能力如何随数据和模型容量涌现和泛化进行大规模实证研究
- 开放资源: 完整数据集、基准测试工具包和训练模型在 https://video-reason.com/ 公开发布
视频推理的能力鸿沟
当前视频模型在生成视觉连贯内容方面表现出色,但在需要理解时空结构的基础推理任务上却力不从心。与文本不同,视频提供了具身的视觉环境,推理必须考虑:
- 时间连续性: 理解场景如何随时间一致演化
- 空间关系: 在三维空间中追踪物体位置、方向和交互
- 因果动力学: 从观察到的物理事件推断因果关系
- 反事实推理: 预测不同条件下的替代结果
缺乏大规模训练数据阻碍了对这些能力的系统研究。现有视频推理数据集通常只包含数百到数千个样本,不足以训练现代深度学习模型或研究规模化规律。VBVR通过提供与语言模型预训练数据集相当规模的资源,弥补了这一差距。
数据集设计与分类体系
VBVR将其200个推理任务组织成基于认知复杂度和推理类型的层次化分类体系:
物理推理: 涉及物理理解的任务,包括物体动力学、碰撞预测、稳定性评估和力的推断。这些任务测试模型是否掌握支配运动和交互的基本物理定律。
时间推理: 需要理解事件序列、时间顺序、持续时间估计和变化检测的任务。模型必须追踪状态如何演化并识别时间依赖关系。
空间推理: 专注于三维理解的任务,包括深度感知、遮挡推理、视角转换和空间关系推断。
因果推理: 需要识别因果关系、预测后果和理解动态场景中干预效应的任务。
组合推理: 结合多种推理类型的复杂任务,测试模型整合不同认知能力的能力。
每个任务包含多个难度级别,支持对模型能力的细粒度分析。数据集构建过程经过精心策划,确保视觉内容、场景复杂度和推理需求的多样性。
VBVR-Bench: 可验证评估框架
评估方法论是一项关键创新。传统视频理解基准通常依赖模型评判(例如使用GPT-4对响应评分),这引入了几个问题:
- 不一致性: 模型评判可能对相同输入在不同运行中产生不同分数
- 偏差: 评判可能偏好某些响应风格或表现出系统性偏好
- 不透明性: 评分理由通常不清楚,使调试困难
- 成本: 基于API的评估在大规模时可能昂贵
VBVR-Bench通过与人类判断对齐的基于规则的程序化评分器解决这些问题。对于每个任务,框架定义了可自动验证的明确成功标准。这种方法提供:
- 可重现性: 相同输入始终产生相同分数
- 可解释性: 清楚解释响应成功或失败的原因
- 效率: 无需API调用或模型推理的快速评估
- 可靠性: 不依赖外部服务或模型可用性
人类对齐过程涉及广泛验证,确保基于规则的分数与专家人类判断在各种推理任务中高度相关。
规模化行为与涌现泛化
利用VBVR,作者进行了广泛的规模化实验,变化包括:
- 数据规模: 在从到样本的子集上训练
- 模型大小: 测试从小型(数百万参数)到大型(数十亿参数)的架构
- 任务多样性: 在训练期间未见的保留推理任务上评估
关键发现包括:
幂律规模化: 视频推理任务的性能与数据大小和模型容量都遵循幂律关系,类似于语言模型的规模化规律。这表明持续规模化可能产生实质性改进。
涌现泛化: 在多样化推理任务上训练的模型对完全未见的任务类型表现出非平凡的迁移能力。这种零样本泛化主要出现在更大规模、训练数据更多样化的模型中,表明视频推理可能表现出类似大语言模型观察到的涌现能力。
任务组合: 模型展示了通过组合训练期间学习的简单推理原语来解决复杂组合任务的能力,表明推理技能的层次化学习。
瓶颈: 涉及精确动力学预测的物理推理任务即使对最大模型仍具挑战性,表明当前架构可能需要超越纯规模化的架构创新。
对视频AI的启示
VBVR将视频推理确立为具有独特挑战和机遇的研究方向:
超越视觉质量: 该领域必须超越感知指标,评估对时空结构和因果关系的真正理解。
具身智能: 视频为连接感知与物理理解的具身推理提供了自然测试平台,可能架起视觉与机器人学的桥梁。
规模化范式: 观察到的规模化行为表明视频推理可能受益于改变语言模型的相同数据驱动规模化方法,但需要像VBVR这样的领域特定数据集。
评估严谨性: 基于规则评估的成功证明了可验证、可解释基准在AI研究中的重要性,特别是随着模型能力增强。
要点总结
- VBVR提供了首个足够规模(100万+视频,200任务)的数据集,使视频推理及其规模化特性的系统研究成为可能
- 视频推理表现出对未见任务涌现泛化的早期迹象,表明规模化规律可能适用于语言模型之外
- 基于规则的评估框架可以为结构化推理任务提供比模型评判更可靠和可解释的评估
- 物理推理即使对大型模型仍是重大挑战,表明架构创新的机会
- 系统化分类体系和开放资源为下一代专注于推理而非仅感知的视频理解研究奠定了基础