Paper: 2604.11582 Authors: Olga Chetverina Categories: cs.CL, cs.AI, cs.LG
The Gap
Standard subword tokenizers (BPE, WordPiece, SentencePiece) treat numbers as just another text stream. They fragment “123456” inconsistently — sometimes as “123|456”, sometimes as “12|34|56”, depending on training corpus statistics. This destroys two critical properties: positional structure (which digit is in the thousands place?) and decimal alignment (where’s the decimal point relative to each digit?). The result: LLMs fail at basic arithmetic not because they can’t learn addition, but because the input representation scrambles the problem before the model even sees it.
Prior fixes fall into two camps: (1) character-level tokenization (preserves structure but explodes sequence length), (2) learned embeddings that try to recover position post-tokenization (adds parameters and training complexity). Both treat the symptom, not the cause. The cause is that tokenization throws away the very structure arithmetic depends on.
Problem: Standard tokenizers fragment numbers inconsistently
   |
   v
Assumption: If we chunk deterministically + annotate magnitude explicitly
   |
   v
Method: Triadic Suffix Tokenization (3-digit groups + magnitude markers)
   |
   v
Evidence: [Deferred - no experiments yet]
   |
   v
Conclusion: Should provide stable gradient signal for numerical reasoning
The Increment
One sentence: Before this paper, numbers entered LLMs as structurally ambiguous token sequences; after, they arrive as magnitude-annotated triads with explicit positional semantics baked into the vocabulary.
Core Mechanism
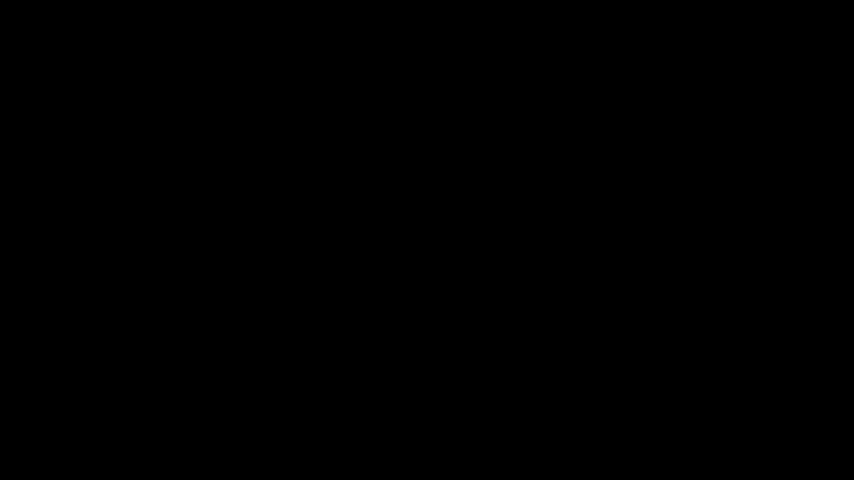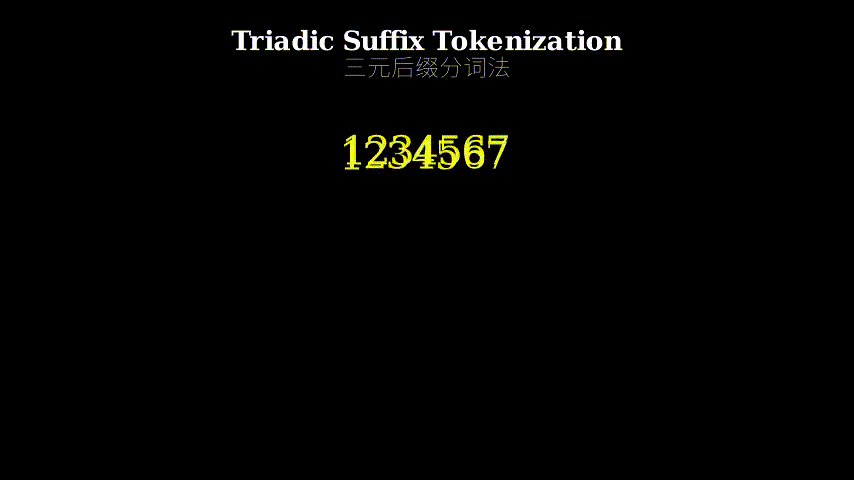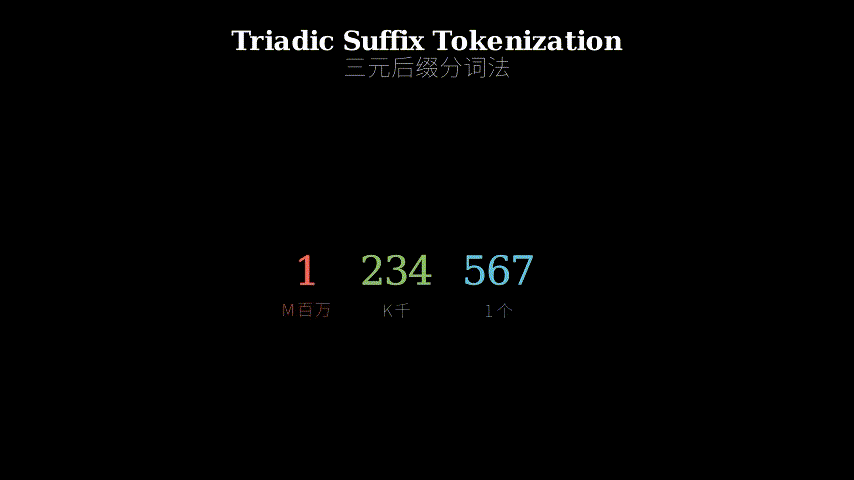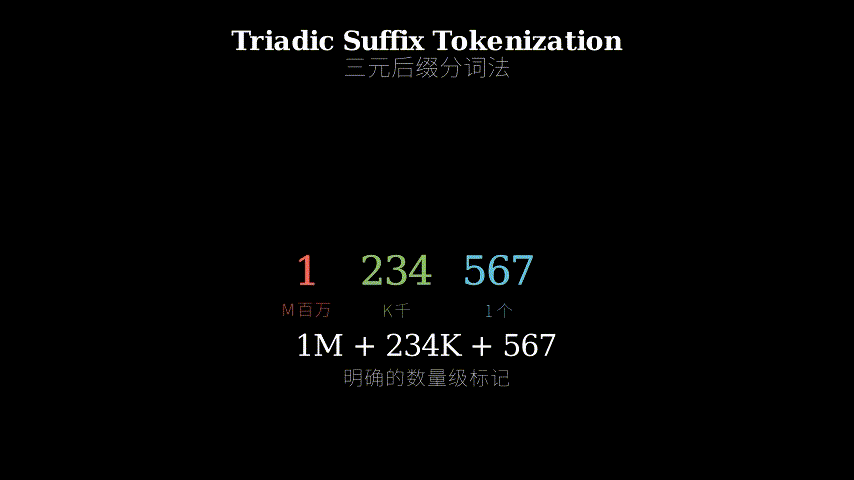
TST operates in three stages. First, it partitions any number into three-digit groups (triads) from the decimal point outward in both directions. For 1234567.89, that’s [1][234][567].[890]. Second, it assigns each triad a magnitude suffix: the integer side gets “thousand”, “million”, “billion” markers; the fractional side gets “thousandth”, “millionth” markers. Third, it either (a) creates fixed vocabulary entries like “234_thousand” covering all 1000 possibilities per magnitude, or (b) uses dynamic suffix tokens like “234” + <MAG_3> that compose at runtime.
The vocabulary-based variant pre-allocates 10,000 tokens (1000 triads × 10 magnitudes) to cover 10^-15 to 10^18. The suffix-marker variant uses ~20 special tokens that attach to any digit sequence. Both preserve exact digits while making magnitude relationships explicit: “234_million” and “567_thousand” carry their relative scale in the token itself, not as an inference problem for the model.
Input: 1234567.89
   |
   v
[Partition into triads from decimal point]
   |
   +---> Integer side: 1 | 234 | 567
   |
   +---> Fractional side: 890
   |
   v
[Assign magnitude markers]
   |
   +---> 1_million | 234_thousand | 567_unit | 890_thousandth
   |
   v
[Tokenize using fixed vocab OR dynamic suffixes]
   |
   v
Output: [TOK_1M] [TOK_234K] [TOK_567] [TOK_890m]
Think of it like a postal address system. Standard tokenizers are like writing “1234 Main Street” but sometimes splitting it as “12|34 Main” and sometimes as “123|4 Main” — the mail carrier (model) has to guess where the house number ends. TST is like requiring “1234 Main St, Block 12, District 3” — every component has an explicit label. The number “234” isn’t just three digits; it’s “234 in the thousands place”, which is a different entity from “234 in the millions place”. The model doesn’t have to infer position from context; position is part of the token’s identity. When you add “234_thousand” + “567_unit”, the magnitude markers tell you exactly how to align them, just like “Block 12” + “Block 13” tells you they’re neighbors.
Key Concepts
-
Magnitude marker: A suffix that explicitly encodes a digit group’s order of magnitude. Instead of letting the model infer that “234” in “1234567” represents 234,000, TST makes it “234_thousand”. This is like the difference between showing someone a ruler with unlabeled tick marks versus one where every centimeter is numbered — the second one doesn’t require you to count from zero every time. For fractional parts, it works in reverse: “890” after a decimal becomes “890_thousandth”, making it clear we’re talking about 0.890, not 890. The key insight: magnitude is a property of position, and position should be explicit, not implicit.
-
Triadic chunking: Grouping digits in threes from the decimal point outward. Why three? Because human numerical notation already uses this (1,234,567), and it aligns with named magnitudes (thousand, million, billion). But the deeper reason: three digits give you 1000 unique patterns, which is small enough to enumerate in a vocabulary but large enough to be efficient. Two digits would require more tokens for the same range; four would bloat the vocabulary. It’s the Goldilocks zone where vocabulary size and coverage balance. Each triad becomes an atomic unit — “234” is one token, not three separate digits fighting for attention in the embedding space.
Framework Shift
Before (standard subword):           After (TST):

Number: 1234567                      Number: 1234567
   |                                    |
   v                                    v
[BPE fragments statistically]        [Deterministic triadic split]
   |                                    |
"12|34|56|7"  OR  "123|456|7"        "1|234|567"
   |                                    |
   v                                    v
[Model infers position]              [Explicit magnitude markers]
   |                                    |
Embedding space:                     Token identities:
[12] [34] [56] [7]                   [1_million] [234_thousand] [567_unit]
  ^    ^    ^   ^                       ^            ^              ^
  |    |    |   |                       |            |              |
Position is implicit                 Position is explicit
From statistical fragmentation to deterministic structure, the core shift is: numbers stop being text and start being annotated quantities.
Expert Assessment
Problem choice: Real gap, not manufactured. LLMs’ arithmetic failures are well-documented, and tokenization is a plausible culprit — it’s the first place structure gets lost. The problem sits at the intersection of representation learning and numerical reasoning, which is timely given the push for LLMs to handle scientific/financial tasks. However, the paper oversells the novelty slightly; digit grouping and magnitude annotation aren’t new ideas (see: scientific notation, financial formatting). The contribution is formalizing this for LLM tokenization.
Method maturity: Clever insight, not brute force. The triadic structure is elegant because it piggybacks on existing human conventions. But there’s a simpler approach being overlooked: just use scientific notation (1.234567e6) and tokenize that. The paper doesn’t compare against this baseline or explain why triads are superior. The two variants (fixed vocab vs. dynamic suffixes) feel underexplored — no analysis of which is better when, or what the trade-offs are beyond vocabulary size.
Experimental integrity: No experiments. The paper explicitly defers validation to future work, which is a massive red flag. Without empirical evidence, we’re evaluating a hypothesis, not a result. The claims about “stable convergence” and “consistent gradient signal” are plausible but unproven. This reads like a position paper or a preprint that escaped too early.
Writing quality: The abstract and method description are crisp, but the paper lacks depth. Section 3 (the method) is only a few paragraphs — it should be twice as long, with worked examples, edge case handling (what about scientific notation inputs? negative numbers? leading zeros?), and complexity analysis. The related work section is missing entirely, which makes it hard to position this against prior art. If the authors rewrote Section 4 (experiments) with even toy results — training a small model on arithmetic tasks with TST vs. standard tokenization — the paper would jump from “interesting idea” to “credible contribution”.
Verdict: weak reject — Promising idea undermined by zero experimental validation; feels like a workshop paper submitted to a main venue.
Takeaways
The core transferable idea: when your model struggles with structured data, check if your tokenization is destroying the structure before the model sees it. This applies beyond numbers — think dates (YYYY-MM-DD), coordinates (lat/lon), chemical formulas (H2O), version numbers (1.2.3). The pattern: if humans use positional or hierarchical conventions to encode meaning, your tokenizer should respect those conventions, not treat them as arbitrary text.
Concretely, practitioners can steal the “annotate magnitude explicitly” principle. If you’re fine-tuning on financial data, don’t let BPE fragment “$1,234,567” inconsistently — preprocess it into magnitude-tagged chunks. If you’re working with scientific measurements, don’t let “1.23e-5” get split randomly — tokenize the mantissa and exponent separately with explicit markers. The vocabulary-based approach (pre-allocating tokens for common patterns) is a useful trick when you have a bounded domain and want deterministic behavior.
The deeper lesson: tokenization is not a solved problem. We’ve been using subword methods designed for natural language on data that isn’t natural language. Numbers, code, structured formats — these need domain-specific tokenization strategies. TST is one example; the field needs more.
论文: 2604.11582 作者: Olga Chetverina 分类: cs.CL, cs.AI, cs.LG
缺口
标准子词分词器(BPE、WordPiece、SentencePiece)把数字当成普通文本流处理。
它们会把”123456”切得乱七八糟——有时是”123|456”,有时是”12|34|56”,取决于训练语料的统计特性。
这破坏了两个关键属性:位置结构(哪个数字在千位?)和小数对齐(小数点相对于每个数字在哪?)。
结果:大模型做不好基础算术,不是因为学不会加法,而是输入表示在模型看到问题之前就把问题搅乱了。
此前的修复方案分两派:(1)字符级分词(保留结构但序列长度爆炸),(2)学习嵌入来在分词后恢复位置(增加参数和训练复杂度)。
两者都在治标不治本。
病根在于分词扔掉了算术依赖的结构。
问题:标准分词器不一致地切分数字
   |
   v
假设:如果确定性分组 + 显式标注量级
   |
   v
方法:三元后缀分词(三位数组 + 量级标记)
   |
   v
证据:[推迟 - 尚无实验]
   |
   v
结论:应能为数值推理提供稳定梯度信号
增量
一句话:这篇论文之前,数字以结构模糊的词元序列进入大模型;之后,它们以量级标注的三元组到达,位置语义直接烘焙进词表。
核心机制
TST分三步运作。
第一步,它把任何数字从小数点向两侧分割成三位数组(三元组)。
对于1234567.89,就是[1][234][567].[890]。
第二步,它给每个三元组分配量级后缀:整数侧得到”千""百万""十亿”标记;小数侧得到”千分之""百万分之”标记。
第三步,它要么(a)创建固定词表条目如”234_千”,覆盖每个量级的全部1000种可能,要么(b)使用动态后缀词元如”234” + <MAG_3>在运行时组合。
基于词表的变体预分配10,000个词元(1000个三元组 × 10个量级)来覆盖10^-15到10^18。
后缀标记变体使用约20个特殊词元附加到任何数字序列。
两者都保留精确数字,同时让量级关系显式化:“234_百万”和”567_千”在词元本身就携带相对尺度,而非作为模型的推理问题。
输入:1234567.89
   |
   v
[从小数点分割成三元组]
   |
   +---> 整数侧:1 | 234 | 567
   |
   +---> 小数侧:890
   |
   v
[分配量级标记]
   |
   +---> 1_百万 | 234_千 | 567_个位 | 890_千分之
   |
   v
[使用固定词表或动态后缀分词]
   |
   v
输出:[TOK_1M] [TOK_234K] [TOK_567] [TOK_890m]
把它想象成邮政地址系统。
标准分词器就像写”主街1234号”但有时切成”12|34号主街”有时切成”123|4号主街”——邮递员(模型)得猜门牌号在哪结束。
TST就像要求”主街1234号,12街区,3区”——每个组件都有显式标签。
数字”234”不只是三个数字;它是”千位上的234”,这跟”百万位上的234”是不同实体。
模型不必从上下文推断位置;位置是词元身份的一部分。
当你加”234_千” + “567_个位”时,量级标记准确告诉你如何对齐它们,就像”12街区” + “13街区”告诉你它们是邻居。
关键概念
- 量级标记:显式编码数字组的数量级的后缀。
与其让模型推断”1234567”中的”234”代表234,000,TST直接写成”234_千”。
这就像给人看一把刻度无标签的尺子和一把每厘米都标号的尺子的区别——后者不需要你每次都从零数起。
对于小数部分,它反向运作:“890”在小数点后变成”890_千分之”,明确表示我们说的是0.890,不是890。
关键洞察:量级是位置的属性,而位置应该显式,不是隐式。
- 三元分组:从小数点向外每三位数字分组。
为什么是三?因为人类数字记法已经这样用(1,234,567),且它与命名量级(千、百万、十亿)对齐。
但更深层原因:三位数给你1000种独特模式,小到能在词表中枚举,大到足够高效。
两位数需要更多词元覆盖同样范围;四位数会让词表膨胀。
这是词表大小和覆盖范围平衡的黄金地带。
每个三元组成为原子单元——“234”是一个词元,不是三个独立数字在嵌入空间争夺注意力。
框架转变
之前(标准子词):                之后(TST):

数字:1234567                      数字:1234567
   |                                  |
   v                                  v
[BPE统计性切分]                    [确定性三元分割]
   |                                  |
"12|34|56|7" 或 "123|456|7"        "1|234|567"
   |                                  |
   v                                  v
[模型推断位置]                     [显式量级标记]
   |                                  |
嵌入空间:                         词元身份:
[12] [34] [56] [7]                 [1_百万] [234_千] [567_个位]
  ^    ^    ^   ^                     ^         ^          ^
  |    |    |   |                     |         |          |
位置是隐式的                       位置是显式的
从统计切分到确定性结构,核心转变是:数字不再是文本,而是标注过的量。
专家评审
选题眼光:真缺口,非人造。
大模型的算术失误有充分记录,分词是合理的罪魁祸首——这是结构丢失的第一站。
问题位于表示学习和数值推理的交叉点,考虑到大模型处理科学/金融任务的推进,这很及时。
但论文略微夸大了新颖性;数字分组和量级标注不是新想法(参见:科学记数法、金融格式)。
贡献在于为大模型分词形式化这一点。
方法成熟度:巧劲,非蛮力。
三元结构优雅,因为它搭了现有人类惯例的便车。
但有个更简单的方法被忽略了:直接用科学记数法(1.234567e6)并分词。
论文没有与这个基线比较,也没解释为什么三元组更优。
两个变体(固定词表vs动态后缀)感觉探索不足——没分析哪个在何时更好,或除了词表大小外有什么权衡。
实验诚意:无实验。
论文明确推迟验证到未来工作,这是巨大红旗。
没有经验证据,我们在评估假设,不是结果。
关于”稳定收敛”和”一致梯度信号”的声称合理但未证明。
这读起来像立场文件或逃逸太早的预印本。
写作功力:摘要和方法描述简洁,但论文缺乏深度。
第3节(方法)只有几段——应该长一倍,带实例、边界情况处理(科学记数法输入怎么办?负数?前导零?)和复杂度分析。
相关工作部分完全缺失,这让人难以将其与前人工作定位。
如果作者重写第4节(实验)哪怕只有玩具结果——在算术任务上用TST vs标准分词训练小模型——论文会从”有趣想法”跃升到”可信贡献”。
判决:弱拒绝——有前景的想法被零实验验证削弱;感觉像投到主会场的研讨会论文。
要点总结
核心可迁移想法:当你的模型在结构化数据上挣扎时,检查你的分词是否在模型看到之前就破坏了结构。
这超越数字——想想日期(YYYY-MM-DD)、坐标(经纬度)、化学式(H2O)、版本号(1.2.3)。
模式:如果人类用位置或层级惯例编码意义,你的分词器应该尊重这些惯例,而非当成任意文本。
具体地,实践者可以偷走”显式标注量级”原则。
如果你在金融数据上微调,别让BPE不一致地切分”$1,234,567”——预处理成量级标记的块。
如果你处理科学测量,别让”1.23e-5”被随机切分——分别用显式标记分词尾数和指数。
基于词表的方法(为常见模式预分配词元)是个有用技巧,当你有有界域且想要确定性行为时。
更深的教训:分词不是已解决的问题。
我们一直在用为自然语言设计的子词方法处理非自然语言的数据。
数字、代码、结构化格式——这些需要领域特定的分词策略。
TST是一个例子;该领域需要更多。