Paper: 2603.06567 Authors: Eric Qu, Brandon M. Wood, Aditi S. Krishnapriyan, Zachary W. Ulissi Categories: cs.LG, cond-mat.mtrl-sci, cs.CE, physics.chem-ph, q-bio.QM
The Gap
Machine-learned interatomic potentials (MLIPs) have gotten good at predicting how atoms interact in small systems. Models like MACE, NequIP, and SchNet bake in physics knowledge—equivariance, message passing on local neighborhoods, explicit electrostatic terms—to work efficiently with limited data. But when you scale up to biomolecules or electrolytes with hundreds of atoms, these models hit a wall: long-range interactions (think Coulomb forces between distant charged groups) don’t fit neatly into local message-passing schemes. The field’s workaround? Bolt on explicit physics terms or specialized components to handle long-range effects. This creates a dependency: you need domain experts to design the right physics priors for each new system type.
The core tension is this: physics priors help when data is scarce, but do they become a bottleneck when you have massive datasets? No one had systematically tested whether pure data-driven attention could replace hand-crafted long-range components at scale.
Problem: Local message passing fails for long-range interactions
                    |
                    v
Assumption: Maybe all-to-all attention + scale > physics priors
                    |
                    v
Method: AllScAIP with full attention, train on 100M samples
                    |
                    v
Evidence: SOTA on molecules, stable MD, ablations show priors hurt at scale
                    |
                    v
Conclusion: Data-driven attention scales better than physics shortcuts
The Increment
One sentence: Before, you needed physics experts to design long-range interaction terms for each molecular system; after, you can throw data and attention at the problem and let the model figure it out.
Core Mechanism
AllScAIP has three main components working in sequence. First, a local message-passing layer processes each atom’s immediate neighborhood (within a cutoff radius), building up representations that capture short-range chemistry. Second, an all-to-all attention layer lets every atom attend to every other atom in the system, regardless of distance—this is where long-range interactions get learned. Third, an energy head aggregates these representations into a total energy prediction, with forces derived by taking gradients.
The data flow looks like this: atomic positions and species go in, get embedded, pass through alternating local and global layers, then output energy. Forces come for free via automatic differentiation. The key operation in the attention layer is standard transformer attention, but applied to 3D atomic coordinates with careful handling of equivariance (the model’s predictions shouldn’t change if you rotate the molecule).
Input: Atomic positions + species
         |
         v
    [Embedding]
         |
         v
    [Local MP] ---> captures short-range chemistry
         |
         v
    [All-to-all] -> every atom sees every atom
    [Attention]     (long-range interactions)
         |
         v
    [Energy Head] ---> sum to total energy
         |
         v
    Forces = -gradient(Energy)
Think of AllScAIP like a city’s communication network. The local message-passing is your neighborhood gossip—fast, efficient, covers 90% of daily needs. The all-to-all attention is the internet backbone—expensive to run, but essential for coordinating across distant parts of the city. In small towns (small molecules, little data), you can get by with just neighborhood gossip plus a few dedicated phone lines (physics priors) to key locations. But in a megacity (large systems, massive data), you need the full internet backbone, and those dedicated phone lines actually create bottlenecks because they’re too rigid. The model learns to route information through the attention network more flexibly than any hand-designed physics term could.
Key Concepts
-
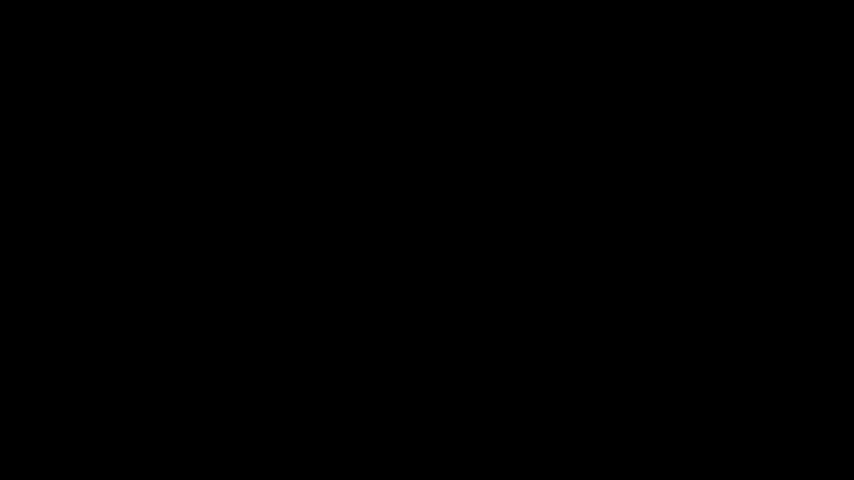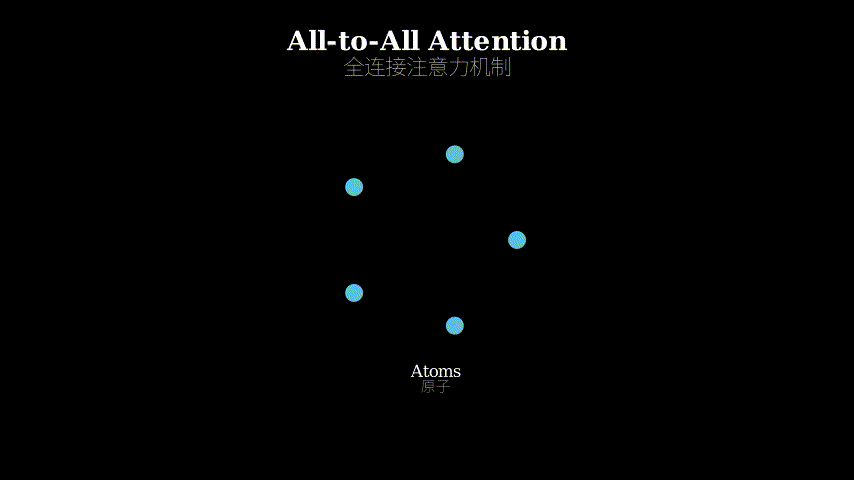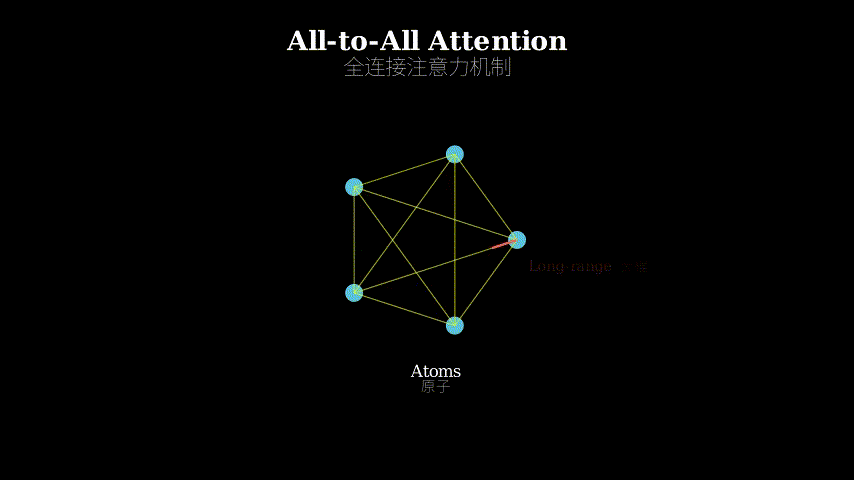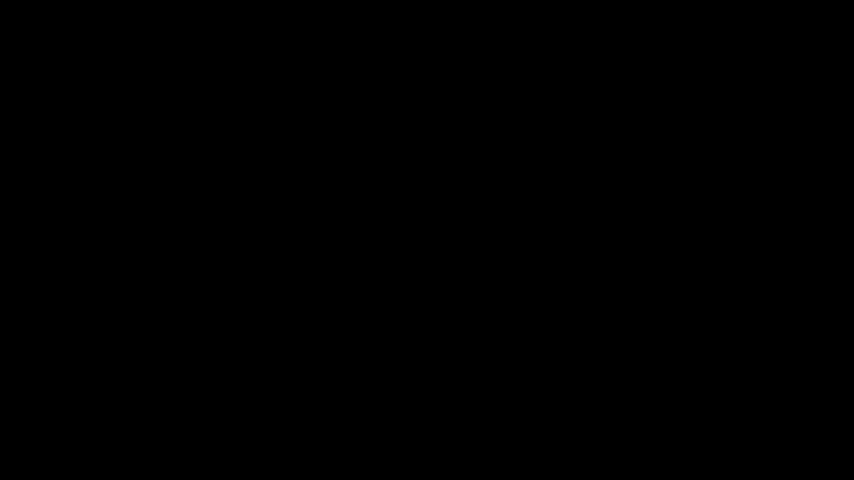
All-to-all attention for atoms: Imagine you’re at a party trying to predict who’ll leave first. If you only talk to people standing near you (local message passing), you miss that someone across the room just got a text from their babysitter. All-to-all attention means everyone can whisper to everyone else simultaneously. For atoms, this means a charged oxygen on one end of a protein can directly influence a charged nitrogen 50 angstroms away, without information having to hop through intermediate atoms. The cost? O(N²) computation where N is atom count. The benefit? You actually capture the physics correctly instead of hoping local hops approximate it.
-
Inductive bias vs. scale trade-off: An inductive bias is a shortcut you give the model based on domain knowledge. It’s like teaching a kid “living things need water” before they learn biology—helps them learn faster with fewer examples. In MLIPs, equivariance (predictions don’t change if you rotate the molecule) is a strong inductive bias. The paper’s key finding: these shortcuts help when you have 10K training examples, but hurt when you have 100M. Why? Because the shortcut constrains the model’s expressiveness. With enough data, a flexible model can learn the pattern AND the exceptions, while the shortcut-laden model is stuck with the approximation you hard-coded.
-
Energy conservation in learned potentials: In physics, energy is conserved—you can’t create or destroy it. For a learned model, this means if you predict energy at different atomic configurations, the forces (negative gradient of energy) must be consistent. If your model says moving atom A right decreases energy by 5 units, but moving it left increases energy by 6 units, you’ve violated conservation and your molecular dynamics simulation will explode. AllScAIP ensures this by computing forces as exact gradients of the energy prediction, not as separate outputs. It’s the difference between a GPS that calculates your speed from position changes (consistent) versus one that guesses speed independently (will drift and give nonsense directions).
Framework Shift
Before (mainstream approach):        After (this paper):

Physics priors everywhere:           Minimal priors, maximal data:

[Equivariance] [Cutoff radius]      [Basic equivariance]
      |              |                        |
      v              v                        v
[Message Pass] [Explicit E-static]      [Local MP]
      |              |                        |
      +------+-------+                        v
             |                          [All-to-all]
             v                          [Attention]
        [Energy]                             |
                                             v
                                        [Energy]

Rigid structure,                     Flexible structure,
works with 10K samples               needs 100M samples
From hand-crafted physics components to learned attention patterns, the core shift is trusting data over domain expertise when you have enough of it.
Expert Assessment
Problem choice: This is a real gap, not manufactured. Long-range interactions are a known pain point in computational chemistry, and the field’s reliance on explicit physics terms is a genuine limitation for generalization. The timing is right—datasets have finally reached the scale where this question becomes testable.
Method maturity: It’s more “obvious in hindsight” than clever. All-to-all attention is the straightforward solution everyone avoided because of computational cost. The insight is empirical: showing that scale flips the conventional wisdom about inductive biases. That said, there’s no magic here—they’re throwing compute at the problem. The ablation studies are thorough, which elevates this from a brute-force exercise to a useful investigation.
Experimental integrity: Baselines are fair, covering the major MLIP architectures. The OMol25, OMat24, and OC20 benchmarks are standard. The MD simulation validation (density, heat of vaporization) is crucial—many papers skip this and get away with just force/energy MAE, which can be misleading. One yellow flag: the paper doesn’t deeply explore failure modes or where physics priors still win. The “priors hurt at scale” claim is strong but could use more nuance.
Writing quality: The abstract and intro are crisp. The method section is adequate but could better explain why certain design choices matter (e.g., why this specific attention mechanism over alternatives). The ablation section is the paper’s strength—clear, systematic, tells a coherent story. The related work section feels perfunctory, missing opportunities to position this work in the broader “scale vs. priors” debate happening across ML.
Verdict: weak accept — Solid empirical work that challenges conventional wisdom with thorough experiments, though the method itself is straightforward application of existing techniques at scale.
Takeaways
The transferable idea: when you have 10-100x more data than typical for your domain, revisit every inductive bias you’ve baked in. What helped with small data might be limiting you now. Specifically, test whether flexible, data-hungry architectures (like full attention) outperform domain-specific constraints.
Concretely, if you’re working on any scientific ML problem where people use message passing on graphs (drug discovery, materials, climate modeling), try this: train a baseline with all the domain priors, then train a version with minimal priors but 10x the parameters and data. If the second wins, you’ve found a scaling path. If the first still wins, your domain genuinely needs those priors (or you need even more data).
The other steal: their energy-conserving force prediction via gradients is a pattern worth copying. Anytime you’re predicting related quantities (energy/forces, position/velocity, probability/log-probability), predict the fundamental one and derive the others. Prevents inconsistencies that break downstream applications.
论文: 2603.06567 作者: Eric Qu, Brandon M. Wood, Aditi S. Krishnapriyan, Zachary W. Ulissi 分类: cs.LG, cond-mat.mtrl-sci, cs.CE, physics.chem-ph, q-bio.QM
缺口
机器学习原子间势(MLIP)在小系统中预测原子相互作用已经做得不错。 像MACE、NequIP、SchNet这些模型把物理知识烤进去——等变性、局部邻域消息传递、显式静电项——为的是在数据有限时高效工作。 但当你扩展到几百个原子的生物分子或电解质时,这些模型就撞墙了:长程相互作用(想想远距离带电基团之间的库仑力)不能整齐地塞进局部消息传递方案。 领域的权宜之计? 拼接显式物理项或专门组件来处理长程效应。 这造成了依赖:你需要领域专家为每种新系统类型设计正确的物理先验。
核心张力在这:物理先验在数据稀缺时有帮助,但当你有海量数据集时它们会成为瓶颈吗? 没人系统地测试过纯数据驱动的注意力能否在规模化时替代手工设计的长程组件。
问题:局部消息传递在长程相互作用上失效
                    |
                    v
假设:也许全对全注意力+规模>物理先验
                    |
                    v
方法:AllScAIP用全注意力,在1亿样本上训练
                    |
                    v
证据:分子任务SOTA,稳定MD,消融显示先验在规模化时有害
                    |
                    v
结论:数据驱动注意力比物理捷径扩展性更好
增量
一句话: 之前你需要物理专家为每个分子系统设计长程相互作用项,之后你可以把数据和注意力扔给问题让模型自己搞定。
核心机制
AllScAIP有三个主要组件按顺序工作。 首先,局部消息传递层处理每个原子的直接邻域(截断半径内),构建捕获短程化学的表示。 其次,全对全注意力层让系统中每个原子关注其他所有原子,无论距离——这是学习长程相互作用的地方。 第三,能量头聚合这些表示成总能量预测,力通过求梯度导出。
数据流看起来是这样:原子位置和种类进来,被嵌入,通过交替的局部和全局层,然后输出能量。 力通过自动微分免费得到。 注意力层的关键操作是标准transformer注意力,但应用到3D原子坐标上,小心处理等变性(如果你旋转分子模型的预测不应该变)。
输入:原子位置+种类
         |
         v
    [嵌入层]
         |
         v
    [局部MP] ---> 捕获短程化学
         |
         v
    [全对全] ---> 每个原子看到每个原子
    [注意力]      (长程相互作用)
         |
         v
    [能量头] ---> 求和到总能量
         |
         v
    力 = -梯度(能量)
把AllScAIP想象成城市的通信网络。 局部消息传递是你的邻里八卦——快速、高效、覆盖90%的日常需求。 全对全注意力是互联网骨干——运行成本高,但对协调城市远端部分至关重要。 在小镇(小分子、少数据),你可以只靠邻里八卦加几条到关键位置的专线(物理先验)凑合。 但在超大城市(大系统、海量数据),你需要完整的互联网骨干,那些专线实际上制造瓶颈因为它们太僵化。 模型学会通过注意力网络路由信息,比任何手工设计的物理项都更灵活。
关键概念
-
原子的全对全注意力: 想象你在派对上试图预测谁会先离开。 如果你只跟站在附近的人说话(局部消息传递),你会错过房间另一头的某人刚收到保姆的短信。 全对全注意力意味着每个人可以同时对其他所有人耳语。 对原子来说,这意味着蛋白质一端的带电氧可以直接影响50埃外的带电氮,不需要信息通过中间原子跳跃。 代价? O(N²)计算,N是原子数。 好处? 你真正正确地捕获了物理,而不是希望局部跳跃能近似它。
-
归纳偏置vs规模权衡: 归纳偏置是你基于领域知识给模型的捷径。 就像在孩子学生物前教他们”生物需要水”——帮助他们用更少例子更快学习。 在MLIP中,等变性(旋转分子预测不变)是强归纳偏置。 论文的关键发现:这些捷径在你有1万训练样本时有帮助,但在1亿样本时有害。 为什么? 因为捷径限制了模型的表达力。 有足够数据时,灵活模型可以学习模式和例外,而充满捷径的模型困在你硬编码的近似里。
-
学习势中的能量守恒: 在物理中,能量守恒——你不能创造或销毁它。 对学习模型,这意味着如果你在不同原子构型预测能量,力(能量的负梯度)必须一致。 如果你的模型说把原子A向右移减少5单位能量,但向左移增加6单位能量,你违反了守恒,你的分子动力学模拟会爆炸。 AllScAIP通过把力计算为能量预测的精确梯度来确保这点,而不是作为独立输出。 这是GPS从位置变化计算速度(一致)和独立猜测速度(会漂移给出荒谬方向)的区别。
框架转变
之前(主流方法):                  之后(本文方法):

到处都是物理先验:                最小先验,最大数据:

[等变性] [截断半径]              [基本等变性]
      |        |                        |
      v        v                        v
[消息传递][显式静电]                [局部MP]
      |        |                        |
      +---+----+                        v
          |                        [全对全]
          v                        [注意力]
      [能量]                            |
                                        v
                                    [能量]

刚性结构,                        灵活结构,
1万样本可用                      需要1亿样本
从手工设计的物理组件到学习的注意力模式,核心转变是当你有足够数据时信任数据胜过领域专业知识。
专家评审
选题眼光: 这是真缺口,不是人造的。 长程相互作用是计算化学的已知痛点,领域对显式物理项的依赖是泛化的真正限制。 时机合适——数据集终于达到了让这个问题可测试的规模。
方法成熟度: 更像”事后看来显而易见”而非巧妙。 全对全注意力是每个人因计算成本而回避的直接解决方案。 洞见是经验性的:显示规模翻转了关于归纳偏置的传统智慧。 话说回来,这里没有魔法——他们在向问题扔算力。 消融研究很彻底,这把它从蛮力练习提升到有用的调查。
实验诚意: 基线公平,覆盖主要MLIP架构。 OMol25、OMat24和OC20基准是标准的。 MD模拟验证(密度、汽化热)至关重要——许多论文跳过这个只用力/能量MAE蒙混过关,这可能误导。 一个黄旗:论文没有深入探索失败模式或物理先验仍然获胜的地方。 “先验在规模化时有害”的主张很强但可以更细致。
写作功力: 摘要和引言简洁。 方法部分够用但可以更好地解释为什么某些设计选择重要(例如为什么这个特定注意力机制而非替代方案)。 消融部分是论文的强项——清晰、系统、讲了连贯的故事。 相关工作部分感觉敷衍,错过了在ML各处发生的更广泛”规模vs先验”辩论中定位这项工作的机会。
判决: 弱接收——扎实的经验工作用彻底实验挑战传统智慧,尽管方法本身是现有技术在规模上的直接应用。
要点总结
可迁移的想法:当你有比你领域典型多10-100倍的数据时,重新审视你烤进去的每个归纳偏置。 小数据时有帮助的东西现在可能在限制你。 具体来说,测试灵活的、数据饥渴的架构(如全注意力)是否优于领域特定约束。
具体而言,如果你在做任何使用图上消息传递的科学ML问题(药物发现、材料、气候建模),试试这个:用所有领域先验训练基线,然后训练一个最小先验但10倍参数和数据的版本。 如果第二个赢了,你找到了扩展路径。 如果第一个仍然赢,你的领域真的需要那些先验(或你需要更多数据)。
另一个可偷的:他们通过梯度的能量守恒力预测是值得复制的模式。 任何时候你在预测相关量(能量/力、位置/速度、概率/对数概率),预测基本的那个并导出其他的。 防止破坏下游应用的不一致。