Paper: 2608.07427 Authors: Bhavika Jalli, Nikhil Korati Prasanna, Jayanta Choudhury Categories: cs.AI, cs.PF
The Gap
Two research lines have been running in parallel and mostly ignoring each other.
The first is “LLMs for time series.” Since roughly 2023 people have been serializing numeric sequences into text and prompting a language model — PromptCast-style forecasting, LLMTime, Time-LLM, and the whole family of “just write the numbers in the prompt” approaches. These work surprisingly well, and they have one structural flaw nobody wants to talk about: a floating-point number is a catastrophically expensive thing to tokenize. 0.038271 is not one token. Depending on the tokenizer it’s four, five, sometimes six. Multiply by 96 timesteps, multiply by 24 KPIs, and a single 15-minute window from one cell site becomes tens of thousands of tokens. The paper’s sharpest observation is that this isn’t just expensive — at 24 KPIs it’s infeasible, blowing past the 128K context window that most production models ship with. You either truncate your data or you don’t run.
The second line is energy accounting for inference — the systems-side literature establishing that inference, not training, dominates operational energy at scale, and that inference energy scales close to linearly with input token count. That’s a well-established relationship but it has mostly lived in performance papers, not in modeling papers.
The gap this paper occupies is the intersection: nobody had measured what happens to joules when you change the input modality for numeric data, and nobody had checked whether the cheap modality is also the accurate one. The classical baselines in this domain (ARIMA, LSTM) sidestep the token problem entirely but can’t produce natural-language rationales, and the text-LLM approach that can produce rationales is drowning in tokens.
PROBLEM
[ inference joules ~ input token count ]
[ 24 KPIs x 96 timesteps of floats = 10Ks of tokens ]
[ exceeds 128K context = truncate or fail ]
        |
        v
ASSUMPTION
[ what a model needs from a KPI window is ]
[ shape / trend / spike -- not 7-digit precision ]
        |
        v
METHOD
[ render window as a 2D plot ] --> [ VLM patch encoder ]
[ token budget becomes fixed. decoupled from precision ]
        |
        v
EVIDENCE
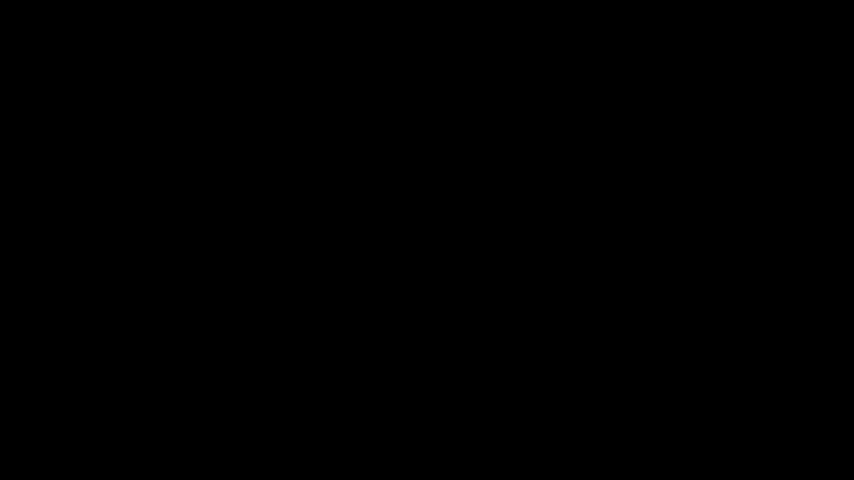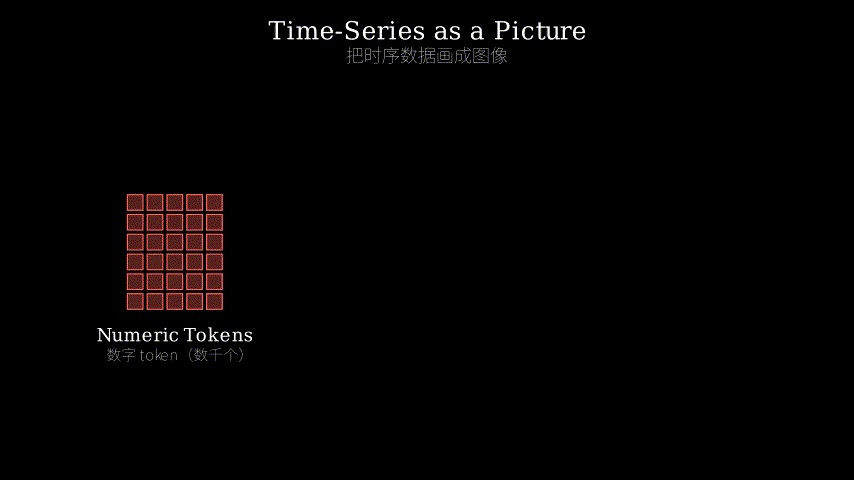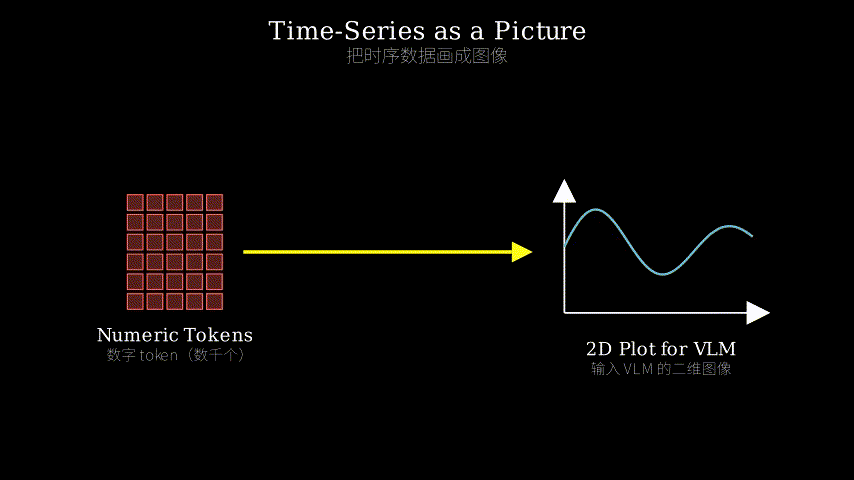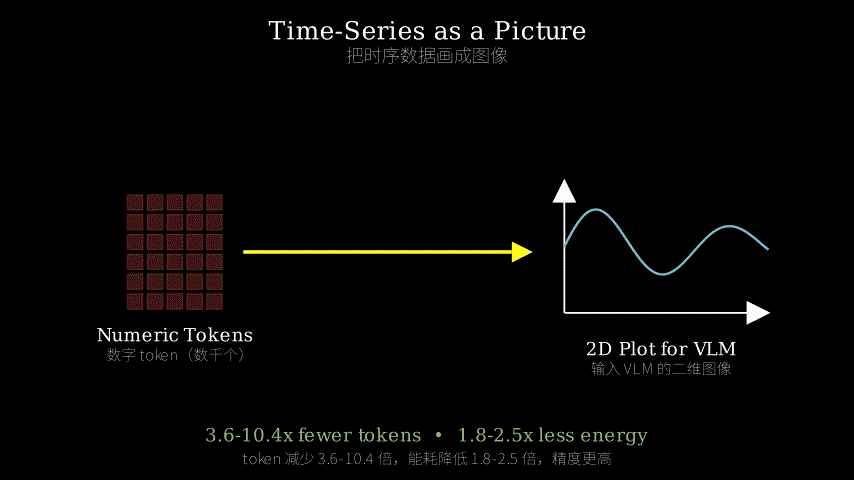
[ 3.6x - 10.4x fewer input tokens across 3 VLMs ]
[ 1.8x - 2.5x measured joules per inference ]
[ tuned Llama-3.2-90B-V: +220.7% precision vs text-only ]
[ vs LSTM / ARIMA: +144% on telecom anomaly detection ]
[ Pixtral-12B: 20.6x better J/F1 at mean F1 = 0.82 ]
        |
        v
CONCLUSION
[ for numeric time series pixels are a carrier that is ]
[ both cheaper and more accurate than digits ]
The Increment
One sentence: Before this paper, “plot your time series and show it to a VLM” was a curiosity with a few accuracy results attached; after it, there’s a measured energy ledger behind it plus a hard feasibility argument (past ~24 channels, the text path simply doesn’t fit in a production context window).
Core Mechanism
The pipeline itself is unglamorous, which is fine — the claim is empirical, not architectural. Raw KPI counters stream off 4G/5G cell sites on 15-minute intervals. Instead of serializing the multivariate window into a text block, a renderer draws it: axes, gridlines, one panel or overlaid traces per KPI, saved as a single image. That image goes through the VLM’s vision encoder, which chops it into a fixed grid of patches and emits a fixed number of visual tokens — and this is the whole trick. The patch count depends on image resolution, not on how many data points you drew or how many decimal places each one had. You can draw 96 timesteps or 960; the token bill barely moves.
Those visual tokens get projected into the language model’s embedding space and prepended to a text prompt asking for an anomaly verdict. The decoder answers in natural language, so you keep the thing that made LLMs attractive here in the first place — a rationale, not just a label. For the headline telecom result the authors fine-tune Llama-3.2-90B-Vision on labeled anomalies; the abstract doesn’t specify the adapter scheme, but a LoRA-style tuning of the projector and late layers is the obvious and cheap choice. Energy is measured, not estimated, presumably via GPU power sampling per inference, and folded into a composite metric: joules per unit F1.
The accuracy result is the interesting part and it needs a mechanism story, which the abstract only gestures at. My read: a plot performs an aggressive, lossy, task-aligned compression. It throws away the fifth decimal place — which was never load-bearing for “is this cell degraded?” — and preserves shape, slope, periodicity, and co-movement across KPIs in a spatial layout that a pretrained vision encoder already has good features for. Digit sequences give the model everything and no inductive bias; plots give it less and a better prior.
  4G/5G cell sites (200 cells per 15-min interval)
        |
        v
  +------------------------------+
  | KPI window collector         |  24 KPIs x N steps
  | floats like 0.038271         |
  +------------------------------+
        |
        +---------------------------+
        |                           |
        v                           v
  TEXT PATH (baseline)        VISION PATH (this paper)
  +--------------------+      +------------------------+
  | BPE tokenizer      |      | plot renderer          |
  | one float -> 4..6  |      | axes. gridlines.       |
  | tokens             |      | panel layout. DPI      |
  +--------------------+      +------------------------+
        |                           |
        v                           v
  ~10K - 100K+ tokens         1 image = fixed patch set
  (24 KPIs > 128K limit)      (~1K - 3K visual tokens)
        |                           |
        v                           v
  [ truncate or fail ]        +------------------------+
        |                     | ViT patch encoder      |
        |                     +------------------------+
        |                           |
        |                           v
        |                     +------------------------+
        |                     | projector -> LLM dim   |
        |                     +------------------------+
        |                           |
        +-----------+---------------+
                    v
        +--------------------------------+
        | LLM decoder                    |
        | + fine-tune on telecom labels   |
        +--------------------------------+
                    |
                    v
        [ anomaly verdict + rationale ]
                    |
                    v
        GPU power sampling -> joules / inference
                             -> J per F1
The metaphor: this is a cardiologist reading an ECG, and the paper is an argument about fax machines versus phone calls.
You have a patient’s trace and a specialist in another city. Option A — the text path — is to read the voltage samples aloud down the phone: “zero point zero two three one, zero point zero two four four, zero point zero two five one…” Every digit costs breath. Sixty seconds of ECG at 500 Hz will take you all afternoon, and the specialist’s working memory (the context window) gives out long before you finish, so you skip most of it and hope the interesting part survived. Now add eleven more leads. The call becomes impossible, not merely tedious.
Option B — the vision path — is to fax the strip. The paper cost of a fax page is fixed. One lead or twelve, thirty seconds or five minutes: still one page. That’s the patch encoder. And the specialist reads it faster and better, because a decade of residency trained her eyes on exactly this kind of squiggle — that’s the pretrained vision encoder’s inductive bias. She loses the exact millivolt values in the fax’s grain, but she never needed them; she needed the ST elevation, the rhythm, the shape. The fine-tuning step is her first month at this hospital, learning that this machine’s paper runs a little fast and this population skews a certain way. And the joules-per-F1 metric is the hospital administrator finally asking what each of these two workflows costs per correct diagnosis, a question nobody in the building had been tracking.
The metaphor also tells you where the paper is vulnerable. If the diagnosis genuinely depended on precise millivolts, the fax loses. And a cardiologist is an expensive reader — sometimes a $50 automated rhythm detector is the right call, which is exactly the baseline question I’ll come back to below.
Key Concepts
-
The token cost of a number: language model tokenizers were built for prose, and they chop numbers into whatever sub-strings happened to be frequent in text.
0.038271might split as0.038271— five tokens for one measurement, and the split isn’t even consistent across similar values. So the model pays five times to receive one number, and then has to reassemble it. Compare a photograph: a 1120x1120 image at 14-pixel patches is a fixed ~6400 patches whether it shows a blank wall or a thousand-point chart. Text token cost scales with your data; visual token cost is a flat rate. That asymmetry is the entire paper. -
Joules per F1: instead of reporting accuracy and efficiency in separate tables, divide. If system A hits F1 = 0.82 for 100 J per inference and system B hits F1 = 0.80 for 900 J, A’s J/F1 is roughly 122 versus B’s 1125 — a 9x efficiency gap that neither an accuracy table nor a latency table alone would show. It’s a crude ratio (it implicitly says a 1% F1 gain is worth exactly 1% more energy, which is rarely true), but it forces energy into the same sentence as quality, which is the point.
-
Task-aligned lossy compression: the counterintuitive result here is that throwing information away *improved accuracy. That only makes sense if the discarded information was noise relative to the task. A plot discards precision and preserves geometry. For “did this cell degrade?”, geometry is the signal. This is a general design principle: pick a representation whose losses align with your task’s irrelevancies, and you get compression for free rather than paying for it in accuracy.
Framework Shift
Before (mainstream)                 After (this paper)

  numbers                             numbers
     |                                   |
     v                                   v
[ serialize to digits ]           [ render to pixels ]
     |                                   |
     v                                   v
 token cost =                       token cost =
   precision                          image size
   x length                             (constant)
   x #channels                        |
     |                                 v
     v                            [ fixed patch budget ]
[ grows without bound ]                |
     |                                 v
     v                            fits at any scale.
[ hits 128K wall ]                shape preserved.
     |                            prior of a pretrained
     v                            vision encoder applies
[ truncate. accuracy               |
  falls. joules stay high ]        v
                                  [ fewer joules AND
                                    higher precision ]
From digits to pixels, the core shift is that input cost stops scaling with data volume and becomes a fixed rate you choose in advance — and the compression happens to align with what the task actually needs.
Expert Assessment
Problem choice: The gap is real, but it’s narrower than the abstract implies. The token-inefficiency-of-floats problem is genuine and underappreciated, and the context-window feasibility argument at 24 KPIs is the paper’s most defensible contribution — a capability wall is more persuasive than a cost saving. The energy framing is where I’d push back. “Over 90% of AI operational energy” is a widely repeated figure with soft provenance, and the flagship savings number deserves a unit conversion: 7.2 MJ/day is 2 kWh/day. That’s a household refrigerator. Stated as megajoules it sounds like an infrastructure win; stated as kilowatt-hours it’s about twenty cents of electricity per site per day. The honest version of this paper’s pitch is “we made an infeasible workload feasible, and it also happens to be cheaper,” not “we saved the planet at the telecom edge.”
Method maturity: This is plumbing, and the paper doesn’t pretend otherwise. Rendering time series as images for VLMs already exists in the literature; the increment is the energy ledger and the telecom domain. That’s a legitimate contribution but it’s an empirical-study contribution, and it should be positioned as one. The bigger issue is a simpler approach hiding in plain sight: patch-based numeric tokenizers. PatchTST and Chronos-style models already compress numeric sequences into a small number of learned tokens, achieving the same decoupling of token count from series length *without the detour through a rasterizer. If your goal is fewer tokens per KPI window, a purpose-built numeric tokenizer is the direct route and pixels are the scenic one. The paper’s implicit answer is presumably “but then you lose the pretrained VLM and its natural-language output,” which is a fair answer — I’d just want it argued rather than left unstated.
Experimental integrity: This is where I’d spend my review. “+220.7% precision over its text-only counterpart” is the number that worries me. A 3.2x precision gain from changing input format alone is not a plausible modality effect; it’s the signature of a broken baseline. Two likely mechanisms: (a) the VLM was fine-tuned and the text-only model wasn’t, in which case the comparison measures fine-tuning, not modality; and (b) at 24 KPIs the text model *had to be truncated to fit the context window, so it was answering with a fraction of the data. Both are noted in the abstract, which makes the comparison self-undermining — if the text path is infeasible, then say it’s infeasible and stop there. Reporting a percentage gain against a crippled baseline converts a clean feasibility argument into a suspicious accuracy claim. Similarly, “20.6x improvement in J/F1” needs its denominator spelled out: against text-only Pixtral? Against LSTM? Against the truncated variant?
And the energy comparison has a conspicuous hole. The accuracy comparison against LSTM and ARIMA (+144%) apparently doesn’t come with an energy comparison — but a small LSTM runs anomaly detection for microjoules on a CPU, three to four orders of magnitude below a 90B VLM. If joules are a first-class constraint, the most energy-efficient system in the paper is almost certainly the LSTM baseline, and the paper’s own metric would say so. The defensible claim is conditional: given that you want an LLM in this loop for its reasoning and explanations, images are the cheap way to feed it. That framing survives scrutiny. The unconditional “energy-efficient modality” framing doesn’t.
Writing quality: The abstract is a wall of ratios — nine numeric claims in eleven sentences — and ratio density is usually inversely correlated with methodological detail. Two sections almost certainly need more room than they got. First, the energy measurement methodology: what instrument, sampled at what rate, batch size, prefill versus decode attribution, whether idle power was subtracted. Every joule claim rests on this and it’s the easiest thing in the paper to get wrong. Second, plot rendering as a design space. Axis scaling, DPI, gridline density, color mapping, and panel layout are now hyperparameters that directly affect accuracy, and an ablation over them would be the paper’s most reusable asset. If I could force one rewrite, it would be replacing the percentage-gain claims with a clean fine-tuned-versus-fine-tuned comparison at a channel count where both modalities fit.
Verdict: borderline — the feasibility argument and the measured energy numbers are worth publishing, but the headline accuracy gains rest on baselines that appear structurally disadvantaged, and the energy framing omits the small-model comparison that its own metric demands.
Takeaways
Concrete things worth stealing:
Fixed-cost encoders as a compression channel. The transferable insight isn’t “plots are good.” It’s that any modality with a fixed-size encoder — images, audio, learned patch tokenizers — decouples prompt cost from data volume. If you’re stuffing oversized structured input into a context window (logs, tabular data, dependency graphs, traces), ask whether there’s a fixed-rate encoder that can carry it. The flat-rate-versus-metered distinction is the reusable frame.
Lead with feasibility, not cost. The strongest sentence in this paper is that at 24 KPIs the text representation doesn’t fit, full stop. Cost savings invite haggling; capability walls don’t. If you’re pitching an efficiency change internally, find the threshold where the old approach stops working at all and lead with that.
Put joules in your eval table. Adopt the joules-per-quality ratio even if the exact ratio is crude. Once energy sits in the same table as F1, architecture conversations change — and note that this paper’s own metric would have flagged the LSTM question if applied consistently. A metric that only ever flatters you isn’t being applied honestly.
Rendering is now prompt engineering. If you go down this path, your matplotlib defaults are model hyperparameters. Fix DPI, axis normalization, gridlines, and color mapping explicitly, version them, and ablate them. Silent renderer changes will look like model drift and you will lose a week finding it.
Always price the small model. The discipline this paper lacks is the one to keep: before claiming an efficiency win for a large model, compute joules-per-quality for the boring 5M-parameter alternative. Sometimes the answer is that you don’t need the large model at all, and it’s better to learn that from your own table than from a reviewer’s.
论文: 2608.07427 作者: Bhavika Jalli, Nikhil Korati Prasanna, Jayanta Choudhury 分类: cs.AI, cs.PF
缺口
有两条研究脉络一直在并行推进,却基本互不搭理。
第一条是”用 LLM 做时间序列”。
从 2023 年前后开始,大家把数值序列序列化成文本塞进 prompt——PromptCast 式的预测、LLMTime、Time-LLM,以及一整家族”直接把数字写进提示词”的做法。
它们效果意外地不错,但有一个没人愿意细说的结构性缺陷:浮点数是 tokenizer 的噩梦。
0.038271 不是一个 token。
取决于分词器,它是四个、五个、有时六个。
乘以 96 个时间步,再乘以 24 个 KPI,一个基站 15 分钟窗口就膨胀成几万个 token。
这篇论文最锋利的观察在于:这不只是贵,在 24 个 KPI 的规模下它是不可行——直接撞穿了大多数生产级模型 128K 的上下文上限。
你要么截断数据,要么根本跑不起来。
第二条是推理能耗核算。 系统侧的文献已经确立:在规模化部署下主导运营能耗的是推理而非训练,而推理能耗与输入 token 数近似线性相关。 这是个成立得挺牢的关系,但它主要活在性能论文里,没进建模论文。
这篇论文占的缺口正是两者的交叉点:此前没人测过——当你把数值数据的输入模态换掉,焦耳会怎么变;也没人验证过便宜的那条路是不是同时也是更准的那条。 这个领域的经典基线(ARIMA、LSTM)完全绕开了 token 问题,但给不出自然语言的解释;能给解释的文本 LLM 路线,则被 token 淹死了。
PROBLEM
[ inference joules ~ input token count ]
[ 24 KPIs x 96 steps of floats = 10Ks of tokens ]
[ exceeds 128K context = truncate or fail ]
        |
        v
ASSUMPTION
[ model needs shape / trend / spike ]
[ NOT 7 digits of precision ]
        |
        v
METHOD
[ render window as 2D plot ] --> [ VLM patch encoder ]
[ token budget fixed. decoupled from data volume ]
        |
        v
EVIDENCE
[ 3.6x - 10.4x fewer input tokens. 3 VLMs ]
[ 1.8x - 2.5x measured joules per inference ]
[ tuned Llama-3.2-90B-V: +220.7% precision vs text ]
[ vs LSTM / ARIMA: +144% on telecom anomaly ]
[ Pixtral-12B: 20.6x better J/F1 at F1 = 0.82 ]
        |
        v
CONCLUSION
[ pixels carry numeric series both cheaper ]
[ and more accurately than digits do ]
增量
一句话:这篇之前,“把时间序列画成图给 VLM 看”是个附带几个精度结果的小把戏;这篇之后,它背后有了一份实测的能耗账本,外加一条硬邦邦的可行性论证——超过约 24 个通道,文本路线根本进不了生产级上下文窗口。
核心机制
管线本身不华丽,这没关系——本文的主张是经验性的,不是架构性的。 原始 KPI 计数器以 15 分钟粒度从 4G/5G 基站流出。 不做文本序列化,而是交给渲染器画图:坐标轴、网格线、每个 KPI 一个子图或叠在一起,存成一张图像。 图像走 VLM 的视觉编码器,被切成固定网格的 patch,吐出固定数量的视觉 token——诀窍全在这里。 patch 数量取决于图像分辨率,不取决于你画了多少个点、每个点有几位小数。 你画 96 步还是 960 步,token 账单几乎不动。
这些视觉 token 被投影进语言模型的嵌入空间,拼在一段”请判断是否异常”的文本提示前面。 解码器用自然语言作答,所以最初让人想用 LLM 的那个东西被保留了下来——不是一个标签,而是一段理由。 电信那个头条结果里,作者在带标注的异常数据上微调了 Llama-3.2-90B-Vision;摘要没说适配方案,但对投影层和后段层做 LoRA 式微调是最显然也最便宜的选择。 能耗是实测的而非估算的,大概是逐次推理采样 GPU 功率,最后折进一个复合指标:每单位 F1 消耗多少焦耳。
精度提升才是有意思的部分,而摘要只是点了一下。 我的读法是:画图执行的是一次激进的、有损的、与任务对齐的压缩。 它扔掉第五位小数——这位小数对”这个小区是否劣化”从来不承重;同时它把形状、斜率、周期性、以及多个 KPI 之间的同步变化保留在一个空间布局里,而预训练视觉编码器对这类布局早就有好特征了。 数字序列给模型一切信息,却不给任何归纳偏置;图给的信息更少,但先验更好。
  4G/5G cell sites (200 cells / 15-min interval)
        |
        v
  +------------------------------+
  | KPI window collector         |  24 KPIs x N steps
  | floats like 0.038271         |
  +------------------------------+
        |
        +---------------------------+
        |                           |
        v                           v
  TEXT PATH (baseline)        VISION PATH (paper)
  +--------------------+      +------------------------+
  | BPE tokenizer      |      | plot renderer          |
  | one float -> 4..6  |      | axes. gridlines.       |
  | tokens             |      | layout. DPI            |
  +--------------------+      +------------------------+
        |                           |
        v                           v
  ~10K - 100K+ tokens         1 image = fixed patches
  (24 KPIs > 128K)            (~1K - 3K visual tokens)
        |                           |
        v                           v
  [ truncate or fail ]        +------------------------+
        |                     | ViT patch encoder      |
        |                     +------------------------+
        |                           |
        |                           v
        |                     +------------------------+
        |                     | projector -> LLM dim   |
        |                     +------------------------+
        |                           |
        +-----------+---------------+
                    v
        +--------------------------------+
        | LLM decoder + fine-tune        |
        +--------------------------------+
                    |
                    v
        [ anomaly verdict + rationale ]
                    |
                    v
        power sampling -> joules -> J per F1
核喻:这是一位心脏科医生在读心电图,而这篇论文是一场关于”传真机 vs 打电话”的争论。
你手上有一份病人的心电波形,专家在另一个城市。 方案 A——文本路线——是把电压采样值一个个念到电话里:“零点零二三一,零点零二四四,零点零二五一……” 每一位数字都要耗一口气。 500 Hz 采样的六十秒心电图,你得念一整个下午;而专家的工作记忆(上下文窗口)远在你念完之前就崩了,于是你跳过大部分内容,指望关键那段刚好被留下来。 现在再加十一个导联。 这通电话不再只是啰嗦,而是不可能。
方案 B——视觉路线——是把纸带传真过去。 一页传真的纸张成本是固定的。 一个导联还是十二个,三十秒还是五分钟:都是一页。 这就是 patch 编码器。 而且专家读得更快也更准,因为十年住院医训练把她的眼睛专门喂给了这类曲线——这就是预训练视觉编码器的归纳偏置。 她在传真的颗粒里丢掉了精确的毫伏值,但她本来也不需要;她需要的是 ST 段抬高、节律、形状。 微调那一步,是她在这家医院的第一个月:搞清楚这台机器走纸偏快、这个人群的基线偏在哪。 而”每 F1 多少焦耳”这个指标,是医院管理者终于开始问:这两套流程每做出一个正确诊断各花多少钱——一个整栋楼里此前没人记账的问题。
这个核喻也顺手指出了论文的软肋。 如果诊断真的依赖精确毫伏值,传真就输了。 另外,心脏科医生是很贵的读者——有时候一台 50 美元的自动节律检测仪才是对的选择,这正是下面要回到的基线问题。
关键概念
-
一个数字的 token 成本:语言模型的分词器是为散文造的,它按文本里的高频子串切数字。
0.038271可能被切成0.038271——一个测量值五个 token,而且相似数值的切法还不一致。 模型为收到一个数付了五次费,然后还得自己把它拼回来。 对比图像:1120x1120、patch 边长 14,就是固定的约 6400 个 patch,不管画的是一面白墙还是一千个数据点的曲线。 文本 token 成本随数据量增长;视觉 token 成本是包月。 这个不对称就是整篇论文。 -
每 F1 焦耳数(J/F1):不要把精度和效率放在两张表里,直接相除。 系统 A 用 100 J 拿到 F1 = 0.82,系统 B 用 900 J 拿到 0.80,那么 A 的 J/F1 约 122,B 约 1125——9 倍的效率差,单看精度表或延迟表都看不出来。 这个比值很粗糙(它隐含地认为 1% 的 F1 提升正好值 1% 的额外能耗,而这很少成立),但它把能耗逼进了和质量同一个句子里,这才是重点。
-
与任务对齐的有损压缩:这里反直觉的结果是,扔掉信息反而提高了精度。 这只有在被扔掉的信息相对该任务是噪声时才讲得通。 画图丢掉精度、保留几何。 对”这个小区劣化了吗”来说,几何就是信号。 这是个通用设计原则:挑一种”损失方向”与任务”无关维度”对齐的表示,压缩就是白得的,而不是用精度换来的。
框架转变
Before (mainstream)                 After (this paper)

  numbers                             numbers
     |                                   |
     v                                   v
[ serialize to digits ]           [ render to pixels ]
     |                                   |
     v                                   v
 token cost =                       token cost =
   precision                          image size
   x length                             (constant)
   x #channels                        |
     |                                 v
     v                            [ fixed patch budget ]
[ grows without bound ]                |
     |                                 v
     v                            fits at any scale.
[ hits 128K wall ]                shape preserved.
     |                            pretrained vision
     v                            prior applies
[ truncate. accuracy               |
  down. joules up ]                v
                                  [ fewer joules AND
                                    higher precision ]
一句话:从数字到像素,核心转变是输入成本不再随数据量增长,而变成一个你预先选定的固定费率——并且这次压缩恰好压掉了任务不需要的东西。
专家评审
选题眼光:缺口是真的,但比摘要暗示的要窄。 浮点数的 token 低效是个真问题且被低估了,而 24 个 KPI 处的上下文可行性论证是本文最站得住的贡献——能力天花板比成本节省更有说服力。 能耗那层包装是我要顶一下的地方。 “超过 90% 的 AI 运营能耗”是个被反复引用但出处偏软的数字,而旗舰节能数据需要做一次单位换算:7.2 MJ/天 = 2 kWh/天。 那是一台家用冰箱。 写成兆焦,听起来像基础设施级别的胜利;写成千瓦时,就是每站每天约两毛钱电费。 这篇论文诚实的卖点应该是”我们把一个不可行的工作负载变可行了,顺带还更省”,而不是”我们在电信边缘拯救了地球”。
方法成熟度:这是管道工程,论文也没假装不是。 把时间序列渲染成图喂 VLM 在文献里已经有了;增量是能耗账本和电信场景。 这是正当贡献,但它是实证研究型贡献,就该这么定位。 更大的问题是一个明摆着的更简单方案:基于 patch 的数值 tokenizer。 PatchTST、Chronos 那一类模型已经把数值序列压成很少的可学 token,实现了同样的”token 数与序列长度解耦”,而且不用绕道栅格化。 如果目标只是”每个 KPI 窗口少用 token”,专用数值 tokenizer 是直路,像素是风景路线。 论文隐含的回答大概是”但那样你就丢了预训练 VLM 和它的自然语言输出”——这是个成立的回答,我只是希望它被论证,而不是留白。
实验诚意:这是我会花掉大半评审时间的地方。 “精度比纯文本对照高 220.7%“是让我担心的那个数。 仅靠改输入格式带来 3.2 倍的 precision 提升,不是一个可信的模态效应量级,而是基线坏掉的特征信号。 两个可能机制:(a) VLM 被微调了而文本模型没有,那这个对比测的是微调而不是模态;(b) 24 个 KPI 下文本模型必须被截断才能塞进上下文,于是它是在只看到一部分数据的情况下作答。 两点摘要里都提到了,这让对比自我瓦解——如果文本路线不可行,那就说它不可行,到此为止。 拿一个被削残的基线去报百分比增益,把一个干净的可行性论证变成了一个可疑的精度声明。 同理,“J/F1 提升 20.6 倍”需要写清分母:对比纯文本 Pixtral?对比 LSTM?对比截断版?
而能耗对比有个显眼的空洞。 对 LSTM 和 ARIMA 的精度对比(+144%)似乎没有配套的能耗对比——可一个小 LSTM 在 CPU 上做异常检测是微焦级别,比 90B VLM 低三到四个数量级。 如果焦耳真是一等约束,那论文里最省能的系统几乎肯定是 LSTM 基线,而论文自己的指标会这么说。 站得住的主张是有条件的:在你确实需要一个 LLM 在环里提供推理与解释的前提下,图像是喂它的便宜方式。 这个框架经得起推敲。 无条件的”能效模态”框架经不起。
写作功力:摘要是一堵比值砌成的墙——十一句话里九个数字声明,而比值密度通常与方法学细节负相关。 两节几乎肯定该比现在长。 第一是能耗测量方法:什么仪器、多高采样率、batch size 多少、prefill 与 decode 如何归因、空载功率有没有扣。 每一个焦耳声明都压在这上面,而这也是全文最容易做错的东西。 第二是”画图”作为一个设计空间。 坐标轴缩放、DPI、网格线密度、配色、子图布局,现在都是直接影响精度的超参数,一组对它们的消融会是本文最可复用的资产。 如果只能强制重写一处,我会把百分比增益换成一次”微调 vs 微调”的干净对比,通道数取在两种模态都能塞进上下文的位置。
判决:临界 — 可行性论证和实测能耗数据值得发表,但头条精度增益建立在结构性劣势的基线上,而能耗叙事又漏掉了它自己的指标本该要求的小模型对照。
要点总结
值得偷走的具体东西:
把固定成本编码器当压缩通道用。 可迁移的洞见不是”画图好”,而是:任何带固定尺寸编码器的模态——图像、音频、可学 patch tokenizer——都能把 prompt 成本与数据量解耦。 如果你正在往上下文窗口里硬塞超大的结构化输入(日志、表格、依赖图、trace),先问一句有没有一个固定费率的编码器能扛。 “包月 vs 按量”这个区分才是可复用的框架。
先讲可行性,再讲成本。 本文最强的一句话是:24 个 KPI 时文本表示装不进去,句号。 成本节省会引来讨价还价,能力天花板不会。 如果你在公司内部推一个效率改造,去找到”旧方案彻底不工作”的那个阈值,然后从它开讲。
把焦耳写进评测表。 即便比值粗糙,也采用”每单位质量多少能耗”。 能耗一旦和 F1 坐进同一张表,架构讨论就会变——顺便注意,这篇论文自己的指标如果被一致地应用,本该把 LSTM 那个问题标出来。 一个只会替你说好话的指标,说明它没被诚实地用。
渲染现在属于 prompt engineering。 如果你走这条路,你的 matplotlib 默认值就是模型超参数。 把 DPI、坐标轴归一化、网格线、配色显式固定下来,纳入版本管理,并做消融。 渲染器的无声变更看起来会像模型漂移,而你会花掉一周才找到它。
永远给小模型报个价。 这篇论文缺的那份纪律,恰恰是最该留下的:在宣称大模型的效率胜利之前,先算一遍那个无聊的 5M 参数替代品的”每单位质量能耗”。 有时答案是你根本不需要大模型——而这件事,从自己表里学到比从评审意见里学到要好。