Paper: 2604.25905 Authors: Christopher Potts, Moritz Sudhof Categories: cs.CL
The Gap
Existing AI evaluation research measures model performance in isolation—accuracy on benchmarks, response quality, task completion rates. The implicit assumption: better models automatically deliver better outcomes for users. But this ignores a critical variable: user skill. We know from every other technology that expertise shapes outcomes (expert photographers get more from cameras, skilled drivers extract more from cars), yet AI research treats users as uniform consumers of model outputs.
The specific gap: no one has systematically measured how user fluency with AI changes what tasks they attempt, how they interact, what failures they encounter, and what outcomes they achieve. Without this, we’re optimizing models in the dark, not knowing whether friction comes from model limitations or user behavior.
Problem: AI evaluation ignores user skill variance
   |
   v
Assumption: Model quality = User outcome
   |
   v
Method: Annotate 27K real conversations by user fluency
        + Measure task complexity, interaction patterns, failure types
   |
   v
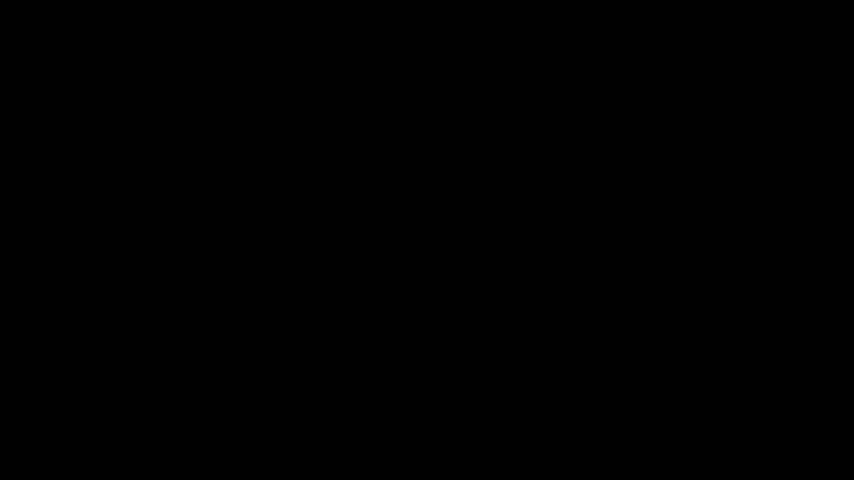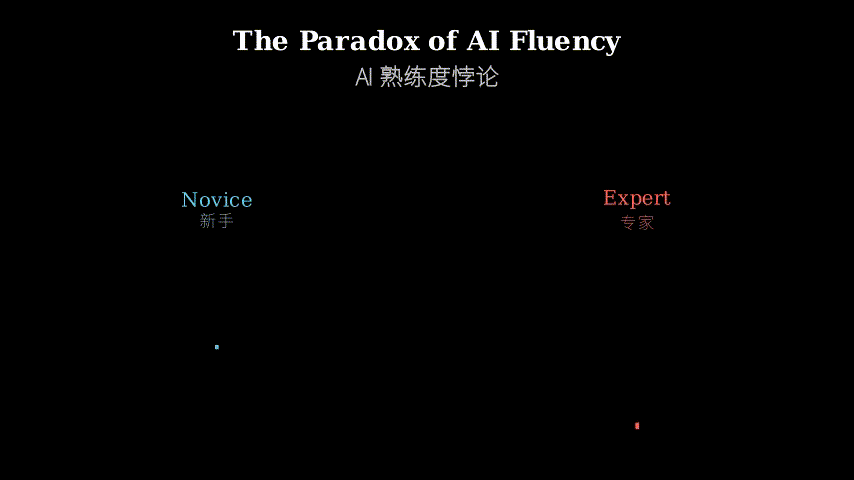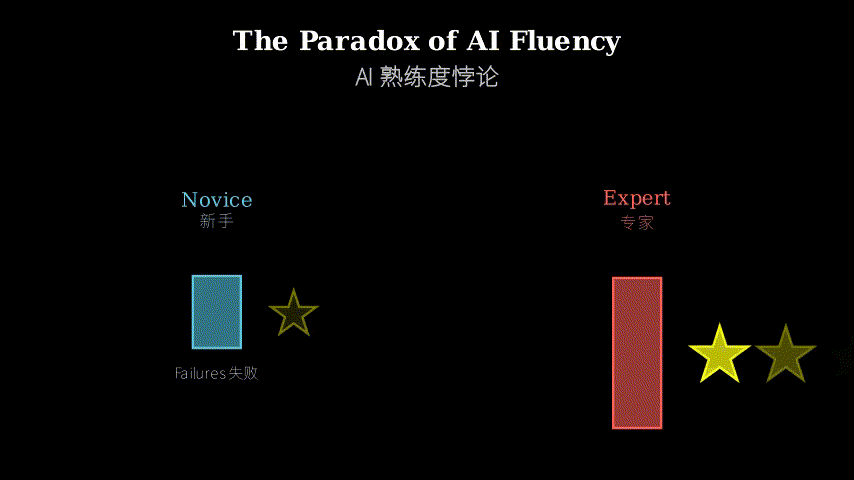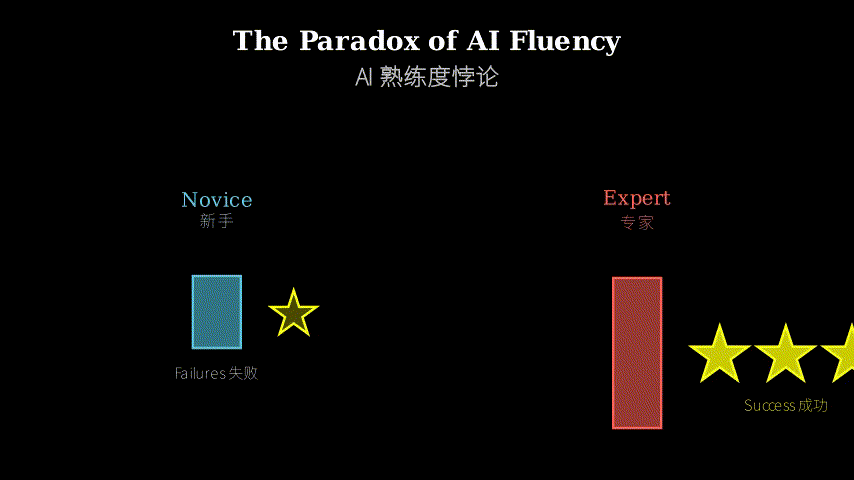
Evidence: Fluent users fail MORE but differently
          (visible failures + partial recovery + complex success)
          Novices fail invisibly (appear successful but miss goals)
   |
   v
Conclusion: Success depends on user stance, not just model quality
            Design implication: Encourage engagement, not frictionlessness
The Increment
One sentence: Before this paper, we assumed better AI models automatically help all users equally; after, we know user fluency fundamentally reshapes what AI delivers—and that visible failure is often a sign of deeper engagement leading to better outcomes.
Core Mechanism
The method has three components working in sequence. First, they sample 27K conversations from WildChat (a dataset of real ChatGPT interactions) and develop an annotation scheme to classify users by fluency level based on prompt sophistication, iteration patterns, and critical assessment behaviors. Second, they code each conversation for task complexity (simple lookup vs. multi-step reasoning), interaction mode (one-shot vs. iterative refinement), and outcome type (success, visible failure, invisible failure). Third, they cross-tabulate fluency against these dimensions to reveal systematic patterns.
The data flow is straightforward: raw transcripts → fluency classification → task/interaction/outcome coding → statistical analysis of correlations. The key operation is the outcome taxonomy: visible failures are explicit (user recognizes the problem, AI admits limitation), invisible failures are conversations that end without error signals but fail to meet the user’s actual goal (detected through manual review of intent vs. delivery).
Raw transcripts (27K)
   |
   v
[Fluency Classifier]
   |  (prompt quality, iteration depth, critical stance)
   v
Fluent / Intermediate / Novice labels
   |
   v
[Outcome Annotator]
   |  (task complexity, interaction mode, failure type)
   v
Cross-tabulation matrix
   |
   v
Pattern: Fluent users → more visible failures + complex successes
         Novice users → more invisible failures + simple successes
Think of this like a driving instructor analyzing dashcam footage. Novice drivers take simple routes (residential streets) and rarely honk or brake hard—their trips look smooth. Expert drivers tackle complex routes (downtown rush hour) and frequently brake, swerve, honk—their trips look chaotic. But the expert’s “failures” (hard braking) prevent actual crashes, while the novice’s smooth ride often means they’re lost but don’t realize it. The instructor’s job is to code each trip: route difficulty, driver interventions, and whether they reached the intended destination. The revelation: visible corrections correlate with route mastery, not incompetence.
Key Concepts
-
Invisible failure: A conversation that terminates without error signals (no “I can’t do that” from the AI, no user complaint) but objectively fails to meet the user’s goal. Example: User asks “help me write a cover letter for a data science job,” AI produces a generic template, user says “thanks” and leaves. The transcript looks successful—polite exchange, output delivered—but the letter is unusable (no specifics about the user’s background or the target role). Invisible failures are dangerous because neither user nor system learns from them; they masquerade as success in aggregate metrics. The paper detects these through manual review: annotators infer user intent from context and judge whether the final output actually serves that intent.
-
Iterative refinement stance: An interaction mode where the user treats the AI as a collaborative partner rather than an oracle. Instead of crafting one perfect prompt and accepting the output, the user issues a rough initial request, critically evaluates the response, then refines through follow-ups (“make it more technical,” “focus on the methodology section,” “that’s not quite right—I meant X”). This stance requires fluency because it demands: (1) ability to assess output quality, (2) vocabulary to articulate corrections, (3) mental model of what the AI can adjust. Novices lack these, so they either accept the first output or abandon the conversation when it’s wrong.
-
Paradox of AI fluency: The counterintuitive finding that fluent users experience higher failure rates than novices—but their failures are productive. Fluent users attempt harder tasks (more opportunities to fail), iterate more (each iteration is a chance to hit a model limitation), and critically assess outputs (they notice problems novices miss). Their failures are visible (logged as explicit errors or user corrections), often lead to partial recovery (user adjusts approach, eventually succeeds), and occur alongside successes on complex tasks. Novices fail less often in the data because they attempt simpler tasks and don’t recognize when outputs are wrong—but their “successes” are often hollow. The paradox: high failure rate signals engagement, not incompetence.
Framework Shift
Before (mainstream approach):        After (this paper):

    [Model Quality]                      [Model Quality]
          |                                     |
          v                                     v
    [User Outcome]                        [User Stance] <--+
     (uniform effect)                           |          |
                                                v          |
                                          [Interaction]    |
                                           /        \      |
                                          v          v     |
                                    [Visible    [Invisible |
                                     Failure]    Failure]  |
                                         |          |      |
                                         v          v      |
                                    [Recovery] [Missed     |
                                               Goal]       |
                                         |                 |
                                         +-- Feedback -----+
                                    (learning loop)

Model-centric:                       User-centric:
Better model → better outcome        Engaged user → productive failure
                                                   → learning → success
One sentence: From treating users as passive recipients of model quality to recognizing that user stance (active vs. passive) fundamentally determines whether AI interactions produce learning and success or invisible failure.
Expert Assessment
Problem choice: This is a real gap with significant practical implications. The field has been obsessed with model benchmarks while ignoring the human side of the interaction loop. The timing is perfect—now that LLMs are deployed at scale, understanding user behavior matters more than squeezing another 2% on MMLU. The framing (fluency as a variable) is obvious in retrospect but genuinely underexplored.
Method maturity: The approach is straightforward—almost too straightforward. Manual annotation of 27K transcripts is labor-intensive but not methodologically novel. The outcome taxonomy (visible/invisible failure) is the paper’s clever contribution, but the execution relies heavily on annotator judgment calls about “user intent,” which introduces subjectivity. They report inter-annotator agreement but don’t deeply probe edge cases. A more mature approach would develop computational proxies for fluency and failure types, enabling analysis at WildChat’s full 4.8M scale.
Experimental integrity: The baselines are implicit (prior work assumes uniform user behavior), so there’s no direct comparison. The numbers are descriptive statistics (fluent users iterate 3.2x per conversation vs. 1.4x for novices) rather than causal claims, which is appropriate given the observational data. One red flag: selection bias. WildChat users who consent to data sharing may differ systematically from the broader population. Fluent users might be overrepresented (they understand data collection), or underrepresented (they use enterprise APIs instead). The paper acknowledges this but doesn’t quantify the bias.
Writing quality: The abstract and introduction are sharp—they set up the paradox clearly. The related work section is thin; it gestures at HCI and education research but doesn’t engage deeply with prior work on user expertise in other domains (search engines, programming tools). The results section is where the paper loses steam: it presents finding after finding without a unifying narrative thread. Rewriting the results as a progression (novice behavior → intermediate → fluent, showing how each level unlocks new interaction modes) would make the patterns more memorable. The discussion recovers with strong practical implications, but it arrives too late.
Verdict: Weak accept — The core finding (fluency reshapes outcomes, visible failure signals engagement) is valuable and underexplored, but the execution is workmanlike rather than groundbreaking. The paper will influence product design more than research methodology.
Takeaways
For AI product builders: Stop optimizing for frictionless experiences. Friction—in the form of visible failures, user corrections, iterative refinement—is a feature, not a bug. Design interfaces that encourage users to critique outputs (e.g., “What’s wrong with this response?” buttons) and iterate (e.g., conversation branching, version comparison). Measure success not by first-response acceptance rate but by depth of engagement and goal achievement after iteration.
For researchers: The visible/invisible failure taxonomy transfers to any human-AI interaction domain. Apply it to code generation (does the code run? does it solve the actual problem?), content moderation (does the user accept the decision? was the decision correct?), recommendation systems (does the user click? does the click satisfy their intent?). The method—manual annotation of intent vs. outcome—is tedious but reveals gaps that aggregate metrics miss.
For users: Adopt the iterative refinement stance. Treat the AI’s first response as a draft, not a final answer. Ask follow-ups, point out errors, request adjustments. The paper’s evidence suggests this stance is learnable (intermediate users show partial adoption), not an innate skill. Concretely: after every AI response, ask yourself “Does this actually solve my problem?” If not, say so explicitly rather than accepting and moving on.
论文: 2604.25905 作者: Christopher Potts, Moritz Sudhof 分类: cs.CL
缺口
现有的 AI 评估研究孤立地测量模型性能——基准测试的准确率、响应质量、任务完成率。
隐含假设是:更好的模型自动为用户带来更好的结果。
但这忽略了一个关键变量:用户技能。
我们从其他所有技术中都知道,专业知识会塑造结果(专业摄影师从相机中获得更多,熟练司机从汽车中榨取更多),但 AI 研究将用户视为模型输出的统一消费者。
具体缺口:没有人系统地测量过用户对 AI 的熟练度如何改变他们尝试的任务、交互方式、遇到的失败以及获得的结果。
没有这些,我们就是在黑暗中优化模型,不知道摩擦来自模型局限还是用户行为。
问题:AI 评估忽略用户技能差异
   |
   v
假设:模型质量 = 用户结果
   |
   v
方法:按用户熟练度标注 27K 条真实对话
      + 测量任务复杂度、交互模式、失败类型
   |
   v
证据:熟练用户失败更多但方式不同
      (可见失败 + 部分恢复 + 复杂成功)
      新手不可见失败(看似成功但偏离目标)
   |
   v
结论:成功取决于用户姿态,而非仅模型质量
      设计启示:鼓励参与,而非无摩擦
增量
一句话:在这篇论文之前,我们假设更好的 AI 模型自动平等地帮助所有用户;之后,我们知道用户熟练度从根本上重塑了 AI 交付的内容——而且可见失败往往是更深层参与的标志,导致更好的结果。
核心机制
该方法有三个按顺序工作的组件。
首先,他们从 WildChat(真实 ChatGPT 交互数据集)中抽取 27K 条对话,并开发标注方案,根据提示词复杂度、迭代模式和批判性评估行为按熟练度对用户分类。
其次,他们对每个对话进行任务复杂度(简单查询 vs. 多步推理)、交互模式(一次性 vs. 迭代细化)和结果类型(成功、可见失败、不可见失败)编码。
第三,他们将熟练度与这些维度交叉制表,揭示系统性模式。
数据流很直接:原始记录 → 熟练度分类 → 任务/交互/结果编码 → 相关性统计分析。
关键操作是结果分类法:可见失败是显式的(用户识别问题,AI 承认局限),不可见失败是没有错误信号就结束的对话,但未能满足用户的实际目标(通过人工审查意图 vs. 交付来检测)。
原始记录 (27K)
   |
   v
[熟练度分类器]
   |  (提示词质量、迭代深度、批判姿态)
   v
熟练 / 中级 / 新手 标签
   |
   v
[结果标注器]
   |  (任务复杂度、交互模式、失败类型)
   v
交叉制表矩阵
   |
   v
模式:熟练用户 → 更多可见失败 + 复杂成功
      新手用户 → 更多不可见失败 + 简单成功
把这想象成驾驶教练分析行车记录仪录像。
新手司机走简单路线(住宅区街道),很少按喇叭或急刹车——他们的行程看起来很顺畅。
专家司机应对复杂路线(市中心高峰期),频繁刹车、转向、按喇叭——他们的行程看起来很混乱。
但专家的”失败”(急刹车)防止了真正的碰撞,而新手的顺畅行驶往往意味着他们迷路了但没意识到。
教练的工作是对每次行程编码:路线难度、司机干预、是否到达预定目的地。
启示:可见的纠正与路线掌握相关,而非无能。
关键概念
- 不可见失败:一个没有错误信号就终止的对话(AI 没有”我做不到”,用户没有抱怨),但客观上未能满足用户的目标。
例子:用户问”帮我写一封数据科学工作的求职信”,AI 生成一个通用模板,用户说”谢谢”然后离开。
记录看起来成功——礼貌交流,输出交付——但信件无法使用(没有关于用户背景或目标职位的具体信息)。
不可见失败很危险,因为用户和系统都无法从中学习;它们在总体指标中伪装成成功。
论文通过人工审查检测这些:标注者从上下文推断用户意图,并判断最终输出是否真正服务于该意图。
- 迭代细化姿态:一种交互模式,用户将 AI 视为协作伙伴而非神谕。
用户不是精心制作一个完美提示词并接受输出,而是发出一个粗略的初始请求,批判性地评估响应,然后通过后续跟进细化(“让它更技术化”,“专注于方法论部分”,“那不太对——我是指 X”)。
这种姿态需要熟练度,因为它要求:(1)评估输出质量的能力,(2)表达纠正的词汇,(3)AI 可以调整什么的心智模型。
新手缺乏这些,所以他们要么接受第一个输出,要么在错误时放弃对话。
- AI 熟练度悖论:反直觉的发现,即熟练用户比新手经历更高的失败率——但他们的失败是有成效的。
熟练用户尝试更难的任务(更多失败机会),迭代更多(每次迭代都是碰到模型局限的机会),并批判性地评估输出(他们注意到新手错过的问题)。
他们的失败是可见的(记录为显式错误或用户纠正),通常导致部分恢复(用户调整方法,最终成功),并与复杂任务上的成功同时发生。
新手在数据中失败较少,因为他们尝试更简单的任务,并且不认识到输出何时错误——但他们的”成功”往往是空洞的。
悖论:高失败率标志着参与,而非无能。
框架转变
之前(主流方法):                之后(本文方法):

    [模型质量]                        [模型质量]
          |                                 |
          v                                 v
    [用户结果]                        [用户姿态] <--+
     (统一效应)                             |          |
                                            v          |
                                      [交互过程]        |
                                       /        \      |
                                      v          v     |
                                  [可见      [不可见   |
                                   失败]      失败]    |
                                     |          |      |
                                     v          v      |
                                  [恢复]   [偏离      |
                                           目标]      |
                                     |                |
                                     +-- 反馈 --------+
                                    (学习循环)

以模型为中心:                    以用户为中心:
更好的模型 → 更好的结果           参与的用户 → 有成效的失败
                                            → 学习 → 成功
一句话:从将用户视为模型质量的被动接受者,到认识到用户姿态(主动 vs. 被动)从根本上决定 AI 交互是产生学习和成功,还是不可见失败。
专家评审
选题眼光:这是一个具有重大实际意义的真实缺口。
该领域一直痴迷于模型基准测试,而忽略了交互循环的人类一侧。
时机完美——现在 LLM 已大规模部署,理解用户行为比在 MMLU 上再挤出 2% 更重要。
框架(熟练度作为变量)事后看来显而易见,但确实未被充分探索。
方法成熟度:方法很直接——几乎太直接了。
对 27K 条记录的人工标注是劳动密集型的,但在方法论上并不新颖。
结果分类法(可见/不可见失败)是论文的巧妙贡献,但执行严重依赖标注者对”用户意图”的判断,这引入了主观性。
他们报告了标注者间一致性,但没有深入探讨边缘案例。
更成熟的方法会开发熟练度和失败类型的计算代理,使分析能够在 WildChat 的完整 480 万规模上进行。
实验诚意:基线是隐式的(先前工作假设统一的用户行为),所以没有直接比较。
数字是描述性统计(熟练用户每次对话迭代 3.2 次 vs. 新手 1.4 次)而非因果声明,这对于观察性数据是合适的。
一个值得警惕之处:选择偏差。
同意数据共享的 WildChat 用户可能与更广泛的人群系统性地不同。
熟练用户可能被过度代表(他们理解数据收集),或代表不足(他们使用企业 API)。
论文承认了这一点,但没有量化偏差。
写作功力:摘要和引言很犀利——它们清楚地设置了悖论。
相关工作部分很薄;它向 HCI 和教育研究示意,但没有深入参与其他领域用户专业知识的先前工作(搜索引擎、编程工具)。
结果部分是论文失去动力的地方:它一个接一个地呈现发现,没有统一的叙事线索。
将结果重写为一个进展(新手行为 → 中级 → 熟练,展示每个级别如何解锁新的交互模式)会使模式更令人难忘。
讨论部分以强有力的实际启示恢复,但它来得太晚了。
判决:弱接收 — 核心发现(熟练度重塑结果,可见失败标志参与)是有价值且未被充分探索的,但执行是工匠式的而非开创性的。
论文对产品设计的影响将大于对研究方法论的影响。
要点总结
对 AI 产品构建者:停止优化无摩擦体验。
摩擦——以可见失败、用户纠正、迭代细化的形式——是特性,而非缺陷。
设计鼓励用户批评输出的界面(例如,“这个响应有什么问题?“按钮)和迭代(例如,对话分支、版本比较)。
衡量成功不是通过首次响应接受率,而是通过参与深度和迭代后的目标实现。
对研究者:可见/不可见失败分类法可迁移到任何人机交互领域。
将其应用于代码生成(代码能运行吗?它解决实际问题了吗?)、内容审核(用户接受决定吗?决定正确吗?)、推荐系统(用户点击了吗?点击满足他们的意图了吗?)。
方法——人工标注意图 vs. 结果——很繁琐,但揭示了总体指标遗漏的缺口。
对用户:采用迭代细化姿态。
将 AI 的第一个响应视为草稿,而非最终答案。
提出后续问题,指出错误,请求调整。
论文的证据表明这种姿态是可学习的(中级用户显示部分采用),而非天生技能。
具体来说:在每个 AI 响应之后,问自己”这真的解决了我的问题吗?“如果没有,明确说出来,而不是接受并继续。