Paper: 2602.24273 Authors: Borja Requena Pozo, Austin Letson, Krystian Nowakowski, Izan Beltran Ferreiro, Leopoldo Sarra Categories: cs.AI
The Gap
The automated theorem proving landscape has become cluttered with increasingly complex systems—AlphaProof, DeepSeek-Prover, LEGO-Prover—each introducing novel architectural components that make it nearly impossible to isolate what actually drives performance. When one system outperforms another, is it the model size? The search strategy? The training data? The prompt engineering? We can’t tell, because these systems are monolithic black boxes with dozens of interacting design choices. The field lacks a minimal, transparent baseline that implements only the essential components, allowing researchers to conduct controlled experiments and understand which innovations actually matter.
The Increment
Before: Complex theorem provers with entangled components → impossible to attribute performance gains. After: A minimal agent with three decoupled modules → systematic ablation studies become feasible.
Think of this system as a three-stage assembly line for mathematical proofs. The first station (proof refinement) is where a worker repeatedly examines a partially completed proof, identifies the next gap, and attempts to fill it—this is the iterative core that generates proof steps one at a time based on feedback from the proof assistant. The second station (library search) is the reference desk where the worker looks up relevant theorems and lemmas from a vast catalog—implemented as semantic search over the mathematical library to retrieve useful context. The third station (context management) is the quality control checkpoint that decides what information to keep in the worker’s limited attention span—a filtering mechanism that prevents context overflow while retaining critical proof state. Each station operates independently, making it trivial to swap out components or measure their individual contributions.
The architecture deliberately avoids sophistication. No reinforcement learning, no tree search, no ensemble methods—just an LLM in a loop with access to a search index and a context window manager. Yet this simplicity is the point: by stripping away everything non-essential, the authors create a reference implementation that reveals which complexities in existing systems are load-bearing and which are ornamental.
Key Concepts
Iterative Proof Refinement
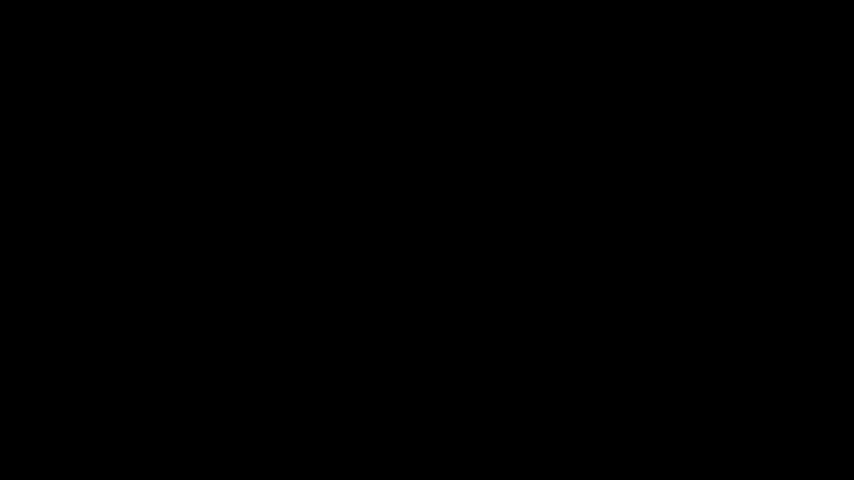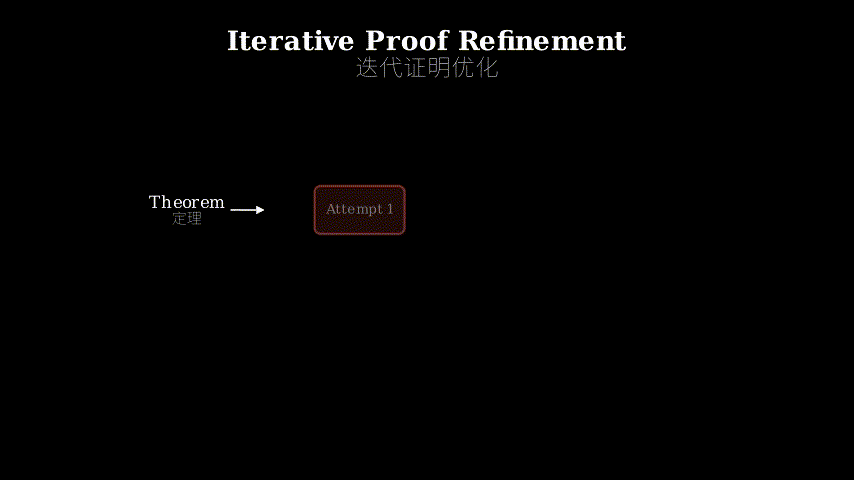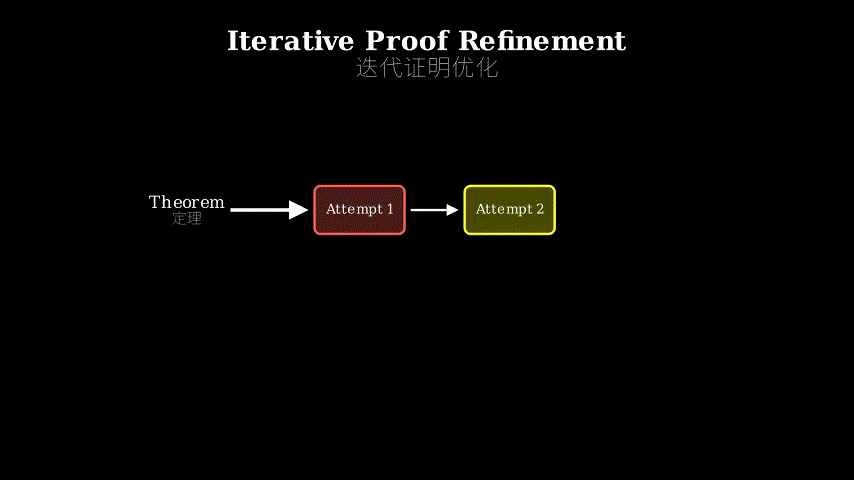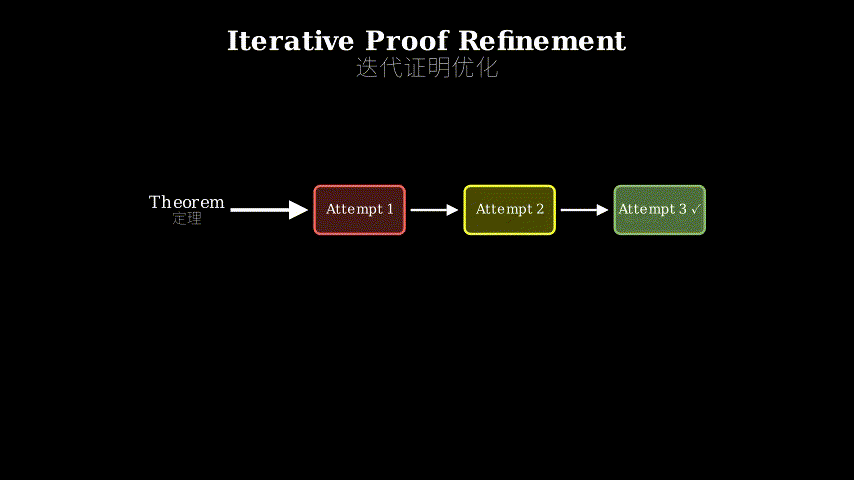
Imagine you’re solving a jigsaw puzzle, but you can only see one piece at a time, and after placing each piece, someone tells you whether it fits or not. That’s iterative refinement. In formal mathematics, a proof isn’t written in one shot—it’s constructed step-by-step, where each step must be verified by a proof assistant (like Lean or Coq) before you proceed. If a step fails, you get an error message explaining why, and you try again.
The minimal agent implements this as a simple loop: (1) send the current proof state to the LLM, (2) receive a proposed next tactic, (3) execute it in the proof assistant, (4) if it succeeds, append it to the proof and repeat; if it fails, include the error in the next prompt and ask for a correction. This is fundamentally different from generating an entire proof at once, because the LLM gets real-time feedback about what’s valid. It’s like having a compiler that talks back to you after every line of code, rather than only after you hit “run” on the whole program.
Library Search as Retrieval-Augmented Generation
Formal mathematics has a chicken-and-egg problem: to prove theorem X, you often need to invoke lemma Y, but how do you know lemma Y exists in the library? Human mathematicians spend years internalizing their field’s “standard toolkit,” but LLMs don’t have this—they hallucinate lemma names or miss relevant results.
The solution here is semantic search: embed all theorems in the library into a vector space (using something like sentence transformers), then at each proof step, embed the current goal and retrieve the nearest neighbors. These retrieved theorems get injected into the LLM’s context as “here are some potentially useful facts.” It’s RAG (retrieval-augmented generation) applied to mathematics. The key insight is that you don’t need a fancy learned retriever—even a simple embedding model gives you enough signal to surface relevant lemmas, dramatically reducing hallucination rates.
Context Management
LLMs have finite context windows, but proofs can be arbitrarily long. After 50 proof steps, you’ve accumulated thousands of tokens of history—previous tactics, error messages, retrieved lemmas—and you’re about to hit the context limit. What do you keep?
The minimal agent uses a sliding window with priority retention: always keep the original theorem statement and the current proof state (these are non-negotiable), then fill the remaining space with recent history and high-relevance retrieved lemmas. Older steps get evicted first, under the assumption that recent context is more predictive of the next step. This is crude but effective—it’s the difference between a system that crashes after 30 steps and one that can handle 200-step proofs. More sophisticated approaches (like compressing history with a summarization model) are possible, but the authors show you can get surprisingly far with this simple heuristic.
Expert Assessment
Problem significance: High. Automated theorem proving is a testbed for AI reasoning capabilities, and the lack of standardized baselines has made progress hard to measure. The affected community includes not just formal verification researchers, but anyone working on AI for mathematics, code synthesis, or multi-step reasoning. This paper provides infrastructure that should accelerate the field.
Method maturity: This is a reference implementation, not a production system. The authors are explicit about limitations—no learning from feedback, no sophisticated search strategies, no handling of proof repair beyond simple retry. The architecture is deployment-ready in the sense that it’s stable and reproducible, but it’s not designed to be the best prover; it’s designed to be the simplest prover that’s still competitive. That’s a feature, not a bug, but it means practitioners looking for state-of-the-art performance will need to add components back in.
Experimental rigor: Strong. The authors test on multiple benchmarks (miniF2F, ProofNet, and others) with different characteristics, compare against both simple baselines (single-shot generation) and complex systems (AlphaProof-style approaches), and ablate each component to show its contribution. One potential concern: the paper doesn’t deeply explore failure modes—when the minimal agent fails, is it because the problem is genuinely hard, or because some missing component (like tree search) would have solved it? More error analysis would strengthen the claims.
Verdict: Weak accept — valuable contribution to research infrastructure, but limited novelty in individual components; the value is in the integration and the open-source release, not in algorithmic innovation.
Takeaways
Simplicity as a research tool: When a field gets too complex, the highest-leverage move is often to build the simplest thing that works, then use it as a baseline to measure everything else. This applies beyond theorem proving—any domain with proliferating architectures (e.g., code generation, robotics planning) would benefit from a “minimal agent” that isolates core components.
Iterative refinement beats one-shot generation: The paper shows consistent gains from letting the model see feedback and retry, even with no learning. This pattern transfers directly to code synthesis (run the code, see the error, fix it), dialogue systems (get user feedback, refine the response), and scientific reasoning (propose hypothesis, see experimental result, update). The key is closing the loop between generation and evaluation.
Retrieval is underrated: Many researchers focus on making models bigger or training them longer, but this paper shows that a simple semantic search over a knowledge base can match or exceed the gains from scale. If your domain has a structured knowledge source (API docs, scientific literature, legal precedents), embedding-based retrieval should be your first move before reaching for a larger model.
Context management is a first-class design problem: As tasks get longer (multi-turn conversations, long-horizon planning, extended proofs), what you keep in context matters as much as the model itself. The sliding window with priority retention is a transferable pattern—always preserve the task specification and current state, then allocate remaining space to recent history and high-relevance retrieved information.
论文: 2602.24273 作者: Borja Requena Pozo, Austin Letson, Krystian Nowakowski, Izan Beltran Ferreiro, Leopoldo Sarra 分类: cs.AI
缺口
自动定理证明领域已经变成了一个复杂系统的竞技场——AlphaProof、DeepSeek-Prover、LEGO-Prover——每个都引入新颖的架构组件,让人根本无法分离出真正驱动性能的因素。当一个系统超越另一个时,是模型规模的功劳?搜索策略?训练数据?提示工程?我们无从得知,因为这些系统都是整体性的黑箱,包含数十个相互作用的设计选择。这个领域缺少一个极简、透明的基线,只实现必要组件,让研究者能够进行受控实验,理解哪些创新真正重要。
增量
之前: 复杂的定理证明器,组件纠缠 → 性能提升无法归因。之后: 极简智能体,三个解耦模块 → 系统性消融研究成为可能。
把这个系统想象成数学证明的三站式流水线。第一站(证明精炼)是工人反复检查部分完成的证明,识别下一个缺口并尝试填补——这是迭代核心,根据证明助手的反馈逐步生成证明步骤。第二站(库检索)是参考台,工人从庞大目录中查找相关定理和引理——实现为对数学库的语义搜索以检索有用上下文。第三站(上下文管理)是质量控制检查点,决定在工人有限的注意力范围内保留什么信息——一个过滤机制,既防止上下文溢出又保留关键证明状态。每一站独立运作,使得替换组件或测量其单独贡献变得轻而易举。
这个架构刻意避免复杂性。没有强化学习,没有树搜索,没有集成方法——只是一个循环中的LLM,配备搜索索引和上下文窗口管理器。然而这种简洁性正是要点:通过剥离一切非必要元素,作者创建了一个参考实现,揭示现有系统中哪些复杂性是承重的,哪些是装饰性的。
关键概念
迭代式证明精炼
想象你在拼拼图,但每次只能看到一块,放置每块后有人告诉你是否合适。这就是迭代精炼。在形式化数学中,证明不是一次性写出的——而是逐步构建的,每一步都必须经过证明助手(如Lean或Coq)验证才能继续。如果某步失败,你会得到解释原因的错误消息,然后重试。
极简智能体将此实现为简单循环:(1)将当前证明状态发送给LLM,(2)接收建议的下一个策略,(3)在证明助手中执行,(4)如果成功,将其追加到证明中并重复;如果失败,在下一个提示中包含错误并请求修正。这与一次性生成整个证明根本不同,因为LLM获得关于什么有效的实时反馈。就像有一个编译器在你每写一行代码后都与你对话,而不是只在你对整个程序点击”运行”后才反馈。
库检索作为检索增强生成
形式化数学有个先有鸡还是先有蛋的问题:要证明定理X,你常常需要引用引理Y,但你怎么知道引理Y存在于库中?人类数学家花费数年内化其领域的”标准工具包”,但LLM没有这个——它们会幻想引理名称或错过相关结果。
这里的解决方案是语义搜索:将库中所有定理嵌入到向量空间(使用句子转换器之类),然后在每个证明步骤,嵌入当前目标并检索个最近邻。这些检索到的定理被注入LLM的上下文,作为”这里有一些可能有用的事实”。这是应用于数学的RAG(检索增强生成)。关键洞察是你不需要精巧的学习型检索器——即使是简单的嵌入模型也能给你足够的信号来浮现相关引理,大幅降低幻觉率。
上下文管理
LLM有有限的上下文窗口,但证明可以任意长。经过50个证明步骤后,你已经积累了数千个token的历史——先前的策略、错误消息、检索到的引理——你即将触及上下文限制。你保留什么?
极简智能体使用带优先级保留的滑动窗口:始终保留原始定理陈述和当前证明状态(这些不可协商),然后用最近历史和高相关性检索引理填充剩余空间。较旧的步骤首先被驱逐,假设最近的上下文对下一步更有预测性。这很粗糙但有效——这是一个在30步后崩溃的系统与一个能处理200步证明的系统之间的差异。更复杂的方法(如用摘要模型压缩历史)是可能的,但作者展示了用这个简单启发式你能走得出奇地远。
专家评审
问题重要性: 高。自动定理证明是AI推理能力的试验场,缺乏标准化基线使得进展难以衡量。受影响的群体不仅包括形式化验证研究者,还包括任何从事AI数学、代码合成或多步推理的人。这篇论文提供的基础设施应该能加速该领域发展。
方法成熟度: 这是参考实现,不是生产系统。作者明确说明了局限性——没有从反馈中学习,没有复杂的搜索策略,除了简单重试外没有处理证明修复。该架构在稳定性和可重现性意义上是可部署的,但它不是设计成最佳证明器;它被设计成仍具竞争力的最简证明器。这是特性而非缺陷,但意味着寻求最先进性能的实践者需要重新添加组件。
实验严谨性: 强。作者在多个具有不同特征的基准(miniF2F、ProofNet等)上测试,与简单基线(单次生成)和复杂系统(AlphaProof风格方法)进行比较,并消融每个组件以显示其贡献。一个潜在担忧:论文没有深入探索失败模式——当极简智能体失败时,是因为问题真的很难,还是因为某个缺失组件(如树搜索)本可以解决它?更多错误分析会加强论断。
判决: 弱接收 — 对研究基础设施有价值的贡献,但单个组件的新颖性有限;价值在于集成和开源发布,而非算法创新。
要点总结
简洁性作为研究工具: 当一个领域变得过于复杂时,最高杠杆的举措往往是构建能工作的最简单东西,然后用它作为基线来衡量其他一切。这适用于定理证明之外——任何架构激增的领域(如代码生成、机器人规划)都会受益于隔离核心组件的”极简智能体”。
迭代精炼胜过一次性生成: 论文展示了让模型看到反馈并重试带来的一致性收益,即使没有学习。这个模式直接迁移到代码合成(运行代码,看到错误,修复它)、对话系统(获得用户反馈,精炼响应)和科学推理(提出假设,看到实验结果,更新)。关键是闭合生成与评估之间的循环。
检索被低估了: 许多研究者专注于让模型更大或训练更久,但这篇论文表明对知识库的简单语义搜索可以匹配或超过规模带来的收益。如果你的领域有结构化知识源(API文档、科学文献、法律先例),基于嵌入的检索应该是你在求助更大模型之前的第一步。
上下文管理是一流的设计问题: 随着任务变长(多轮对话、长期规划、扩展证明),你在上下文中保留什么与模型本身同样重要。带优先级保留的滑动窗口是可迁移的模式——始终保留任务规范和当前状态,然后将剩余空间分配给最近历史和高相关性检索信息。