Paper: 2602.23358 Authors: Elad Kimchi Shoshani, Leeyam Gabay, Yedid Hoshen Categories: cs.LG, cs.CV
Abstract
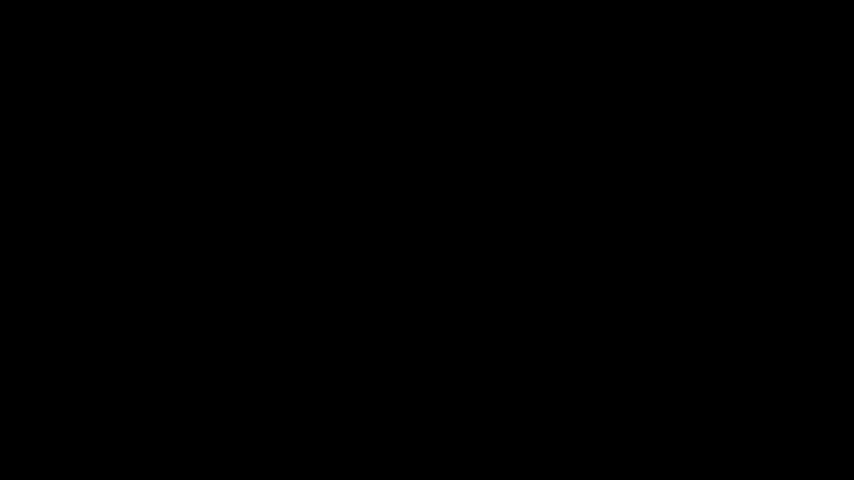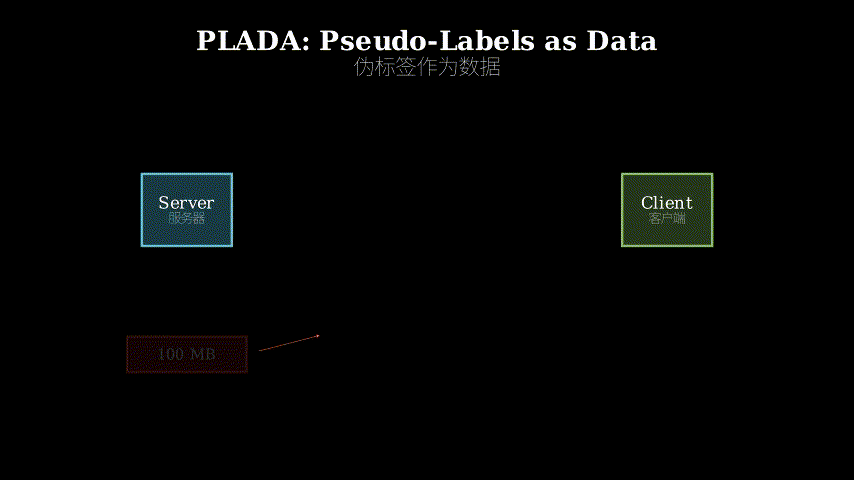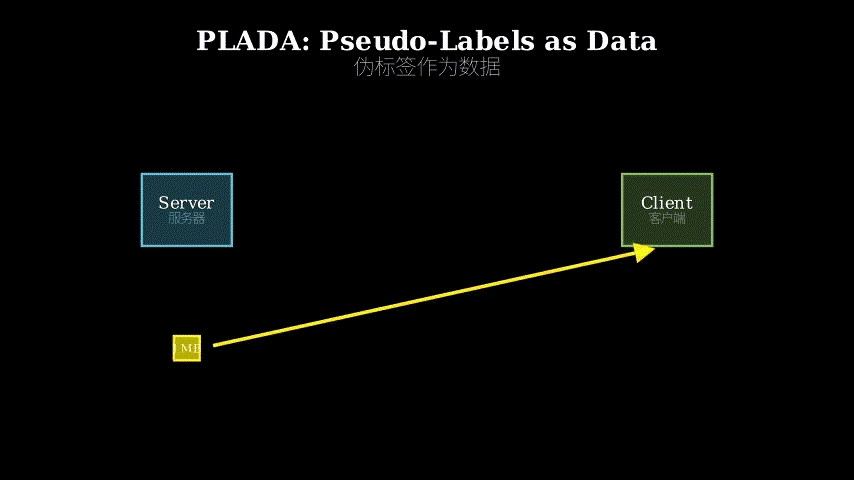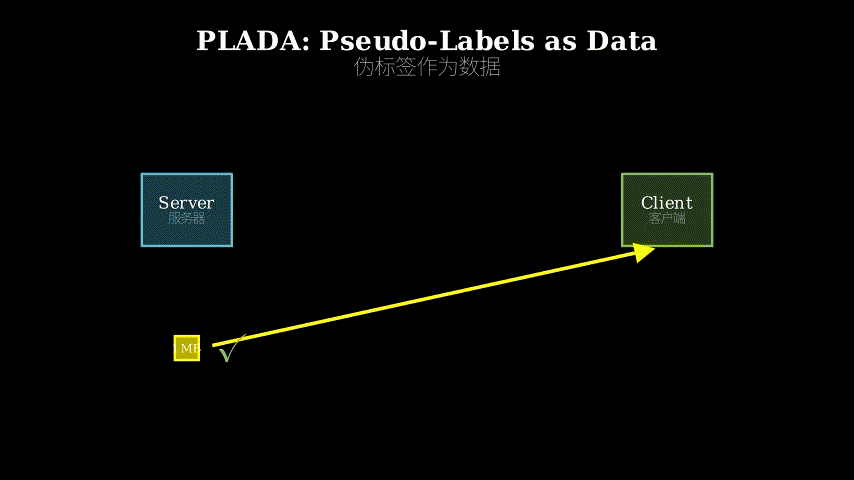
This paper introduces PLADA (Pseudo-Labels as Data), a novel approach to dataset distribution that radically reduces communication costs. Instead of transmitting raw pixel data or distilled datasets, PLADA assumes clients have access to a large, unlabeled reference dataset (like ImageNet) and transmits only class labels for selected images. The method incorporates an intelligent pruning mechanism to filter the reference dataset, retaining only semantically relevant images for the target task. Experimental validation across 10 datasets shows that PLADA can transfer complete task knowledge with payloads under 1 MB while maintaining competitive classification accuracy, representing a breakthrough in efficient dataset serving.
Key Contributions
- Zero-pixel transmission paradigm: Completely eliminates the need to transmit image data by leveraging pre-loaded reference datasets
- Semantic pruning mechanism: Intelligently filters reference datasets to select only the most relevant images for target tasks, balancing efficiency and accuracy
- Sub-megabyte payloads: Achieves dataset distribution with less than 1 MB of transmitted data across diverse classification tasks
- Scalability to high-resolution data: Overcomes limitations of traditional dataset distillation methods that struggle with large, high-resolution images
Methodology: Pseudo-Labels as Data
The PLADA framework operates on a simple but powerful premise: rather than transmitting pixels, transmit semantic information. The approach consists of three key components:
Reference Dataset Assumption: Clients are assumed to have access to a large, generic, unlabeled dataset (e.g., ImageNet-1K with 1.2M images or ImageNet-21K with 14M images). This one-time preloading cost is amortized across multiple task distributions.
Label Assignment: For a target task with classes , the server assigns pseudo-labels from to images in . The transmitted payload consists solely of tuples where is an image index and is the assigned class label.
Semantic Pruning: To address distribution mismatch between reference and target datasets, PLADA employs a pruning strategy that selects a subset of the most semantically relevant images. This selection process uses feature-based similarity metrics to identify images that best represent the target task’s semantic space, simultaneously reducing payload size and improving training efficiency.
The pruning mechanism is critical: transmitting labels for all 1.2M ImageNet images would still require significant bandwidth, while random sampling would include many irrelevant images. PLADA’s intelligent selection ensures that only the most informative pseudo-labels are transmitted.
Experimental Results and Analysis
The authors evaluate PLADA across 10 diverse datasets spanning different domains, image resolutions, and classification complexities. Key findings include:
Compression Performance: PLADA consistently achieves payloads under 1 MB across all tested datasets. For context, transmitting even a single high-resolution image can exceed this size, yet PLADA encodes entire task-specific training signals within this budget.
Accuracy Retention: Despite the extreme compression, PLADA maintains competitive classification accuracy compared to training on full target datasets. The semantic pruning mechanism proves effective at identifying reference images that capture the essential visual patterns needed for target tasks.
Scalability: Unlike dataset distillation methods that struggle with high-resolution images due to computational and memory constraints, PLADA’s label-only approach scales effortlessly to any image resolution since pixels are never processed or transmitted.
Cross-domain Transfer: The method demonstrates robustness across domain shifts between reference and target datasets, suggesting that large generic datasets like ImageNet contain sufficient visual diversity to support diverse downstream tasks through appropriate label assignment.
Implications and Future Directions
PLADA represents a paradigm shift in how we think about dataset distribution. The implications extend beyond mere bandwidth savings:
Federated Learning: In federated settings where communication is the primary bottleneck, PLADA could enable more frequent model updates and support for resource-constrained edge devices.
Privacy Considerations: By transmitting only labels rather than raw images, PLADA inherently provides a degree of privacy protection, though the reference dataset itself must still be carefully curated.
Environmental Impact: Reducing data transmission from gigabytes to kilobytes translates to significant energy savings at scale, particularly for cloud-based ML services serving millions of clients.
Limitations: The approach requires clients to store large reference datasets locally, which may be prohibitive for extremely resource-constrained devices. Additionally, performance depends on the semantic coverage of the reference dataset relative to target tasks.
Future work could explore dynamic reference dataset selection, where different clients use different reference datasets based on their storage capabilities, or investigate methods to generate synthetic reference datasets optimized for label-based transfer.
Takeaways
- PLADA achieves dataset distribution with sub-1MB payloads by transmitting only class labels for pre-loaded reference datasets, eliminating pixel transmission entirely
- Semantic pruning is essential for selecting relevant reference images, balancing transmission efficiency with training effectiveness
- The approach scales to high-resolution data where traditional dataset distillation methods fail, offering a practical solution for real-world deployment
- Experimental validation across 10 datasets confirms that extreme compression (1000x+ reduction) is achievable while maintaining competitive accuracy
- The method opens new possibilities for efficient federated learning, privacy-preserving dataset sharing, and environmentally sustainable ML infrastructure
论文: 2602.23358 作者: Elad Kimchi Shoshani, Leeyam Gabay, Yedid Hoshen 分类: cs.LG, cs.CV
摘要
本文提出了PLADA(伪标签作为数据)方法,这是一种革命性的数据集分发方案,能够大幅降低通信成本。PLADA不传输原始像素数据或蒸馏数据集,而是假设客户端已预加载大型无标签参考数据集(如ImageNet),仅传输选定图像的类别标签。该方法引入智能剪枝机制来过滤参考数据集,只保留与目标任务语义相关的图像。在10个数据集上的实验验证表明,PLADA能够以小于1MB的传输负载完成任务知识迁移,同时保持竞争力的分类准确率,为高效数据集服务提供了突破性解决方案。
主要贡献
- 零像素传输范式: 通过利用预加载的参考数据集,完全消除了图像数据传输的需求
- 语义剪枝机制: 智能过滤参考数据集,仅选择与目标任务最相关的图像,在效率和准确率之间取得平衡
- 亚兆字节传输负载: 在多样化分类任务中实现小于1MB的数据集分发
- 高分辨率数据可扩展性: 克服了传统数据集蒸馏方法在处理大型高分辨率图像时的局限性
方法论:伪标签作为数据
PLADA框架基于一个简单而强大的前提:传输语义信息而非像素。该方法包含三个关键组件:
参考数据集假设: 假设客户端可访问大型通用无标签数据集(例如包含120万图像的ImageNet-1K或包含1400万图像的ImageNet-21K)。这种一次性预加载成本可在多个任务分发中摊销。
标签分配: 对于具有类别集的目标任务,服务器为中的图像分配来自的伪标签。传输的负载仅包含元组,其中是图像索引,是分配的类别标签。
语义剪枝: 为解决参考数据集与目标数据集之间的分布不匹配问题,PLADA采用剪枝策略选择最具语义相关性的图像子集。该选择过程使用基于特征的相似度度量来识别最能代表目标任务语义空间的图像,同时减少传输负载并提高训练效率。
剪枝机制至关重要:为所有120万ImageNet图像传输标签仍需要大量带宽,而随机采样会包含许多不相关图像。PLADA的智能选择确保只传输最具信息量的伪标签。
实验结果与分析
作者在10个涵盖不同领域、图像分辨率和分类复杂度的数据集上评估了PLADA。主要发现包括:
压缩性能: PLADA在所有测试数据集上始终实现小于1MB的传输负载。作为对比,传输单张高分辨率图像就可能超过这个大小,而PLADA却能在此预算内编码完整的任务特定训练信号。
准确率保持: 尽管压缩极端,PLADA相比在完整目标数据集上训练仍保持竞争力的分类准确率。语义剪枝机制有效识别了能够捕获目标任务所需关键视觉模式的参考图像。
可扩展性: 与因计算和内存限制而难以处理高分辨率图像的数据集蒸馏方法不同,PLADA的纯标签方法可轻松扩展到任何图像分辨率,因为从不处理或传输像素。
跨域迁移: 该方法在参考数据集和目标数据集之间的域偏移中表现出鲁棒性,表明像ImageNet这样的大型通用数据集包含足够的视觉多样性,可通过适当的标签分配支持多样化的下游任务。
影响与未来方向
PLADA代表了数据集分发思维方式的范式转变。其影响超越了单纯的带宽节省:
联邦学习: 在通信是主要瓶颈的联邦学习场景中,PLADA可实现更频繁的模型更新,并支持资源受限的边缘设备。
隐私考虑: 通过仅传输标签而非原始图像,PLADA本质上提供了一定程度的隐私保护,尽管参考数据集本身仍需仔细策划。
环境影响: 将数据传输从GB级降至KB级,在大规模场景下可显著节省能源,特别是对服务数百万客户端的云端机器学习服务。
局限性: 该方法要求客户端本地存储大型参考数据集,这对极度资源受限的设备可能不可行。此外,性能取决于参考数据集相对于目标任务的语义覆盖范围。
未来工作可探索动态参考数据集选择,让不同客户端根据存储能力使用不同参考数据集,或研究生成针对基于标签迁移优化的合成参考数据集的方法。
要点总结
- PLADA通过仅传输预加载参考数据集的类别标签实现小于1MB的数据集分发,完全消除像素传输
- 语义剪枝对于选择相关参考图像至关重要,在传输效率和训练效果之间取得平衡
- 该方法可扩展到传统数据集蒸馏方法失效的高分辨率数据场景,为实际部署提供实用解决方案
- 在10个数据集上的实验验证确认,在保持竞争力准确率的同时可实现极端压缩(1000倍以上的缩减)
- 该方法为高效联邦学习、隐私保护数据集共享和环境可持续的机器学习基础设施开辟了新可能性