Paper: 2603.04370 Authors: Quan Shi, Alexandra Zytek, Pedram Razavi, Karthik Narasimhan, Victor Barres Categories: cs.AI, cs.CL, cs.IR
The Gap
Existing benchmarks test retrieval (RAG systems) and tool use (ReAct, function calling) as separate skills. HotPotQA checks if you can hop across Wikipedia articles. ToolBench checks if you can call APIs in sequence. But real customer support agents need both simultaneously: retrieve policy documents while executing account changes, where the policy determines which tool calls are legal.
The gap is evaluation realism. Current benchmarks don’t capture the interleaved decision-making that happens when an agent must consult unstructured knowledge to decide what actions are permissible, then verify those actions comply with retrieved policies. It’s like testing a lawyer’s research skills and courtroom skills separately, never asking them to argue a case using case law.
Problem: Agents deployed in knowledge-intensive settings fail unpredictably
   |
   v
Assumption: Existing benchmarks test retrieval + tool use in isolation
   |
   v
Method: τ-Knowledge = τ-Bench + 700-doc knowledge base + policy constraints
   |
   v
Evidence: Frontier models @ 25.5% pass rate (vs 70%+ on isolated tasks)
   |
   v
Conclusion: Coordinating knowledge + tools is a distinct, unsolved capability
The Increment
One sentence: Before, we knew agents could retrieve OR act; now we know they fail catastrophically when required to do both in realistic, policy-governed workflows.
Core Mechanism
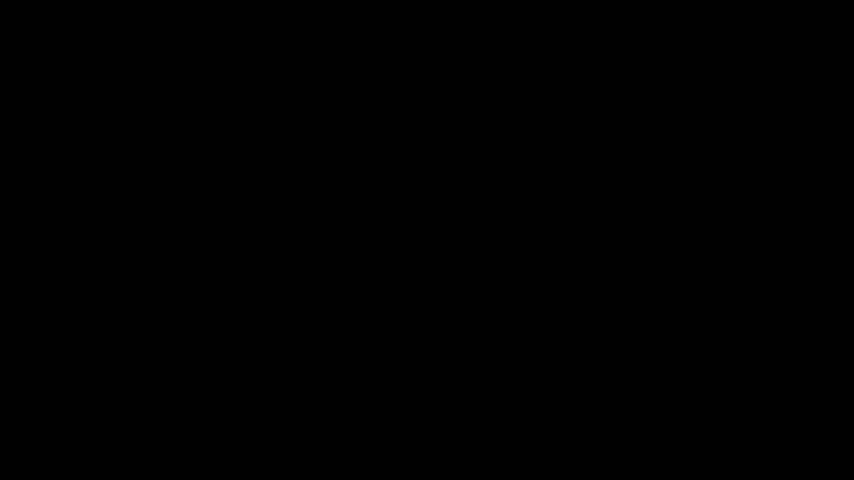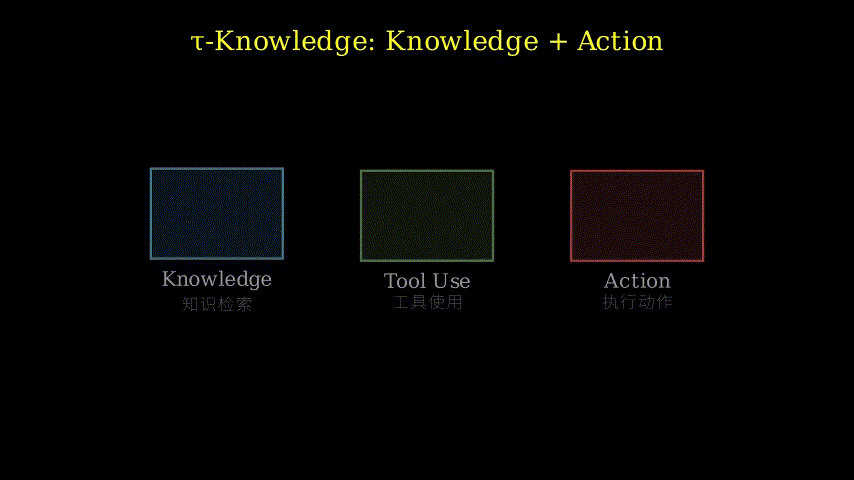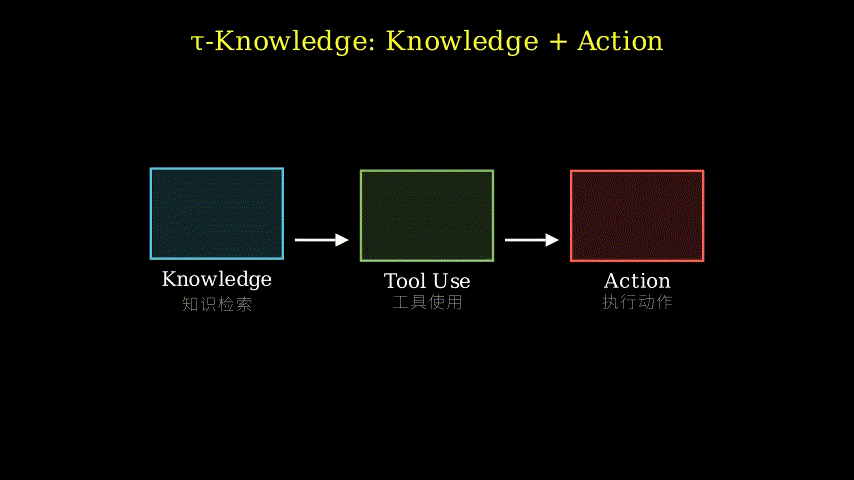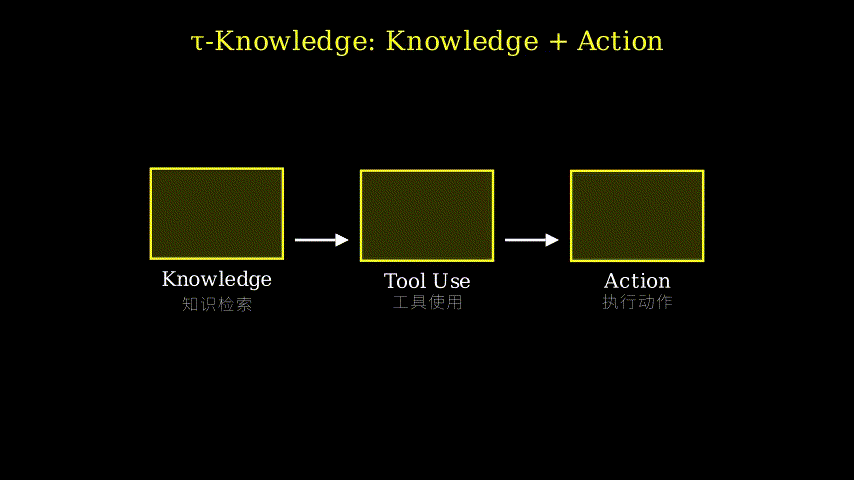
τ-Knowledge extends τ-Bench (a tool-use benchmark) by injecting a knowledge layer. The setup has three components: a task environment (simulated banking system with account states), a knowledge corpus (700 interconnected policy documents), and success criteria (state changes must be both correct and policy-compliant).
Here’s the flow: The agent receives a customer request like “I want to dispute a charge.” It must first search the knowledge base to find relevant policies (dispute eligibility, required documentation, time limits). Then it executes tool calls (check transaction history, verify account status, file dispute). Finally, the environment checks if the resulting state change matches ground truth AND whether the agent followed the policies it should have retrieved.
The twist is verification. Unlike traditional RAG where retrieval quality is measured by answer correctness, here retrieval quality is measured by action legality. You can retrieve the right document but still fail if you misinterpret the policy. You can execute the right tool sequence but fail if you skipped a required policy check.
User Request
     |
     v
+----+--------------------+
|  Agent Decision Loop   |
|                        |
|  [Retrieve] <--+       |
|      |         |       |
|      v         |       |
|  [Reason]      |       |
|      |         |       |
|      v         |       |
|  [Act] --------+       |
|      |                 |
+------+-----------------+
       |
       v
Environment Verification
   /           \
  /             \
State          Policy
Correct?       Compliant?
  \             /
   \           /
    v         v
   Pass / Fail
Think of it like a hospital resident handling a patient. The resident has access to medical literature (knowledge base) and can order tests or prescribe medications (tools). A good outcome requires both: consulting the right clinical guidelines AND executing the right treatment sequence. If they prescribe correctly but skip checking for drug interactions in the literature, the patient suffers. If they read all the guidelines but order the wrong tests, same problem. τ-Knowledge is the attending physician watching the resident work, checking both the medical reasoning and the procedural execution.
The knowledge base structure matters. Documents are densely interlinked—a dispute policy references fraud detection policies, which reference account verification policies. This mimics real corporate knowledge bases where information is scattered across SOPs, legal docs, and internal wikis. Agents can’t just retrieve one document; they need to follow chains of references, like a lawyer tracing precedents.
Key Concepts
-
Policy-Compliant State Changes: Imagine you’re a bank teller. A customer asks to withdraw $10,000. You can physically hand over the cash (state change), but first you must verify their identity, check for withdrawal limits, and file a currency transaction report if required (policy compliance). The action is only correct if both the outcome (customer gets money) and the process (followed regulations) are right. In τ-Knowledge, agents must produce state changes that match the expected outcome while respecting constraints buried in policy documents. It’s not enough to get the right answer; you must show your work using the right rules.
-
Interleaved Retrieval and Action: Most benchmarks treat retrieval as a preprocessing step—fetch documents, then answer questions. But real agents alternate: retrieve a policy, realize it references another document, retrieve that, discover a constraint, execute a tool call, check if the result requires consulting another policy. It’s like cooking from a recipe that says “see page 47 for the sauce” and page 47 says “if using fresh tomatoes, see page 12 for blanching instructions.” You can’t batch all the reading upfront; you read, act, read more, act more. τ-Knowledge forces this interleaving by making policy compliance depend on tool outputs (e.g., “if account balance
< $100, waive the fee” requires checking balance before deciding which policy applies). -
Densely Interlinked Knowledge: Picture a corporate wiki where every page has 5-10 hyperlinks to other pages, and those pages link to others, forming a web. Finding the right information isn’t a single retrieval; it’s graph traversal. You land on “Dispute Policy” but it says “see Fraud Detection for suspicious transactions,” and Fraud Detection says “see Account Verification for identity checks.” Agents must decide which links to follow, when to stop, and how to synthesize information across multiple documents. The 700-doc knowledge base in τ-Banking is structured this way—policies reference each other, creating a maze where the path to the right answer isn’t obvious.
Framework Shift
Before (mainstream approach):        After (this paper):

[Retrieval Task]                     [Unified Task]
     |                                    |
     v                                    v
  Answer                            +---------+
                                    |Retrieve |
[Tool Use Task]                     |    +    |
     |                              | Reason  |
     v                              |    +    |
  State Change                      |   Act   |
                                    +---------+
                                         |
                                         v
                                   State Change
                                   + Policy Log
From testing retrieval and action as separate skills to testing them as a coupled capability where neither works without the other.
Expert Assessment
Problem choice: This is a real gap, not manufactured. Anyone who’s tried deploying agents in enterprise settings knows the pain: agents that ace RAG benchmarks but hallucinate policies in production, or agents that execute tool sequences flawlessly in demos but violate compliance rules with real data. The field has been optimizing components in isolation while ignoring integration failures. This benchmark sits at the right place in the trajectory—we’ve solved the pieces, now we need to solve the assembly.
Method maturity: It’s mostly engineering, not a novel algorithm. They took τ-Bench, added a knowledge corpus, and defined stricter success criteria. The insight is in problem formulation, not method innovation. That said, the execution is solid—700 interlinked documents is non-trivial to construct, and the banking domain is well-chosen (realistic, policy-heavy, verifiable ground truth). No simpler approach is being overlooked; sometimes the right move is to build the benchmark the field needs rather than invent a new technique.
Experimental integrity: The 25.5% pass rate is damning and credible. They test frontier models (GPT-4, Claude) with high reasoning budgets, so it’s not a resource constraint. The reliability degradation over repeated trials is particularly interesting—agents don’t fail consistently, they fail unpredictably, which is worse for deployment. One red flag: the paper doesn’t deeply analyze failure modes. Are agents retrieving wrong documents, misinterpreting correct documents, or executing wrong tool sequences? The aggregate numbers are clear, but the diagnostic value is limited.
Writing quality: The abstract and intro are crisp. The related work section is perfunctory—it lists prior benchmarks but doesn’t explain why each one fails to capture the coordination problem. The results section reports numbers but lacks the qualitative analysis that would make this paper a resource for future work. If they rewrote Section 5 to include error taxonomy (retrieval failures vs reasoning failures vs execution failures) and case studies of typical failure patterns, this would go from a solid benchmark paper to a foundational reference.
Verdict: weak accept — Addresses a real gap with a well-constructed benchmark, but the analysis doesn’t fully exploit the data they collected.
Takeaways
If you’re building agents for knowledge-intensive domains, steal the evaluation structure: don’t just check if the agent’s final answer is correct, check if the reasoning path is policy-compliant. Instrument your agent to log which documents it retrieved and which policies it applied, then verify those against ground truth. This catches a class of failures (right answer, wrong reasoning) that standard accuracy metrics miss.
The interlinked knowledge base design is worth copying. If you’re creating synthetic eval data, don’t make documents independent—add cross-references, make policies depend on other policies, force agents to traverse a graph rather than retrieve from a flat list. This stress-tests the agent’s ability to follow chains of reasoning, which is where real-world deployments break.
The repeated trial reliability metric is underused in the field. Run your agent on the same task 5 times and measure variance. If pass rate drops from 80% to 40%, you have a deployment problem even if the average looks good. This paper shows frontier models degrade sharply on repeated trials, which suggests current agents are guessing their way through ambiguity rather than reasoning robustly.
论文: 2603.04370 作者: Quan Shi, Alexandra Zytek, Pedram Razavi, Karthik Narasimhan, Victor Barres 分类: cs.AI, cs.CL, cs.IR
缺口
现有基准把检索(RAG系统)和工具使用(ReAct、函数调用)当作独立技能来测试。
HotPotQA检查你能否跨维基百科文章跳转。
ToolBench检查你能否按顺序调用API。
但真实的客服智能体需要同时做这两件事:在执行账户变更时检索政策文档,而政策决定了哪些工具调用是合法的。
缺口在于评估的真实性。
当前基准没有捕捉到这种交织的决策过程:智能体必须查阅非结构化知识来决定哪些操作是允许的,然后验证这些操作是否符合检索到的政策。
这就像分别测试律师的研究能力和庭审能力,却从不要求他们用判例法来辩论案件。
问题: 部署在知识密集型场景的智能体不可预测地失败
   |
   v
假设: 现有基准孤立地测试检索+工具使用
   |
   v
方法: τ-Knowledge = τ-Bench + 700文档知识库 + 政策约束
   |
   v
证据: 前沿模型通过率25.5% (vs 孤立任务70%+)
   |
   v
结论: 协调知识+工具是一种独特的、未解决的能力
增量
一句话: 之前我们知道智能体能检索或行动;现在我们知道当要求它们在真实的、受政策约束的工作流中同时做这两件事时,它们会灾难性地失败。
核心机制
τ-Knowledge通过注入知识层来扩展τ-Bench(一个工具使用基准)。
设置包含三个组件:任务环境(带账户状态的模拟银行系统)、知识语料库(700个互联的政策文档)、成功标准(状态变更必须既正确又符合政策)。
流程是这样的:智能体收到客户请求,比如”我想争议一笔收费”。
它必须首先搜索知识库找到相关政策(争议资格、所需文档、时间限制)。
然后执行工具调用(检查交易历史、验证账户状态、提交争议)。
最后,环境检查结果状态变更是否匹配真值,以及智能体是否遵循了它应该检索的政策。
关键在于验证。
与传统RAG通过答案正确性衡量检索质量不同,这里检索质量通过行动合法性来衡量。
你可以检索到正确文档但仍然失败,如果你误解了政策。
你可以执行正确的工具序列但失败,如果你跳过了必需的政策检查。
用户请求
     |
     v
+----+--------------------+
|  智能体决策循环        |
|                        |
|  [检索] <--+           |
|      |     |           |
|      v     |           |
|  [推理]    |           |
|      |     |           |
|      v     |           |
|  [行动] ---+           |
|      |                 |
+------+-----------------+
       |
       v
环境验证
   /           \
  /             \
状态          政策
正确?         合规?
  \             /
   \           /
    v         v
   通过/失败
把它想象成医院住院医师处理病人。
住院医师可以访问医学文献(知识库)并能开检查单或开药(工具)。
好的结果需要两者:查阅正确的临床指南并执行正确的治疗序列。
如果他们开药正确但跳过了在文献中检查药物相互作用,病人会受伤害。
如果他们读了所有指南但开错了检查单,同样的问题。
τ-Knowledge就是主治医师看着住院医师工作,既检查医学推理又检查程序执行。
知识库结构很重要。
文档密集互联——争议政策引用欺诈检测政策,欺诈检测政策引用账户验证政策。
这模拟了真实的企业知识库,信息分散在SOP、法律文档和内部wiki中。
智能体不能只检索一个文档;它们需要跟随引用链,就像律师追溯先例。
关键概念
- 符合政策的状态变更: 想象你是银行柜员。
客户要求取款10,000美元。
你可以物理上交出现金(状态变更),但首先必须验证他们的身份、检查取款限额,如果需要还要提交货币交易报告(政策合规)。
只有当结果(客户拿到钱)和过程(遵循了规定)都正确时,行动才是正确的。
在τ-Knowledge中,智能体必须产生匹配预期结果的状态变更,同时尊重埋藏在政策文档中的约束。
得到正确答案还不够;你必须用正确的规则展示你的工作。
- 交织的检索和行动: 大多数基准把检索当作预处理步骤——获取文档,然后回答问题。
但真实智能体是交替进行的:检索一个政策,意识到它引用了另一个文档,检索那个,发现一个约束,执行一个工具调用,检查结果是否需要查阅另一个政策。
这就像按食谱做菜,食谱说”酱汁见第47页”,第47页说”如果用新鲜番茄,焯水说明见第12页”。
你不能预先批量完成所有阅读;你读、做、再读、再做。
τ-Knowledge通过让政策合规依赖于工具输出来强制这种交织(例如,“如果账户余额<100美元,免除费用”需要在决定适用哪个政策之前检查余额)。
- 密集互联的知识: 想象一个企业wiki,每个页面有5-10个到其他页面的超链接,那些页面又链接到其他页面,形成一个网络。
找到正确信息不是单次检索;而是图遍历。
你落在”争议政策”上,但它说”可疑交易见欺诈检测”,欺诈检测说”身份检查见账户验证”。
智能体必须决定跟随哪些链接、何时停止、如何综合多个文档的信息。
τ-Banking中的700文档知识库就是这样结构化的——政策相互引用,创造了一个迷宫,通往正确答案的路径并不明显。
框架转变
之前(主流方法):                  之后(本文方法):

[检索任务]                       [统一任务]
     |                                |
     v                                v
   答案                          +---------+
                                 |检索     |
[工具使用任务]                   |    +    |
     |                           | 推理    |
     v                           |    +    |
  状态变更                       | 行动    |
                                 +---------+
                                      |
                                      v
                                 状态变更
                                 + 政策日志
从把检索和行动作为独立技能测试,到把它们作为耦合能力测试,其中任何一个没有另一个都不起作用。
专家评审
选题眼光: 这是真缺口,不是人造的。
任何尝试在企业环境中部署智能体的人都知道这种痛苦:在RAG基准上表现优异的智能体在生产中幻想政策,或者在演示中完美执行工具序列的智能体用真实数据违反合规规则。
该领域一直在孤立地优化组件,同时忽略集成失败。
这个基准处于轨迹中的正确位置——我们已经解决了各个部分,现在需要解决组装问题。
方法成熟度: 主要是工程,不是新算法。
他们拿了τ-Bench,添加了知识语料库,定义了更严格的成功标准。
洞察在于问题表述,而非方法创新。
话虽如此,执行是扎实的——构建700个互联文档并非易事,银行领域选择得很好(真实、政策密集、可验证的真值)。
没有被忽略的更简单方法;有时正确的举措是构建该领域需要的基准,而不是发明新技术。
实验诚意: 25.5%的通过率既令人沮丧又可信。
他们测试了前沿模型(GPT-4、Claude)并给予高推理预算,所以这不是资源约束。
重复试验中的可靠性退化特别有趣——智能体不是一致地失败,而是不可预测地失败,这对部署来说更糟。
一个警示:论文没有深入分析失败模式。
智能体是检索了错误文档、误解了正确文档,还是执行了错误的工具序列?总体数字很清楚,但诊断价值有限。
写作功力: 摘要和引言简洁。
相关工作部分敷衍——它列出了先前的基准但没有解释为什么每个都未能捕捉协调问题。
结果部分报告了数字但缺乏定性分析,而这会使本文成为未来工作的资源。
如果他们重写第5节,包括错误分类(检索失败vs推理失败vs执行失败)和典型失败模式的案例研究,这将从一篇扎实的基准论文变成基础性参考文献。
判决: 弱接收 — 用精心构建的基准解决了真实缺口,但分析没有充分利用他们收集的数据。
要点总结
如果你在为知识密集型领域构建智能体,偷走评估结构:不要只检查智能体的最终答案是否正确,检查推理路径是否符合政策。
给你的智能体加仪表记录它检索了哪些文档、应用了哪些政策,然后对照真值验证这些。
这能捕捉到一类失败(正确答案、错误推理),而标准准确率指标会漏掉。
互联知识库设计值得复制。
如果你在创建合成评估数据,不要让文档独立——添加交叉引用,让政策依赖于其他政策,强制智能体遍历图而不是从扁平列表检索。
这压力测试了智能体跟随推理链的能力,而这正是真实世界部署崩溃的地方。
重复试验可靠性指标在该领域使用不足。
在同一任务上运行你的智能体5次并测量方差。
如果通过率从80%降到40%,即使平均值看起来不错,你也有部署问题。
本文显示前沿模型在重复试验中急剧退化,这表明当前智能体是在猜测它们通过模糊性的方式,而不是稳健地推理。